Qualcomm
Qualcomm · AI / ML · Filed Feb 13, 2025 · USPTO published Aug 13, 2026 · Aug 13 release
Qualcomm Patents a Way to Stop AI Video Models From Running Out of Memory
Running an AI model on video is memory-hungry work. Qualcomm's new patent describes a method that automatically figures out which stored data is redundant and discards it, so the model can keep running without choking on its own memory footprint.
- Publication number
- US 2026/0236402 A1(US20260236402A1)
- Applicant
- QUALCOMM Incorporated
- Filed · Published
- Feb 13, 2025 · Aug 13, 2026
- Inventors
- Minsoo KIM, Kyuhong SHIM, Seunghan YANG, Juntae LEE, Jihwan BANG, Simyung CHANG
- Status when we published
- Approved; patent expected soon
- Document
- 20 claims
- US classification
- 711/133
- Examiner
- WADDY JR, EDWARD (Art Unit 2135)
How Qualcomm's video AI trims its own memory use
Every time an AI model processes a video on your phone, it stores a small snapshot of each frame to help understand what comes next. Do that for hundreds of frames and the storage fills up fast, which either slows everything down or forces the system to stop processing altogether.
Qualcomm's patent describes a system that scores each frame's stored data on two dimensions: how different it is from nearby frames (temporal) and how much information it actually carries (spatial). Data that is too similar to what came before, or too sparse to be useful, gets automatically discarded to free up room.
The goal is to let a generative AI model, the kind that can describe, caption, or answer questions about video, run on a device with limited memory without losing meaningful accuracy. The model works with whatever data survives the cut, and the idea is that what gets discarded is the stuff that wouldn't have changed the answer anyway.
… evict the first key tensor and the first value tensor from the memory based on at least one of the first temporal score or the first spatial score; and generate an output of the generative machine learning model based at least in part on one or more key tensors and one or more value tensors remaining in the memory …
Translation: The system deletes data that is less important to free up space so the AI can keep working without crashing.
How temporal and spatial scores decide what gets dropped
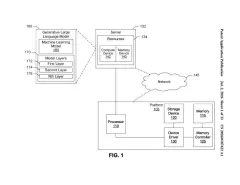
The patent describes a memory management system built for generative AI models that process sequences of images or video frames. These models use a structure called a KV cache (short for key-value cache), which stores intermediate representations of each frame so the model can reference earlier context. On a phone or edge chip, that cache can grow large enough to become a bottleneck.
The system generates two scores for every stored data chunk tied to a frame token:
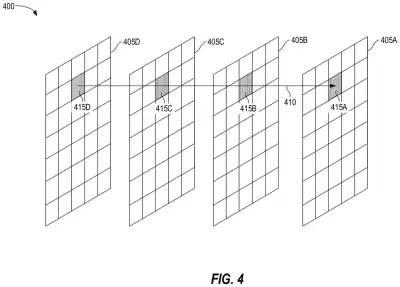
- Temporal score: measures how similar this frame's key tensor (a compact mathematical fingerprint of the frame) is to the same position in neighboring frames. High similarity means the data is redundant. A high similarity aggregate produces a low temporal score, marking it as a discard candidate.
- Spatial score: measures the norm of the value tensor (roughly, how much signal or information the stored value carries). A low norm means the data doesn't contribute much and can go.
Data is evicted from memory when either score falls below the threshold. What remains is the subset of frame data that is genuinely informative, and the AI model generates its output from that leaner cache.
The claim specifies that similarity is computed per neighboring key tensor, aggregated, and then inverted, so frames that look very much like their neighbors score lowest and get dropped first. It is an automated housekeeping routine that runs inside the model's inference loop.
… a temporal score is generated, for the token, based on the key tensor and a set of key tensors for corresponding tokens in other images of the sequence of images. A spatial score is generated, for the token, based on a norm of the value tensor. The key tensor and the value tensor are evicted from the memory based on at least one of the temporal score or the spatial score …
Translation: The AI calculates how much each piece of video data matters by comparing it to other frames and checking its internal value.
What this means for AI on phones and edge chips
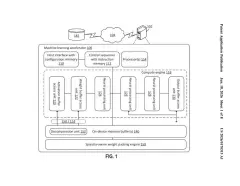
For users, the practical payoff is an AI that can process longer video clips on a device without needing a data-center connection. Today, many video AI features either run in the cloud (where memory is cheap) or cap out at a handful of frames on-device. A more efficient cache means the model can handle more frames before it hits a wall, which translates to more accurate captions, longer clip understanding, or faster responses when you ask your phone a question about something in a video.
Qualcomm supplies the chips inside a large share of Android flagship phones, and on-device AI for video is a clear priority across the industry. A cache management scheme that reduces memory pressure without retraining the model would be attractive to any hardware maker trying to run large models on constrained silicon. For anyone following Big Tech patent news around on-device AI inference and chip-level memory optimization, this filing sits squarely in that conversation.
Source: US 2026/0236402 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Qualcomm patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 9 sheets
9 drawing sheets from US 2026/0236402 A1 · click any drawing to enlarge


Show the other 1 sheets

More from Qualcomm
All 624 Qualcomm patents →
More in AI assistant & agent
All 413 AI assistant & agent patents →
IBM
IBM Patents a System That Moves Database Data Before You Even Ask for It
AMD
Xilinx Patents a Way to Trace AI Model Bugs Back to Their Source on Neural Chips
Samsung
Samsung Patent: Loading Only Required AI Model Sections Per Token Reduces Latency
Amazon