AMD
AMD · Chip · Filed Feb 12, 2025 · USPTO published Aug 13, 2026 · Aug 13 release
Xilinx Patents a Two-Table Shortcut for Running AI Math on Chips
Every time an AI model makes a decision, it fires a wave of math functions that can slow chips down. Xilinx has filed a patent for a two-table lookup system that approximates those functions without doing the hard math each time.
- Publication number
- US 2026/0236753 A1(US20260236753A1)
- Applicant
- XILINX, INC.
- Filed · Published
- Feb 12, 2025 · Aug 13, 2026
- Inventors
- Krishnakumar NAIR, Ashish SIRASAO, Rajeev PATWARI, Steven Karl REINHARDT, Satyaprakash PAREEK
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 706/15
How Xilinx speeds up AI calculations on its chips
Ever had a calculator that could answer certain questions instantly, just by looking up a pre-filled table instead of working through the arithmetic fresh? That is essentially what Xilinx is building here, but for the repetitive math that sits at the heart of every AI model.
When AI models process data, they rely on functions (called activation functions) that shape and filter information at each step. These functions, things like GELU or Tanh, involve curves and exponents that are expensive for hardware to compute on the fly. Xilinx's approach is to pre-calculate good approximations and store them in two linked tables. Your chip looks up the answer rather than grinding through the equation.
The clever part is that the first table isn't uniform. It devotes more entries to the parts of the curve that change fastest, and fewer entries to the flat, predictable parts. That keeps the tables small while keeping the answers accurate enough for real AI workloads.
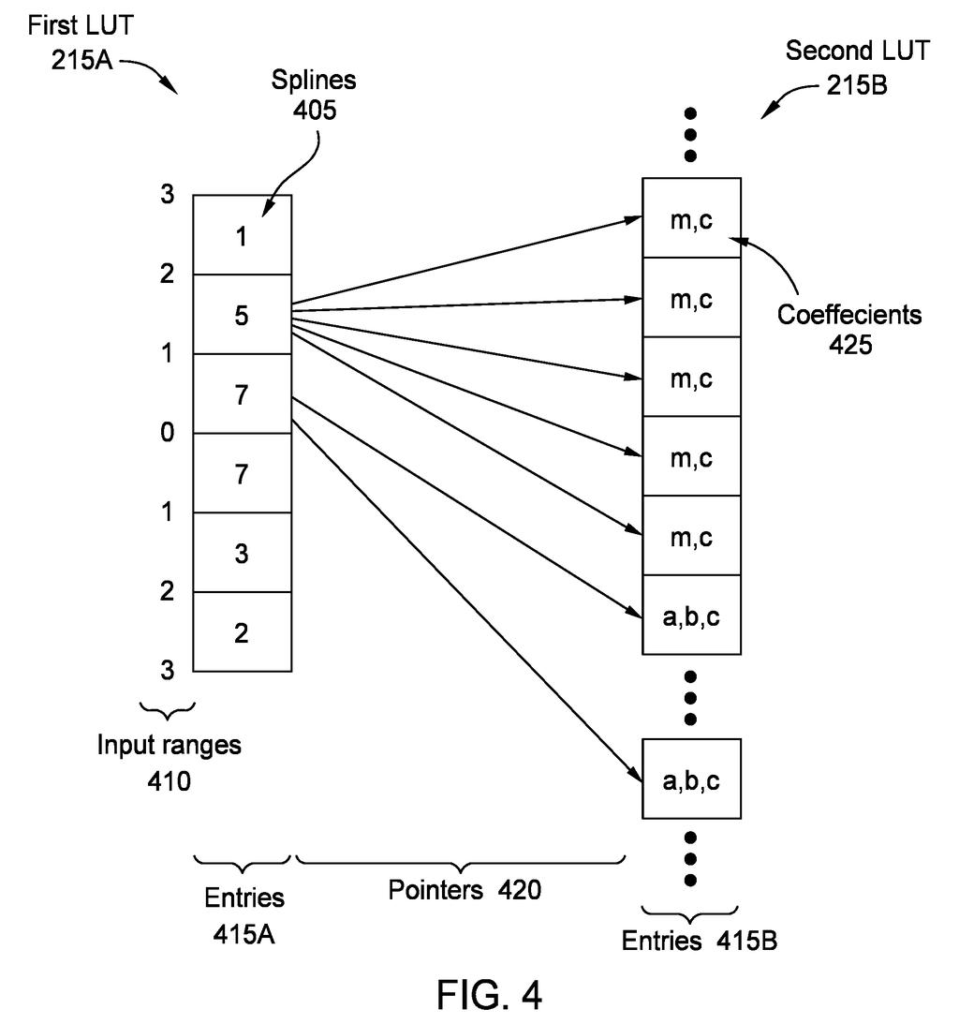
… the first LUT is divided into a plurality of input ranges, wherein each of the plurality of input ranges comprises at least one spline, wherein each of the splines corresponds to a pointer stored in the first LUT, and wherein the second LUT comprises entries pointed to by the pointers in the first LUT …
Translation: The system uses a two-step lookup process where the first table directs the chip to the specific math data in the second table.
How the two lookup tables split the math workload
The patent describes a memory-based system built around two look-up tables (LUTs), which are essentially pre-filled spreadsheets that a chip can read in a single fast step instead of computing an answer from scratch.
The first LUT divides the input number line into ranges (for example, -2 to -1, -1 to 0, 0 to 1, and so on). Within each range it uses a set of splines (short curve-fitting segments, like tiny rulers that approximate a curve piece by piece). Crucially, ranges where the activation function changes quickly get more splines; flat, boring regions get fewer. This uneven allocation is determined by running a derivative analysis (a calculus tool that measures how fast a curve is changing) on the target function ahead of time.
Each spline in the first LUT stores a pointer (a reference, like a page number) that points to an entry in the second LUT. That entry holds the coefficients (the numerical ingredients needed to compute the final answer) for that tiny segment of the curve.
At inference time, the chip:
- Takes an input number and looks it up in the first LUT to find the right spline.
- Follows the pointer to the matching entry in the second LUT.
- Uses those coefficients to calculate the non-linear output in a small, cheap arithmetic step.
The result is a close approximation of demanding functions like GELU, SiLU, Sigmoid, and Tanh, without the full floating-point computation those functions normally require.
The first LUT can define input ranges (e.g., -1 to 0, 0 to 1, 1 to 2, etc.) which have unequal numbers of splines, which can be determined using derivative analysis on the non-linear function.
Translation: The chip divides math problems into custom segments based on how complex the function is in that specific range.
What faster AI activation means for chip performance
For anyone running AI inference on an FPGA or accelerator chip, activation functions are a hidden tax paid on every layer of every forward pass. A faster, cheaper way to evaluate them means either faster throughput on the same hardware or the same throughput on a smaller, cheaper chip. Neither outcome is glamorous, but both show up directly in how fast a model responds and how much the hardware costs to deploy.
Xilinx, now part of AMD, has long focused on putting AI workloads onto FPGAs (programmable chips that can be reconfigured for specific tasks). This filing fits that strategy: LUT-based computation is exactly how FPGAs are wired to work, so a LUT-native approximation of AI math is a natural match for the platform. Patentlyze covers plain-English patent summaries across the AI chip space, and this filing sits in a busy area where AMD, Intel, and others are all racing to squeeze more AI math out of fewer transistors.
Source: US 2026/0236753 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time AMD patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 6 sheets
6 drawing sheets from US 2026/0236753 A1 · click any drawing to enlarge


More from AMD
All 119 AMD patents →


More in Chip
All 645 Chip patents →
OpenAI
OpenAI Patents a Chip That Runs AI Calculations Forward and Backward Without Interruption

Qualcomm
Qualcomm Patents a Chip That Stores Data and Calculates It Simultaneously

Google
Google Patents a Chip Layout That Splits AI Work Across Shared Memory Tiles

Intel