
Microsoft Patents a Way to Split AI Model Work Between Secure and Low-Cost Chips
Running a powerful AI model is expensive, partly because it demands fast, premium chips at every step. Microsoft has filed a patent that asks a different question: what if only the most critical parts of the math needed the good chip?
How Microsoft's hybrid chip split keeps AI accurate and cheap
You're a company trying to run an AI assistant on your servers, but the chips that can do the job fast enough cost a fortune. Every query your users send has to pass through expensive, high-speed processors, and the bill keeps climbing.
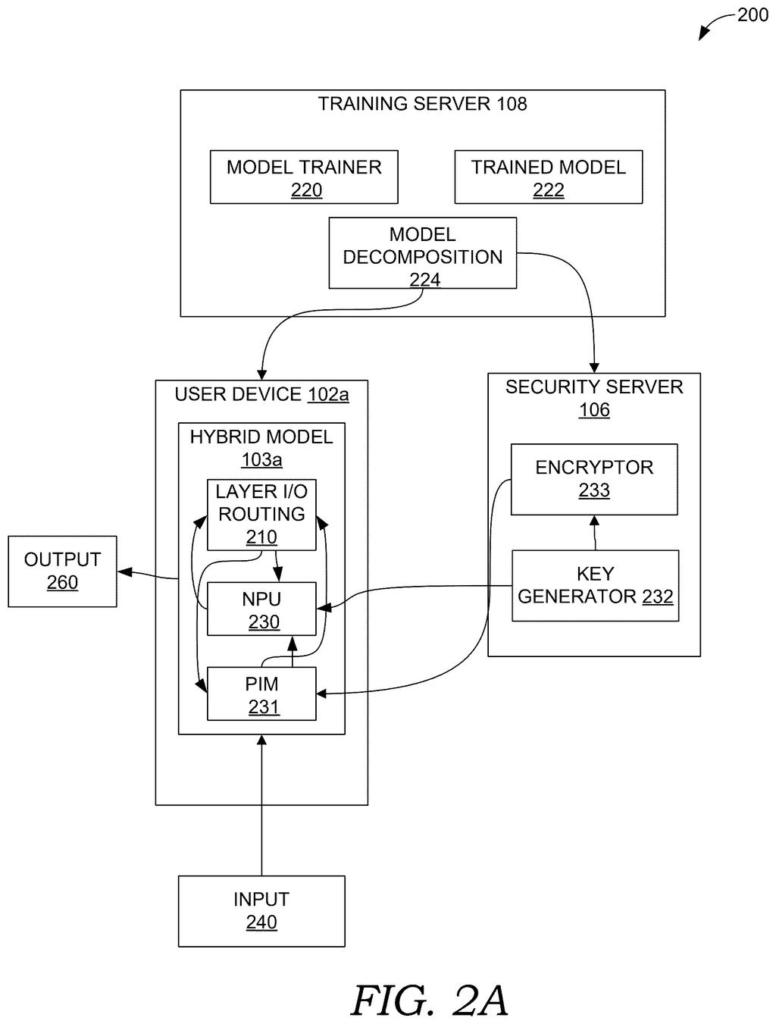
Microsoft's patent describes a way to split the work. An AI model does its calculations in layers, one after another, like an assembly line. For each layer, the patent identifies the small fraction of calculations that matter most for accuracy, maybe less than 20% of the total work, and routes those to a trusted, fast processor. The other 80% or more gets handed off to a much cheaper type of chip called a processor-in-memory, which does math right inside the memory chip itself instead of shipping data back and forth.
The results from both chips get combined at the end of each layer, and the next layer picks up from there. The goal is an AI model that runs nearly as accurately as an expensive all-premium setup, but at a fraction of the cost.
receiving, at a partial processor-side neural network operating on a processor, a processor in memory (PIM)-side output for a first layer of the neural network generated based on a layer input, wherein the PIM-side output is generated by a partial PIM-side neural network that includes less than 100% of all matrix components associated with the first layer …
Translation: The main processor receives part of the data from the memory chip that handled the rest of the workload.
How the patent divides matrix math across two chip environments
The patent covers a method for running a neural network (the mathematical engine behind most modern AI) across two very different types of hardware at the same time.
A standard AI model processes data through dozens or hundreds of layers, each consisting of large grids of numbers called matrices. Normally, every cell in every matrix is computed on the same class of processor. This patent breaks that assumption. For each layer, it classifies individual matrix components (think: cells in the grid) by how much they influence the final answer. The components with the highest influence, the significant components, stay on a conventional processor in a trusted environment, meaning hardware the system can verify and control.
Everything else, the bulk of the matrix math, is offloaded to a processor-in-memory (PIM): a chip that performs arithmetic directly inside the memory module, avoiding the energy and time cost of moving data around. The PIM is called an untrusted environment not because it's malicious, but because it operates outside the verified security boundary.
- The PIM produces its partial result for a layer.
- The secure processor runs its small but high-impact slice of the same layer on the same input.
- The two results are added together to form the complete layer output.
- That combined output feeds into the next layer, which repeats the process.
The claim specifies that the processor-side slice covers less than 20% of the layer's matrix components, meaning at least 80% of each layer's work can move to cheaper memory-based silicon.
The matrix components that make the largest contribution may be described as the significant components and be deployed for use in the trusted processor environment. The rest of the layer may be deployed to the PIM.
Translation: The most important parts of the AI run on a secure processor while the rest runs on cheaper memory chips.
What this means for running AI on affordable hardware
The cost of running AI at scale is one of the biggest constraints facing companies right now. Chips capable of handling full AI workloads are expensive, power-hungry, and in short supply. A method that routes most of the math to cheaper, lower-power memory chips, while keeping only the accuracy-critical slice on premium silicon, could make large AI models significantly cheaper to operate without a major drop in output quality.
For everyday users, that could translate to AI tools that are faster to roll out, available on more devices, or simply less costly for the companies offering them. Microsoft's filing activity around AI inference efficiency suggests this is an area the company is treating as a long-term infrastructure problem, not a one-off experiment.
This is the 14th Microsoft filing we've tracked in the AI chip wars since July, adding to earlier applications like a training data traffic director and a three-way cooling system.
The shortest path from this patent to a shipping product is longer than the abstract makes it sound. You need PIM hardware to be widely available and standardized enough for software to target it reliably, and right now PIM is still a niche category with limited off-the-shelf options.
That said, the core idea here is well-defined and testable. Identifying which matrix components carry the most weight in a layer is a known technique in AI compression research, and the split-execution architecture described is specific enough that a small engineering team could prototype it. The patent is less of a moonshot and more of an engineering blueprint waiting for its hardware moment.
If PIM chips become commodity parts in data centers over the next few years, this kind of hybrid deployment could flip from a research curiosity to a standard deployment pattern. The filing is early, but it is not far from the ground.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
9 drawing sheets from US 2026/0267512 A1 · click any drawing to enlarge


Show the other 1 sheets

Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in