
Google Files Patent for Teaching Speech Recognition to Learn From Its Own Best Guesses
When your phone mishears you, a better answer can be sitting lower on its own list of guesses. Google's patent trains speech recognition to pull that better guess up the list.
What Google's speech-training patent actually does
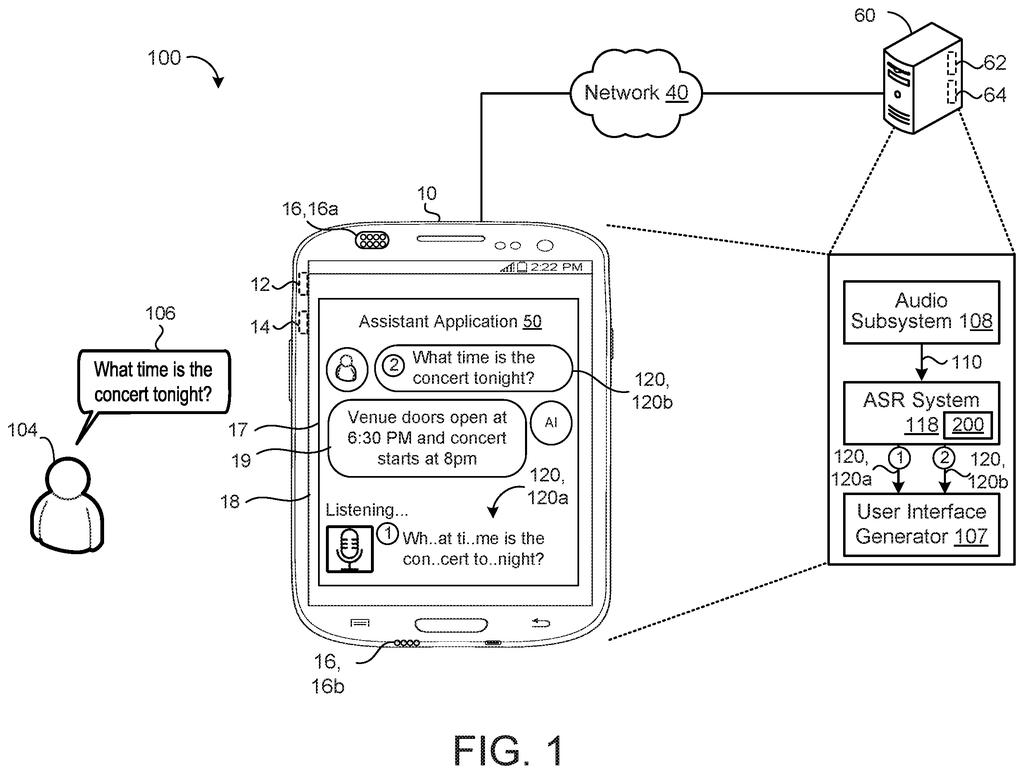
Imagine you ask your phone, "What time is the concert tonight?" Behind the scenes, the speech software doesn't come up with just one answer. It builds a ranked list of possible transcriptions, and the one at the top is what shows up on your screen.
Sometimes a better version is sitting lower on that list. Google's patent describes a training method that takes advantage of this. While the software is being taught, it checks every candidate against the correct text, finds the one with the fewest word errors, and nudges the software to rank that candidate higher. If the software's favorite was worse, it gets pushed down.
For audio that nobody has transcribed, a larger "teacher" model can supply the correct text. The filing says this narrows the gap between the software's first pick and its best pick, and takes less training time than an older method.
… selecting an oracle transcription from the plurality of candidate transcriptions, wherein the oracle transcription possesses a lower word error rate relative to the corresponding ground-truth transcription than the top-ranked transcription; …
Translation: The system finds the runner up guess that is actually closest to the correct text.
How the model picks its best guess to learn from
The patent covers a way to train an automatic speech recognition model, the software that turns spoken audio into text. The example model is a recurrent neural network-transducer (RNN-T, a design that handles audio as it streams in and is small enough to run on a phone). For each training recording, it produces an n-best list, a ranked set of candidate transcriptions.
Then the training works through three steps:
- Take the top-ranked candidate, the one the model rates as most probable.
- Count the word errors in every candidate against the correct transcription, and pick the oracle, the candidate with the fewest errors.
- Work out a penalty (a "loss," a number showing how wrong the model was) for each, scale each penalty by its word errors, and combine them.
The description says that when the top pick and the oracle are the same, the combined penalty comes out to zero, so the model only gets pushed when its favorite isn't its best. All other candidates are ignored, which is how the filing says it avoids the cost of an older method called EMBR (expected minimum Bayes risk, which weighs every candidate on the list).
For recordings with no human transcript, a teacher model (a separate model that supplies a best-guess transcript) can stand in for the correct text. That lets the same recipe use unlabeled audio.
… identifying, as an oracle hypothesis, the speech recognition hypothesis from the n-best list having the smallest corresponding number of word errors relative to the corresponding ground-truth transcription, …
Translation: The AI picks its best alternative attempt by checking which one made the fewest mistakes.
What this means for voice assistants that mishear
If you talk to a phone, speaker or car, the payoff would be fewer misheard words, though you would never see this step. It happens during training, long before the software reaches you. The filing says the method narrows the gap between a model's top pick and its best available pick, which is the gap you feel when the right answer was almost on screen.
There is a cost side too. The filing says training takes less time and computing than the older method it builds on, and the RNN-T design it describes can run entirely on a device. Cheaper training means a company can retrain speech models more often, and that is where this idea would most likely pay off for Google.
Google's 61st filing in Voice & speech AI we've tracked since May follows a self-correcting speech recognizer and noise-canceling earbud mic patent.
You will never find this patent in your phone's settings. What you would notice is the moment a voice assistant hears the wrong name or the wrong word and you have to repeat yourself.
A training recipe like this aims at that moment. It teaches the software to rank its most accurate candidate first, so the version on your screen is more likely the correct one. The text we have includes no accuracy numbers, so how much you would actually notice is unknown.
It is a routine, sensible refinement. If it works as described, the gain is a few fewer repeated sentences for you, and the savings in training time stay on Google's side of the screen.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
6 drawing sheets from US 2026/0351247 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in