
Amazon
Amazon · AI / ML · Filed Mar 5, 2026 · USPTO published Sep 24, 2026 · Sep 24 release
Amazon Patents a Way to Score AI Responses Before You Ever See Them
Most AI systems generate a response and hand it over. Amazon's patent describes a system that grades its own answers before sending them, using a separate scoring model to pick the best one.
- Publication number
- US 2026/0289158 A1(US20260289158A1)
- Applicant
- Amazon Technologies, Inc.
- Filed · Published
- Mar 5, 2026 · Sep 24, 2026
- Inventors
- Sailik Sengupta, Daniele Bonadiman, Yi-An Lai, Arshit Gupta, Dan Roth, Katrin Kirchhoff, Saab Mansour, James Yipeng Huang
- Status when we published
- Waiting for an examiner
- Document
- 21 claims
- US classification
- 704/9
- Parent application
- Continuation of 18/518,329 (filed Nov 22, 2023)(18518329)
What Amazon's response-checking system actually does
Right now, when you ask an AI assistant a question, it generates an answer and passes it straight to you. There's no internal check asking, "Wait, is this actually a good answer?" Amazon wants to change that.
This patent describes a setup where a large language model generates several possible responses to your question, then a separate "alignment model" scores each one. Think of the alignment model as a strict editor sitting between the AI and your screen. It reads each draft answer and picks the one most likely to be accurate, helpful, or safe.
The clever part is that this alignment model can be swapped out depending on what kind of question you're asking. A customer service bot and a medical information tool might each need a different definition of a "good" answer. Amazon's system lets that scoring layer be chosen or adjusted at the moment your question comes in, rather than being baked in ahead of time.
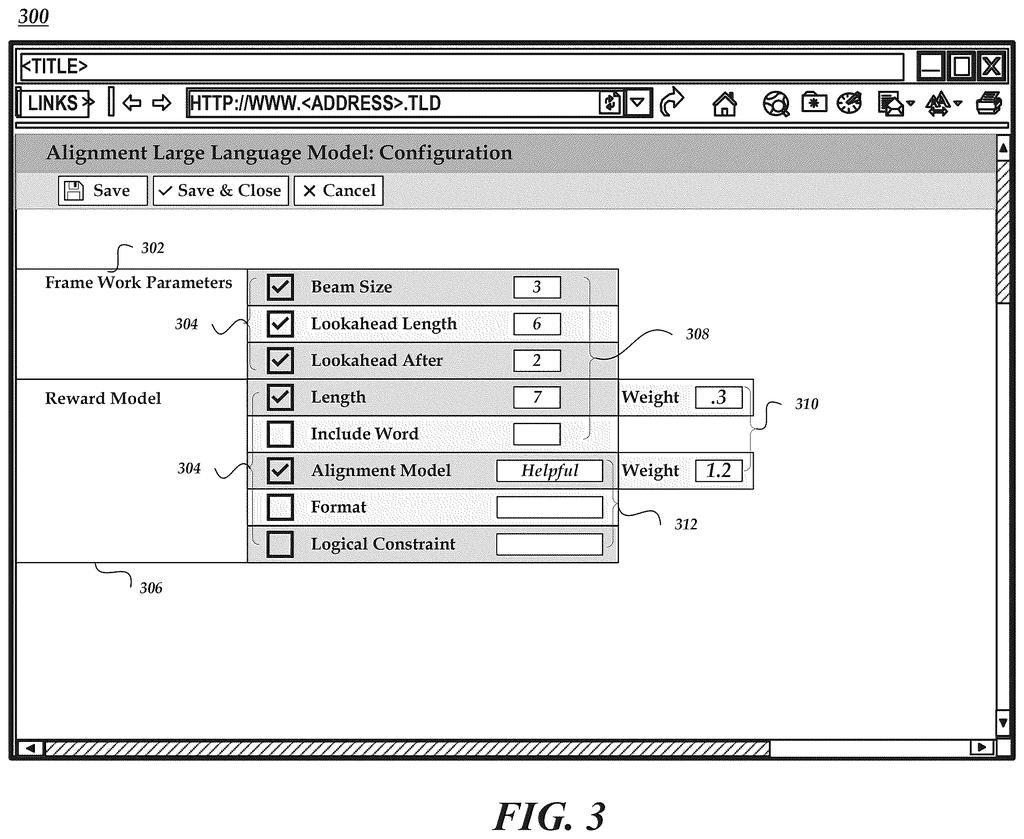
The large language model populates tokens for potential responses based on framework parameters and evaluates the potential responses using an alignment model.
Translation: The AI system generates different reply options and judges them using a built-in quality checker.
How the alignment model scores and filters AI output
The patent describes a pipeline with two main pieces working together. First, a large language model (LLM) generates what the patent calls "potential responses" to an incoming prompt. Rather than committing to one answer, the system produces multiple candidates.
Second, an alignment model evaluates those candidates. An alignment model is essentially a trained scoring system that judges whether a given piece of text meets certain criteria, such as being factually grounded, policy-compliant, or appropriate for the context. The winning candidate becomes the actual output.
What makes this design distinctive is when the alignment model gets applied. Most existing approaches train alignment into the base LLM itself, locking in one set of values. Here, alignment happens at decoding-time, meaning during the moment the model is actively generating text, not months earlier during training. That timing shift means:
- Different alignment models can be plugged in for different types of prompts
- The system can be updated without retraining the entire LLM
- Different use cases or customers could theoretically get different alignment criteria
The patent covers both the method of doing this and the computational framework ("framework parameters") that governs how candidate responses are generated and ranked.
What this means for AI assistants that get things wrong
For anyone frustrated by AI giving confident but wrong or inappropriate answers, this approach addresses the problem from a different angle than the usual fix. Instead of trying to train "better values" into one giant model, Amazon's design layers a separate judge on top, one that can be updated or replaced without overhauling the core AI.
The practical upside is flexibility. A retail assistant, a coding helper, and a children's education tool all have different ideas of what counts as a good response. A swappable scoring layer makes that customization far more tractable than retraining a full LLM from scratch each time. If Amazon is building this into services like Alexa or AWS AI tools, the ability to tune response quality per deployment could matter a great deal to business customers.
Amazon's fourth filing we've tracked since July in our AI guardrails race adds to a set that includes one blocking harmful chatbot output and one flagging unfair AI behavior.
Source: US 2026/0289158 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Amazon patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 7 sheets
7 drawing sheets from US 2026/0289158 A1 · click any drawing to enlarge


More from Amazon
All 111 Amazon patents →

More in AI / ML
All 2,637 AI / ML patents →
Nvidia
Nvidia Patents an AI Answer System That Trusts Expert Authors Over Everyone Else
Adobe
Adobe Patents an AI Coding System That Learns by Studying Its Own Mistakes
Microsoft
Microsoft Patents an AI Coding Tool That Flags Unsafe Inputs Before Running Your Code
IBM
No comments yet