
Google
X (Google) · AI / ML · Filed Jan 16, 2026 · USPTO published Aug 13, 2026 · Aug 13 release
Google Files Patent for AI That Searches Across Multiple Data Sources at Once
What if asking one question got you answers pulled simultaneously from a dozen different data sources, each accessed in exactly the way that source requires? That's the core idea behind a new Google patent on AI-driven data feed aggregation.
- Publication number
- US 2026/0236474 A1(US20260236474A1)
- Applicant
- X Development LLC
- Filed · Published
- Jan 16, 2026 · Aug 13, 2026
- Inventors
- David Andre
- Status when we published
- Waiting for an examiner
- Document
- 21 claims
- US classification
- 707/722
- Parent application
- Continuation of 18/673,222 (filed May 23, 2024)(18673222)
How Google's multi-feed AI query system works for you
You're typing a question into an AI assistant and you want the most complete answer possible, but the information you need is scattered across several different services, each with its own rules for how to ask for data.
Right now, most AI tools either search one source at a time or require someone to manually stitch results together. Google's patent describes a system where a single question, written in plain English, gets automatically translated into the right kind of request for each data service simultaneously. The AI learns each service's own "language" for fetching data, so you don't have to.
The practical upshot is that one question could return a unified answer assembled from multiple specialized sources, without you ever knowing how many different systems the AI queried behind the scenes.
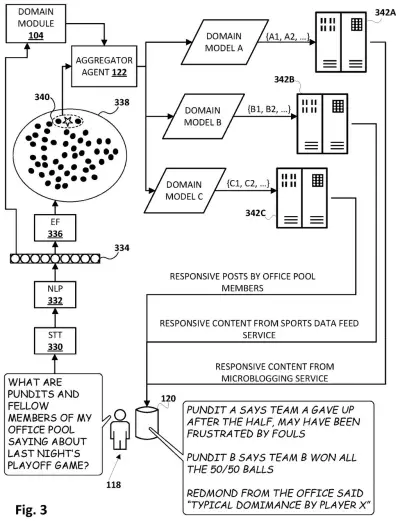
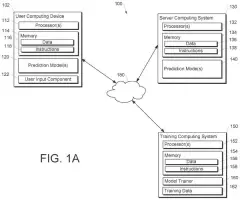
… NLP may be performed on a natural language input comprising a query for information to generate a data feed-agnostic aggregator embedding (FAAE). A plurality of data feed services may be selected, each having its own data feed service action space that includes actions that are performable to access data via the data feed service.
Translation: The system turns your search into a universal code that can trigger specific actions across many different apps at once.
How the feed-agnostic embedding bridges different data services
The patent describes a machine learning pipeline built around what Google calls a feed-agnostic aggregator embedding (FAAE), essentially a shared, neutral representation of what a user is asking for, expressed in a way that doesn't favor any single data source's format.
Here's how the pieces fit together:
- Natural language processing (NLP) converts your plain-English query into that neutral FAAE representation.
- The system selects multiple data feed services, each of which has its own vocabulary of actions, meaning specific operations you can perform to retrieve data from it.
- Domain-specific machine learning models, one per data service, translate the neutral embedding into whatever that particular service understands, picking the right actions from its action space.
- Those actions are executed in parallel and the results are aggregated into a unified response.
The key insight is the separation of concerns: the system learns one general understanding of what the user wants, then separately learns how each data service works, rather than building a bespoke connector for every possible source-to-source combination. This makes it far easier to add new data services over time without retraining the whole system from scratch.
What this means for AI assistants and data aggregation
For everyday users, this kind of system would mean an AI assistant that gives you richer, more complete answers without you needing to open five tabs or rephrase your question five times for five different tools. The failure it prevents is the familiar one: asking an AI something and getting a partial answer because it only checked one source.
For Google, the strategic value is in positioning an AI layer as the universal translator between users and the messy patchwork of data services that exist across the web and enterprise software. This filing sits alongside the broader wave of latest Big Tech patents targeting AI-driven data retrieval and multi-service orchestration, a space where Google, Microsoft, and others are all racing to own the query layer.
Source: US 2026/0236474 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 5 sheets
5 drawing sheets from US 2026/0236474 A1 · click any drawing to enlarge


More from Google
All 1,079 Google patents →
More in AI / ML
All 2,637 AI / ML patents →
Salesforce
Salesforce Patents a Dashboard for Ranking AI Models by Business Task
Adobe
Adobe Patents a System That Finds the Right Page and Answers Your Document Questions
Adobe
Adobe Patents a System That Uses Competitor Search Rankings to Write Your Website Content
Nvidia