
Google
Google · AI / ML · Filed Mar 31, 2025 · USPTO published Oct 1, 2026 · Oct 1 release
Google Patents a System That Keeps Track of Who's Talking in Long Audio Recordings
Every AI transcription service has the same embarrassing problem: in a long meeting recording, the system might call the same person 'Speaker 1' in one section and 'Speaker 2' in another. Google's new patent tackles exactly that.
- Publication number
- US 2026/0300624 A1(US20260300624A1)
- Applicant
- Google LLC
- Filed · Published
- Mar 31, 2025 · Oct 1, 2026
- Inventors
- Quan Wang, Neeraj Gaur, Guanlong Zhao, Parisa Haghani
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 704/9
- Examiner
- ISLAM, MOHAMMAD K (Art Unit 2653)
How Google's speaker-tracking AI handles long conversations
Every time an AI tries to transcribe a long meeting or podcast, it faces a messy problem: the recording is too long to analyze all at once, so the system chops it into chunks and processes each one separately. In one chunk, your boss might be labeled 'Speaker A.' In the next chunk, the AI starts fresh and accidentally calls her 'Speaker B.' The transcript is technically accurate word-by-word, but the speaker labels are a jumble.
Google's patent describes a system that fixes this after the fact. A neural network (a type of AI modeled loosely on how the brain connects information) looks at all the separately processed chunks and figures out which labels should actually match across the whole recording. When two chunks disagree about who is who, the system swaps the labels in one chunk to make everything consistent.
The result is a single, clean transcript where the same person carries the same label from start to finish, even in a recording that runs for hours.
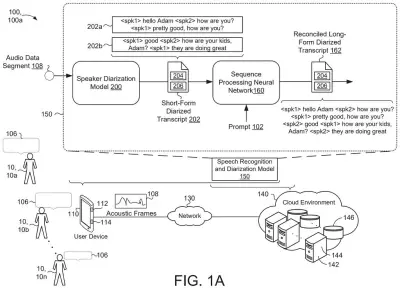
obtaining a plurality of audio data segments characterizing a conversation between two or more speakers; for each respective audio data segment, generating, using a speaker diarization model, a corresponding short-form diarized transcript …
Translation: The system breaks a long conversation audio file into smaller chunks and labels who is speaking in each piece.
How the neural network reconciles mismatched speaker labels
The patent describes a two-stage pipeline for handling long audio recordings with multiple speakers.
Stage one: chunked diarization. A speaker diarization model (diarization means splitting audio by speaker identity) processes each audio chunk independently and produces a short-form transcript. Each transcript contains the words spoken and speaker tokens, which are placeholder labels like 'Speaker 1' or 'Speaker 2' that indicate who said what within that chunk.
Stage two: reconciliation. Here is where the core invention lives. Because each chunk is processed independently, the label assignments are arbitrary and inconsistent across chunks. A sequence processing neural network (a type of AI that reads data in order, similar to how a language model reads sentences) then examines the full set of chunk transcripts and resolves the conflicts. It does this by permuting speaker tokens, meaning it systematically swaps label assignments in specific chunks so that the same real-world person ends up with the same label everywhere.
The patent specifies that the network generates a reconciled long-form diarized transcript as its output. The design avoids re-processing the raw audio, working instead purely from the text-and-label outputs of the first stage, which keeps the computation manageable for arbitrarily long recordings.
… generating a reconciled long-form diarized transcript based on the corresponding short-form diarized transcript generated for each respective audio data segment.
Translation: An artificial intelligence network stitches the smaller labeled chunks back together into one unified transcript.
What this means for transcription and voice AI products
Automatic transcription tools are already widely used for meetings, legal depositions, medical consultations, and podcast production. The speaker-label inconsistency problem is one of the main reasons these transcripts still require human cleanup, especially for recordings longer than about 30 minutes. A reliable fix would make AI-generated transcripts far more useful as standalone documents.
For Google, this capability fits naturally into products like Google Meet, Google Workspace's transcription features, and any voice AI that processes multi-speaker audio. Google keeps filing around long-form audio intelligence suggests the company sees speaker understanding as infrastructure-level work, not a niche add-on. For you as an end user, the practical payoff would be meeting summaries and call records where you can actually trust which name is next to which quote.
Google's 49th filing in Voice & speech AI we've tracked since May follows work like smarter follow-up questions and fixed-speed audio generation.
Source: US 2026/0300624 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
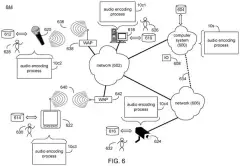
The drawings · 6 sheets
6 drawing sheets from US 2026/0300624 A1 · click any drawing to enlarge


More from Google
All 1,079 Google patents →
More in AI / ML
All 2,637 AI / ML patents →
Nvidia
Nvidia Patents a Speech-to-Text System That Routes Audio Through the Right Processor
Adobe
Adobe Patents a System That Turns a Text Description Into a Full Video
Disney
Disney Patents AI Theme Park Characters That Know When You're Interrupting Them
Microsoft
No comments yet