
IBM
IBM · AI / ML · Filed Mar 25, 2025 · USPTO published Oct 1, 2026 · Oct 1 release
IBM's New Patent Keeps Its AI Current by Watching How Real-World Information Changes
AI models go stale the moment the world changes around them. IBM's new patent describes a system that watches for those changes in real time and automatically decides when and how to retrain the model before the answers get bad.
- Publication number
- US 2026/0300579 A1(US20260300579A1)
- Applicant
- INTERNATIONAL BUSINESS MACHINES CORPORATION
- Filed · Published
- Mar 25, 2025 · Oct 1, 2026
- Inventors
- Gregory R. Hintermeister, Bryan M. Buckland, Chris Moss
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 703/1
What IBM's self-updating AI model system actually does
Have you ever gotten advice from someone who was clearly working from outdated information? That's what happens to AI systems all the time: the data they were trained on gets old, and nobody notices until the predictions start going wrong.
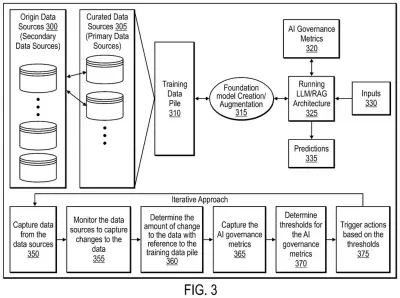
IBM's patent describes a system that keeps an eye on two kinds of data: the information used to train the AI in the first place, and outside data that serves as a signal for what's changing in the real world. When something shifts enough to cross a preset alarm threshold, the system automatically takes action, whether that means retraining the model, fine-tuning it, or flagging it for review.
The idea is to take the burden off your team to manually check whether an AI is still performing well. Instead, the system tracks its own health metrics and responds on its own, so the model you're relying on stays current without constant babysitting.
monitoring data in data sources for changes to the data, wherein the data comprises primary data stored in one or more primary data sources that is used to train a foundation model and secondary data stored in one or more secondary data sources; …
Translation: The system watches multiple data sources for changes to both the core training data and other related information.
How the threshold-and-trigger retraining loop works
The patent describes a foundation model governance loop built around continuous data monitoring and automated response.
At its core, the system watches two categories of data sources:
- Primary data: the training data the foundation model was originally built on.
- Secondary data: external signals (like market data, user behavior patterns, or real-world events) that aren't part of training but indicate whether the model's environment has changed.
The system automatically captures AI governance metrics (think: accuracy scores, fairness indicators, statistical drift measures that show how far the live data has drifted from training data). It then compares these metrics against preset thresholds. Each threshold is paired with a specific trigger action, a predetermined response such as retraining the model from scratch, applying a lighter fine-tuning pass, or alerting a human administrator.
Once a threshold is crossed, the action fires automatically, and the updated model takes over generating predictions. The whole loop is designed to run without manual intervention, making it suited to enterprise environments where AI models are embedded in business-critical workflows and left running for months at a time.
Based on meeting or exceeding a threshold of the one or more thresholds, the trigger action associated with the threshold is performed to update the foundation model.
Translation: When metrics cross a set limit, the system automatically runs a specific action to update the AI model.
What this means for AI reliability in enterprise software
Most enterprise AI deployments today rely on someone manually noticing that a model's performance has degraded, then scheduling a retraining cycle. That gap between when a model goes wrong and when someone fixes it can cost real money in bad decisions.
If this system works as described, it closes that gap automatically. For organizations running AI in finance, healthcare operations, or supply chain forecasting, where stale predictions carry real consequences, IBM keeps filing on AI governance and model reliability, and this patent fits squarely into that track. The practical upside for you as an end user is simple: the AI tools your company relies on would be less likely to degrade over time without anyone realizing it.
IBM's 36th filing we've tracked in our AI training and infrastructure coverage since May joins earlier work including one on training on unclear questions and one on teaching AI to forget.
Source: US 2026/0300579 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 5 sheets
5 drawing sheets from US 2026/0300579 A1 · click any drawing to enlarge


More from IBM
All 470 IBM patents →
More in AI training & infrastructure
All 316 AI training & infrastructure patents →
Qualcomm
Qualcomm Patents a Way to Update On-Device AI Models Without Replacing the Whole File
Qualcomm
Qualcomm Patents an AI System That Verifies Your Identity Across Devices
Google
Google Patents a System That Picks the Right AI Model for Each Question
Microsoft
No comments yet