
Microsoft Files Patent to Stop AI Search Databases From Storing Data Twice
Microsoft's new patent filing splits an AI search index from the storage underneath it, so the same data doesn't get saved twice.
What Microsoft's split-up search index does
Every time you ask an AI-powered search tool for something similar to what you typed, it does two jobs: find the closest matches on a giant map of meaning, then fetch the actual files from storage. Today those two jobs are often glued together, so the same information can end up saved in more than one place.
Microsoft's patent filing pulls them apart. Each item gets a short label built from where it sits on that map, what kind of item it is, and a unique ID. The map stores only that label and a pointer to where the real data lives. The data itself stays in ordinary storage.
One payoff the filing describes: many customers can share the same storage behind the scenes, and the storage can change without the apps on top needing a rewrite.
… convert the first vector into a first prefix by encoding the first vector into a representation specifying a location of the first vector in vector space and a type of the first vector; assign a first vector identifier to the first vector; generate a first index key based on the first prefix and the first vector identifier; …
Translation: It turns the data's mathematical coordinates into a unique tracking tag to map its exact location.
How the address-style key finds your data
The filing describes a way to store data for AI-powered search without tying the search index (the lookup structure that finds matches) to the way the data is physically saved. When a request to store something arrives, the system turns it into a vector, a long list of numbers where items with similar meaning end up close together. If the data is already a vector, that step is skipped.
Then it builds a key in three parts:
- A prefix: a hash (a fixed-length code) of the vector's location in that number space, joined with a label for its type, such as a full vector, a compressed vector, or a list of neighbors. One example uses 15 bytes for the hash and 1 byte for the type.
- A unique vector ID.
- The two combined make the index key, which the index maps to a physical storage address where the data actually sits.
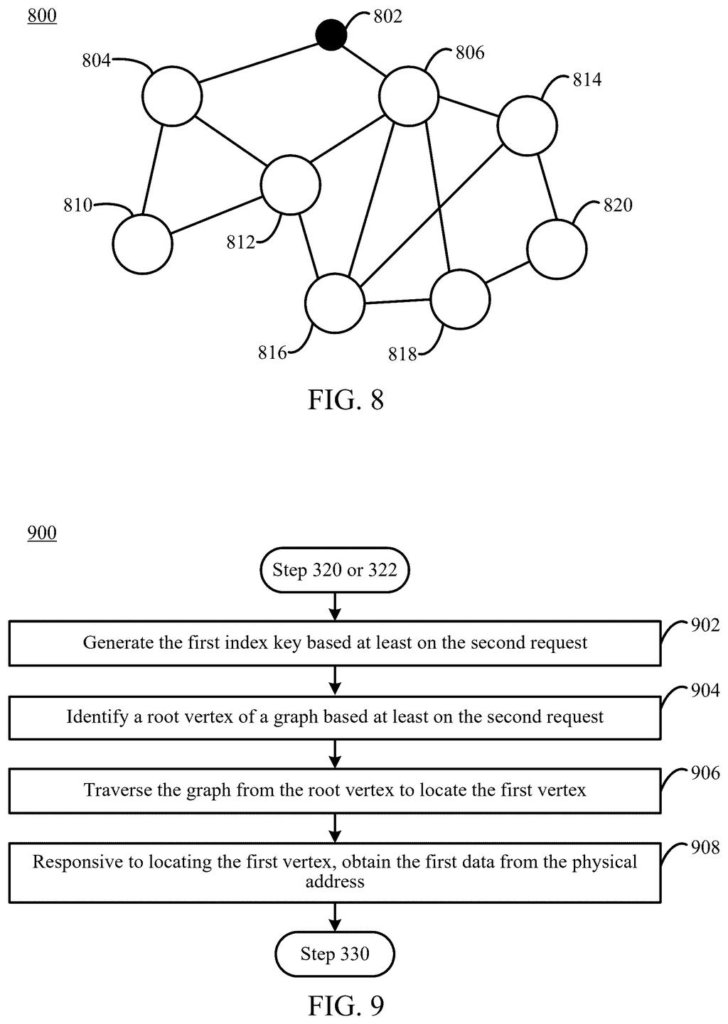
To find something later, the system builds a key from the request, enters the graph (a web of points linked by similarity) at a starting point, and greedily hops to whichever neighbor looks most similar until it lands on the best match. The data is then fetched from its address.
Because the index holds only keys and addresses, the filing says one index can point to several storage systems, each with its own format. That includes compressed copies of vectors, shrunk to save room.
A second index key is generated based on the second request. The second index key is utilized to locate the first index key in the index. The value of the data is returned as a response to the second request.
Translation: When a user searches, the system builds a matching tag to quickly find and pull the stored information.
Why shared storage matters for AI search
If you use any search tool that finds results by meaning instead of exact words, part of its running cost is the storage and memory it eats. The filing says today's designs can save the same full vector in two places, once in the customer's records and again in the search index. That piles up when a provider hosts hundreds or thousands of customers.
Keeping the lookup map apart from storage lets a provider put many customers on shared storage and swap storage systems without forcing customers to rewrite their apps. For you, the effect would mostly be indirect: less overhead for the companies hosting the search, with no change to how you type a query. It is a filing about plumbing, and plumbing is where cloud costs add up.
That makes this Microsoft's 582nd filing in our Microsoft coverage since May, adding to work like chatbot tone control and AI-checked database code.
The problem here is real, and it grows with scale. Search by meaning runs on long lists of numbers, and the filing says those lists get copied into several places, which eats storage and memory. Multiply that by thousands of customers, some of them tiny, and the bookkeeping gets expensive.
The fix matches the size of the problem: a labeling scheme that keeps one copy of the data and a map that points to it. Nothing about it is dramatic, and that suits a cost problem. A key built from an item's position, type and ID is simple, which is what you want from plumbing.
You will never see this on a screen. If it works, you would notice only that the service behind your AI search costs less to run.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
9 drawing sheets from US 2026/0339912 A1 · click any drawing to enlarge


Show the other 1 sheets

Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in