
Nvidia Files Patent to Let Software Tell Where a Moving Sports Camera Is Looking
Every arena paints its court a little differently, and that trips up the software that has to know where a broadcast camera is pointing. Nvidia's filing has the software teach itself, one venue at a time, using the court's own official layout as the answer key.
What Nvidia's court-reading camera patent does
Today, a computer that wants to paint a graphic onto a basketball court during a broadcast has to know exactly where the camera is aimed and how far it is zoomed, at every moment. The usual fixes are motion sensors bolted onto the camera, which take people and time to set up, or software that gets confused because every arena has different colors and logos.
Nvidia's patent application describes a third route. First, software learns what a court looks like from computer-generated courts and some real photos (the filing gives 1,000 synthetic images and 50 real ones as an example). Then, at one specific arena, it practices on that arena's own footage. It guesses where the court's lines and corners are, uses those guesses to work out the camera's position, and then redraws the official court layout on the image to check itself.
Any gap between the guess and the redrawn layout becomes a lesson, so nobody has to hand-label the new court's footage.
… updating, based at least on the one or more first feature points and the one or more second feature points, one or more parameters of the one or more machine learning models to generate one or more fine-tuned machine learning models.
Translation: The system improves its accuracy by comparing what the AI detects against known field markings.
How the model grades its own court guesses
The system works in two stages. A base model (a neural network, meaning software that learns patterns from examples) is first trained on many images of one type of surface, such as basketball courts, to find keypoints: set spots like line intersections. The filing describes training on computer-generated courts with varied colors and logos, then on real photos.
Then comes self-supervised fine-tuning (the model teaches itself, with no human-written answers) for one specific court:
- The model marks keypoints in each image and scores its confidence in each one. The most confident images are picked for training.
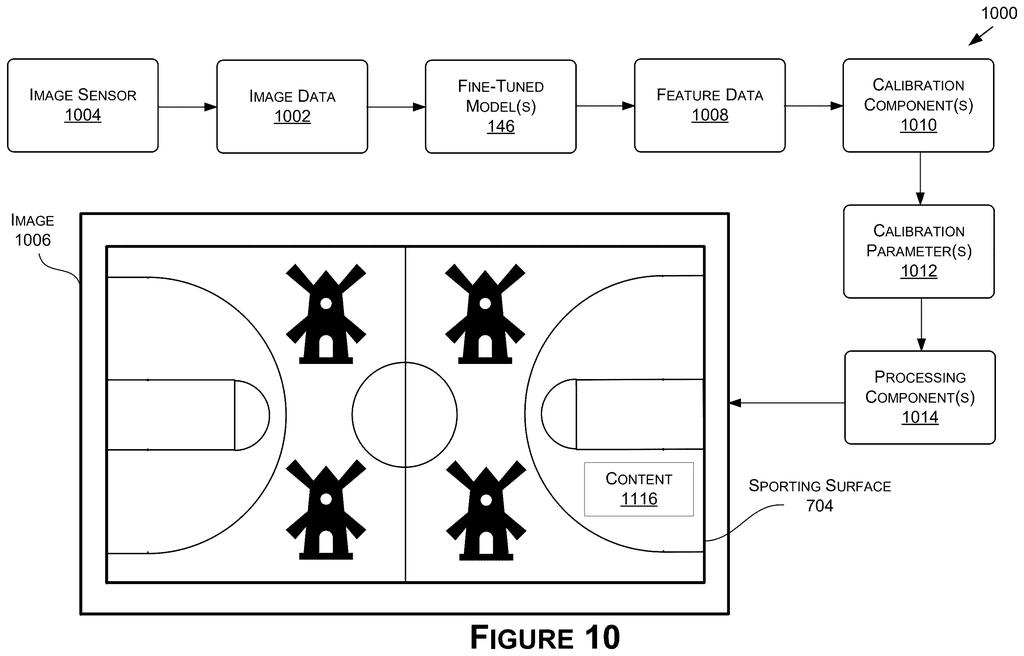
- From those keypoints it computes calibration parameters, the numbers (stored in a matrix) that describe the camera's position, rotation and zoom.
- Using those numbers, it projects the 3D keypoints from a reference layout (the known dimensions and landmarks of that type of court) back onto the image.
- The distance between the model's keypoints and the projected ones becomes the error (the loss), and the model's internal settings are adjusted to shrink it.
That loop can repeat until a set number of rounds passes or accuracy reaches a threshold. Afterward, the tuned model can run on live video, calibrating every frame or every few frames, for tasks such as placing an overlay on the court or locating players. The filing says the same approach could apply to other surfaces with a shared layout, such as warehouse floors or intersections.
Systems and methods described herein may then perform self-supervised fine-tuning of the model(s) for a specific sporting surface that is also associated with the surface layout.
Translation: The software teaches itself how to adjust to a new arena using the permanent lines on the ground.
Why venue-by-venue self-training matters
If it works as described, the practical change is for broadcasters and sports-tech crews. Overlays that sit on the court and tracking of where players stand could be set up with software instead of sensor rigs. The filing says the method avoids specialized hardware and cuts the human labor of preparing a camera for each venue.
For you as a viewer, the effect would show up as on-screen graphics that stay put while the camera pans and zooms, even in an arena with an unusual floor design. Beyond sports, the filing also lists warehouses and road intersections that share a common layout, so the same trick could apply to cameras watching those spaces.
Nvidia's 85th filing in the AI vision patents we cover since May follows one on unlabeled object training and one on cameras in bad weather.
Of everything in this filing, the closest part to a shippable feature is also the least exotic: it is pure software. The camera only needs to supply video, and no new hardware appears anywhere in the design.
A sports team adopting this would need two things ready first: a starting model trained on computer-generated courts plus some labeled real photos, and a file containing the official measurements and landmark positions for their specific sport. The filing offers no accuracy numbers, so there is no way to judge how close this gets to the sensor-based setups it aims to replace.
The shortest path to a real product is narrow but plausible, letting a court's own painted lines grade the model's calibration automatically the first time cameras roll in a new arena. The open question is what happens when players crowd the floor and block those lines, since the filing acknowledges the problem but reports no results.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
16 drawing sheets from US 2026/0330294 A1 · click any drawing to enlarge


Show the other 8 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in