
Nvidia · Filed Jan 20, 2026 · Published Oct 22, 2026

Nvidia Files Patent for an AI Chip Stacked on Memory to Cut Chatbot Lag

Nvidia's filing describes an AI chip that sits directly on top of its memory, so the data a chatbot needs is a short hop away instead of a long trip. The chip also passes results between its own parts on pre-set routes, without parking them in shared storage first.
A grid of processors and fast memory on a chip built to help chatbots answer questions without hesitation. Drawing from patent filing US 2026/0330261 A1.
A grid of processors and fast memory on a chip built to help chatbots answer questions without hesitation.
See all 37 drawings from this filing ↓
Publication number US 2026/0330261 A1 US20260330261A1
Applicant NVIDIA Corporation
Filing date Jan 20, 2026
Publication date Oct 22, 2026
Inventors William James Dally, Po-An Tsai, Brian Matthew Zimmer, Rangharajan Venkatesan
US classification 706/46
Status when we published Waiting for an examiner (Mar 2, 2026)
Parent application Claims priority from a provisional application 63792579 (filed 2025-04-22)
Document 20 claims

What Nvidia's memory-stacked AI chip does

Imagine asking an AI assistant a question and watching it type out the answer one word at a time, pausing between words. Part of that delay comes from the chip fetching data from memory and passing notes between its own parts.

Nvidia's filing describes a chip built to cut those trips. Instead of sitting beside its memory, the chip is stacked directly on memory chips, so data has a short path. Inside, one group of small processing blocks does the math in pieces, and another group combines those pieces into a finished answer for each step.

The pieces travel over a wiring network that is set up in advance for the specific AI model. Results go straight from one block to the next instead of being dropped into a shared storage area first.

From the filing · CLAIM 1
transmitting, by one or more compute tiles fabricated in the LLI device, a read request generated by one or more memory read interfaces within the one or more compute tiles via first electrical contacts to the one or more memory dies to retrieve one or more tensor inputs stored in the one or more memory dies; …

Translation: The chip's processing units send read requests directly into the adjacent memory layers to pull in stored data.

How the chip's tiles pass partial answers along

The filing covers a method for doing the core math of an AI model on a chip that is stacked with one or more memory chips (the claims call it a low-latency inference, or LLI, device). Electrical contacts line up between the layers, so the processor reads its inputs from memory and writes finished results back over short, direct connections.

The work is split between two kinds of blocks:

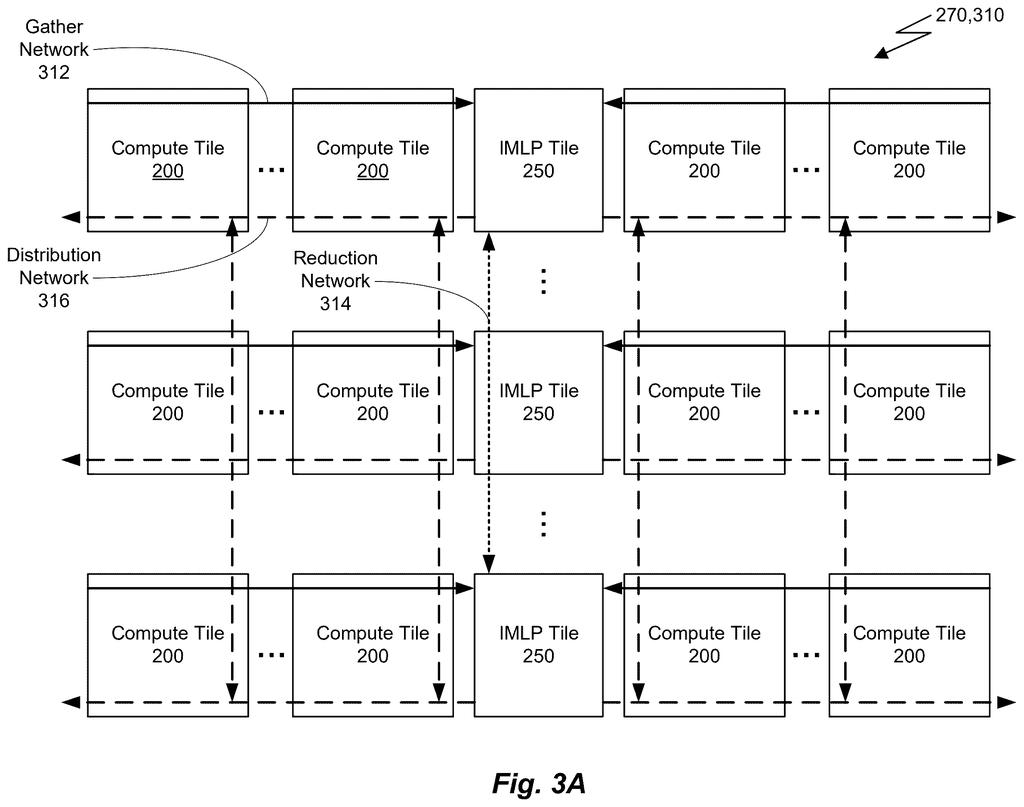
  • Compute tiles read the model's numbers from memory and do matrix math (multiplying big grids of numbers), producing partial results.
  • Inter-matrix layer processing (IMLP) tiles add those partial pieces into reduced results, handle steps like normalizing values, and write the finished answer back to memory.

A configurable network links the tiles. It has a gather network (pieces go to an IMLP tile), a reduction network (IMLP tiles combine their results), and a distribution network (answers are broadcast back to compute tiles). The connections are pre-configured for the model being run, and partial results move tile to tile without being stored in the stacked memory.

The memory also holds the KV cache (the running notes a model keeps about your conversation so far). The filing describes boards of 24 such chips and racks of boards, and puts the chip on top of the memory so more of its surface can shed heat.

From the filing · THE ABSTRACT
The low-latency inference device may be stacked with one or more memory die for storing tensor inputs, KV cache data, activations, and other neural network-related information required for inference.

Translation: Placing the AI chip directly on top of memory dies keeps chat history and model data close at hand to speed up responses.

Why faster chatbot replies depend on memory

If you use a chatbot, voice assistant or live translator, part of the wait between your question and the answer comes from chips shuffling data around. A design that keeps data close and skips parking results in shared memory could shorten that wait and cut the power a data center burns doing it. The filing lists language models, self-driving simulation and AR among possible uses, though its detailed examples center on language models.

In the filing's example system, regular graphics processors handle reading your prompt while these chips generate the reply one word at a time. That split shows how Nvidia is thinking about dividing inference work between different kinds of hardware. Whether it ever ships is unknown, since a patent application describes a design, not a product.

Nvidia's 53rd filing we've tracked in the AI chip wars since July builds on one cutting data shuffling and one on shared chip memory.

Editorial take

The big trade here is flexibility for speed. Wiring the chip's pathways in advance for one specific AI model removes a lot of waiting, but it also builds the chip around a known recipe. If the models change shape, the chip needs new setup, and a pre-planned route cannot adapt on the fly the way a general-purpose chip can.

Stacking the chip on memory has its own cost: heat. Piling chips on top of each other makes warmth harder to get out, and the filing puts the compute layer on top so more of its surface can cool off. That helps, and it also limits how hot the chip can run.

The trade reads as worth it for one job: answering chatbot prompts quickly in a data center, where the same models run all day. For anything else, expect a narrower tool than a regular graphics chip.

Get our take in your Top Stories

Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.

There are more where this came from

We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.

The drawings

37 drawing sheets from US 2026/0330261 A1 · click any drawing to enlarge

How an AI system turns user prompts into generated words, drawing sheet 1 from US 2026/0330261 A1
Sheet 1 How an AI system turns user prompts into generated words
Steps the AI chip runs to calculate each response, drawing sheet 2 from US 2026/0330261 A1
Sheet 2 Steps the AI chip runs to calculate each response
Building blocks pairing onboard memory with math circuits, drawing sheet 3 from US 2026/0330261 A1
Sheet 3 Building blocks pairing onboard memory with math circuits
Multiple math units wired together to share data quickly, drawing sheet 4 from US 2026/0330261 A1
Sheet 4 Multiple math units wired together to share data quickly
Adding circuits combine math results across rows of units, drawing sheet 5 from US 2026/0330261 A1
Sheet 5 Adding circuits combine math results across rows of units
Internal parts of a specialized tile that coordinates calculations, drawing sheet 6 from US 2026/0330261 A1
Sheet 6 Internal parts of a specialized tile that coordinates calculations
Grouping processor tiles around a hub to speed tasks, drawing sheet 7 from US 2026/0330261 A1
Sheet 7 Grouping processor tiles around a hub to speed tasks
Linking stacks of compute groups into a flexible chip network, drawing sheet 8 from US 2026/0330261 A1
Sheet 8 Linking stacks of compute groups into a flexible chip network
Show the other 29 sheets
How worker cores feed answers into a central hub, drawing sheet 9 from US 2026/0330261 A1
Sheet 9 How worker cores feed answers into a central hub
Connecting central hubs across the chip to tally results, drawing sheet 10 from US 2026/0330261 A1
Sheet 10 Connecting central hubs across the chip to tally results
Sending fresh chatbot data across rows and columns of cores, drawing sheet 11 from US 2026/0330261 A1
Sheet 11 Sending fresh chatbot data across rows and columns of cores
Internal switches steering data into a single worker core, drawing sheet 12 from US 2026/0330261 A1
Sheet 12 Internal switches steering data into a single worker core
Wiring clusters of processing hubs across a full AI chip, drawing sheet 13 from US 2026/0330261 A1
Sheet 13 Wiring clusters of processing hubs across a full AI chip
Steps the chip hardware takes to generate chatbot words, drawing sheet 14 from US 2026/0330261 A1
Sheet 14 Steps the chip hardware takes to generate chatbot words
Splitting math chores across groups of cores to save time, drawing sheet 15 from US 2026/0330261 A1
Sheet 15 Splitting math chores across groups of cores to save time
Combining partial answers inside a hub to speed replies, drawing sheet 16 from US 2026/0330261 A1
Sheet 16 Combining partial answers inside a hub to speed replies
Distributing math workloads across tiles to speed up responses, drawing sheet 17 from US 2026/0330261 A1
Sheet 17 Distributing math workloads across tiles to speed up responses
Overlapping chatbot calculations in time to reduce delays, drawing sheet 18 from US 2026/0330261 A1
Sheet 18 Overlapping chatbot calculations in time to reduce delays
Linking multiple AI chips together in a high-speed grid, drawing sheet 19 from US 2026/0330261 A1
Sheet 19 Linking multiple AI chips together in a high-speed grid
Combining chip clusters with memory to handle heavy AI workloads, drawing sheet 20 from US 2026/0330261 A1
Sheet 20 Combining chip clusters with memory to handle heavy AI workloads
Connecting user devices to cloud servers that run AI models, drawing sheet 21 from US 2026/0330261 A1
Sheet 21 Connecting user devices to cloud servers that run AI models
Streaming AI generated visuals from remote servers to a display, drawing sheet 22 from US 2026/0330261 A1
Sheet 22 Streaming AI generated visuals from remote servers to a display
Stacking memory dies directly on top of the AI chip, drawing sheet 23 from US 2026/0330261 A1
Sheet 23 Stacking memory dies directly on top of the AI chip
Flipping the stack so the AI chip sits on top, drawing sheet 24 from US 2026/0330261 A1
Sheet 24 Flipping the stack so the AI chip sits on top
An AI chip mounted on top of stacked memory dies, drawing sheet 25 from US 2026/0330261 A1
Sheet 25 An AI chip mounted on top of stacked memory dies
Multiple memory stacks placed across a single AI chip, drawing sheet 26 from US 2026/0330261 A1
Sheet 26 Multiple memory stacks placed across a single AI chip
Stacking a single memory die over the AI chip, drawing sheet 27 from US 2026/0330261 A1
Sheet 27 Stacking a single memory die over the AI chip
Placing the AI chip directly onto a wider memory die, drawing sheet 28 from US 2026/0330261 A1
Sheet 28 Placing the AI chip directly onto a wider memory die
Distributing several memory dies across the AI chip, drawing sheet 29 from US 2026/0330261 A1
Sheet 29 Distributing several memory dies across the AI chip
How processing blocks share memory contacts across the chip, drawing sheet 30 from US 2026/0330261 A1
Sheet 30 How processing blocks share memory contacts across the chip
Inside the specialized unit that pools and moves data, drawing sheet 31 from US 2026/0330261 A1
Sheet 31 Inside the specialized unit that pools and moves data
Wiring two sets of memory contacts to each compute section, drawing sheet 32 from US 2026/0330261 A1
Sheet 32 Wiring two sets of memory contacts to each compute section
Internal parts of a single calculation block on the chip, drawing sheet 33 from US 2026/0330261 A1
Sheet 33 Internal parts of a single calculation block on the chip
Connecting memory controllers to stacked storage above, drawing sheet 34 from US 2026/0330261 A1
Sheet 34 Connecting memory controllers to stacked storage above
Grid layout of memory base units across the chip, drawing sheet 35 from US 2026/0330261 A1
Sheet 35 Grid layout of memory base units across the chip
Simplified layout using fewer memory controllers per unit, drawing sheet 36 from US 2026/0330261 A1
Sheet 36 Simplified layout using fewer memory controllers per unit
How stacked memory dies exchange data with the processor, drawing sheet 37 from US 2026/0330261 A1
Sheet 37 How stacked memory dies exchange data with the processor
Browse all the drawings 37 drawing sheets
Patent filing page

Source. Full patent text and figures from the official USPTO publication PDF.
Reader comments

Be the first to weigh in

Start the discussion

Real name or a handle, either is fine. Comments are read by a person before they appear, so allow a little time. Keep it about the filing.