
Adobe Files Patent to Speed Up AI Image Generation by Shrinking the Middle Steps
Adobe's filing describes an AI image generator that shrinks its own work in the middle of the process, then expands it back out. In some versions, a picture could appear in under a second.
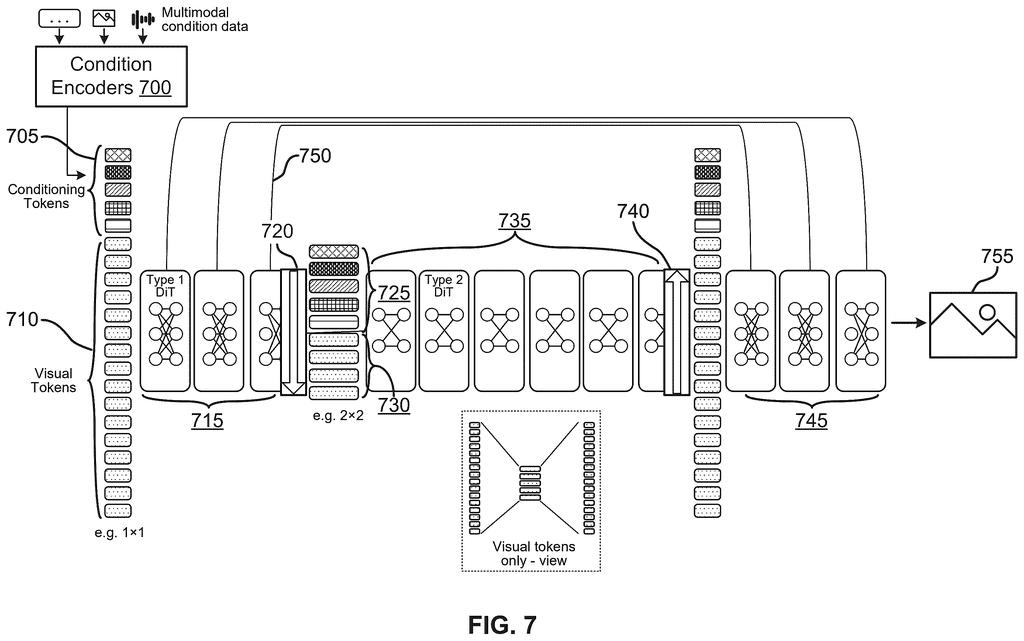
What Adobe's squeeze-the-middle image design does
Ever tried to proofread a long report by checking every sentence against every other sentence? Double the length and the work roughly quadruples. AI image generators have a similar problem: they chop a picture into small pieces and compare each piece with all the others, over and over.
Adobe's patent application describes a design that zooms out in the middle. The model starts with small, fine pieces, bundles them into bigger and fewer chunks for the heavy middle work, then spreads them back into small pieces at the end. A shortcut carries the fine detail from the early steps straight to the late ones, so the picture keeps its sharpness.
Adobe also describes training a small, fast model to copy a bigger, slower one, so you could get a finished picture in a few passes instead of dozens.
… generating, using a first transformer block of an image generation model, a first set of intermediate tokens having a first patch size based on the input prompt; …
Translation: The AI creates an initial set of data chunks from your text prompt using a primary processing block.
How the model shrinks, then restores the picture
The claims cover an image generator built from several transformer blocks (processing stages that use attention, a way of letting every piece of the image consider every other piece). The first block works on tokens (the numeric stand-ins for small patches of the image) at one patch size. The second block works on tokens at a different patch size, built from the first block's output.
The filing's main example is a U-Net diffusion transformer, or UDiT:
- Early blocks work on small patches, which keeps fine detail.
- A downsampling layer squeezes those into larger patches: fewer tokens, but each one carries more numbers (a higher embedding dimension).
- Middle blocks do the heavy attention work on that shorter list.
- An upsampling layer expands everything back, and final blocks finish the image. A skip connection (a direct shortcut) carries early detail forward.
Attention cost grows with the square of the token count, so a shorter list in the middle saves a lot of work.
The filing also covers training by distillation: a big "teacher" model that needs 50 to 1000 denoising steps (rounds of cleaning noise out of the image) guides a "student" that needs 1 to 4. The training score is a distribution matching loss, which nudges the student's range of outputs toward the teacher's. At generation time, the teacher can handle the first few steps and the student the rest.
Why faster image generation matters for Adobe
Waiting is the part of AI image tools you actually feel. The filing says the teacher design needs 50 to 1000 passes, while the trained fast version needs 1 to 4, and in some versions an image could appear in under a second. That would matter the next time you try a prompt, dislike the result and try again.
It also matters to whoever pays for the computers. Fewer passes and a shorter list of pieces to compare means less processing per picture, and the filing says the same design could apply to video. For Adobe, whose business is creative tools, cheaper and quicker generation is a practical edge. A patent application is no promise of a product, though.
Adobe's 44th filing in our AI image and video work we've tracked since May follows one on sharpening subject edges and one on fast-slow AI training.
Every shortcut in image generation costs something, and this one pays in fine detail. Squeezing the picture into bigger chunks in the middle means the model briefly works with a coarser view of small features.
Adobe's answer is extra layers to squeeze and expand, plus a direct shortcut that carries early detail past the middle. Those parts add complexity, and the filing gives no measured results for how much sharpness survives. It only says quality is comparable or better than standard designs.
The other cost sits in training. The fast model learns from a slower, bigger teacher, so someone still has to build and run that teacher first. The hybrid option brings the teacher back for the early steps, which gives up some speed for safer results on odd prompts. For a tool people use all day, where waiting is the thing they notice, those trades look reasonable.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Adobe patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
13 drawing sheets from US 2026/0330605 A1 · click any drawing to enlarge


Show the other 5 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in