

Amazon
Amazon · AI / ML · Filed Mar 20, 2025 · USPTO published Sep 24, 2026 · Sep 24 release
Amazon Patents a Database That Speeds Up AI Search Across Stored Data
Reading and writing data at the same time is one of database engineering's oldest headaches. Amazon's new patent tries to solve it specifically for the AI-era problem of searching by meaning, not by exact keyword.
- Publication number
- US 2026/0288687 A1(US20260288687A1)
- Applicant
- Amazon Technologies, Inc.
- Filed · Published
- Mar 20, 2025 · Sep 24, 2026
- Inventors
- Marc Brooker, Mrithyunjaya Kumar Annapragada, James Alexander Morle
- Status when we published
- Rejected again; the company can still amend or appeal
- Document
- 20 claims
- US classification
- 707/715
- Examiner
- JAMI, HARES (Art Unit 2164)
What Amazon's split-tier AI database actually does
You're using an app that searches a product catalog by describing what you want in plain language. Behind the scenes, the app is constantly receiving new products and answering your search at the same moment. Doing both things well in a single database is surprisingly hard.
Amazon's patent describes a database split into three zones, called tiers. New data lands in the "hot" tier, which is built to accept writes quickly. Searches pull results from all three tiers at once and combine them. Over time, older data migrates in batches to a "medium" tier and eventually a "cold" tier, each one tuned to return search results faster than the last.
The key idea is that no single tier has to do everything. The hot tier doesn't have to be fast at searching; the cold tier doesn't have to be fast at writing. Your search still gets a complete answer because the system stitches the results together before handing them back to you.
the cold tier is read-optimized, relative to the hot tier, to retrieve a given one or more of the data items based on a given search vector; the hot tier is write-optimized, relative to the cold tier, to perform transactions to store incoming data items and associated vector labels …
Translation: The system splits storage between one tier built for fast reading and another built for fast writing.
How hot, medium, and cold tiers divide the work
This patent covers a vector-labeled database (a database where each piece of data gets a numeric fingerprint, called a vector, that represents its meaning or content) split into three distinct tiers.
The hot tier is write-optimized. When new data arrives, it lands here first because this tier is structured to accept a high volume of incoming records without slowing down. The tradeoff is that searching the hot tier is slower and less efficient.
The cold tier is read-optimized, meaning its internal data structures are tuned for fast similarity searches (finding vectors whose numeric values are closest to a given query vector). Data moves to the cold tier in batches, not in real time. A medium tier sits between the two, balancing read and write performance for data that is neither brand new nor old enough to archive.
When a query arrives, the system searches all three tiers simultaneously. Each tier returns a candidate list of vectors. The system then merges those lists and picks the final results by measuring the distance between each candidate vector and the query vector. Shorter distance means closer meaning, so the nearest neighbors win.
- Hot tier: fast writes, slower searches, always current
- Medium tier: balanced reads and writes, transitional data
- Cold tier: fast reads, batch-updated, most of the historical data
A vector-labeled database, which stores data in association with multi-dimensional vectors, comprises a hot tier which is optimized for writes, a cold tier which is optimized for reads, and a medium tier which is optimized to balance reads and writes.
Translation: The database uses three distinct tiers to handle incoming writes and stored data searches efficiently.
What this means for AI-powered search at cloud scale
Vector databases are the backbone of most AI-powered search, recommendation, and retrieval systems today. They let apps find things by meaning rather than exact text match. The problem is that most vector database designs force an ugly choice: optimize for writing new data or for reading it back quickly, not both at once.
For Amazon, which runs AWS and powers countless real-time applications, this tension matters at enormous scale. Amazon's bet on AI infrastructure makes tiered approaches like this one a natural building block. If this design works as described, services like product recommendations, document search, and AI assistants could handle far higher update rates without degrading search quality for your queries.
Amazon's fourth Language AI filing we've tracked since May follows earlier applications on a faster AI database search and turning plain text into video.
Source: US 2026/0288687 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Amazon patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 15 sheets
15 drawing sheets from US 2026/0288687 A1 · click any drawing to enlarge


Show the other 7 sheets


More from Amazon
All 111 Amazon patents →
More in AI / ML
All 2,637 AI / ML patents →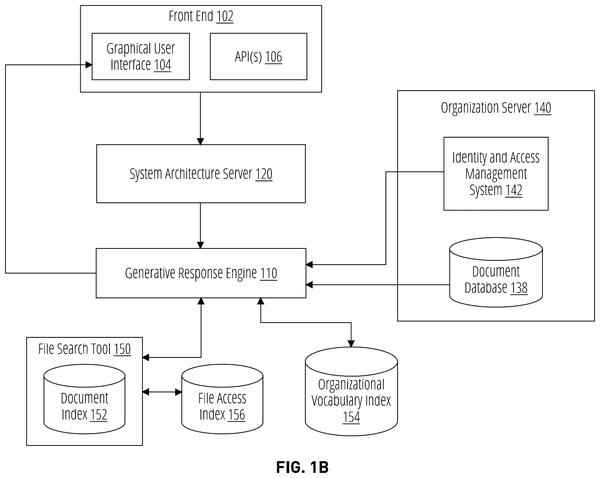
OpenAI
OpenAI Patents a Way for Its AI to Answer Questions Using Company Documents Securely
Google
Google Patents an AI That Fetches One-Time Login Codes From Your Email
Microsoft
Microsoft Patents an AI Engine That Writes Animation Instructions From Plain Text
Microsoft
No comments yet