
AMD
AMD · Chip · Filed Mar 31, 2025 · USPTO published Oct 1, 2026 · Oct 1 release
AMD Patents a Chip That Picks Its Own Best Code Path While Running
Every GPU instruction set contains dozens of ways to do the same job, and choosing the wrong one can waste a huge chunk of processing power. AMD is patenting hardware that auditions its own code paths on the fly and locks in the winner.
- Publication number
- US 2026/0300012 A1(US20260300012A1)
- Applicant
- Advanced Micro Devices, Inc.
- Filed · Published
- Mar 31, 2025 · Oct 1, 2026
- Inventors
- Johannes Manfred DIETERICH, Gurunath Anandrao KADAM
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 719/330
What AMD's runtime kernel-picker actually does for you
Every time a program hands a big math job to a GPU, the chip has to pick a specific recipe for doing that work. Those recipes are called kernels, and there are usually many versions of each one. Picking the wrong version means slower results, higher power use, or both, and the "right" choice can change depending on the job size, the data, and the hardware.
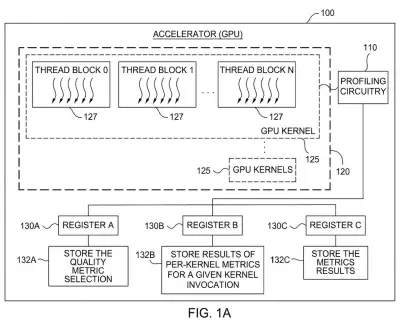
AMD's patent describes extra circuitry built into the chip itself that watches several kernel options run in real time, scores them on quality metrics like speed and efficiency, and then automatically switches to whichever one is winning. You don't have to do anything. The chip is essentially running a quiet competition among its own code recipes while your program is already executing.
The practical idea is that the chip stops relying on developers or drivers to pre-select the best approach. Instead, it samples performance during your actual workload and adapts on the spot.
sample, using profiling circuitry, a kernel space including multiple kernels to evaluate the multiple kernels based on one or more quality metrics; identify an optimal kernel from the multiple kernels in the kernel space; and use the optimal kernel for a computation task.
Translation: The chip tests multiple versions of code while running and instantly switches to the best performing one.
How the profiling circuitry samples and scores each kernel
The patent describes an accelerator (a specialized chip or chip block, like a GPU or AI processor) that contains dedicated profiling circuitry. During normal program execution, that circuitry doesn't just run a single kernel; it samples across a kernel space, meaning it evaluates multiple candidate implementations of the same computation.
Each kernel is judged against one or more quality metrics. The patent doesn't lock in specific metrics, but the language covers things like execution time, throughput, and resource usage. The profiling circuitry monitors and analyzes how each kernel behaves specifically during the live computation task, not in a synthetic pre-run benchmark.
Once the circuitry identifies the optimal kernel from that evaluated set, the accelerator commits to it for the task at hand. Key things to note about the design:
- All of this happens at runtime, not at compile time or driver installation.
- The selection is tied to the user's specific computation task, not a one-size-fits-all default.
- The profiling hardware is built into the accelerator itself, so it doesn't rely on external software to make the call.
This is different from existing approaches where software libraries (like AMD's ROCm or Nvidia's CUDA tuning tools) pre-select or offline-tune kernels before a workload runs. Here, the hardware is doing the tuning loop itself, in the moment.
The profiling circuitry monitors and analyzes how the multiple kernels behave during execution of the computation task.
Translation: Built-in monitors watch how different code options perform while the processor is actually doing work.
What self-tuning hardware means for GPU workloads
For AI training and scientific computing, kernel choice can swing performance by 20-40% on the same hardware. Today, getting that choice right requires software engineers to run offline benchmarks, update driver configs, or use auto-tuning libraries that add setup time. If AMD can move that decision into the chip itself, workloads could self-optimize without any developer intervention.
For everyday users, the impact would show up as faster AI inference on AMD hardware, better GPU utilization in games that use compute shaders, and lower power draw for the same output. Whether this circuitry appears in a discrete GPU, an AI accelerator card, or an integrated chip is an open question, but the patent covers all of those targets.
AMD's 19th filing we've tracked since June in our GPU rendering race watch adds to earlier work on finding triangles faster and stopping mid-scene stalls.
Source: US 2026/0300012 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time AMD patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 7 sheets
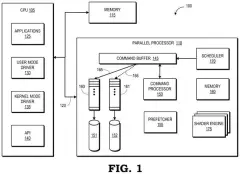
7 drawing sheets from US 2026/0300012 A1 · click any drawing to enlarge


More from AMD
All 119 AMD patents →
More in Chip
All 651 Chip patents →
Qualcomm
Qualcomm Patents a Self-Correcting Method for Generating Images That Look Photographed
Nvidia
Nvidia Patents a Way to Keep Graphics Data on the Right Chip
Nvidia
Nvidia Patents a Way to Stop Multi-Chip GPUs from Talking Over Each Other
Qualcomm
No comments yet