
Google Patents an AI That Does the Research When You Ask About a Photo
Google's filing describes an AI that treats a question about your photo like a research assignment: it looks, searches, checks what it found, and backs up if a lead goes nowhere.
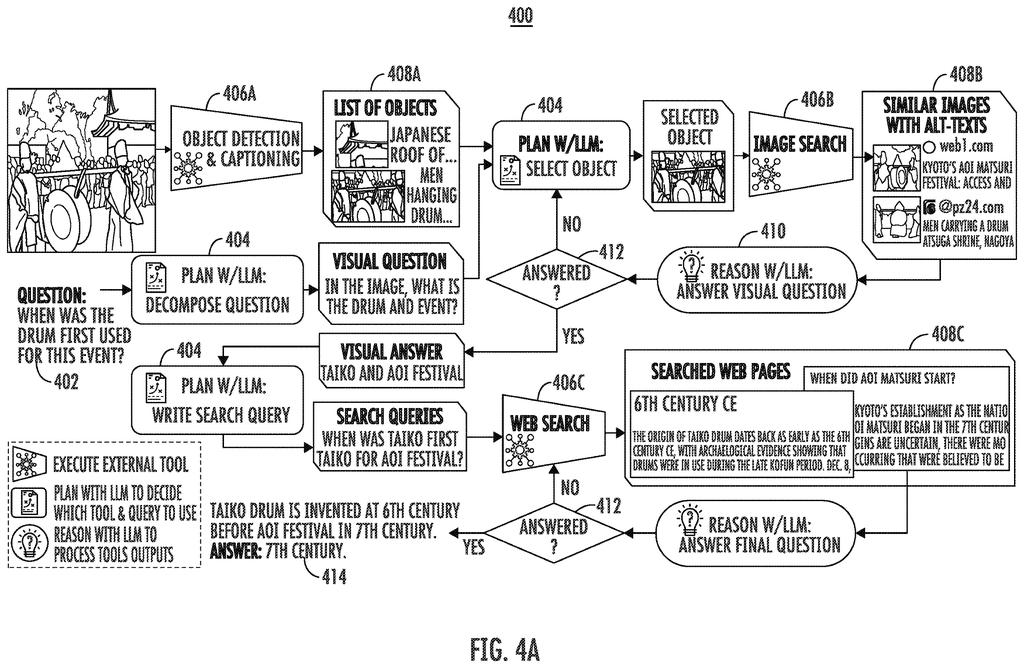
What Google's photo-question AI actually does
You're on a trip, you snap a photo of a building you don't recognize, and you ask your phone, "What event does this commemorate?" Typing a search is hard because you don't know what to call the thing. Google's filing says language models on their own also struggle with this kind of question about a picture.
So Google describes an AI that works more like a detective. It first figures out what's in the photo, then decides what to look up, reads what comes back, and chooses its next move. If a lead is a dead end, it backs up and tries another.
Along the way it writes its own search questions. In one example from the filing, a photo of a parade drum becomes a web search about when that drum was first used at a specific festival. Only after that does the AI give you a plain-text answer.
… processing the input data with a machine-learned model to generate first planning data, wherein the first planning data is descriptive of instructions to provide the input data to a first data processing tool; …
Translation: The AI figures out which external tool to use first based on your photo and question.
How the AI picks its next lookup, step by step
The system takes a photo plus a text question about it. In claim 1, a language model reads both and writes planning data, which is a set of instructions telling the system which tool to use first. The filing describes these as API calls (requests sent to another piece of software). The tool's output goes back to the model, which writes a second round of planning data for a second tool. Then the model writes the final answer.
The filing splits the AI into three parts:
- Planner: decides which tool to use next and what to ask it.
- Reasoner: reads each tool's output and judges whether it is useful, useless, or a final answer.
- Working memory: keeps everything found so far.
The first tool is often an object detector, which draws bounding boxes (outlines) around things in the photo and captions each cropped piece. The model might then send one cropped piece to an image search, or send a question it wrote itself to a web search. Claims 11 and 17 specifically require sending a particular portion of the image to the second tool.
To teach the model good habits, the filing describes a user study where people chose tools step by step. Their choices became a transition graph (a map of which moves make sense after which) and a set of examples. Planning one step at a time, the filing says, avoids pointless tool calls, and the loop can run five or more times.
The one or more machine-learned models may iteratively process data to generate planning data that may include application programming interface calls to the one or more data processing tools.
Translation: The system repeatedly talks to other software tools to gather all the facts needed for an answer.
Why photo questions could get easier to ask
The practical payoff is a camera that answers questions you couldn't easily type. The filing's examples are things like "what species of butterfly is this?" and "how do you make this thing?" The filing says the answer could appear in a panel next to regular search results, and it lists smartphone cameras and smart glasses as sources of the photo.
It also shows where AI help is heading: from answering from memory to doing the lookup work across several tools and checking its own progress. The filing's main efficiency argument is that deciding each step after seeing the last result wastes fewer searches than mapping out the whole plan in advance.
Google's 47th filing we've tracked since May in our AI agents acting for you watchlist builds on earlier ideas like one turning sensor data into actions and one writing formulas from examples.
Claim 1 is broad. It needs a photo, a typed question, and a language model that picks one lookup, reads the result, then picks a second lookup based on it. It never names the tools, so object detection and web search show up only in the narrower claims underneath.
That wording would cover almost any photo-question assistant that chains two lookups. It also leaves out the backtracking and the human-study training that the description spends so much time on. Claims 11 and 17 are tighter: they require the model to send only a cropped piece of the photo to the second tool.
Claim 1's breadth is its selling point and its weak spot. "Ask, look something up, look something else up" describes a lot of AI helpers people already use, so expect the claim to get narrowed if it moves forward.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
14 drawing sheets from US 2026/0310717 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in