
Google Files Patent for Sizing AI Models to Fit Any Computing Budget
Training an AI model is expensive, and picking the wrong shape wastes a lot of that money. Google's patent application describes a way to test small models cheaply, learn how each part should grow, and then scale up to the budget you can actually afford.
What Google's AI-model sizing recipe does
Today, nobody has a clean rule for how deep, wide or bulky to make an AI model. Google's filing calls it an open problem, and the usual workaround is to train lots of costly test versions and see which one wins. Google's patent application describes a shortcut for teams that already know their computing budget, meaning how much processing power they can afford to spend.
The idea runs in two parts. First, train a batch of tiny models, which is cheap, to find a good basic design. Second, train a handful of bigger ones, changing one trait at a time, to learn how fast each trait should grow as the budget grows. Then you scale the tiny design up using that growth rule.
In the filing's example, the resulting image model held its own against an earlier one with 2.5 times more parts to tune, trained on the same budget.
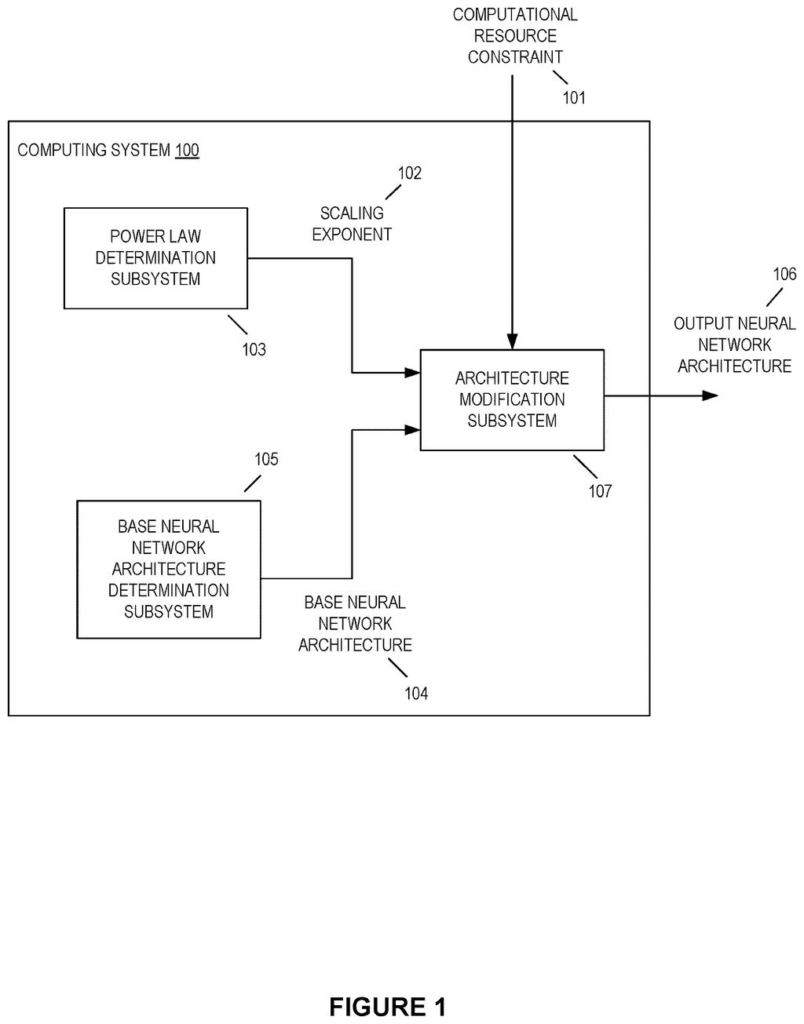
… modifying the one or more architecture dimensions of the base neural network architecture based upon the corresponding scaling exponents, a computational resource utilization of the base neural network architecture and the given computational resource constraint to provide an output neural network architecture.
Translation: It scales the base design using those math rules to fit your exact hardware budget.
How Google tests small models to size big ones
The patent describes a two-stage method for choosing the shape of a neural network (the layered math system behind modern AI) when you are handed a fixed compute budget (how much processing power you can spend, often counted in floating-point operations, a tally of basic math steps).
In stage one, the system picks each shape dimension it wants to adjust. In a Transformer-style network, those are depth (the number of repeating blocks), width (the size of the internal representation of each input piece) and MLP size (the size of one sub-layer inside each block). For each dimension it trains several networks that are identical except for that one value, spaced about 20% apart in the filing's example.
- It fits a power law (a curve where results change by a steady ratio as the inputs grow) linking performance, that dimension and compute.
- From the curve it pulls a scaling exponent, a ratio of the curve's exponents that says how fast that dimension should grow.
In stage two, it trains many smaller candidate networks with different shapes on a lighter budget. It picks the best one as the base architecture, using a grid search (trying every combination on a preset list). The two stages are independent and can run in any order or in parallel.
Finally, it divides your budget by the base model's compute to get a scale factor, then grows each dimension by that factor raised to a power tied to its exponent. For image classification, the filing reports exponents of about 0.22 for width, 0.45 for depth and 0.6 for MLP size. It also says 115 training runs can tune three dimensions, versus 400 runs for one dimension in earlier work.
Why cheaper AI model design matters for Google
Training a large AI model can cost a fortune, and guessing its shape wrong means paying for a worse result. A recipe that gets to a good design with far fewer trial runs saves money and time. The filing also says a model sized this way can have fewer parts to tune, so it costs less to run once people are using it.
You would never see this as a feature, but you could feel it indirectly. The filing lists tasks like labeling photos, captioning images, recognizing speech and translating text, all of which depend on models sized to fit real hardware. It names Google's own chips (TPUs), graphics chips and phones as possible targets. Better sizing could mean the same quality for less computing, or better quality for the same price.
Google's 52nd filing we've tracked in AI training and infrastructure since May builds on low-data AI training and industry-tuned ad agents.
Claim 1 is broad on the subject and picky on the steps. It applies to any machine learning task and any number of adjustable dimensions, so it covers more than photos, language or any single product. Image work only shows up in later claims, and the Transformer design (the layout behind most current AI) appears only in claim 18.
What the claim demands is a specific three-part sequence: fit a curve for each dimension using models that differ in only that dimension, pick a base design from a batch of smaller models trained on a lighter budget, then scale that base by the curve's exponent. If granted, it would reach anyone who sizes a model by that exact sequence. A team that skips the small-model stage or the curve fitting would appear to sit outside the wording.
Verdict: a useful engineering recipe for a very specialized audience, and nothing you will notice as a user. Its value is saving training runs, and the number that carries the pitch is 115 runs for three dimensions versus 400 for one.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
3 drawing sheets from US 2026/0320392 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in