
IBM
IBM · AI / ML · Filed Mar 26, 2025 · USPTO published Oct 1, 2026 · Oct 1 release
IBM Patents a System That Trains AI to Answer Questions About Stored Data
Most databases speak a language only developers know. IBM's new patent describes a way to automatically build the training material an AI needs to bridge that gap, so anyone can ask a database a question in plain English and get a real answer.
- Publication number
- US 2026/0300274 A1(US20260300274A1)
- Applicant
- International Business Machines Corporation
- Filed · Published
- Mar 26, 2025 · Oct 1, 2026
- Inventors
- Timothy Rea DINGER, Alfio Massimiliano GLIOZZO, Nhan Huu PHAM, Oktie HASSANZADEH, Dharmashankar SUBRAMANIAN, Lisa AMINI, Gaetano ROSSIELLO, Md Faisal Mahbub CHOWDHURY, Long VU, Tanvi KAPLE, Michael Robert GLASS
- Status when we published
- Company responded; back with the examiner
- Document
- 21 claims
- US classification
- 707/759
- Examiner
- TRUONG, DENNIS (Art Unit 2164)
What IBM's natural-language database query tool actually does
A database administrator stares at a screen full of tables, columns, and code. Everyone else at the company just wants answers, but getting them still requires knowing a specialized query language called SQL.
This patent describes a method for automatically generating the training data an AI model needs to understand plain-English questions and convert them into proper database queries. The system reads a database's structure (its layout of tables and fields) and uses that structure to create matched pairs: a question in plain English alongside the correct technical query that would answer it. Those pairs can then train an AI to handle real questions from real people.
The key idea is that IBM's system does this work automatically, tailored to whatever specific database you point it at. Instead of hiring experts to hand-write thousands of example questions for each new database, the system generates them on its own.
… determining, by the processor set and based on the database schema, a group of database concept sets for the target database, wherein each database concept set, of the group of database concept sets, includes a primary concept and a set of secondary concepts relating to the primary concept; …
Translation: The system figures out main ideas and related topics based on how the database is structured.
How IBM maps database concepts to query-language pairs
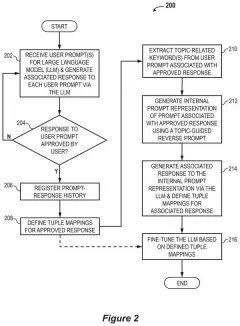
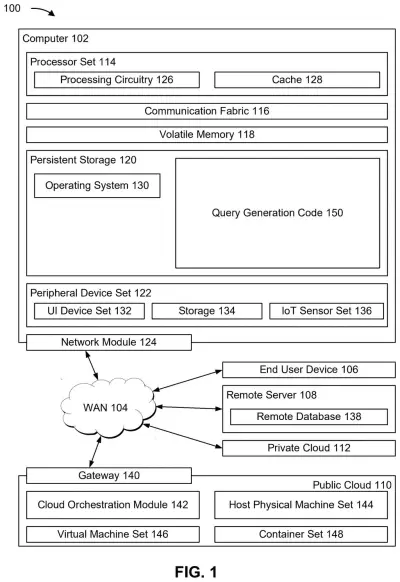
The patent describes a pipeline that starts by reading a database schema (the blueprint describing what tables, columns, and relationships a database contains). From that schema, the system identifies database concept sets, each built around a primary concept (say, "customer orders") and a cluster of related secondary concepts (order dates, product IDs, shipping addresses).
Using those concept clusters, the system generates two parallel sets of query fragments:
- First query parts: fragments written in natural language, like "how many orders were placed last month"
- Second query parts: the matching technical database commands (SQL statements) that would actually retrieve that information
The output is a structured dataset of matched pairs. That dataset becomes training material for an AI model learning to translate between human language and database language.
The process is meant to be automatic and schema-aware, meaning it adapts to the specific layout of whichever database it reads. That matters because no two enterprise databases are structured the same way, and a model trained on one company's data won't automatically understand another's.
… wherein the group of first query parts includes one or more natural language query parts and wherein the group of second query parts includes one or more corresponding query language query parts.
Translation: It pairs everyday human questions with the technical computer code needed to search the database.
What this means for non-technical database users
Most workers who need data from a company database still have to go through a developer or data analyst to write the actual query. That bottleneck slows decisions and creates backlogs. A well-trained AI that converts plain questions into queries could let any employee get their own answers directly.
The challenge has always been training that AI. Building good training data by hand is expensive and slow, especially when a company swaps databases or restructures its data. IBM's patent is aimed squarely at that cost. IBM's track record in natural-language AI patents goes back years, and this filing extends that work into the specific problem of database access for non-technical users.
IBM's 38th filing in the AI training and infrastructure patents we've tracked since May adds to earlier work like one on industry-based learning and one on live data tracking.
Source: US 2026/0300274 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 7 sheets
7 drawing sheets from US 2026/0300274 A1 · click any drawing to enlarge


More from IBM
All 470 IBM patents →
More in AI training & infrastructure
All 316 AI training & infrastructure patents →
Qualcomm
Qualcomm Patents a Way to Update On-Device AI Models Without Replacing the Whole File
Qualcomm
Qualcomm Patents an AI System That Verifies Your Identity Across Devices
Google
Google Patents a System That Picks the Right AI Model for Each Question
Microsoft
No comments yet