
Nvidia Patents a Fix for Digital Faces That Can't Keep Up With Fast Talkers
A new Nvidia patent application tackles a flaw in AI-animated faces: when a character talks fast, the mouth blurs sounds together. Its fix is to stretch the audio clues the AI sees, then keep only the middle.
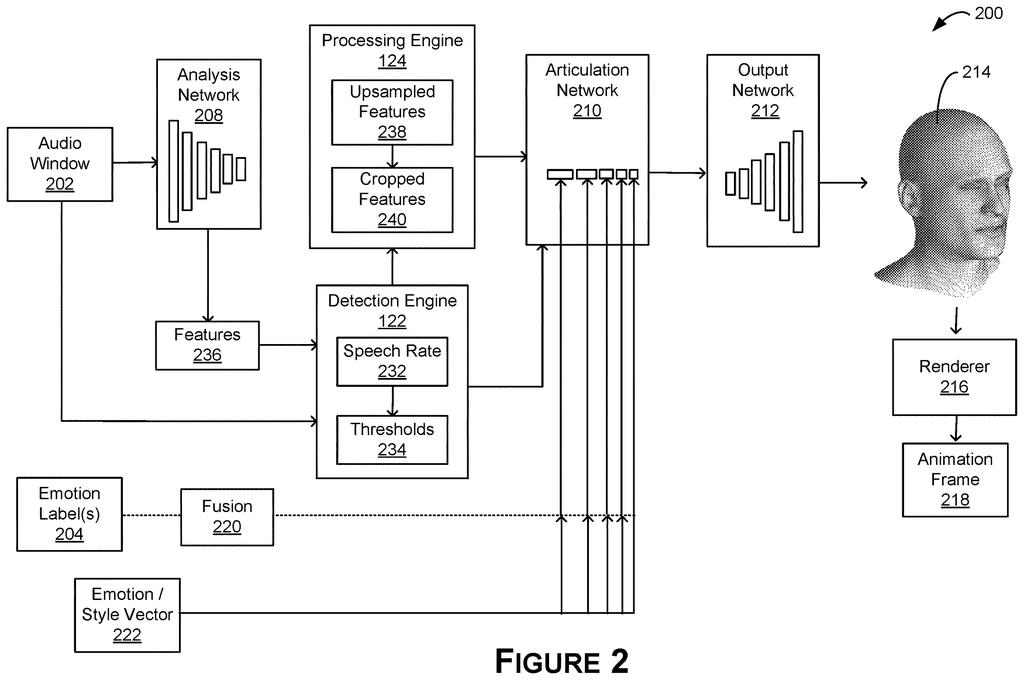
What Nvidia's fast-talker animation fix does
Imagine a video game character who is supposed to rattle off a quick line, but whose mouth just mushes through it without cleanly hitting any of the sounds. That is a real weakness in AI-driven face animation today, and this Nvidia patent application is aimed squarely at it.
Here is the setup. An AI listens to a voice recording and moves a digital face to match. At normal talking speed, it does a good job. When someone talks fast, several sounds pile into a tiny slice of time, and the AI blends them into one in-between mouth shape. Nvidia's idea is to detect when speech is fast, then stretch out the audio clues the AI receives so each sound gets more room.
The stretched clues are then trimmed back to the original size, keeping the middle, so the AI zeroes in on the sound happening right at that moment. The filing says this works without retraining the AI on fast-talking examples.
… upsampling a first set of features associated with the audio segment into a second set of features that is different in size than the first set of features …
Translation: The system expands the audio data when someone talks too fast so the animation has enough detail to keep up.
How Nvidia stretches and crops audio clues
The claim covers a three-step method. First, the system checks whether the rate of speech in an audio segment is above a threshold. Second, if it is, it upsamples (stretches into a longer list) the audio features, the numbers an AI extracts to describe the sound. Third, one or more machine learning models use some of those stretched features to produce a facial animation.
To judge speed, a detection step counts speech sounds (called phonemes) or the transitions between them in a 0.5-second window. It can also use an exponential moving average (a running average that favors recent values) across several windows. The filing's example thresholds sit at 1.5, 2 and 3 times normal speed, paired with stretch factors of 1.5, 2 and 3.
The stretching uses bilinear upsampling (smoothly filling in values between neighbors). In one example, a list of 25 features becomes 50, and the system then crops 25 from the middle of the list, so the existing animation network accepts it unchanged.
In the filing's three-sound example (k, m, i), the middle "m" ends up with most of the cropped features, so the face can land on the right mouth shape instead of a blend. Normal-speed audio skips the stretching entirely.
… generating, using one or more machine learning models and based at least on at least a subset of the second set of features, a facial animation output corresponding to the audio segment …
Translation: Artificial intelligence uses that expanded data to create matching facial movements for the digital avatar.
Why fast talkers matter for game characters
If you have ever watched a game character or digital assistant rush through a line with a mouth that never quite matches, you have seen this problem. The filing names games, films, avatars and in-car assistants as places this kind of animation shows up, and it says current models struggle most when the voice speeds up.
The bigger business angle is cost. Nvidia says the improvement comes without collecting fast-speech recordings or retraining the animation model, because the cropped input is the same size the model already expects. That makes it a small step placed in front of an existing system. It is a patent application, so nothing here says when, or whether, it ships in anything.
Nvidia's 29th filing we've tracked since May in our text-to-3D characters work adds to earlier applications like one photo to a moving head and mood shifts mid-sentence.
The price of this fix is detail at the edges. Keeping only the middle slice of the stretched clues means sounds near the start and end get trimmed, and in Nvidia's own example the first of three sounds is mostly cut.
That looks like a fair trade, because the filing describes sliding the audio window forward frame by frame, so a trimmed sound can land closer to the center of a later window. A second cost is that someone has to pick what counts as fast, and a badly placed threshold would stretch speech that did not need it or miss speech that did.
Set against skipping a round of new fast-talking recordings and retraining, those costs are small. For a patch on an existing animation model, the bargain reads as worth it.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
15 drawing sheets from US 2026/0360063 A1 · click any drawing to enlarge


Show the other 7 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in