
Samsung Patents a Fix for AI Video Characters That Change Looks Mid-Story
One of the most frustrating quirks of AI-generated video is that a character can look completely different from one scene to the next. Samsung has filed a patent for a system designed to solve exactly that.
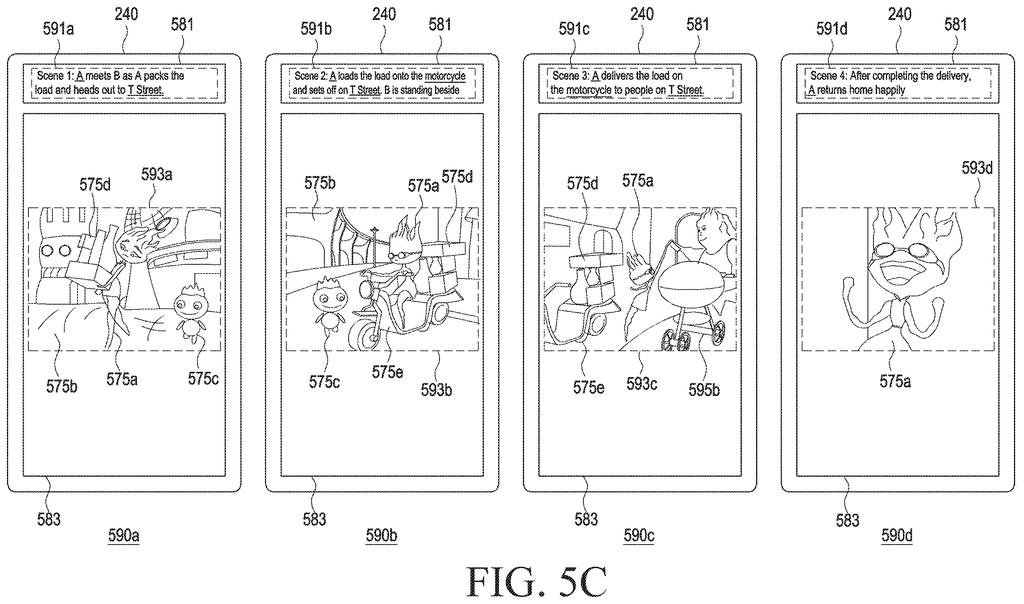
What Samsung's character-consistency video system actually does
Every time you try to make a short AI-generated video, the hero of your story might have brown hair in scene one and blond hair in scene three. The AI just forgets what it drew before. That inconsistency is one of the biggest reasons AI video still feels amateurish.
Samsung's approach is to pull out the main character or object first, generate a locked-down visual reference for it, and then use that reference to guide every scene in the video. Think of it as giving the AI a "model sheet" the way traditional animation studios do, so the character always looks the same no matter what's happening in the background.
The result is a video where your main subject stays visually consistent from beginning to end, even across scenes with very different settings or actions. For anyone trying to tell a story with AI-generated video tools, that's the difference between a clip that feels polished and one that feels broken.
identify first information associated with a description corresponding to a plurality of scenes, based on the first information, identify at least one main object included in at least a portion of the plurality of scenes …
Translation: The system reads the story descriptions to figure out who or what needs to stay the same across different parts of the video.
How the first model locks in a main object across scenes
The system starts by reading scene descriptions for an entire video, treating them all together rather than one at a time. From those descriptions, it identifies at least one main object (a person, a character, a product) that appears across multiple scenes.
That main object's description is then fed into a first model (an AI trained specifically to generate visual content from scene-level information). The model outputs first content, essentially a stable visual representation of what that object looks like. This acts as an anchor.
With that anchor established, the system generates the full video by combining:
- The original scene descriptions (layout, action, setting)
- The locked visual reference for the main object
The key claim is that the main object is consistently visualized across the relevant scenes, meaning the AI is constrained to respect the reference it already generated rather than re-inventing the character from scratch each time. The patent doesn't name a specific underlying model architecture, but the structure implies a two-pass process: anchor generation first, full scene rendering second.
… input descriptions corresponding to the at least one main object into a first model trained to output content on the basis of the reception of information associated with scenes, thereby acquiring, on the basis of information output from the first model, first content corresponding to the at least one main object …
Translation: It feeds those core elements into an AI model to generate consistent visual references.
What this means for anyone generating AI video today
If you've ever used a text-to-video AI tool and watched your main character transform into a different person halfway through, you already know the problem this patent is targeting. Character drift isn't a minor annoyance; it's the reason most AI video output still can't tell a coherent story.
Samsung keeps filing on AI content generation in ways that suggest the company sees on-device or Galaxy-integrated video creation as a near-term product direction. A fix for character consistency is the kind of quiet infrastructure work that makes the difference between a feature people actually use and one they try once and abandon. Whether this shows up in a Galaxy AI video tool or a standalone app, the practical payoff for you is video that looks like it was made intentionally.
Samsung's 34th filing we've tracked in AI image and video since May follows one on editing from your photos and one on self-written training videos.
Character consistency is one of those problems that sounds like a technical footnote until you actually try to make an AI video. Then it becomes the only thing you notice. Samsung is filing on a real pain point, not a showcase feature.
The approach described here is logical: generate a reference for the important thing first, then let that reference govern every scene. It's essentially the same discipline human animators have used for decades, now encoded as a two-step AI pipeline.
The open question is how well it holds up when the main object changes dramatically within scenes, like a character in different outfits or lighting conditions. The patent claims consistency but doesn't detail how tightly the reference constrains the generator. That gap between the claim and the real-world result is where most AI video promises have historically stumbled.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
18 drawing sheets from US 2026/0290048 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in