
Nvidia
Nvidia · Chip · Filed Jun 9, 2026 · USPTO published Oct 1, 2026 · Oct 1 release
Nvidia Patents a Method for Getting Its Graphics Chips to Share Giant Math Tasks
Modern AI models require billions of matrix multiplications per second, and the way GPUs divide that work across threads can leave a lot of computing power sitting idle. Nvidia's new patent describes a hardware system that lets groups of GPU threads share their memory and coordinate automatically, without waiting on software to manage the handoff.
- Publication number
- US 2026/0299943 A1(US20260299943A1)
- Applicant
- NVIDIA Corporation
- Filed · Published
- Jun 9, 2026 · Oct 1, 2026
- Inventors
- Jack CHOQUETTE, Manan PATEL, Maciej TYRLIK, Ronny KRASHINSKY
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 712/221
- Parent application
- Continuation of 17/691,406 (filed Mar 10, 2022)(17691406)
What Nvidia's group warp matrix math actually does
Today's GPUs run thousands of tiny programs called threads at the same time, but those threads normally keep their working memory private. When a big math job arrives, like multiplying two enormous tables of numbers together, that privacy becomes a bottleneck: each thread can only see its own slice of the data.
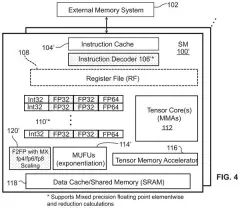
Nvidia's patent describes a system where a batch of threads, organized into groups called warps, are allowed to share their memory with each other's computing pipelines. A dedicated piece of hardware called a state machine takes over the coordination work, loading the right numbers into the right places automatically, so the threads don't have to manage it themselves.
The result is that a single math instruction can recruit a whole gang of cores to work on one big calculation together, finishing it faster and with less wasted effort. This is the kind of low-level engineering that makes the difference between an AI chip that looks good on a spec sheet and one that actually delivers in practice.
… a work distributor circuit configured to distribute a plurality of warps to the plurality of cores, the plurality of warps including a plurality of threads configured to cooperatively execute a matrix multiply and accumulate (MMA) instruction to determine a result matrix based on input matrices …
Translation: A special circuit hands out large math tasks to multiple processing groups so they can solve them together.
How the state machine and shared registers split the load
The patent centers on something called a Group Matrix Multiply and Accumulate (GMMA) instruction. Normal matrix multiply instructions are handled by individual warps (a warp is a fixed-size group of threads, typically 32, that a GPU runs in lockstep). GMMA extends this so that multiple warps collaborate on a single matrix operation.
The key hardware addition is a state machine circuit that operates independently of the threads themselves. When a GMMA instruction fires, the state machine takes responsibility for:
- Loading the input data (called operands) from shared memory into the right datapath inputs across all participating cores
- Sequencing the multiply-and-accumulate steps across asynchronous compute units (meaning units that don't all tick on the same clock cycle)
- Writing the resulting partial outputs back so they can be assembled into the final answer
Threads also pass a descriptor as part of the instruction. Think of a descriptor as a label that tells the hardware the size of the matrices involved and what format the numbers are stored in, so the state machine knows exactly how to route everything.
The design lets each thread's register file (its private scratch-pad memory) be read by the datapaths of other threads in the group, which is normally forbidden. That sharing is what makes the collaborative calculation possible without a costly round-trip through slower shared memory.
A group MMA (GMMA) instruction provides for a descriptor to be provided as parameter where the descriptor may include information regarding size and formats of input data to be loaded into shared memory and/or the datapath.
Translation: A new master command uses a data sheet to tell the chips exactly how big the numbers are and where to put them.
What this means for AI training speed on Nvidia hardware
Matrix multiplication is the single most repeated operation in training and running AI models. The faster and more efficiently a GPU can do it, the more AI work you can squeeze out of the same chip. Nvidia's run of GPU compute architecture filings shows how seriously the company treats this layer of the stack, and this patent sits right at its core.
For you as an end user, this kind of patent doesn't change what software you install, but it does affect how much compute your cloud provider needs to rent you to run a large AI model, and how much that costs. Chips built on this architecture could handle the same workload with fewer cores active, or tackle bigger models in the same time window.
Nvidia's 50th filing we've tracked since July in the AI chip wars follows work like the GPU workload splitting API and the AI compression math fix.
Source: US 2026/0299943 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 19 sheets
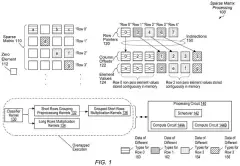
19 drawing sheets from US 2026/0299943 A1 · click any drawing to enlarge


Show the other 11 sheets


More from Nvidia
All 665 Nvidia patents →
More in Chip
All 651 Chip patents →
Google
Google Patents an AI Chip That Skips Blank Video Segments to Save Battery
Apple
Apple Patents a Slice-by-Slice Image Processing Method That Cuts Chip Memory Use
AMD
AMD Patents Technology to Redirect Unused Storage Space Toward AI Processing
AMD

No comments yet