
Tesla
Tesla · AI / ML · Filed Sep 8, 2025 · USPTO published Oct 1, 2026 · Oct 1 release
Tesla Patents a Method to Adjust Its In-Car AI Chips on the Fly
Tesla's in-car AI chips have to process sensor data fast enough to make split-second driving decisions. A new patent reveals how Tesla is teaching those chips to dial their math precision up or down on the fly, squeezing out more speed without sacrificing accuracy.
- Publication number
- US 2026/0299946 A1(US20260299946A1)
- Applicant
- Tesla, Inc.
- Filed · Published
- Sep 8, 2025 · Oct 1, 2026
- Inventors
- Ritvik RAWAT, Valeriy ROTAN, Alex SINGH, Srihari SAMPATHKUMAR
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 712/7
- Parent application
- Claims priority from a provisional application 63780076 (filed Mar 28, 2025)
What Tesla's mixed-precision AI chip trick actually does
Today's AI chips face a constant tradeoff: run calculations at high precision and get accurate results slowly, or run them at low precision and get fast but rougher results. Tesla's patent describes a way to do both at the same time, on a single chip, depending on what the data actually needs in each moment.
The idea is that not every piece of sensor data requires the same level of mathematical detail. A distant object detected by radar might need only a rough estimate, while a pedestrian at close range demands higher accuracy. The patented system checks each chunk of incoming data individually and adjusts the precision of the math on the spot, rather than committing to one setting for everything.
For you as a driver, this is background plumbing. The goal is an AI that can process more camera, radar, and sensor feeds at once, on the same chip, without needing a bigger or hotter processor to do it.
… executing, by the processor, a dynamic quantization to one or more of the feature vectors based upon a level of precision, to update the number of bits of the feature vectors according to a second precision corresponding to the level of precision for the input data to a subsequent computation operation …
Translation: The chip changes its data precision on the fly to handle incoming tasks more efficiently.
How the processor switches bit-depth token by token
The patent covers what Tesla calls dynamic quantization inside a transformer-based AI model. Transformers (the same family of AI architecture behind large language models) process data as sequences of tokens, small chunks of information. Each token gets converted into a feature vector, a list of numbers representing that chunk's meaning or properties.
Normally, all those numbers are stored and processed at a fixed precision, either high-precision (more bits per number, more accurate, more power-hungry) or low-precision (fewer bits, faster, rougher). Tesla's system instead adjusts the bit-depth per token: it evaluates each feature vector and decides, on the fly, whether to keep it at the original higher precision or compress it to a lower one before passing it on to the next layer of the model.
The claim specifically covers the full attention mechanism that follows:
- Computing similarity values between tokens (which tokens are related to which others)
- Generating attention weights using a normalization function (softmax, which converts raw scores into probabilities that sum to 1)
- Producing a weighted sum of feature vectors using those weights
- Outputting an intermediate context representation, a compressed summary of what the model has learned about the whole input so far
The hardware Tesla names, INT8 MAC units (integer math accelerators) and FP32 SIMD processors (floating-point vector processors), suggests this is designed for Tesla's own custom silicon, where different physical circuits handle different precision levels simultaneously.
… implementing mixed-precision quantization for ingesting and analyzing various types of sensor data. The machine-learning architecture implements a transformer that includes dynamic quantization layers that dynamically quantize tensors, per-token, for downstream operations of the transformer and machine-learning architecture …
Translation: The AI system adjusts data accuracy token by token as it processes information from vehicle sensors.
What this means for Tesla's self-driving hardware
Tesla's self-driving system has to ingest data from multiple cameras, ultrasonic sensors, and other inputs simultaneously, all in real time, on a chip that fits in a car and runs without melting. Every efficiency gain in the AI model translates directly into either faster reaction times or lower power draw, or both.
Tesla's interest in custom AI silicon shows up across multiple filings, and this patent fits that pattern. By controlling precision at the individual-token level inside the attention mechanism, Tesla could run larger or more complex models on the same hardware generation, rather than waiting for a chip upgrade. That matters because Tesla's interest in in-house chip design means it can't simply swap in a third-party accelerator when performance needs to improve.
Tesla's 39th filing we've tracked since May in our Tesla coverage continues its interior focus, joining work on lean-in door opening and rising dashboard screens.
Source: US 2026/0299946 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Tesla patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
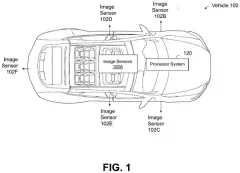
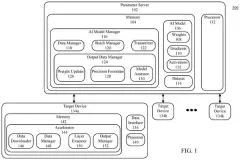
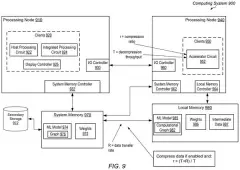
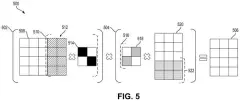
The drawings · 8 sheets
8 drawing sheets from US 2026/0299946 A1 · click any drawing to enlarge


More from Tesla
All 59 Tesla patents →
More in AI training & infrastructure
All 324 AI training & infrastructure patents →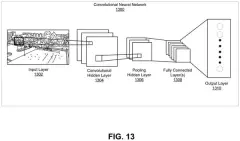
Qualcomm
Qualcomm Patents a Way to Update On-Device AI Models Without Replacing the Whole File
Microsoft
Microsoft Patents a Way to Run Giant AI Models on Chips Too Small to Hold Them
AMD
AMD Patents a System That Compresses AI Model Data Before It Leaves the GPU
Qualcomm

No comments yet