
Adobe
Adobe · AI / ML · Filed May 12, 2025 · USPTO published Nov 12, 2026 · This week's release
Adobe Files Patent for AI Videos That Run Longer Without Losing the Plot
AI video tools tend to forget what their own characters looked like a few seconds ago. Adobe's patent describes a way to keep a teddy bear the same bear from the first scene to the last.
- Publication number
- US 2026/0360066 A1(US20260360066A1)
- Applicant
- Adobe Inc.
- Filed · Published
- May 12, 2025 · Nov 12, 2026
- Inventors
- Seoungwug OH, Subin KIM, Jui-Hsien WANG, Joon-Young LEE
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 345/634
- Examiner
- CREARY, LATRELL ANTHONY (Art Unit 2613)
What Adobe's long-video patent actually does
Most AI video tools top out at clips of roughly 5 to 10 seconds, because training a model on longer footage takes too much computing power. Stitch several clips together and things go wrong: the character's look drifts, the style shifts, and small errors pile up from one clip to the next.
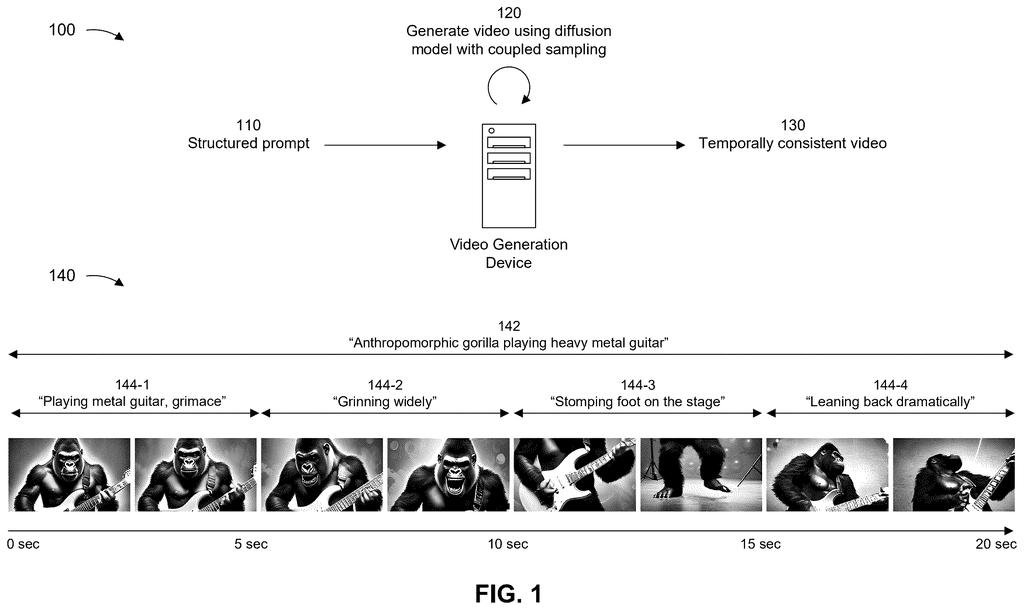
Adobe's patent describes a way to get a longer video out of an existing model without retraining it (that is the 'tuning-free' part of the title). You write one description of what stays the same, such as a brown teddy bear with button eyes and a stitched smile, plus a short note for each stretch of the video, such as standing and then running. The system builds the video in overlapping pieces and keeps comparing them so the bear stays the same bear.
In the company's own example, a gorilla playing heavy metal guitar gets four back-to-back segments of about five seconds each, with a different action in every one.
… performing, using a machine learning model, one or more forward diffusion operations on the input video to generate an intermediate output based on the one or more text prompts associated with the input video and similarities among one or more segments of the input video …
Translation: The AI breaks down the video and text while tracking how different parts of the footage relate to each other.
How overlapping clips get stitched together
The patent covers a text-to-video diffusion model (an AI that starts with pure visual static and removes the noise step by step until a video appears). The twist is how it handles length. At each step, it splits the video into overlapping segments. Each segment is guided by a global prompt (what stays the same across the whole video) plus a local prompt (what changes in that stretch, such as a new motion, camera angle or style). The filing says a language model can help turn a user's story into this global-plus-local structure.
Each segment is cleaned up on its own, then the pieces are blended back together with a weighted average. In the early steps, when the model is still deciding the rough layout, there is an extra pass. Segments are scored on how similar they are to each other, nearby and far apart alike, and similar segments share more of their updates. The filing calls this collaborative score distillation (a method that nudges several samples toward agreeing with each other).
A few details keep the extra pass cheaper and more stable:
- It runs only in the early steps, because later steps just add fine detail.
- It can run on a subset of segments to cut processor and memory use.
- It uses a fixed baseline noise and a fixed timestep instead of random ones, which reduces the variation random choices would cause.
The claims cover this as a method, a system and a set of stored instructions.
Why the 10-second AI video limit is a problem
If you have tried an AI video generator, you know the clips are short, and a character can look different by the end. A method that lets an existing model produce longer, steadier footage, guided by a scene-by-scene script, would turn a novelty clip into something closer to a short story. Writing a prompt per scene also gives you more control than one sentence stretched across the whole video.
The 'no retraining' angle is the practical point. Training video models on long footage is expensive, so a technique that works on top of a model that already exists is cheaper to try. The filing does not name a product, and it is a published application, not a granted patent, so treat it as a look at what Adobe's researchers are working on.
Adobe's 44th filing we've tracked for controllable AI image generation since May adds to a body of work that includes an AI that suggests photo additions and one that renders fur and glass.
Source: US 2026/0360066 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Adobe patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 14 sheets
14 drawing sheets from US 2026/0360066 A1 · click any drawing to enlarge


Show the other 6 sheets


More from Adobe
All 264 Adobe patents →
More in AI vision
All 339 AI vision patents →
Adobe
A New Adobe Patent Turns a Black T-Shirt Into Tiger Fur, Leaving the Photo Intact
Adobe
Adobe Patents AI That Guesses the Whole Room's Lighting From One Photo
Adobe
Adobe Patents an AI Tool That Copies Objects Into New Parts of a Photo
Adobe
No comments yet