
Adobe
Adobe · AI / ML · Filed May 8, 2025 · USPTO published Nov 12, 2026 · This week's release
Adobe Files Patent for Teaching Its AI With Made-Up User Requests
Adobe's patent describes a factory for made-up user requests: it turns details about templates, images and videos into practice prompts, so an AI can learn without reading anyone's private searches.
- Publication number
- US 2026/0359650 A1(US20260359650A1)
- Applicant
- Adobe Inc.
- Filed · Published
- May 8, 2025 · Nov 12, 2026
- Inventors
- Dewang Sultania, Vibha Belavadi, Tushar Vatsa, Suhas Suresha, Ishita Verma, Cheng Chen, Tracy Holloway King, Michael Friedrich
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 706/25
What Adobe's made-up prompt factory actually does
Every time you type "birthday card with a cake" into a design app, an AI has to guess whether you want to find something that already exists or make something new. Teaching it to guess well takes a huge pile of example requests, and real ones from real people are often off limits because of privacy or are simply scarce.
Adobe's patent describes a way to write those practice requests itself. It starts with facts about its own content, like titles, keywords and design types (a card, an invite), plus a map of how ideas connect, such as birthday and cake. Then it pours those facts into sentence templates, from short search phrases to "please generate a template for" a given title, while a set of dials controls how often each style shows up.
A second AI then tags each request as a search or a create command. The finished pile works as a study guide for training other AI models.
… generating a synthetic dataset comprising labeled prompts for training the one or more machine learning models by generating, utilizing one or more large language models, labels indicating function classifications for the machine learning model prompts.
Translation: Creating fake training data by having AI label the made up user requests.
How the weighted router mixes Adobe's prompt types
The system starts by pulling metadata (basic facts such as a title, language, aspect ratio, click-through rate, keywords, and whether AI made the asset) from templates, images and videos. Some versions also read a knowledge graph, a web of linked ideas where "birthday" connects to "card," "cake" and "cut a cake."
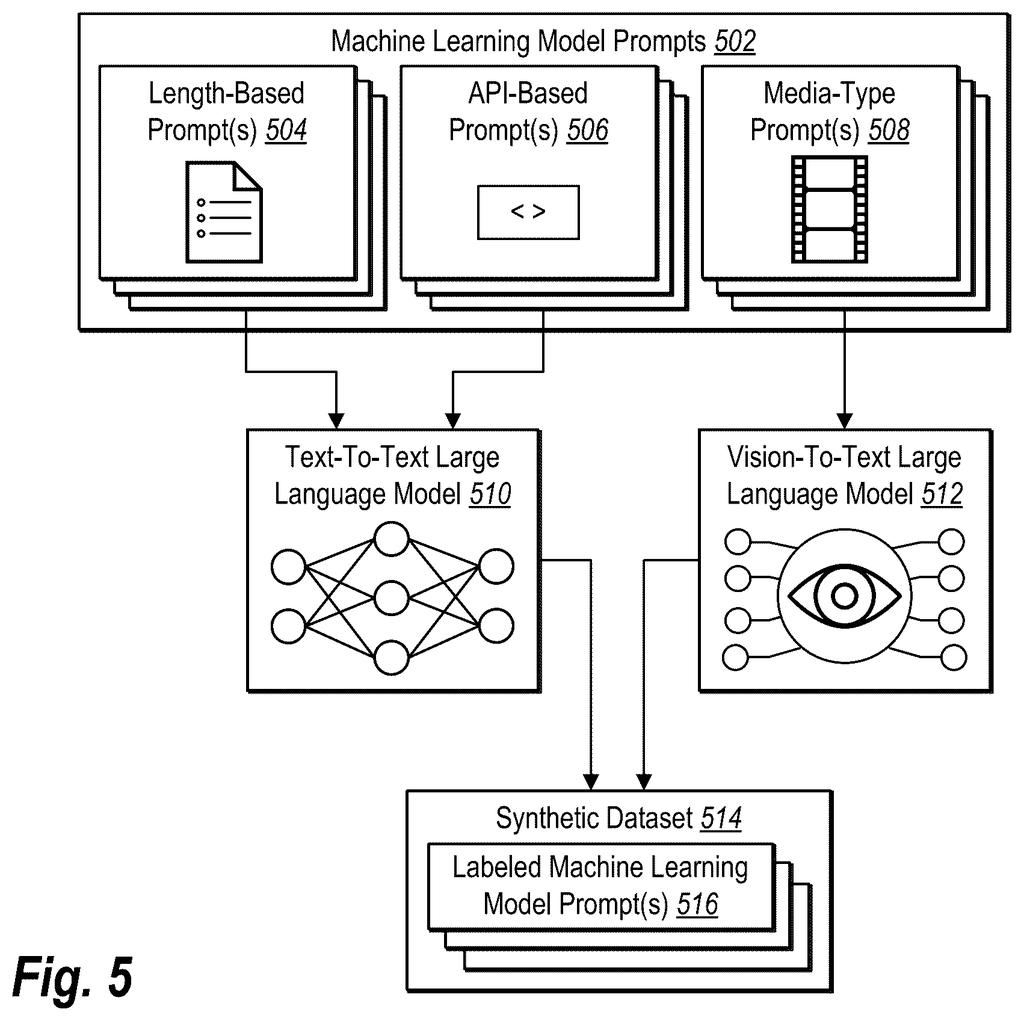
Next, a weighted router (a traffic director that sends information to different destinations in set proportions) feeds that material into prompt templates:
- Length-based: prompts of a set word count, such as two to five words.
- API-based: prompts aimed at a search tool or a content-creation tool (an API is the doorway one program uses to ask another for something).
- Media-type: prompts that include an image.
Templates can also force a keyword to land at the start, middle or end of a request. The filing also describes a feedback loop: real user prompts are compared with the made-up ones, and the router's weights get adjusted until the mix matches.
Finally, large language models (the text-predicting AI behind chatbots) label each prompt as a search or a generate request and note the content type it targets. Image-reading models handle the image prompts. Those labels can be checked against correct answers to fine-tune the labelers.
Why Adobe wants AI trained without your prompts
If you have ever asked a design tool for a template and got a random photo, you know the frustration this is aimed at: an AI that misreads what kind of thing you want. The filing says older practice data piles up too many "image" requests and too few for audio or templates, which leaves models weaker on the rarer types.
For Adobe, the appeal is clear. Templates, images and videos are the raw material here, and the filing says training material can be built from their descriptions without touching private user data. The filing's own graphs show a more even spread of content types and keyword positions than prior methods, though it names no product and gives no release plans.
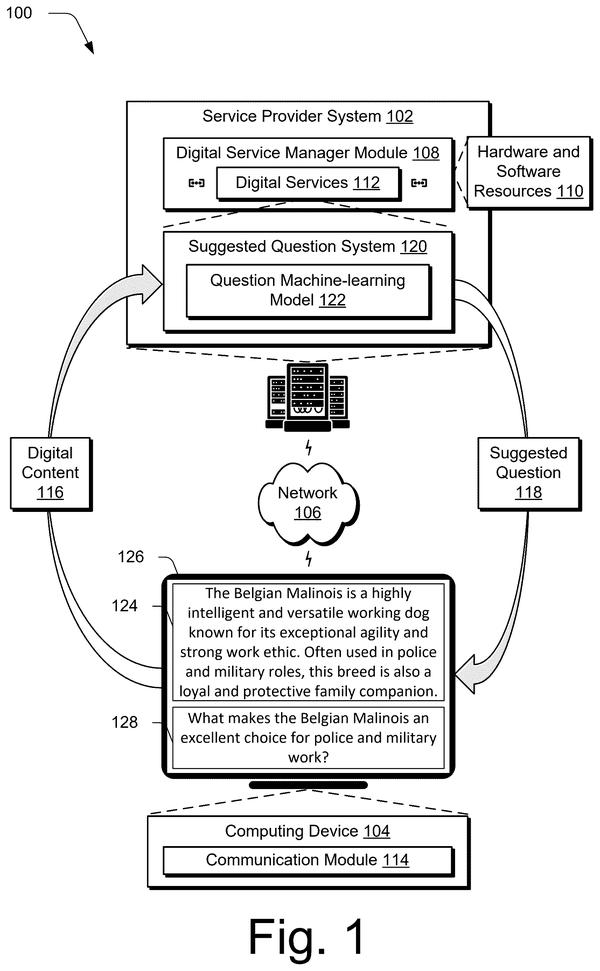
Adobe's second filing we've tracked for on-device AI privacy since October follows a small on-device question suggester with another application to keep AI processing local.
Source: US 2026/0359650 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Adobe patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 9 sheets
9 drawing sheets from US 2026/0359650 A1 · click any drawing to enlarge


Show the other 1 sheets

More from Adobe
All 264 Adobe patents →


More in AI / ML
All 2,637 AI / ML patents →
Qualcomm
Qualcomm Patents Technology That Helps Phones Understand Images Without a Cloud Connection
Google
Google's New Patent Keeps Tabs on Your Phone's AI Without Seeing Your Data
Google
Google Patents a Distributed AI Training System That Keeps Your Data on Your Device
Google
No comments yet