
Google
Google · AI / ML · Filed Apr 13, 2026 · USPTO published Aug 20, 2026 · Aug 20 release
Google Patents a Way to Search Documents by Reading Only the Parts That Matter
Search engines today often have to process every word in every candidate document before deciding which one answers your question. Google's new patent describes a way to skip most of that work without losing accuracy.
- Publication number
- US 2026/0244629 A1(US20260244629A1)
- Applicant
- Google LLC
- Filed · Published
- Apr 13, 2026 · Aug 20, 2026
- Inventors
- Jinhyuk Lee, Zhuyun Dai, Sai Meher Karthik Duddu, Tao Lei, Iftekhar Naim, Ming-Wei Chang, Yuzhe Zhao
- Status when we published
- Waiting for an examiner
- Document
- 21 claims
- US classification
- 707/728
- Parent application
- Continuation of 19/005,388 (filed Dec 30, 2024)(19005388)
How Google's token retrieval cuts search down to size
Imagine you ask a question and a librarian has to read every page of every book in the library before telling you which one is most relevant. That is roughly how some search systems work today, and it is slow.
Google's patent describes a method where, instead of processing all the words in each candidate document, the system pulls out only the specific word level pieces most likely to match your question. Think of it like skimming only the sentences that seem relevant before committing to a full read.
The result, according to the filing, is a search process that is both faster and more accurate, because the system stops wasting attention on parts of a document that clearly do not help answer your question.
… identifying relevant documents to a query by using only retrieved token vectors of candidate documents rather than all token vectors of the documents.
Translation: Google's system speeds up searches by checking only the most important parts of a document instead of reading everything.
How the system picks which token vectors to actually score
Modern AI search systems often represent documents as a collection of vectors, one for each word or word-piece (called a token). To score how well a document matches a query, a system typically compares the query against all of those token vectors. For long documents with thousands of tokens, that is a lot of computation.
This patent proposes a contextualized token retriever: a system that, for any given query, retrieves only a selected subset of token vectors from each candidate document rather than the full set. The selection is context-aware, meaning the system chooses which tokens to pull based on what the query is actually asking about.
The core claim is that scoring documents against only the retrieved (relevant) token vectors, rather than all token vectors, produces better speed and better accuracy at the same time. This matters because the two goals normally trade off against each other: faster scoring usually means coarser, less accurate results.
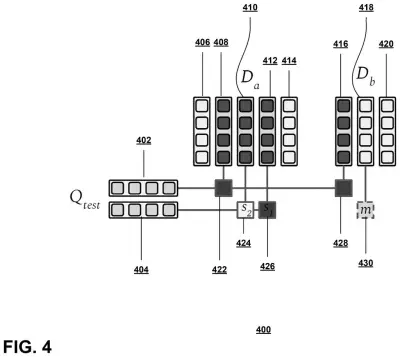
- Query processing: the query is encoded into a vector representation.
- Token retrieval: only the most query-relevant token vectors are fetched from each candidate document.
- Scoring: relevance is computed using only those retrieved token vectors, not the full document.
What this means for AI search speed and accuracy
Search and retrieval are at the center of almost every AI product right now, from chatbot assistants that look up facts to enterprise tools that search internal documents. Any method that makes document retrieval faster without sacrificing accuracy has direct value, because today's systems often face a hard choice: be thorough and slow, or be fast and miss things.
This filing sits in the middle of a busy area of AI infrastructure research, and plain-English patent summaries of search and retrieval patents from Google have appeared with increasing frequency as the company races to make its AI search architecture more efficient. Whether the approach described here ends up in Google Search, Google Cloud's enterprise search tools, or some future AI assistant product is unknown, but the problem it addresses is real and the scale at which Google operates makes even small efficiency gains significant.
Google's 586th filing among the patents we've tracked in our Google coverage since May adds to a body that includes a privacy split across servers and a weather-aware rerouting system.
Source: US 2026/0244629 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 6 sheets
6 drawing sheets from US 2026/0244629 A1 · click any drawing to enlarge


More from Google
All 1,127 Google patents →
More in AI / ML
All 2,745 AI / ML patents →
Nvidia
Nvidia Patents a System That Lets AI Models Select Their Own Training Data
IBM
IBM Patents a System That Catches Two Types of AI Lies in Summaries
Adobe
Adobe Patents a System That Shows You Where an AI's Answer Came From
IBM