
IBM
IBM · AI / ML · Filed Mar 27, 2025 · USPTO published Oct 1, 2026 · Oct 1 release
IBM Patents a System That Rescues AI Training After a Server Crash
Training a large AI model can take days or weeks, so a server failure halfway through is genuinely painful. IBM has filed a patent for a system that automatically saves progress and hands the job off to a backup server when things go wrong.
- Publication number
- US 2026/0300100 A1(US20260300100A1)
- Applicant
- INTERNATIONAL BUSINESS MACHINES CORPORATION
- Filed · Published
- Mar 27, 2025 · Oct 1, 2026
- Inventors
- Hui Wang, Yu Mei Dai, Xiao Chen Huang, Peng Hui Jiang, Xiang Yu Xue, Mai Zeng, Wei Li
- Status when we published
- Examiner raised objections; the company can respond
- Document
- 20 claims
- US classification
- 711/162
- Examiner
- OTTO, ALAN (Art Unit 2132)
What IBM's AI training recovery actually does for you
Training an AI model from scratch is expensive and time-consuming. If the server doing the work crashes or goes offline, everything since the last manual save can be lost, and teams often have to start over.
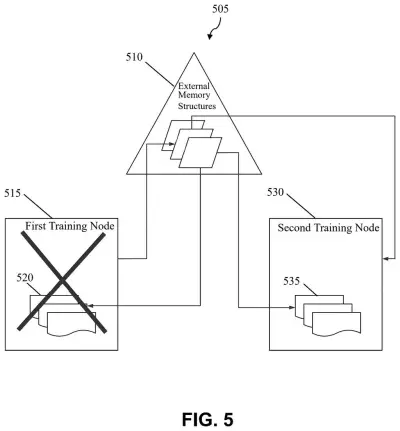
IBM's patent describes a system that saves snapshots of the training process, called checkpoints, to an external storage device as the work progresses. If something interrupts the training on the first server, a second server picks up from the most recent checkpoint and keeps going.
Once training finishes, the completed model is automatically deployed. The whole process is designed so that a hardware failure doesn't mean starting from scratch, and you don't need someone watching the job around the clock to catch a problem before it wastes days of compute time.
… saving a plurality of checkpoints in an external memory device during the training of the deep learning model; determining that there is an interruption of the training of the deep learning model; …
Translation: The system saves progress to an outside memory so it can detect if the server crashes.
How IBM checkpoints survive a server failure mid-training
The patent describes a three-part workflow: train, checkpoint, and recover.
Training begins on a first server, which receives data from an external application and starts building the deep learning model. During this process, the system regularly saves checkpoints (snapshots of the model's current state, including how far training has progressed) to an external memory device that neither server owns exclusively. That external storage is the key: it sits outside both servers, so it survives if either one fails.
Interruption detection is the next layer. The system watches for any break in training, whether from a hardware crash, a network cut, or some other fault. When it detects one, it doesn't wait for a human to intervene.
Recovery happens automatically. A second server reads the most recent checkpoint from the shared external storage and resumes training from that point. When training completes, the system deploys the finished model.
The architecture is straightforward: decouple progress state from any single machine by writing it to neutral storage, and you make the training job portable across machines on the fly.
… resume and complete training of the deep learning model at a second server in response to determining that there the interruption of the training of the deep learning model; …
Translation: After a crash, a different server picks up right where the first one left off.
What this means for companies running long AI training jobs
For any company running AI training jobs on real infrastructure, hardware failures are not rare edge cases. A server can go down mid-job for any number of reasons, and without a recovery system, the cost is measured in both lost compute time and lost money.
This patent targets that specific failure mode. If it works as described, teams running long training jobs get a meaningful safety net: interruptions become delays rather than disasters. The user-facing payoff is a faster path to a finished, deployed model, with less dependence on any single piece of hardware staying healthy for days on end.
IBM's 39th filing we've tracked in AI training & infrastructure since May adds to a run that includes a data question-answering patent and one on learning from industry workflows.
Source: US 2026/0300100 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 7 sheets
7 drawing sheets from US 2026/0300100 A1 · click any drawing to enlarge


More from IBM
All 470 IBM patents →
More in AI training & infrastructure
All 316 AI training & infrastructure patents →
Qualcomm
Qualcomm Patents a Way to Update On-Device AI Models Without Replacing the Whole File
Qualcomm
Qualcomm Patents an AI System That Verifies Your Identity Across Devices
Google
Google Patents a System That Picks the Right AI Model for Each Question
Microsoft
No comments yet