IBM
IBM · AI / ML · Filed Feb 12, 2025 · USPTO published Aug 13, 2026 · Aug 13 release
IBM Patents Smarter AI Training That Allocates More Memory to Harder-Working Connections
Training an AI model treats every internal connection as equally important, even when most of them are doing very little work. IBM wants to fix that by measuring how busy each connection actually is and allocating memory accordingly.
- Publication number
- US 2026/0236776 A1(US20260236776A1)
- Applicant
- International Business Machines Corporation
- Filed · Published
- Feb 12, 2025 · Aug 13, 2026
- Inventors
- Bruce Gordon ELMEGREEN, MALGORZATA JADWIGA ZIMON, Fausto Martelli, Kyong Min Yeo
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 706/15
How IBM's bit-scaling changes AI training efficiency
Every AI model is built from thousands or millions of tiny decision points called nodes, and during training each node stores a number called a weight. Today, every weight gets the same amount of memory, whether that node is doing heavy lifting or barely contributing anything.
IBM's patent wants to change that. After an initial round of training, the system measures how often information actually travels through each node. Nodes that carry a lot of traffic get a higher-precision number, which means more memory for storing their weight accurately. Nodes that barely carry any traffic get a lower-precision number, saving space. Then training continues with this new, custom-fitted setup.
The practical payoff is that you could train a model that uses memory more efficiently, spending precision where it counts and cutting waste where it doesn't. That could mean smaller hardware bills or faster training runs for the same model quality.
… scaling a number of bits used for weights of the nodes based on the determined flow rates, wherein the scaling comprises using a larger number of bits for the nodes with a larger information flow and a smaller number of bits for the nodes with a smaller information flow …
Translation: The system gives more digital memory to the most active parts of the AI while giving less memory to the idle parts.
How flow rates determine each node's bit allocation
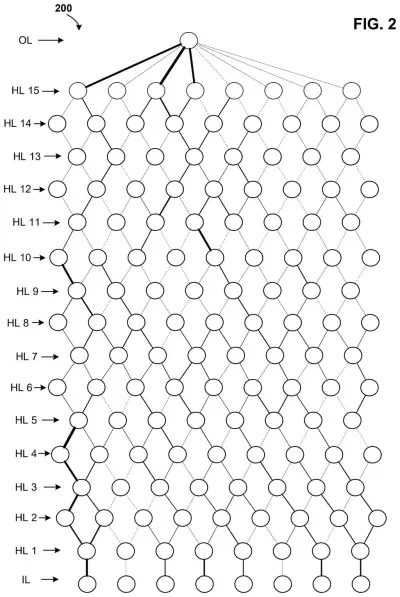
The patent describes a training method for sparse neural networks, meaning networks where nodes are deliberately not connected to every other node (the opposite of a "fully connected" network, where every node talks to every other one).
After one or more training passes (called epochs), the system computes a flow rate for each node. The flow rate is essentially a probability score: how often does information actually pass through this node during a forward computation? A node that sits on a critical path and fires frequently gets a high flow rate; a node that rarely activates gets a low one.
Based on those scores, the system adjusts the bit-width of each node's weight:
- High-flow nodes get more bits, meaning their weights can represent numbers with finer detail and less rounding error.
- Low-flow nodes get fewer bits, meaning their weights are stored more coarsely but take up far less memory.
- The overall network then continues training with this variable-precision setup baked in.
This technique is related to a broader field called mixed-precision training, where different parts of a model use different numerical formats. IBM's specific contribution is tying the precision decision to a measured traffic signal inside the network rather than applying it uniformly or by hand.
A neural network that includes multiple layers and multiple nodes in each layer is trained with training data. The nodes are sparsely connected to each other and not fully connected. After the training occurs for one or more epochs, a respective flow rate of the multiple nodes is determined.
Translation: The AI is built with a web of connections that are not all linked together, allowing the system to track how data moves.
What this means for the cost of training large AI models
Training large AI models is expensive, and memory is one of the biggest costs. Modern models can have billions of weights, and storing all of them at high precision requires enormous amounts of specialized memory on AI chips. Any technique that lets you shrink the memory footprint without meaningfully hurting accuracy translates directly into lower hardware costs or the ability to train larger models on the same hardware.
IBM is one of several companies pushing on efficient AI training from the hardware side, and this patent fits into that broader effort. The approach is particularly relevant as AI workloads grow faster than chip memory capacity. For anyone tracking where the industry is heading on AI infrastructure, this filing sits alongside a steady stream of new Big Tech patents targeting the memory and compute bottlenecks at the heart of AI training.
Source: US 2026/0236776 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 6 sheets
6 drawing sheets from US 2026/0236776 A1 · click any drawing to enlarge


More from IBM
All 470 IBM patents →
More in AI assistant & agent
All 413 AI assistant & agent patents →
Qualcomm
Qualcomm Patents a Way to Stop AI Video Models From Running Out of Memory
Samsung
Samsung Patents a Way to Cut the Memory AI Models Need to Think
Nvidia
Nvidia Patents a Way to Clear AI Memory Without Reloading What Was Just Removed
Nvidia