
Microsoft
Microsoft · AI / ML · Filed Mar 28, 2025 · USPTO published Oct 1, 2026 · Oct 1 release
Microsoft Patents a Way to Compress AI Math Tables Without Losing Precision
AI models are packed with enormous grids of numbers, and storing them is expensive. Microsoft has filed a patent for a compression scheme that lets chips decode those number grids on the fly, using a system of shared reference tables rather than storing every value in full.
- Publication number
- US 2026/0300167 A1(US20260300167A1)
- Applicant
- Microsoft Technology Licensing, LLC
- Filed · Published
- Mar 28, 2025 · Oct 1, 2026
- Inventors
- Robert Peter GMYR, Ashraf Ayman MICHAIL
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 706/15
How Microsoft shrinks the numbers powering AI models
AI models like the ones that power chatbots and image generators are, at their core, enormous spreadsheets of numbers called matrices. Today, those matrices take up huge amounts of memory, which drives up the cost and power consumption of every chip that runs them.
Microsoft's approach cuts that storage burden by dividing each matrix into small chunks, then replacing the actual numbers in each chunk with short codes pointing to a shared reference table. Instead of saving 1,000 unique values, a chip only needs to save a handful of reference tables and a list of codes telling it which table entry each value corresponds to. When the chip actually needs the numbers, it looks up the codes and reconstructs the values in real time.
The twist in this patent is that different chunks of the same matrix can each point to different reference tables, not just one shared table. That flexibility lets the system adapt to the uneven way AI model weights are actually distributed, preserving accuracy while still trimming memory use.
… perform a plurality of table lookup operations using the table index, the lookup table, and the element indices to compute a decoded sub-block that includes, for each of the element indices included in the encoded sub-block, the corresponding centroid value specified by that element index; …
Translation: The system rebuilds the compressed data by matching index numbers to their corresponding values in lookup tables.
How the lookup tables and index arrays fit together
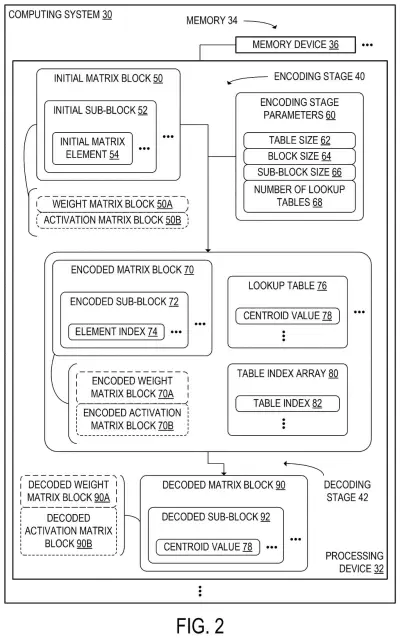
The patent describes a matrix compression and decompression system designed for AI workloads. A matrix here is a large grid of floating-point numbers that an AI model uses to make calculations.
Here is how the encoding works:
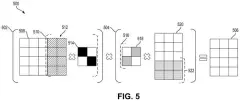
- The matrix is sliced into small sub-blocks, each holding a subset of the original values.
- A set of lookup tables is created, each containing a compact list of representative values called centroids (think of centroids as the "best average" stand-ins for a cluster of nearby numbers).
- Each sub-block's actual values are replaced by short element indices, which are just tiny codes pointing to the right centroid in a lookup table.
- A separate table index array records which lookup table applies to which sub-block, allowing different parts of the matrix to reference different tables.
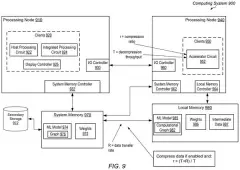
At decode time, the processor retrieves the table index for each sub-block, pulls the right lookup table, reads the element indices, and performs a fast lookup to reconstruct the centroid values. The result is a decoded matrix block that the AI model can use for computation.
The key technical claim is multi-table distribution encoding: rather than forcing every sub-block to share one global table, each sub-block can point to its own table. This matters because real AI weight distributions are not uniform, and a single shared table would introduce more approximation error than a set of specialized tables.
A computing system including memory storing encoded sub-blocks of an encoded matrix block. Each of the encoded sub-blocks includes element indices. The memory further stores lookup tables that each include centroid values.
Translation: The patent describes hardware that stores compressed data blocks alongside reference tables containing the actual math values.
What this means for AI hardware and memory limits
For anyone running AI software, the most direct payoff is cost. Memory is one of the biggest bottlenecks for large AI models, both in terms of how much you can fit on a chip and how much energy the chip burns moving data around. A compression scheme that shrinks matrix storage without a large accuracy penalty means the same hardware can handle bigger models, or handle the same models more cheaply.
For hardware makers and software engineers building AI inference systems (the machines that run a trained model rather than train it from scratch), Microsoft's track record in AI compression patents signals where they see the memory wall as a real engineering problem. Whether this specific scheme makes it into a shipping product depends on how its accuracy-versus-compression tradeoff compares with competing approaches like quantization methods already in wide use.
Microsoft's 17th application we've tracked since July in the AI chip wars, following one on running AI math on any processor and one on fitting giant models onto small chips, adds another piece to the same puzzle.
Source: US 2026/0300167 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 10 sheets
10 drawing sheets from US 2026/0300167 A1 · click any drawing to enlarge


Show the other 2 sheets


More from Microsoft
All 681 Microsoft patents →
More in AI training & infrastructure
All 323 AI training & infrastructure patents →
Qualcomm
Qualcomm Patents a Way to Update On-Device AI Models Without Replacing the Whole File
AMD
AMD Patents a System That Compresses AI Model Data Before It Leaves the GPU
Qualcomm
Qualcomm Patents a Way to Fix the Most Error-Prone Parts of a Compressed AI Model First
AMD
No comments yet