
AMD Patents a Method to Run AI Vision Models With Far Less Computation
The single most expensive calculation inside a modern AI vision model is called attention, and Xilinx just filed a patent for a way to approximate it accurately enough to be useful while cutting the underlying math significantly.
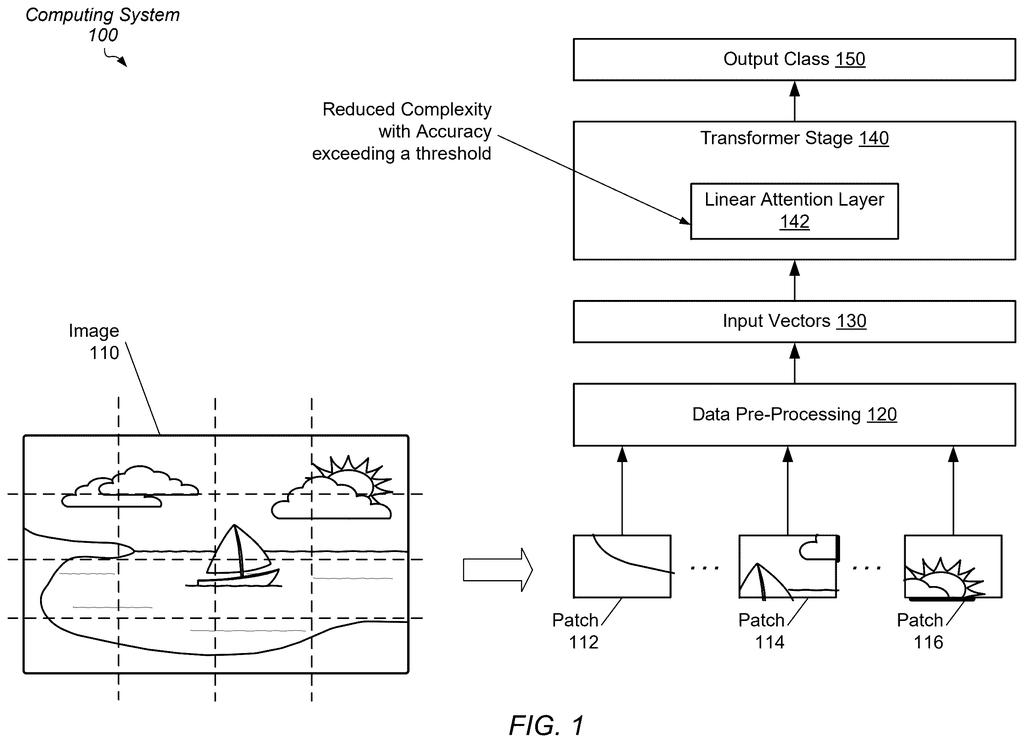
How Xilinx shrinks the heaviest AI math step
Imagine you ask a smart photo app to identify every person in a crowded room. Behind the scenes, the AI has to figure out how every person in the photo relates to every other person before it can label anyone. That comparison step, called attention, is the most computationally expensive part of the whole process, and it gets dramatically more expensive as the image gets more complex.
Xilinx, AMD's chip design division, has filed a patent describing a way to replace the expensive math at the heart of that comparison with a cheaper approximation. Instead of running the full calculation, their method uses a mathematical shortcut involving something called a Kronecker product, which produces a compact version of the same result without the usual cost.
The goal is to run capable AI vision models on hardware that can't afford the full computation, think cameras, drones, or factory sensors, without a big drop in accuracy. For you, that could mean faster, smarter image recognition on devices that currently struggle with it.
… generate a self-attention score representing an amount of relevance between the pair of input values based on an approximation of a similarity measurement function comprising a product of two terms …
Translation: It calculates how relevant input values are by approximating a math function using two terms.
How the Kronecker approximation replaces full softmax attention
Modern AI vision models, like the kind used to recognize objects or faces in images, rely on a mechanism called self-attention. Self-attention works by comparing every part of an input (a patch of pixels, say) against every other part to figure out which ones are relevant to each other. The math that scores those comparisons, usually a function called softmax, scales with the square of the number of inputs, meaning double the image complexity and the cost quadruples.
This patent describes a method to approximate that similarity score using a Taylor expansion (a technique from calculus that replaces a complicated function with a simpler polynomial that behaves almost identically near a given point). Specifically, the approach keeps only the second-order terms of that expansion, which involves squaring and combining the input vectors rather than computing the full exponential.
To make that approximation efficient to compute in hardware, the patent introduces the use of a Kronecker product (a mathematical operation that combines two vectors into a structured matrix in a compact form). Each row of the model's query and key weight matrices is transformed into this compressed representation, and then a standard dot product is run between them.
- Retrieve query and key weight matrices from the AI model
- Compute a Kronecker product for each row vector
- Replace each element with a scaled self-multiplication term
- Run a dot product between the transformed matrices to get the attention score
The result is an attention score that the patent claims approximates the full softmax result while being far cheaper to compute and store on dedicated chip circuitry.
The processing circuit replaces, for each vector (row), each element of the vector (row) with a self-multiplication term. The processing circuit scales, for each vector (row), each element of the vector (row) where the scales are dependent on the denominator of the terms.
Translation: The chip alters and scales rows of data weights to simplify the calculations.
What this means for AI chips in cameras and edge devices
The attention bottleneck is one of the main reasons powerful AI vision models are still largely confined to data centers and cloud servers. Chips inside cameras, medical scanners, or autonomous drones simply don't have the memory bandwidth or compute budget to run full transformer models in real time. A credible approximation that fits inside programmable chip logic, the kind of hardware Xilinx (now part of AMD) specializes in, could move real image intelligence onto those devices.
AMD's steady stream of on-chip AI efficiency filings suggests the company is trying to own the edge inference space, the territory between a cloud server and a tiny embedded chip. For consumers, that eventually means your devices doing more sophisticated AI work locally, with less reliance on a server round trip and, in privacy-sensitive applications, less data leaving the device at all.
That makes this AMD's 34th filing we've tracked since May in the AI chip wars watchlist, adding to work like trimming unused AI software and keeping calculations accurate.
For most people, this patent will show up as a device that simply gets faster at recognizing what it sees, a security camera that flags something in real time, a medical scanner that processes an image without waiting for a server response. The underlying work is about making the math of visual recognition cheap enough to run on the device itself.
That locality matters. When a device handles its own analysis rather than shipping data elsewhere, decisions arrive sooner and sensitive images never leave the room.
The real question is whether the shortcut is accurate enough to trust. A faster answer that is wrong more often is not an improvement, it is a different problem. Whether this approach holds up under real conditions is what determines whether any user ever feels the difference.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time AMD patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
14 drawing sheets from US 2026/0267939 A1 · click any drawing to enlarge


Show the other 6 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in