
OpenAI Files Patent to Stop Its Voice AI From Sounding Like Someone Else
An AI that talks back can also be pushed into sounding like a real person or singing a copyrighted song. OpenAI's filing describes a watchdog that listens to the audio as it is made and shuts it down if it goes off script.
What OpenAI's voice watchdog actually does
A voice assistant is reading you a bedtime story in a calm, friendly voice. Halfway through, the sound slips toward a famous actor's voice, or the narrator starts singing a hit song. OpenAI filed a patent application for a way to catch that before it reaches your ears.
The idea is a second, smaller program that listens in while the AI speaks. It chops the audio into short, overlapping slices and gives each one a score for how closely it matches an approved voice, such as one recorded by a licensed voice actor. It can also score how much a slice sounds like music.
If two slices in a row look wrong, the watchdog tells the AI to stop talking and tells you it can't answer that request. A single odd slice is let through, so you aren't cut off over one hiccup.
… determining, by the safety engine, for a first window of the audio stream, a first score indicating a similarity between audio of the first window of the audio stream and a reference voice …
Translation: The system checks small chunks of generated speech to see how closely they match a protected target voice.
How the watchdog scores each slice of audio
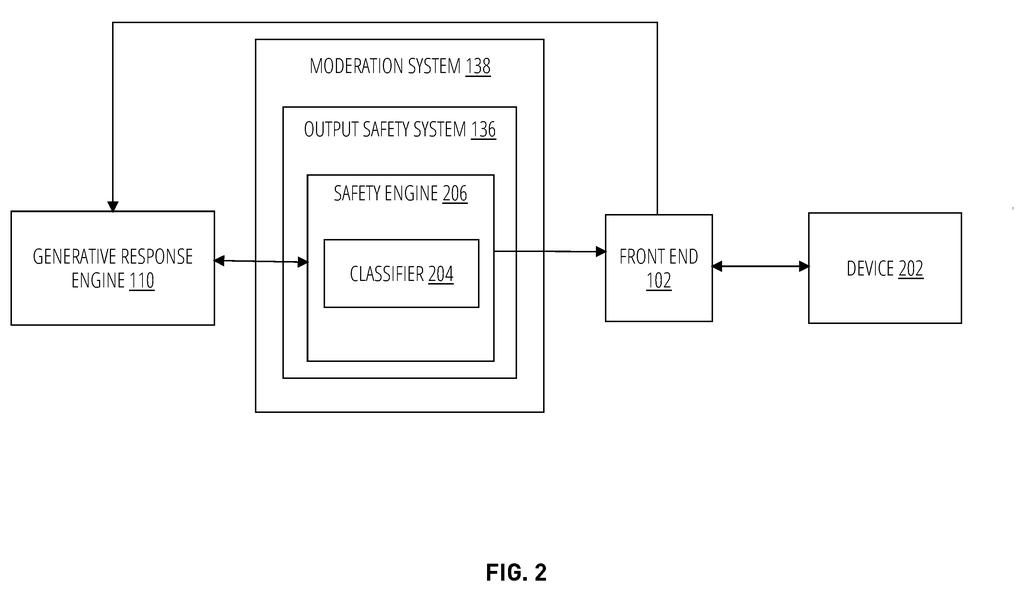
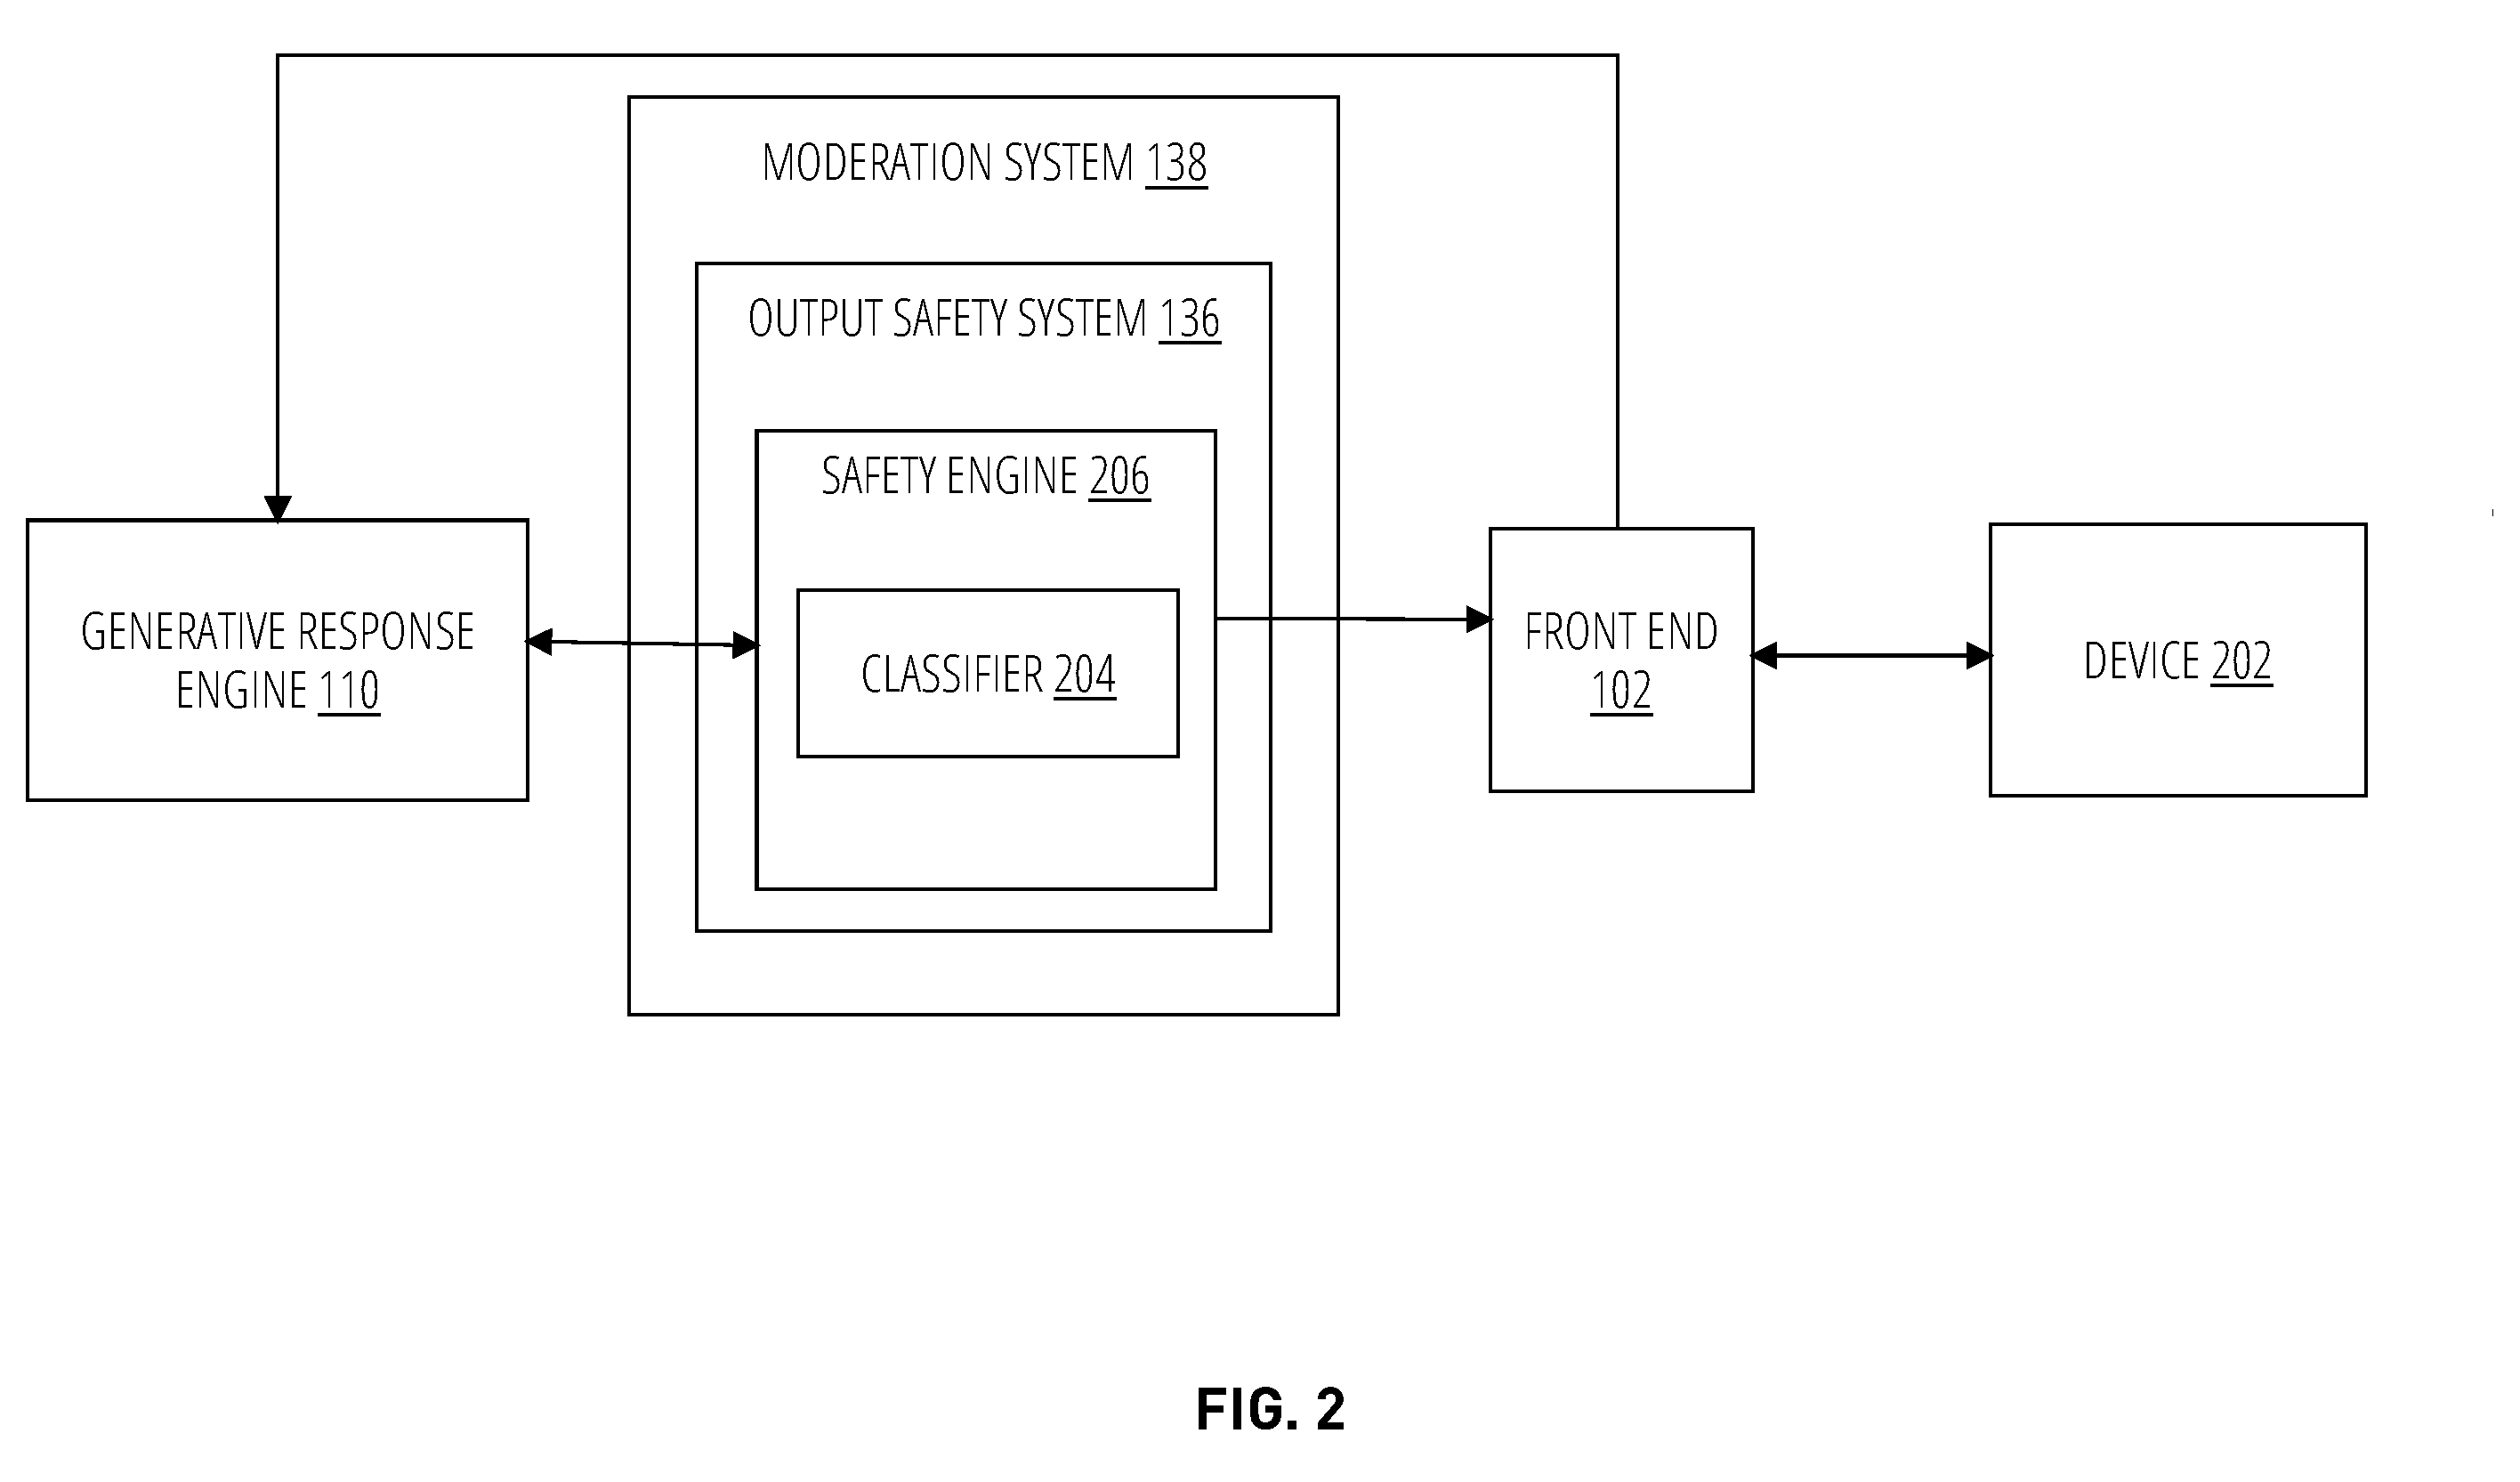
The patent describes a safety engine that sits between the AI model producing the speech (called a generative response engine) and the app that plays audio on your device (the front end). The model streams its audio to the safety engine as small chunks of data called tokens, before anything reaches you.
The safety engine then works like this:
- It splits the stream into windows, short slices of audio of a set length that can partly overlap.
- A classifier (a small AI model with far fewer parameters than the main model, built for one narrow job) gives each window a score showing how far the voice strays from a reference voice.
- The score is compared with a threshold, which an administrator can raise or lower to make the system more or less strict.
If two consecutive windows go over the threshold, the safety engine commands the main model to stop and generates a refusal message. If one window is over but its neighbor is fine, the audio still plays. The reference voice can be a machine-generated voice built from a human voice actor's recordings, and the main model can tell the safety engine which stored voice sample to use.
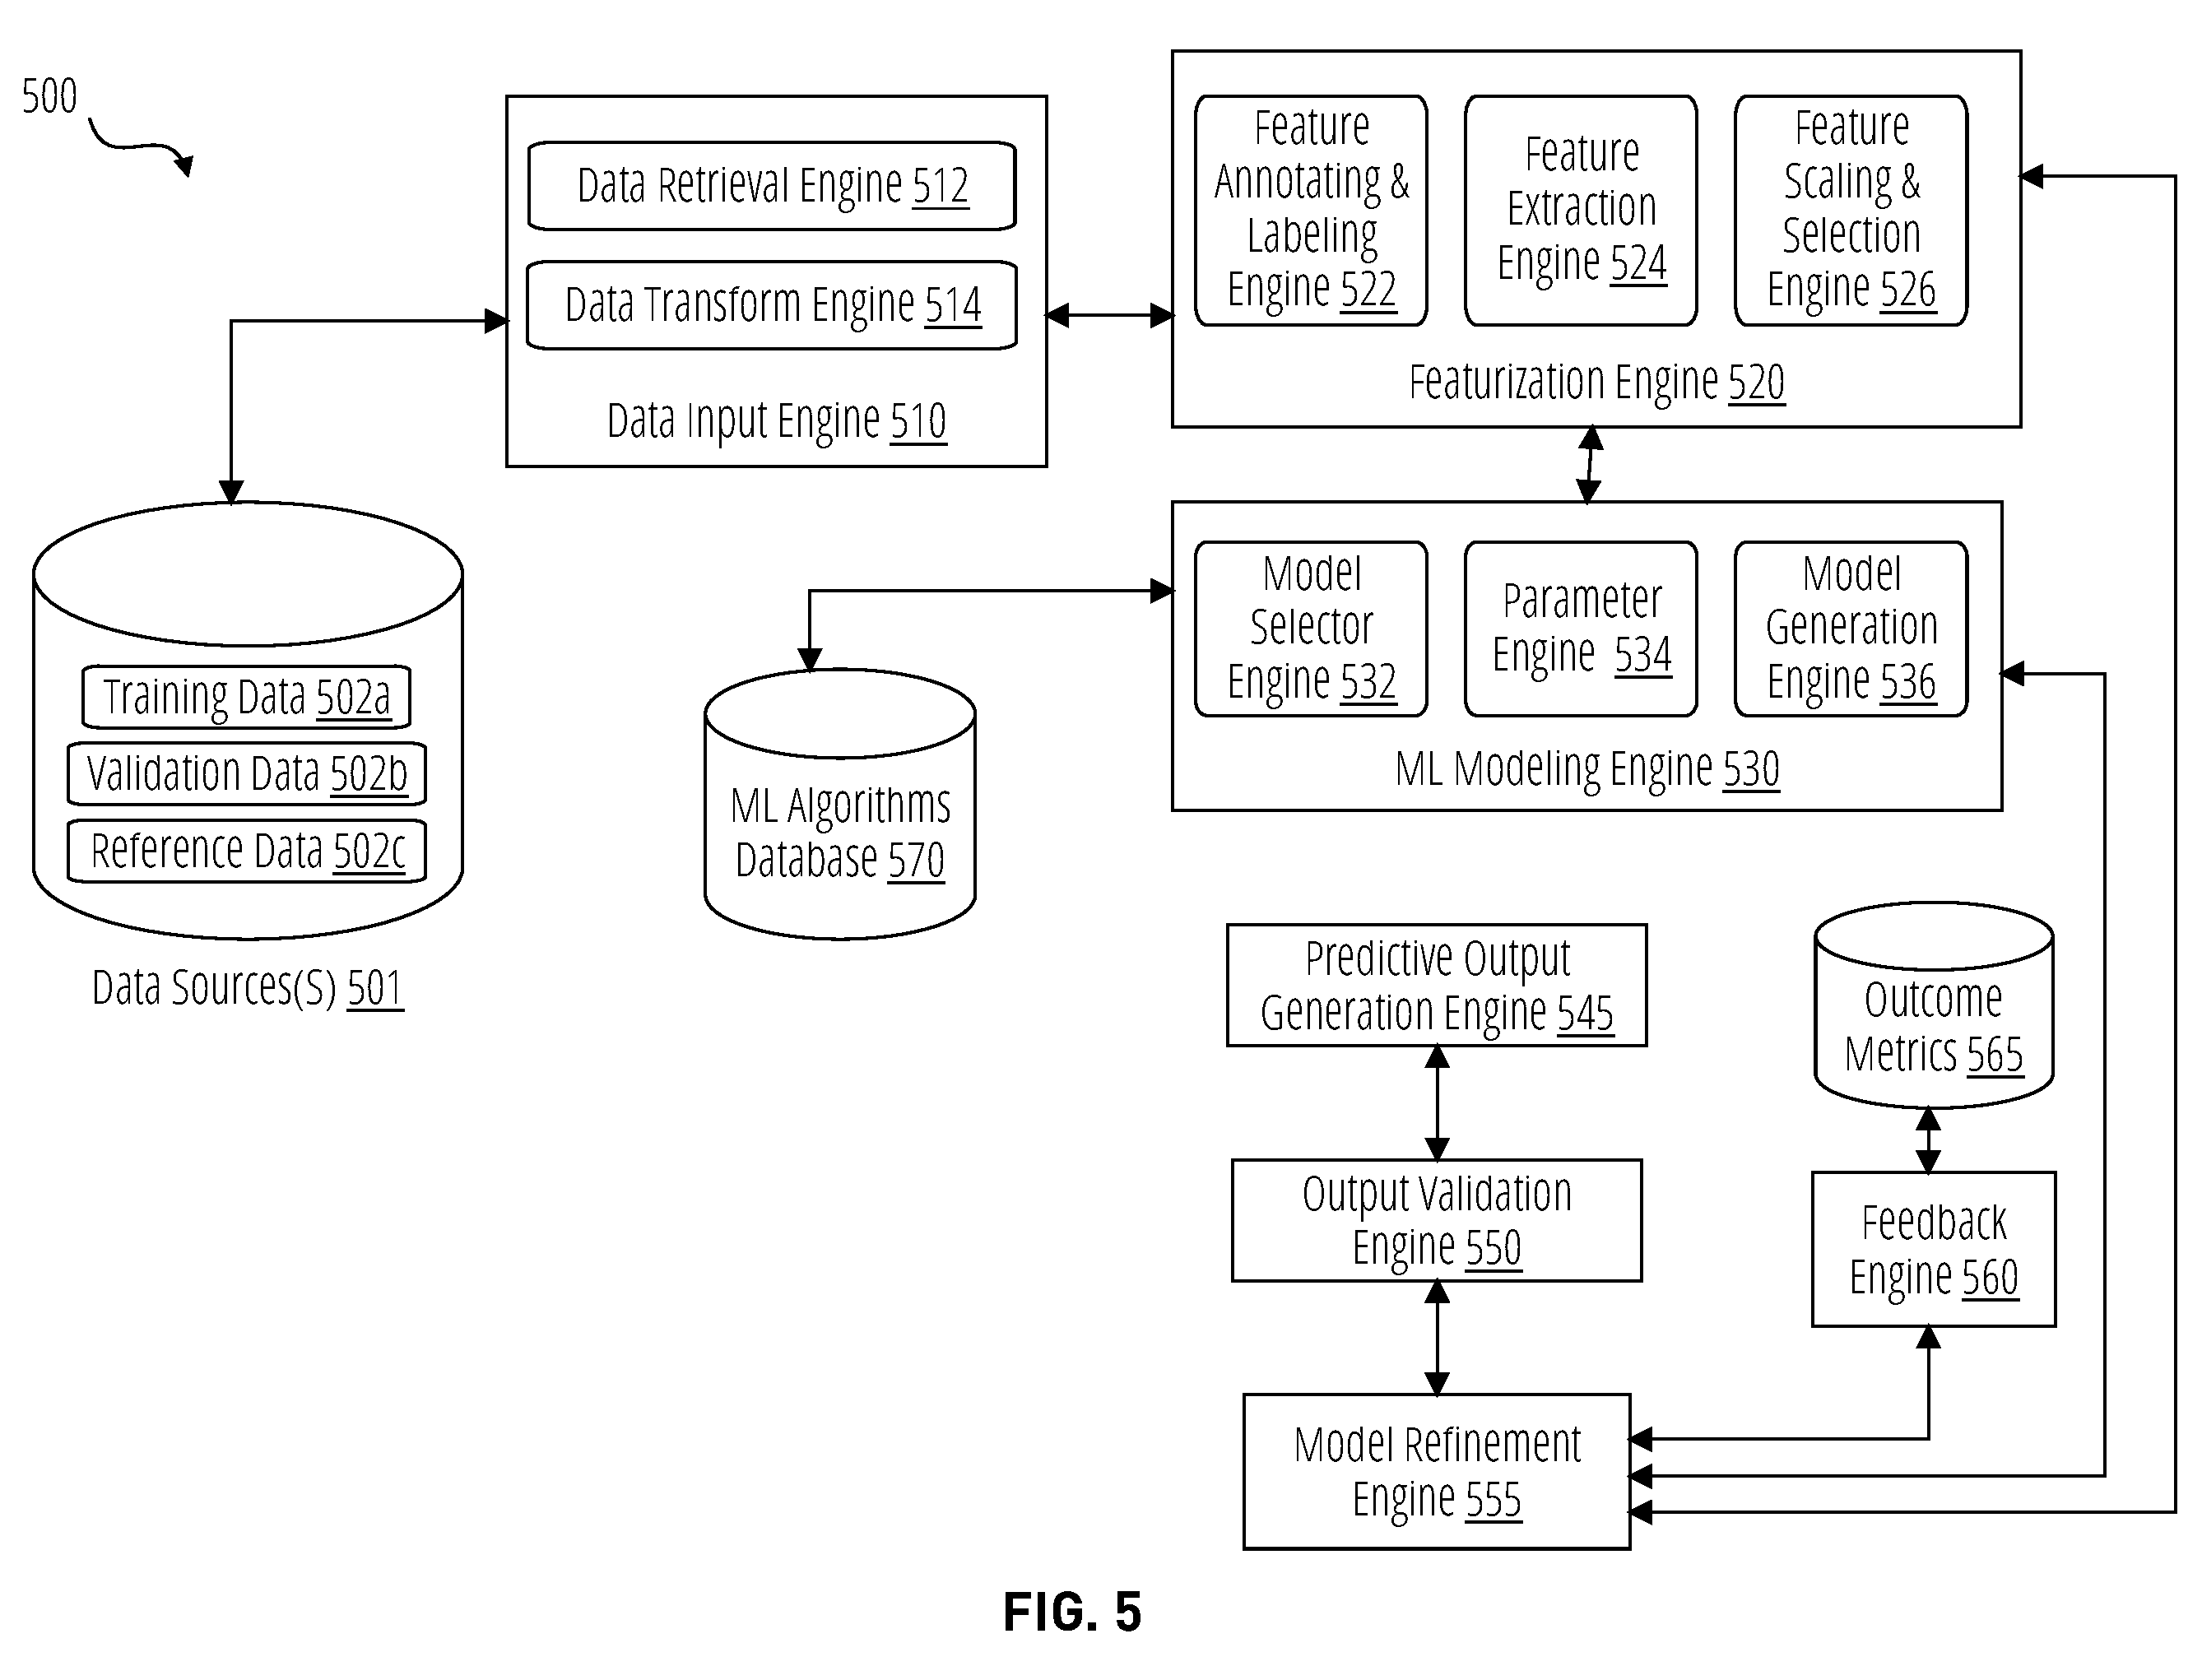
The same classifier, or a second one, can also produce a music score, looking for things like rhyme patterns, shifts in pitch, and percussive beats. The filing says the classifier can be trained on labeled audio, including synthetic audio made by another AI model.
… the first score and the second score are usable in determining whether to output the first window of the audio stream and the second window of the audio stream.
Translation: These similarity scores help the software decide whether it is safe to play the generated audio out loud.
Why voice cloning checks matter for chatbots
If you talk to a voice assistant, a check like this stands between a playful request and an audio clip that sounds like a politician saying something they never said. The filing also targets music, which can carry copyright or licensing limits. The checks run while the audio streams, and the filing says the goal is to avoid adding lag that would make a conversation feel sluggish.
For OpenAI, the filing describes a way to confirm that its voice models stay inside the licensed voices they were built around, and to log what they output. The adjustable threshold means the company could tune how strict it is. The filing names ChatGPT, DALL-E and Sora as examples of generative engines, but it does not tie this system to a specific launch.
This is the fifth OpenAI patent application we've tracked since September, joining earlier ones on pitting two models head-to-head and secure document answers, in our AI guardrails race.
Fake voices are a real and costly problem. A convincing clip of a politician or celebrity can spread before anyone checks it, and music that slips out of a chatbot can bring copyright trouble for the company that built it. Any product that talks in a human voice carries both risks every day.
The approach matches the size of that problem. A small watchdog that scores short slices as they stream is cheap enough to run on every response, and the two-in-a-row rule keeps one noisy moment from ruining a conversation. Because the voice is compared against a fixed set of licensed voices, the check has a clear yardstick.
The limit is that it catches voices that drift away from the approved ones. It says nothing about whether an approved voice is being used honestly. For a company putting talking AI in front of the public, a guardrail like this looks like a sensible minimum.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time OpenAI patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
8 drawing sheets from US 2026/0341299 A1 · click any drawing to enlarge





Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in