Qualcomm
Qualcomm · AI / ML · Filed Feb 14, 2025 · USPTO published Aug 20, 2026 · Aug 20 release
Qualcomm Patents AI That Cuts Out Objects in Video Using Text and Image Cues Together
Qualcomm has filed a patent for an AI system that can isolate objects in video frames by accepting two different kinds of instructions at the same time, such as a typed description and a tapped region, rather than forcing you to pick just one.
- Publication number
- US 2026/0245334 A1(US20260245334A1)
- Applicant
- QUALCOMM Incorporated
- Filed · Published
- Feb 14, 2025 · Aug 20, 2026
- Inventors
- Taotao JING, Shuai ZHANG, Eyasu Zemene MEQUANINT, Yingyong QI
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 382/156
- Examiner
- KOROMA, SORIE IBRAHIM (Art Unit 2662)
What Qualcomm's mixed-input video cutout system actually does
A security camera stares at an empty hallway all night. Eventually a person walks in, and you want the system to highlight just that person, not the whole frame. Today, most AI tools make you choose how to tell them what to find: either you draw a box, or you type a label, but rarely both at once.
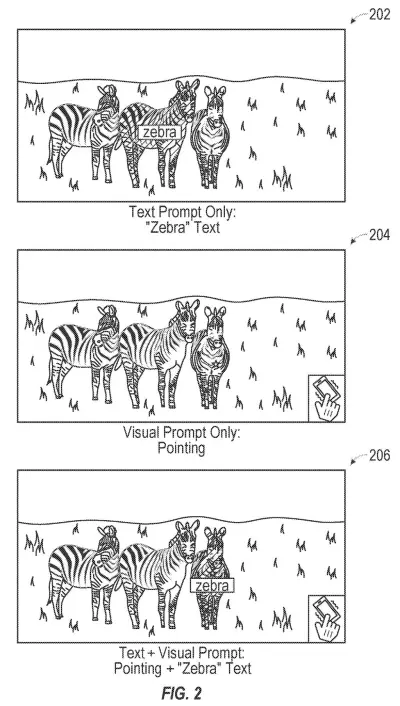
Qualcomm's patent describes a system that accepts two different kinds of input at the same time. You could, for example, tap a spot on the screen and type "person in a red jacket," and the AI would use both clues together to paint a precise outline around the right target. The result is a highlighted mask, a colored overlay, drawn right over the video frame.
The whole process is designed to run on the kind of chip Qualcomm builds for phones and cameras, not on a distant server. That matters because it keeps your video local and makes the response nearly instant.
… generate, by a neural network trained to perform mask segmentation based on a plurality of prompts, one or more masks for one or more target regions, in the frame, determined based on: the first prompt; the second prompt; and the plurality of single-scale features …
Translation: An AI creates precise cutouts using multiple types of instructions and video features combined.
How the neural network combines two prompt types into one mask
The patent describes an apparatus, most likely a chip or system-on-chip, whose processing system runs a neural network trained specifically for mask segmentation (drawing pixel-precise outlines around objects in an image or video frame).
What makes this different from standard segmentation is the input side. The system takes two "prompts" from two different modalities (types of input), such as:
- A text description, for example "the dog near the door"
- A visual cue, for example a tapped point, a drawn box, or a reference image crop
Both prompts are fed into the neural network simultaneously. The network also pulls what the patent calls single-scale features from the frame, meaning it extracts a single, fixed-resolution representation of the image rather than processing it at multiple zoom levels. Single-scale extraction is computationally lighter, which is important for running on mobile hardware.
The network combines all three inputs (prompt one, prompt two, and the frame features) and outputs one or more masks, colored overlays that mark the target region. The final frame, with the mask applied, is then sent to the display. The design is explicitly built to handle multiple prompts, not just one, making the segmentation more precise when the user's intent is ambiguous from a single signal alone.
… obtaining a first prompt associated with a first modality; obtaining a second prompt associated with a second modality that is different than the first modality …
Translation: The system accepts two different input types like text and images to guide the editing process.
What this means for AI cameras and on-device processing
Qualcomm makes the processors that go inside Android phones, security cameras, AR headsets, and automotive systems. A segmentation method designed to run efficiently on those chips, without sending video to the cloud, has practical applications across all of those product categories. For you as a user, it could mean your phone's camera app highlights exactly the subject you want edited, or a smart-home camera flags the specific person you described, faster and without a network connection.
The ability to combine a typed description with a visual pointer is the more interesting part of the claim. Segmentation tools that accept only one type of input can misfire when a scene is crowded or ambiguous. Using two modalities together narrows the target more reliably. Qualcomm's chip division has been filing steadily in on-device AI, and this patent joins a broad stream of interesting tech patents focused on running complex vision tasks directly on mobile and edge processors rather than in the cloud.
Qualcomm's sixth filing we've tracked in our AI photo editing race watchlist since July builds on one rendering parts at different resolutions and one exposing objects separately.
Source: US 2026/0245334 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Qualcomm patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 8 sheets
8 drawing sheets from US 2026/0245334 A1 · click any drawing to enlarge


More from Qualcomm
All 637 Qualcomm patents →
More in AI vision
All 351 AI vision patents →
Google
Google Patents a Camera App That Erases People First, Then Tells You Where to Put Them Back
Sony
Sony Patents a System That Lets AI Style Game Objects From Your Own Photos
Google
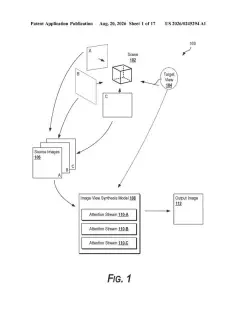
Google Patents a Way to Let AI Reconstruct Any Camera Angle From a Few Photos
Adobe