
Qualcomm
Qualcomm · AI / ML · Filed Mar 20, 2025 · USPTO published Sep 24, 2026 · Sep 24 release
Qualcomm Patents a Way to Update On-Device AI Models Without Replacing the Whole File
Every AI model running on your phone is essentially a giant file full of numbers. Qualcomm has filed a patent for a way to surgically update just the parts that need changing, without touching the rest.
- Publication number
- US 2026/0289390 A1(US20260289390A1)
- Applicant
- QUALCOMM Incorporated
- Filed · Published
- Mar 20, 2025 · Sep 24, 2026
- Inventors
- Nirmit Nayan ZINZUWADIA, Brandon LIEBMAN, Prathamesh Prakash PRABHUDESAI, Shiu Wai HUI, Jian WANG, Veluppillai ARULESAN, Jeffrey Baginsky GEHLHAAR
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 706/12
How Qualcomm patches AI brains without a full reinstall
Every time your phone runs an AI feature, whether it's a camera filter, a voice assistant, or a text suggestion, it's pulling from a file packed with millions of tiny numbers called weights. Those numbers are what make the AI behave the way it does. When the AI needs to improve or adapt, the usual approach is to swap out the whole file, which is slow and wastes storage.
Qualcomm's patent describes a different approach: instead of replacing everything, the system finds exactly where the relevant numbers live inside the file, rewrites only those specific spots, and leaves the rest untouched. Think of it like correcting individual sentences in a book rather than printing a new edition.
The goal is to let AI models on phones and other chips get updated faster and more efficiently, which matters especially on devices with limited storage and no guarantee of a strong internet connection.
obtain a plurality of update weights to apply to respective update layers of a plurality of update layers of an executable file representative of a machine-learning model …
Translation: The system gathers new weights to apply to specific layers inside an AI model's executable file.
How the chunk-and-offset system rewrites model weights
The patent covers a process Qualcomm calls parameter rehydration. At its core, it's a technique for modifying the binary executable file (the compiled, runnable version of a machine-learning model) without rewriting the whole thing from scratch.
Here's the sequence the system follows:
- Extract weights: Pull out the existing numerical parameters (weights) from the executable file. These weights encode what the AI model has learned.
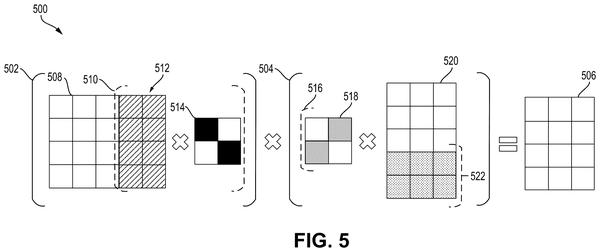
- Chunk and locate: Split those weights into smaller blocks (chunks) and record exactly where each chunk sits inside the file, measured as an offset from a fixed reference point.
- Transform update weights: Take the incoming update weights, run them through a transformation step that matches the format already used in the file, and divide those too into chunks.
- Map to offsets: Use the original chunk positions to figure out exactly where each updated chunk needs to land in the file.
- Insert: Write the transformed, updated chunks into those precise locations, producing a revised executable.
The transformation step is important because model weights stored in a compiled binary are often encoded or reordered for performance reasons. The system has to reverse-engineer that layout, apply updates in the same coordinate system, and then re-encode before inserting.
… dividing the plurality of weights into a plurality of chunks; identifying a respective chunk offset relative to a reference point in the executable file for each chunk of the plurality of chunks …
Translation: It breaks the existing weights into smaller pieces and tracks their exact locations inside the file.
What this means for AI updates on phones and chips
For consumers, the immediate payoff is smaller, faster AI updates on phones and other edge devices. Instead of downloading a full model file every time an AI feature improves, the device could receive a much smaller patch and apply it locally. That's useful on a slow connection and even more useful on a device with tight storage, like a wearable or a car's onboard computer.
For Qualcomm specifically, Qualcomm keeps filing on on-device AI inference and model deployment, and this patent fits that pattern. The company's chips power a huge share of Android phones, and making AI updates leaner directly supports the pitch that its hardware handles AI efficiently without constant cloud round-trips.
Qualcomm's 55th filing we've tracked since July in the AI chip competition adds another layer to their work on splitting processor power and parallel AI calculations.
Source: US 2026/0289390 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Qualcomm patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 14 sheets
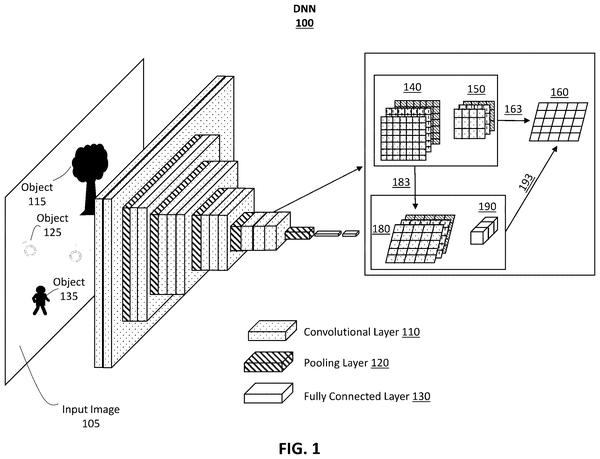
14 drawing sheets from US 2026/0289390 A1 · click any drawing to enlarge


Show the other 6 sheets


More from Qualcomm
All 624 Qualcomm patents →
More in AI training & infrastructure
All 316 AI training & infrastructure patents →
AMD
AMD Patents a System That Compresses AI Model Data Before It Leaves the GPU
Microsoft
Microsoft Patents a Traffic Director for AI Training Data Inside Data Centers
AMD
AMD Patents a Method to Run AI Vision Models With Far Less Computation
Intel
No comments yet