
Qualcomm
Qualcomm · AI / ML · Filed Feb 19, 2025 · USPTO published Aug 20, 2026 · Aug 20 release
Qualcomm Patents a Faster Way to Compress AI Model Data for Chips
Every AI model is a massive pile of numbers, and squeezing those numbers through a chip quickly is one of the hardest problems in on-device AI. Qualcomm's new patent takes a targeted approach: figure out which parts of the data can actually shrink, and only compress those.
- Publication number
- US 2026/0246480 A1(US20260246480A1)
- Applicant
- QUALCOMM Incorporated
- Filed · Published
- Feb 19, 2025 · Aug 20, 2026
- Inventors
- Amir Said
- Status when we published
- Examiner raised objections; the company can respond
- Document
- 20 claims
- US classification
- 341/50
- Examiner
- JEANGLAUDE, JEAN BRUNER (Art Unit 2845)
How Qualcomm shrinks AI model data before shipping it to a chip
A delivery truck carries thousands of identical cardboard boxes every day, most packed loosely, a few crammed full. Smart packers don't waste time trying to compress the full ones, they focus on the loose ones. You can picture the same logic applying to data inside a chip.
Qualcomm's patent describes a way to sort through the raw numbers that make up an AI model, the billions of tiny values called weights that tell the model how to think, and decide upfront which ones can be compressed and which ones can't. The compressible numbers get squeezed; the rest are left alone and copied as-is. The whole thing is arranged so a chip can read it in tidy, predictable chunks.
The result is faster loading and processing of AI models without wasting time trying to compress data that won't budge. That matters most when AI runs directly on a phone or a small device, where storage and processing power are tight.
determining bits of quantized data that are compressible and non-compressible based on one or more properties of the quantized data; performing a byte-aligned rearrangement of the bits of the quantized data; applying a compression technique to at least one compressible bit; and copying at least one non-compressible bit.
Translation: The system sorts AI data into parts that can be shrunk and parts that cannot, then rearranges them to save space.
How the byte-sorting step separates compressible from fixed bits
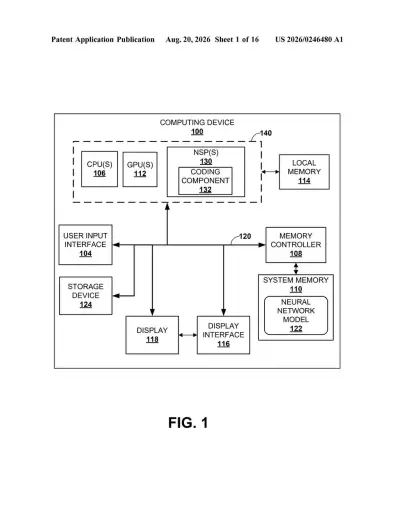
The patent centers on a process for encoding the quantized parameters (the simplified, rounded-down numbers that represent a neural network's learned behavior) in a way that a hardware decoder can handle at high speed.
Here is how the process works:
- Sort the bits: The system looks at properties of the quantized data to decide which individual bits are likely to compress well and which are essentially random noise that won't compress at all.
- Rearrange into byte-aligned blocks: The bits are reorganized so that compressible bits and non-compressible bits sit in predictable positions. "Byte-aligned" means the data lines up on boundaries a processor can read in one clean step, rather than at awkward offsets that slow things down.
- Compress selectively: A standard compression algorithm is applied only to the compressible bits. The non-compressible bits are simply copied straight through, saving the CPU or hardware decoder from wasting cycles on data that won't shrink.
- Decode in a stream: On the receiving end, the decoder reads a stream of bytes, identifies which bytes were compressed, decompresses those, and extracts the original values.
The key insight is that neural network weights, after quantization (the process of rounding full-precision numbers down to smaller integer formats to save space), have a predictable structure. Some bits are highly repetitive and compress well; others are essentially entropy, and forcing compression on them just adds overhead with no benefit.
… the data can be decoded by identifying a compressed byte in a stream of bytes, decompressing the compressed byte, and extracting bits from the stream of bytes that encode quantized data.
Translation: To use the data, the chip finds the compressed sections, expands them, and pulls out the original AI information.
What this means for running AI on phones and edge devices
For anyone using a phone or a laptop with on-device AI features, the bottleneck is rarely the AI model itself; it is the time it takes to load that model into the chip and start running it. A faster, leaner encoding scheme means AI features start more quickly, use less memory bandwidth, and leave more headroom for battery life.
Qualcomm supplies the chips inside a huge share of Android phones and many laptops, so an efficiency gain at this level of the stack touches a lot of devices. The compression and neural-network chip space has attracted a steady stream of interesting tech patents as companies race to make AI inference faster without requiring larger, hotter, or more expensive hardware.
Qualcomm's 36th filing we've tracked in our AI chip wars watchlist since July adds to a run that includes one on chip-level task ordering and one on memory handling multiple jobs.
Source: US 2026/0246480 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Qualcomm patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 16 sheets
16 drawing sheets from US 2026/0246480 A1 · click any drawing to enlarge


Show the other 8 sheets


More from Qualcomm
All 637 Qualcomm patents →
More in AI training & infrastructure
All 324 AI training & infrastructure patents →
Microsoft
Microsoft Patents AI Training That Splits Historical Data Across Multiple Workers Simultaneously
Nvidia
Nvidia Patent Reveals AI Models That Reshape Themselves Mid-Task Based on Chip Power
Nvidia
Nvidia Patents AI Models That Shrink and Grow to Match Your Chip's Workload
Nvidia
