
Adobe
Adobe · AI / ML · Filed Mar 19, 2025 · USPTO published Sep 24, 2026 · Sep 24 release
Adobe Patents a Training System That Teaches AI Video to Track Moving Objects Frame by Frame
One of the biggest problems with AI-generated video is that objects drift, morph, or lose track of themselves mid-clip. Adobe has filed a patent for a training method that explicitly teaches an AI model to keep specific points on a moving object in the right place, frame after frame.
- Publication number
- US 2026/0289737 A1(US20260289737A1)
- Applicant
- Adobe Inc.
- Filed · Published
- Mar 19, 2025 · Sep 24, 2026
- Inventors
- Duygu Ceylan Aksit, Niloy Jyoti Mitra, Hyeonho Jeong, Chun-hao Huang
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 382/157
- Examiner
- OAKES, JUSTIN MONTGOMERY (Art Unit 2662)
What Adobe's point-tracking video AI actually does
Today's AI video generators are surprisingly bad at keeping track of where things are. A person's hand might teleport between frames, or a logo on a shirt might warp as the camera moves. These aren't bugs exactly, they're a consequence of how most video AI is trained: to make each frame look good in isolation, without enough attention to whether objects stay consistent across time.
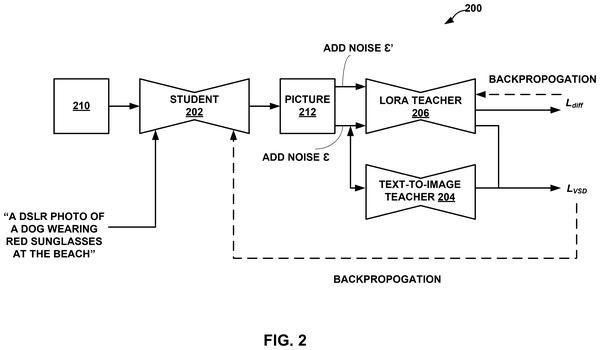
Adobe's patent describes a training approach that adds a second teacher to the process. One part of the AI learns to clean up noisy, blurry frames (the usual job). A second module, called a refiner, learns something different: it checks whether specific points on a moving object stay in the right spatial relationships across every frame. If a shoulder should move a certain way through a sequence, the refiner tracks whether the AI's output actually reflects that.
The result, Adobe says, is a model that can generate video of a target object performing a specific movement, with the motion staying accurate and coherent from start to finish. Think of it as training the AI to have a sense of spatial memory, not just visual style.
… generate, using a machine-learning model and based on the input, the digital video depicting the target object with the reference movement, the machine-learning model trained to minimize a diffusion loss and a correspondence loss …
Translation: The AI creates the video by continuously reducing two specific types of mathematical errors during training.
How the denoiser and refiner split the training work
The system trains a diffusion model (an AI that generates images by learning to remove artificial noise, a process similar to developing a photo from static) to produce video that stays physically consistent across frames.
Training involves two simultaneous objectives:
- Diffusion loss: The denoiser learns to reconstruct clean video frames from noisy ones, which is the standard way diffusion video models are trained.
- Correspondence loss: A separate refiner module tracks how specific points (think: the tip of a finger, the edge of a wing, a logo on a jersey) move across frames. If those points don't match the reference movement the model was given, the loss goes up, penalizing the model until it learns to keep them consistent.
The refiner operates in a feature space (an internal mathematical representation the model uses to reason about content, not the raw pixel level), which means it can catch spatial inconsistencies before they ever appear in the final output.
At inference time (when the trained model is actually used), a user provides an input describing a target object and a reference movement. The model generates a video clip in which that object performs that movement, with point-level spatial consistency baked in through the dual training signal.
A refiner module of the machine-learning model is trained to refine latent features of the noisy video frames by minimizing a correspondence loss that quantifies a spatial correspondence among multiple points in the noisy video frames in relation to the reference movement.
Translation: A special module helps the AI track how specific points on an object move across different frames.
What this means for AI-generated video consistency
For anyone using AI video tools, whether in creative work, advertising, or content production, object drift is one of the most tedious problems to fix manually. A system trained this way could produce clips where a person's gesture, an animated character's limb, or a product's shape stays true across every frame without needing hand-correction.
Adobe's run of generative video filings suggests this is part of a broader effort to make AI-generated video production-ready rather than a novelty. Claim 1 of this patent is written at a fairly high level of abstraction: it covers any system using a model trained with both a diffusion loss and a correspondence loss to generate video. That breadth means, if granted, the patent could apply to a wide range of video generation pipelines, not just Adobe's own implementation.
Adobe's 42nd filing we've tracked since May in the AI photo editing race follows one that picks editing modes and video edits from one photo.
Source: US 2026/0289737 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Adobe patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 13 sheets
13 drawing sheets from US 2026/0289737 A1 · click any drawing to enlarge


Show the other 5 sheets


More from Adobe
All 264 Adobe patents →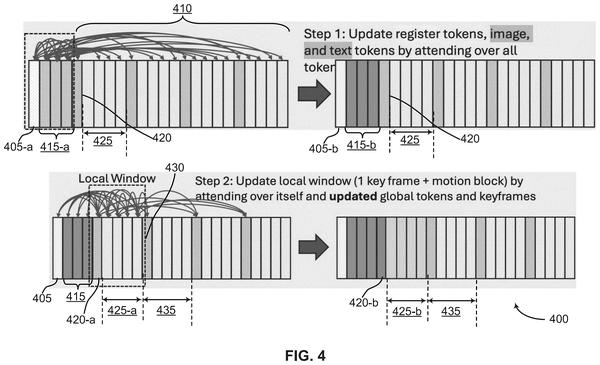
More in AI image & video
All 223 AI image & video patents →
Google
Google Patents a Text-Driven Photo Editing System That Learns by Studying Subtle Image Differences
Samsung
Samsung Patents an AI Photo Editor That Borrows From Your Other Photos
OpenAI
OpenAI Patents a System That Picks Your Best Photos and Redraws Them as AI Art
Microsoft
No comments yet