IBM
IBM · AI / ML · Filed Feb 11, 2025 · USPTO published Aug 13, 2026 · Aug 13 release
IBM Patent Describes AI That Writes and Self-Grades Its Own Synthetic Data Code
Building AI requires massive amounts of training data, and IBM just filed a patent for a system where one AI writes multiple versions of data-generating code and a second AI picks the best one automatically.
- Publication number
- US 2026/0236235 A1(US20260236235A1)
- Applicant
- International Business Machines Corporation
- Filed · Published
- Feb 11, 2025 · Aug 13, 2026
- Inventors
- Yuan Yuan Ding, Shi Yun Liang, Zhong Fang Yuan, Tong Liu
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 717/104
How IBM's two-AI pipeline produces synthetic data
Training AI models takes enormous amounts of data, and getting that data is expensive and slow. Companies increasingly use synthetic data (data that an AI makes up rather than collects from the real world) to fill the gap, but writing the programs that generate good synthetic data is itself a technical headache.
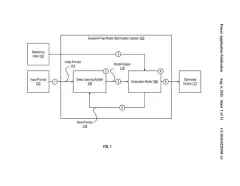
IBM's patent describes a two-step system. First, an AI is given a plain-English instruction and responds by writing several different code programs, each designed to produce synthetic data. Then a second, separate AI reviews all those code options and picks the one it judges to be the best. The winning code is run, and the synthetic data it produces is saved.
The appeal here is that the whole process runs without a human having to write or review any code. You describe what you need in plain language, and the pipeline handles the rest, from writing the programs to choosing between them.
… inputting the multiple versions of the workflow code into at least one evaluator machine learning model such that, in response, the at least one evaluator machine learning model selects one of the multiple versions of the workflow code …
Translation: An AI grader reviews the different options and picks the best piece of code.
How the evaluator AI picks the winning code version
The system works in three main stages:
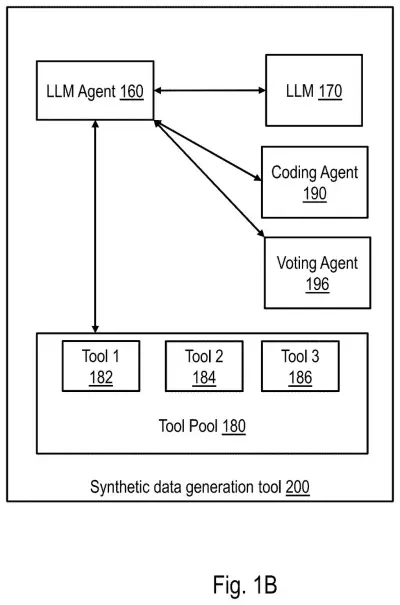
- Prompt generation: A natural-language prompt (a plain-English instruction) is created that tells a generative AI model to produce multiple versions of workflow code (small programs whose job is to generate synthetic data). The AI writing the code has been specifically trained for code-related tasks.
- Code evaluation: All the generated code versions are handed to at least one evaluator AI model, also trained for code tasks, which compares them and selects the best one. The patent doesn't lock in a single selection method, leaving room for quality scoring, correctness checks, or other criteria.
- Data generation and storage: The selected code is actually executed, producing the synthetic data, which is then stored for later use in training other AI models.
The key architectural choice is the separation of generation (one AI writes options) from evaluation (a different AI judges them). This mirrors how software teams use code review: the person who wrote the code isn't the one who approves it. Both models are described as having been trained specifically on code-related tasks, which distinguishes them from general-purpose AI assistants.
According to a technique of synthetic data generation, natural language workflow prompt is generated that includes instructions to generate multiple versions of workflow code for generating synthetic data.
Translation: Plain English instructions tell the AI to create several different code options for making artificial data.
What this means for AI training data at scale
For any company building AI models, high-quality training data is the bottleneck. Synthetic data is already a common workaround, but producing it well usually requires data engineers who know how to write the generation scripts and verify their output. A pipeline that automates both the writing and the selection step compresses that labor significantly.
Claim 1 of this patent is broad: it covers any method that uses a generative model to produce multiple code versions and an evaluator model to pick one, with the output being synthetic data. That breadth means IBM could assert this against a wide range of two-model code-and-judge pipelines, not just one narrow implementation. If granted, it would apply pressure on any AI platform that automates synthetic data generation this way. IBM's AI training data work sits among the plain-English patent summaries Patentlyze tracks across the synthetic data and enterprise AI space.
Source: US 2026/0236235 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 4 sheets
4 drawing sheets from US 2026/0236235 A1 · click any drawing to enlarge


More from IBM
All 470 IBM patents →
More in AI training & infrastructure
All 316 AI training & infrastructure patents →
Google
New Patent Cuts the Cost of Running AI That Handles Many Tasks at Once
Salesforce
Salesforce Patents a System That Coaches AI Into Giving More Accurate Answers
Google
Patent: Google AI Learns From Its Own Errors to Improve Future Predictions
Sony