
Qualcomm
Qualcomm · Chip · Filed Feb 20, 2025 · USPTO published Aug 20, 2026 · Aug 20 release
Qualcomm Patents Technology That Lets Multiple Tasks Share a Memory Unit's Built-In Processing Power
Qualcomm has filed a patent for a system that lets one physical memory-processing unit pretend to be several independent ones, so different parts of a chip can each use it without stepping on each other.
- Publication number
- US 2026/0244473 A1(US20260244473A1)
- Applicant
- QUALCOMM Incorporated
- Filed · Published
- Feb 20, 2025 · Aug 20, 2026
- Inventors
- Subbarao Palacharla, Christopher Lott, Girish Bhat
- Status when we published
- Waiting for an examiner
- Document
- 21 claims
- US classification
- 718/1
What Qualcomm's in-memory chip-sharing system actually does
Right now, a chip that does computing inside its own memory (a trick that cuts down on slow back-and-forth data trips) can only serve one part of the processor at a time. If several parts want to use it, they wait in line or things break down.
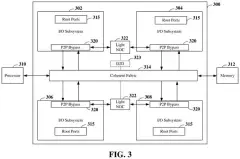
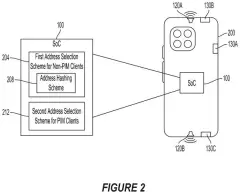
Qualcomm's patent describes a thin slice of organizing logic sitting inside the memory controller. It creates the illusion of several copies of that memory processor, even though only one real unit exists. Each part of the chip believes it has its own private unit, sends requests freely, and the organizing logic sorts and handles those requests in an orderly way.
The system also saves each user's progress when it has to switch between them, much like your phone pausing one app and picking it back up later without losing anything. The goal is to get more work out of expensive memory hardware without buying or building more physical chips.
… translate the received one or more PIM operation requests into one or more PIM operations and interleave the one or more PIM operations.
Translation: It converts incoming task requests and mixes them together so they can share the memory chip's processor.
How the translation layer juggles competing processor requests
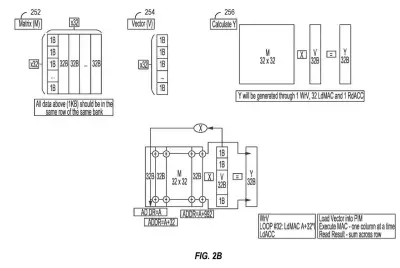
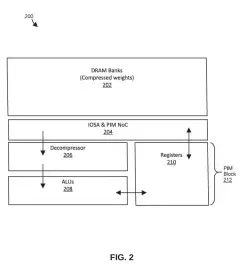
The patent describes an architecture centered on a Process-In-Memory (PIM) unit, a processor that lives inside the memory chip itself rather than on the main processor die. Moving computation closer to data reduces how often the chip has to ferry information back and forth across a slow bus, which matters a lot for tasks like AI inference.
The problem the patent solves is virtualization: how do you let multiple independent processor clients (different cores, accelerators, or subsystems on a system-on-chip, or SoC) share one physical PIM unit without interfering with each other? The answer is a translation layer inside the memory controller that sits between the clients and the hardware.
The translation layer does three things:
- Presents virtual interfaces to each SoC client, so every client thinks it has a dedicated PIM unit of its own.
- Translates and interleaves incoming requests, meaning it converts each client's instructions into physical PIM operations and schedules them so they don't collide.
- Manages context switching, saving the operational state of one client and restoring another's when the physical unit needs to switch focus, much like a CPU switching between processes.
The design also includes arbitration, a referee mechanism that decides whose request goes next when several clients ask at once. Importantly, the patent says the virtual interfaces stay consistent even if the underlying PIM hardware changes, which would make it easier to swap or upgrade the physical memory chip without rewriting software for every client.
… allowing each client to interact with what appears to be its own dedicated PIM unit.
Translation: It tricks different programs into thinking they each have exclusive access to the memory's built-in processing power.
What this means for AI chips and mobile processing
PIM chips are increasingly attractive for AI workloads on mobile and edge devices, where memory bandwidth is tight and power budgets are small. The catch is that most real chips have many competing subsystems (a CPU, a GPU, a neural-processing unit) all wanting the same fast-memory shortcut. Without a sharing mechanism, one unit monopolizes the resource or the chip designer has to add redundant PIM hardware, which costs area and power.
For someone using a phone or tablet built on a future Qualcomm SoC, the practical payoff would be AI features and background tasks running more efficiently at the same time, rather than one hogging the fast lane while others wait. This kind of memory-controller patent sits below the surface but shapes how well those features co-exist, and it joins a growing body of interesting tech patents in the chip architecture space that show how companies are engineering around the physical limits of memory bandwidth.
Qualcomm's 32nd filing we've tracked in the AI chip wars since July follows its work on a low-power video filter and shared AI processing between devices.
Source: US 2026/0244473 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Qualcomm patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 9 sheets
9 drawing sheets from US 2026/0244473 A1 · click any drawing to enlarge


Show sheet 9

More from Qualcomm
All 637 Qualcomm patents →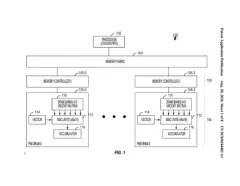
More in Chip
All 651 Chip patents →
Microsoft
Microsoft Patents a Way to Route Database Queries Through a GPU
Apple
Apple Patents a Way for Its AI Chips to Juggle Multiple Tasks Without Losing Their Place
Nvidia
Nvidia Patents a Number-Rounding Shortcut for AI Math That Eats Chip Power
Samsung
