
Tesla
Tesla · AI / ML · Filed Mar 26, 2026 · USPTO published Oct 1, 2026 · Oct 1 release
Tesla Patents a Way to Make Robot AI Run Faster Without Bigger Chips
Running a neural network inside a robot is expensive in two ways: compute and power. Tesla's new patent describes a technique that compresses the numbers feeding into that network on the fly, potentially letting the same chip do far more work.
- Publication number
- US 2026/0299533 A1(US20260299533A1)
- Applicant
- TESLA, INC.
- Filed · Published
- Mar 26, 2026 · Oct 1, 2026
- Inventors
- Ritvik RAWAT, Valeriy ROTAN, Alex SINGH, Srihari SAMPATHKUMAR
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 701/27
- Parent application
- Claims priority from a provisional application 63780070 (filed Mar 28, 2025)
How Tesla shrinks the math inside a robot's brain
Every time a Tesla robot takes a step or picks up an object, a neural network is doing the math behind that decision. That network chews through enormous streams of numbers, and every number has to be stored and processed with enough precision to avoid mistakes.
The problem is that high-precision numbers are slow and power-hungry. This patent describes a system that watches those numbers as they arrive, figures out the biggest value in the group, and uses that to squeeze every other value into a smaller, cheaper format before the neural network ever sees them. The squeeze happens dynamically, meaning it adjusts in real time rather than being baked in at the factory.
The practical effect: the robot's processor handles lighter math during operation, which can mean faster decisions, lower energy draw, or the ability to run a more capable AI on the same hardware. It's the kind of optimization that rarely appears in a press release but shows up directly in how well a robot performs hour after hour.
… adjust each value of the first set of values based on the maximum absolute value; quantize the first set of values based on an exponent and a mantissa of each value to generate a quantized set of values having a second data format …
Translation: It shrinks data sizes by scaling numbers based on the largest one present.
How the quantizer reshapes numbers before the neural network sees them
The patent covers a process called dynamic quantization, which is essentially a real-time compression scheme for the numbers a neural network processes. Instead of storing every value as a large, high-precision floating-point number (the format computers normally use for math that needs decimal places), the system converts them into a smaller format just before they enter the network.
Here's how the conversion works:
- The system scans the incoming batch of numbers and finds the maximum absolute value (the biggest number, ignoring sign).
- It uses that maximum to calculate a scaling factor, a multiplier that maps the whole range of values into a tighter numerical space without losing too much information.
- For each number, it restructures the internal bit layout: specifically, it takes a bit away from the exponent portion (the part that controls how large a number can be) and moves it to the mantissa (the part that controls precision). This trade-off is tuned to the actual data range being processed.
- Sign bits are extracted and each value is bit-shifted (a fast arithmetic trick equivalent to dividing by a power of two) so all values align in the new format.
The resulting quantized values are then fed into the neural network. Because they're in a smaller format, the network's multiply-and-add operations complete faster and consume less energy. The robot's control system then acts on whatever output the neural network produces.
… removing at least one bit from the exponent portion and redistributing it to the mantissa portion.
Translation: It reallocates memory bits to keep math precise while using less space.
What this means for putting AI in affordable robots
Neural networks that run inside physical robots face a constraint that cloud-based AI doesn't: the hardware has to fit in the robot's body, draw from an onboard battery, and respond in milliseconds. Quantization is one of the main ways engineers close that gap, and doing it dynamically at runtime is harder and more powerful than doing it once during training.
For you as a consumer or an observer of the robotics industry, this kind of work is what determines whether an autonomous robot can be built at a price that makes sense outside a research lab. Tesla's track record in robotics AI patents suggests the company is investing seriously in the software layer that makes the Optimus robot tick, and efficiency work at this level is a direct input to both performance and manufacturing cost.
Tesla's third filing we've tracked in our AI chip wars watchlist since October builds on a per-token precision trick and on-the-fly chip tuning.
Source: US 2026/0299533 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Tesla patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 9 sheets
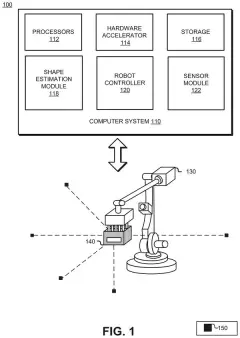
9 drawing sheets from US 2026/0299533 A1 · click any drawing to enlarge


Show sheet 9

More from Tesla
All 59 Tesla patents →
More in AI recommendation
All 91 AI recommendation patents →
Nvidia
Nvidia Patents a Multi-Layer Video Captioning System That Can Move Robots
Google
Google Patents a Two-Model System That Teaches Robots to Reuse Past Experience
Samsung
Samsung Patents an AI That Builds a Personalized Recap When You Resume a Paused Show
Amazon

No comments yet