Intel and AMD's GPU Patents in the Rendering Race, and Where They Point
This tracker collects Intel and AMD patents aimed at specific GPU rendering bottlenecks, including texture conversion, edge smoothing, ray tracing efficiency, and AI-driven lighting and upscaling. Together they show two chipmakers racing to solve the same rendering problems through software and firmware rather than new silicon alone.
140 filings
· tracking since May 2026 · latest Nov 2026 · updates weekly
based on all tracked filings in this watchlist · refreshes every week
This fight is over who controls the tools that decide how good a picture looks on your screen and how fast a chip can produce it, from sharpening blurry frames to tracing how light bounces around a scene.
Nvidia leads on raw filing count with nearly twice as many as anyone else, and AMD sits clearly in second, making those two the heaviest presence in this collection right now.
What’s new in the GPU rendering race
a dated entry each week this watchlist moves · older entries stay archived
Nov 5, 2026 7 filings joined
This week's filings lean heavily on making graphics sharper and faster, covering shadows, reflections, see-through objects, and flickering. Adobe and Microsoft each filed twice, with Nvidia and Qualcomm also pushing image quality ideas.
This week adds two filings: Google wants 3D scenes to run smoothly on phones, while Sony wants to shrink how much space game graphics take up on disk. Both companies are pushing to make graphics lighter and faster.
Sony leads this week with two filings: one to reduce lag in streamed games, one to speed up graphics compression. Samsung adds a filing to split heavy graphics work between a phone and remote servers.
Nvidia and Sony each filed two patents this week. Both companies are focused on making images sharper and frames faster, with Sony leaning toward streaming and Nvidia toward adding and refining frames locally.
This week's filings all circle one idea: making game graphics look better without doing extra work. Microsoft and Nvidia lead with two separate approaches to cleaning up blurry or grainy images on the fly.
Most filings this week tackle stopping GPUs from repeating work they already did. AMD filed the most, covering memory, stalling, and skipping unnecessary steps; Nvidia focused on filling gaps in video and pre-loading code.
Nvidia leads this week with seven filings, mostly around AI-assisted drawing and multi-chip coordination. AMD adds five, focusing on cutting memory waste and reducing detail during fast movement.
Sony leads this week with three filings covering cloud-shared rendering, AI-based image rebuilding, and multi-viewer video output. AMD added two filings on task scheduling and object-wrapping for better lighting, while Nvidia filed one on reusing light-bounce calculations.
Sony leads this week with six filings, mostly around streaming 3D scenes and letting AI learn how game worlds look. The broader group is focused on splitting graphics work smarter, whether between chips, tiles, or devices.
Qualcomm filed two of the three new patents this week, both focused on making screens draw images faster and on converting video data without stopping mid-process. The third filing, from Nvidia, covers software that guides AI in filling in missing video frames.
Aug 27, 2026 8 filings joined
Most of this week's filings focus on making graphics faster by skipping or cutting down unnecessary work, from processing only what the eye is looking at to filling in missing frames before anyone notices. Qualcomm leads with three filings, joined closely by Intel with two.
Aug 20, 2026 8 filings joined
This week's filings focus on tricks that help graphics chips do more work in less time, from skipping unnecessary steps to spreading work across frames or devices. Nvidia and Qualcomm were the most active, each filing multiple patents.
Who’s filing patents in the GPU rendering race
counts from tracked filings · focus read from each company’s own filings
the fights inside the fight · each with its three newest filings · new filings join every week
Cleaning Up Grainy AI Images 12 filings
Nvidia 10, Qualcomm 1, Sony 1
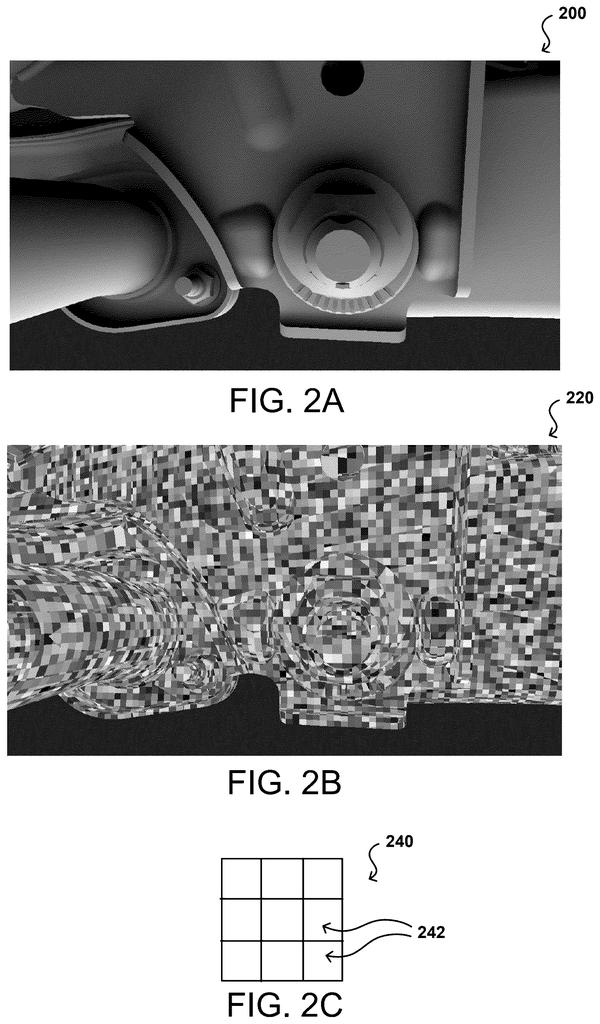
Several companies are filing patents on ways to remove grain and noise from images that computers generate, especially when tracing light rays through a scene. The approaches include AI-based scrubbing and borrowing color detail from other frames.
Skipping Wasted Work When Tracing Light 19 filings
AMD 7, Intel 7, Qualcomm 2
A cluster of patents focuses on making light-tracing faster by cutting out calculations that lead nowhere, remembering past results, and avoiding asking for the same data twice. The shared goal is getting realistic shadows and reflections without burning through processing power.
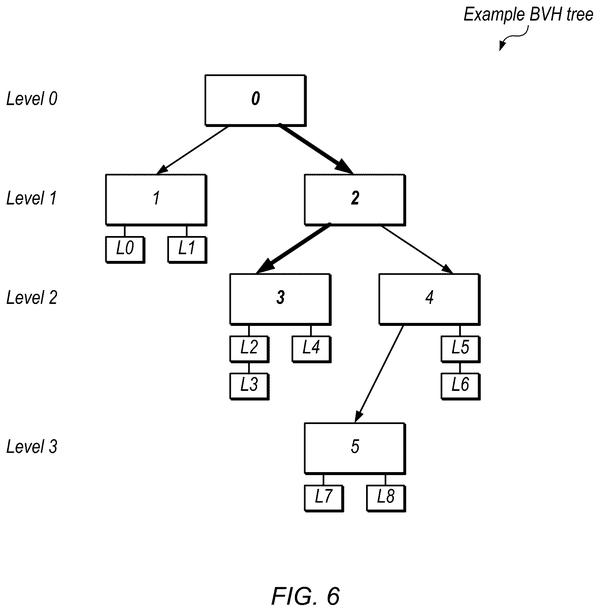
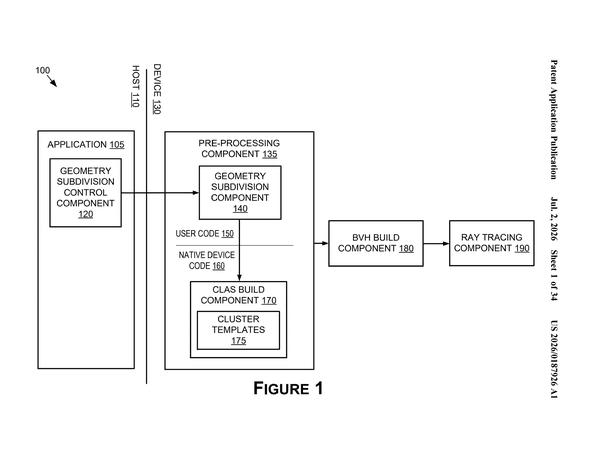
These filings cover pre-building, pre-sorting, and recycling the shape data that describes a 3D scene, so the chip does not have to rebuild it from scratch every frame. Related filings cover smarter sorting and faster ways to build scene structures.
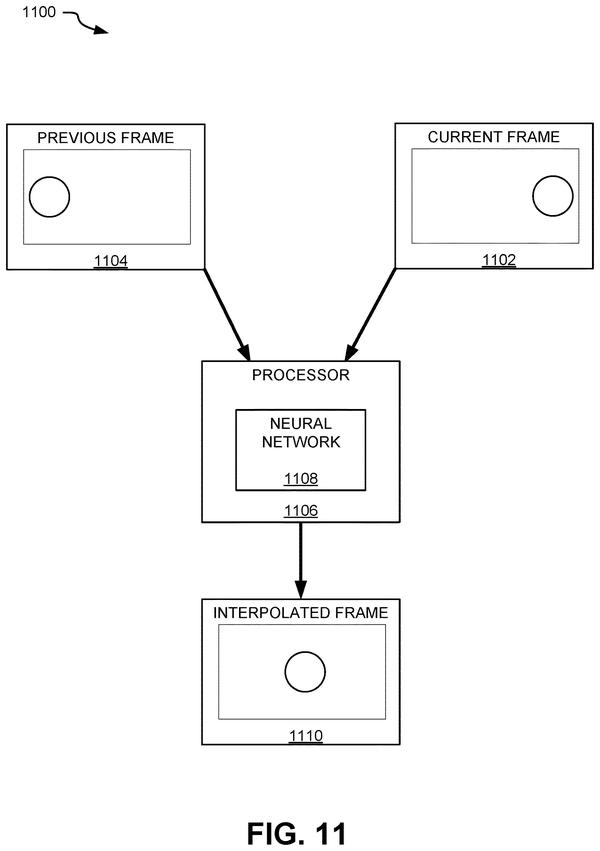
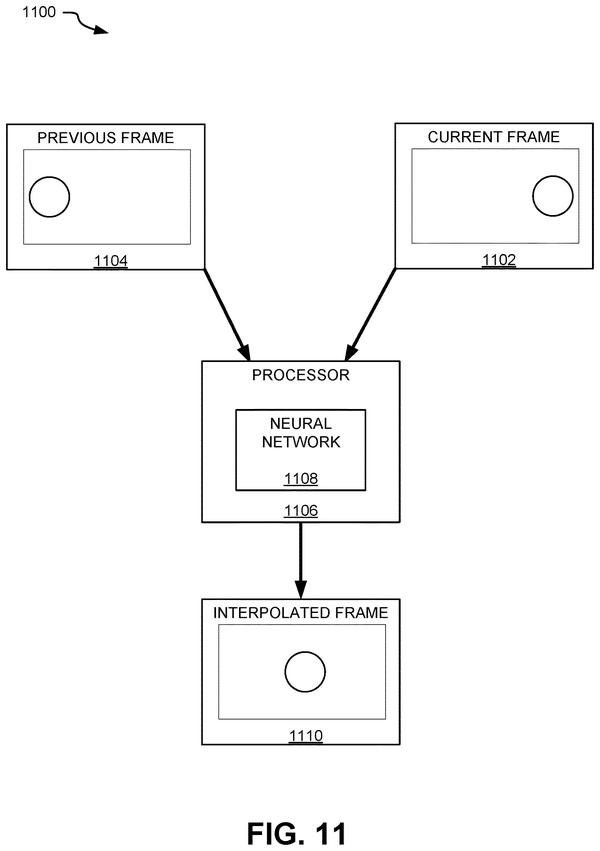
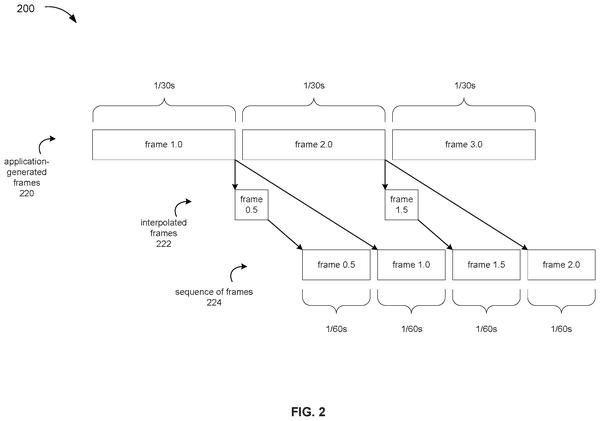
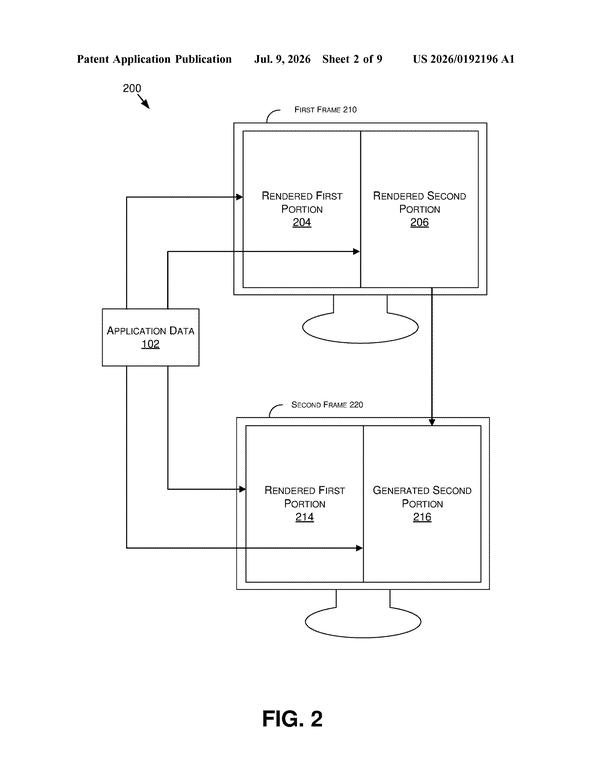
These filings generate missing or in-between frames by pulling information from nearby frames or from the 3D scene itself, rather than drawing every frame fully from scratch.
Splitting Graphics Work Across Hardware 15 filings
Nvidia 4, Qualcomm 4, Sony 3
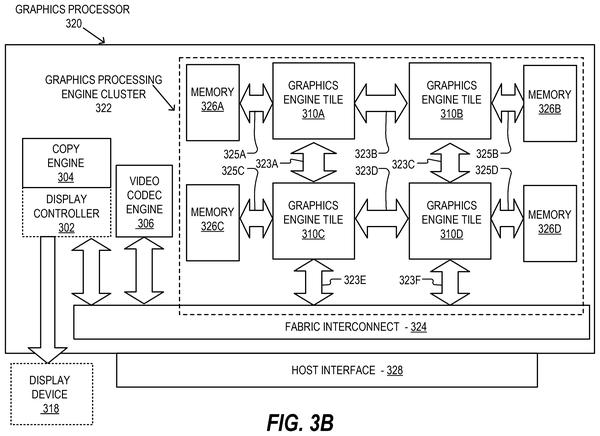
These filings describe ways to divide rendering tasks across multiple chips or chip sections without repeating work or leaving parts of the hardware idle. One approach has the chip check its own active sections before dividing tasks.
These filings cover methods that increase image sharpness or resolution without blurring edges, with some approaches adjusting their own behavior based on how complex a given part of the image is.
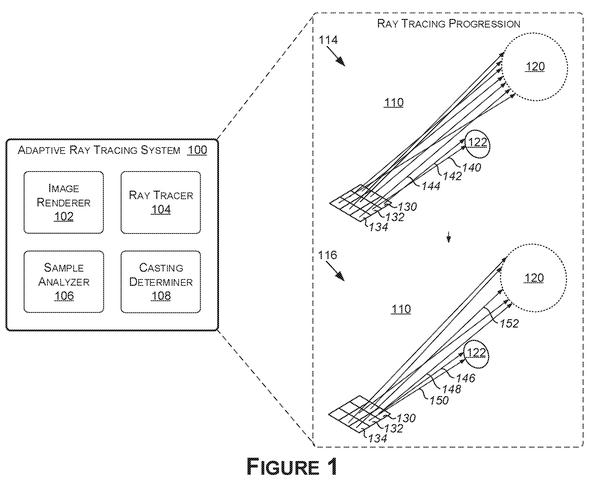
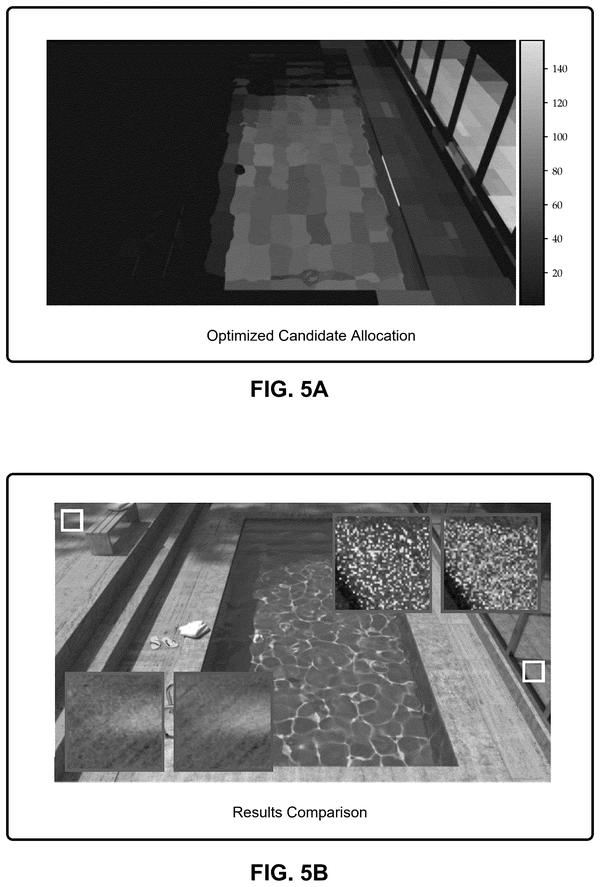
Within the ray tracing efficiency push, this filing narrows focus to adaptive sampling: concentrating computational budget on geometry-heavy shadow regions rather than distributing rays uniformly across the frame.
Probabilistic sampling replaces depth-sorting for transparent geometry, trading exact layer ordering for statistical accuracy. Cuts the per-pixel overhead that typically dominates rendering of complex translucent surfaces.
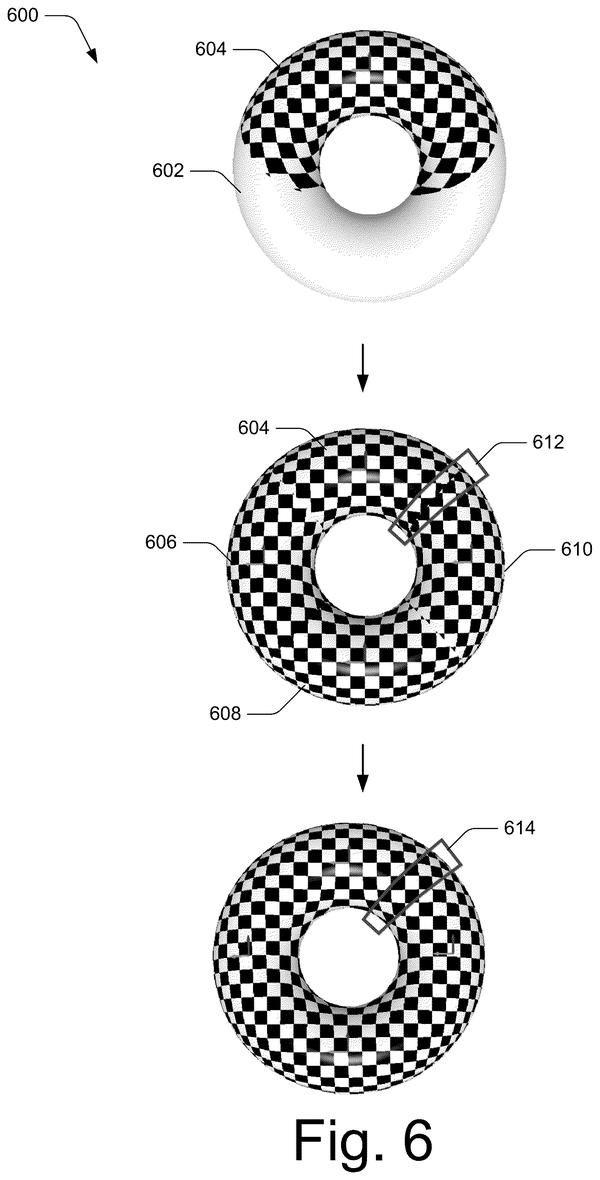
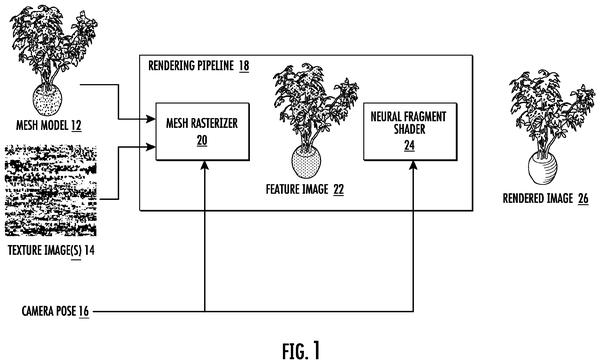
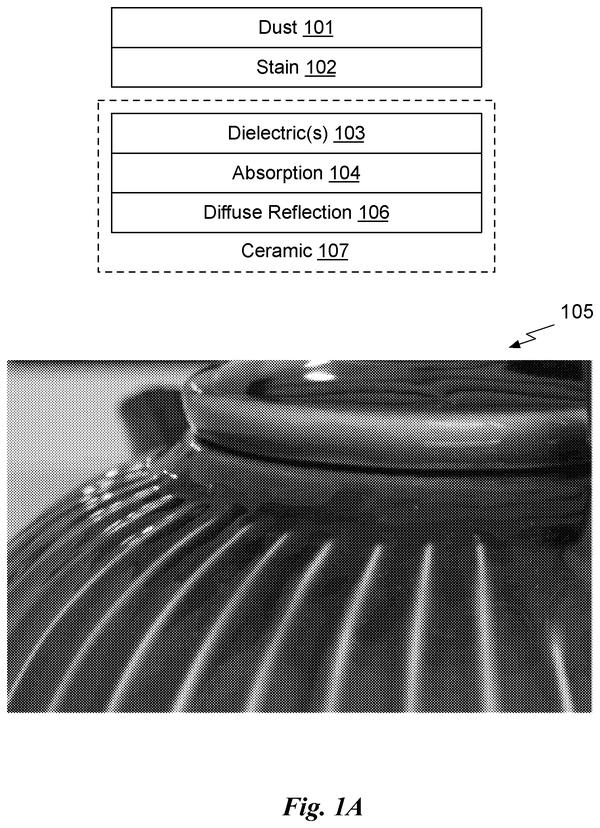
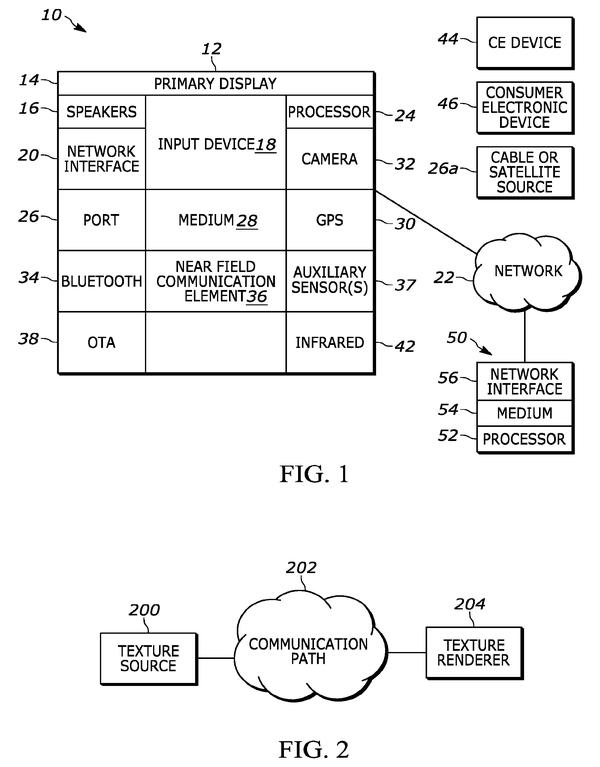
Applying textures directly to parametric surfaces without mesh conversion preserves editability and cuts the conversion overhead that slows real-time rendering pipelines.
Caching learned feature maps during training lets smaller networks converge faster on image synthesis tasks, reducing both training time and inference cost per frame in real-time rendering scenarios.
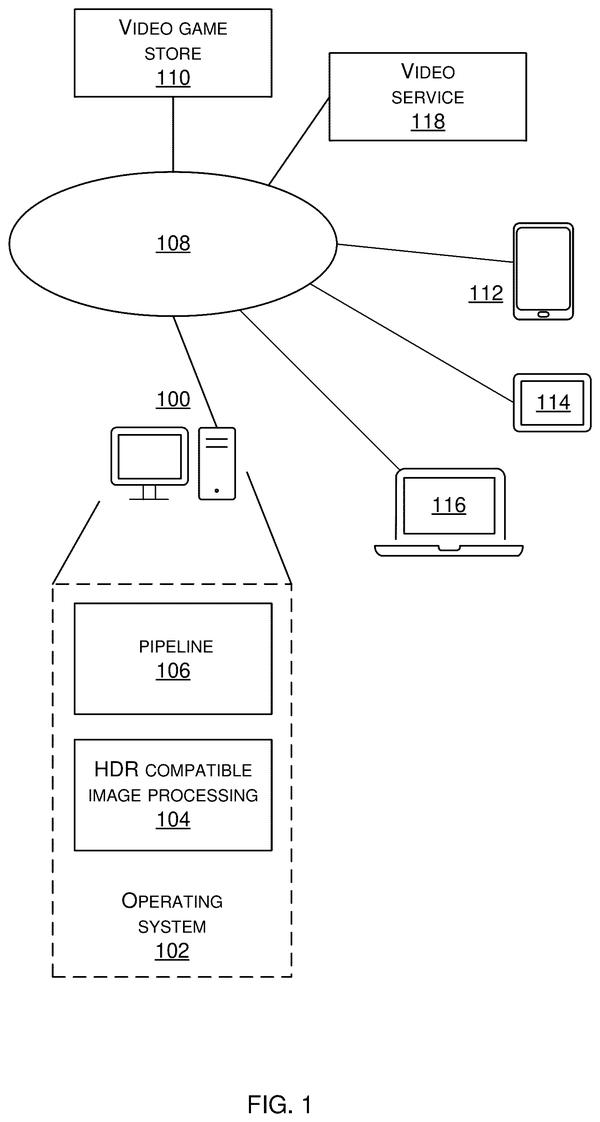
An AI upscaling model tuned for HDR's expanded brightness and color range, embedded in the OS layer. Confirms the shift toward system-level intervention for AI-driven rendering as HDR adoption spreads in gaming.
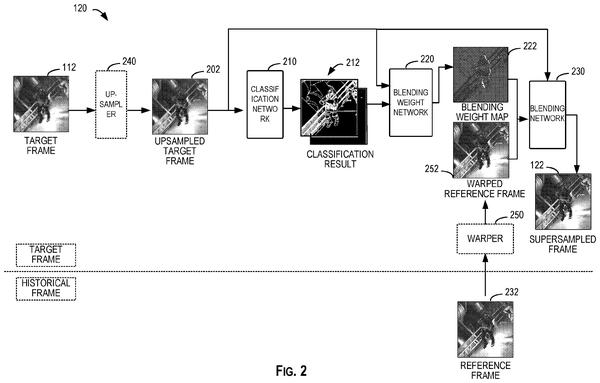
After upscaling from prior frames, temporal artifacts split into two classes: shimmer at edges versus ghosting in motion. Microsoft's approach sorts pixels by artifact type before correction, allowing tailored fixes for each.
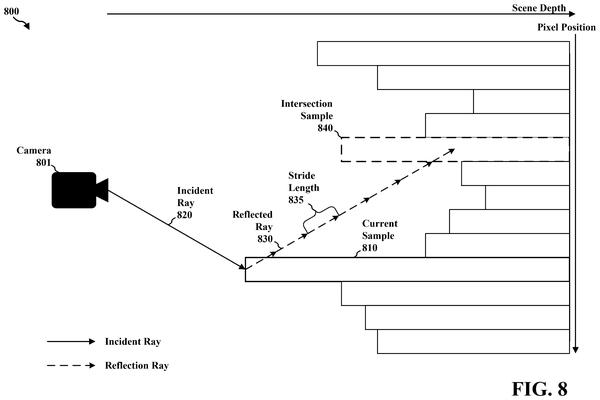
Reusing existing depth maps to accelerate reflection ray tracing cuts the per-pixel step count from 1,400 to a fraction, directly improving real-time mirror and water surface rendering without full ray-trace overhead.
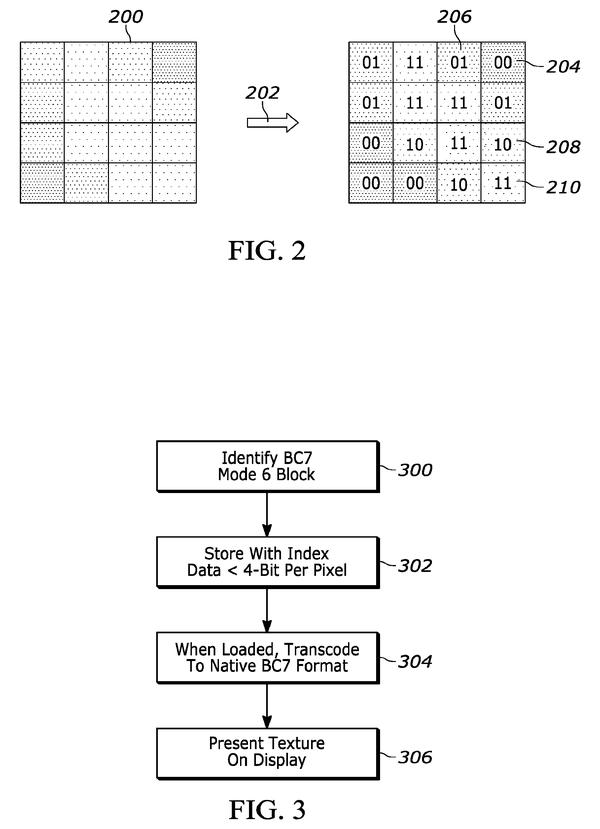
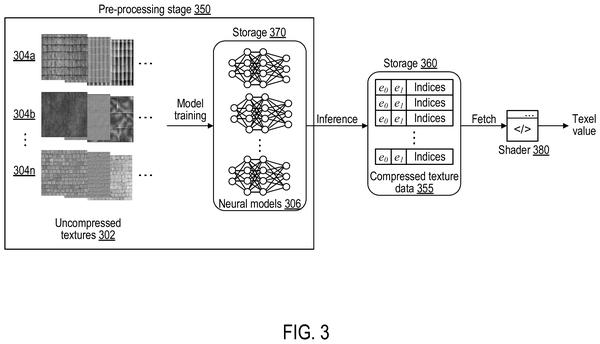
Smaller texture files on disk mean faster downloads and installs. Sony's compression method keeps visual quality by storing fewer color blends per pixel block, then reconstructing the full detail at runtime rather than on disk.
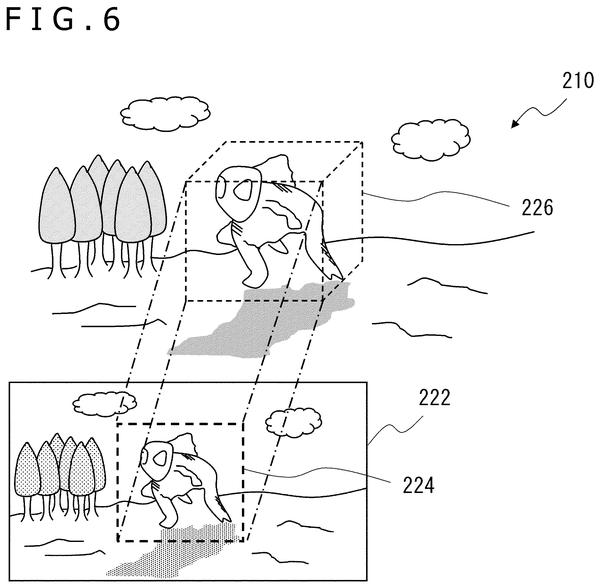
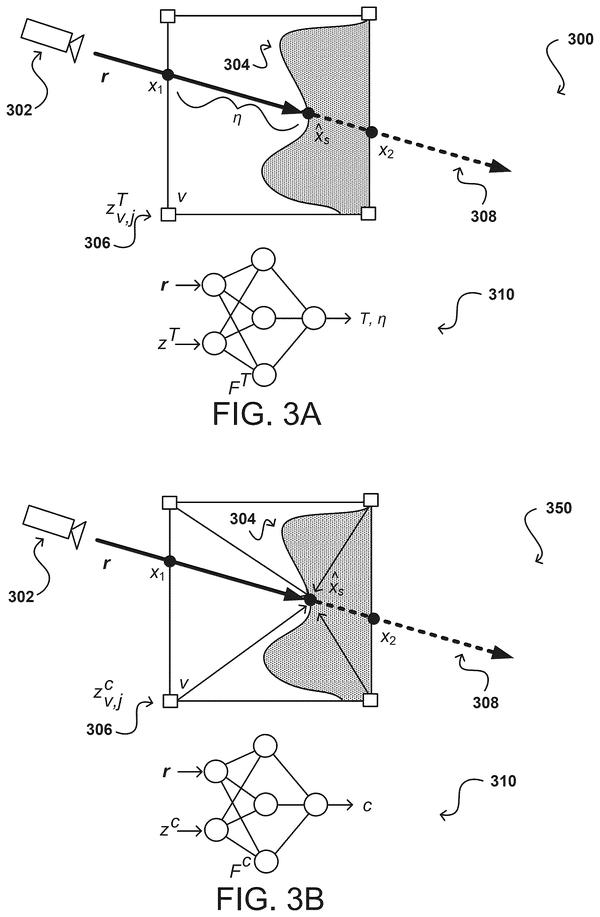
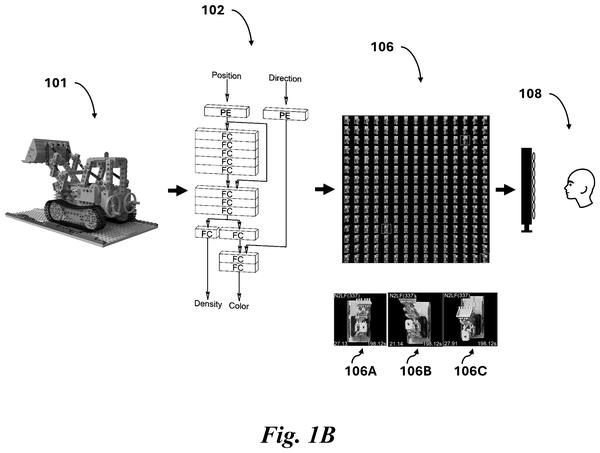
Rendering NeRF scenes on mobile means running neural models per-pixel, which tanks performance. Google's approach bakes the AI work upfront into a geometric shell, letting phones use standard rasterization instead of per-frame inference.
Within the GPU rendering race, this shifts the bottleneck from transmission to edge compute: rather than streaming frames, Sony trains lightweight AI models server-side to let clients render locally, cutting latency and packet-loss glitches in VR.
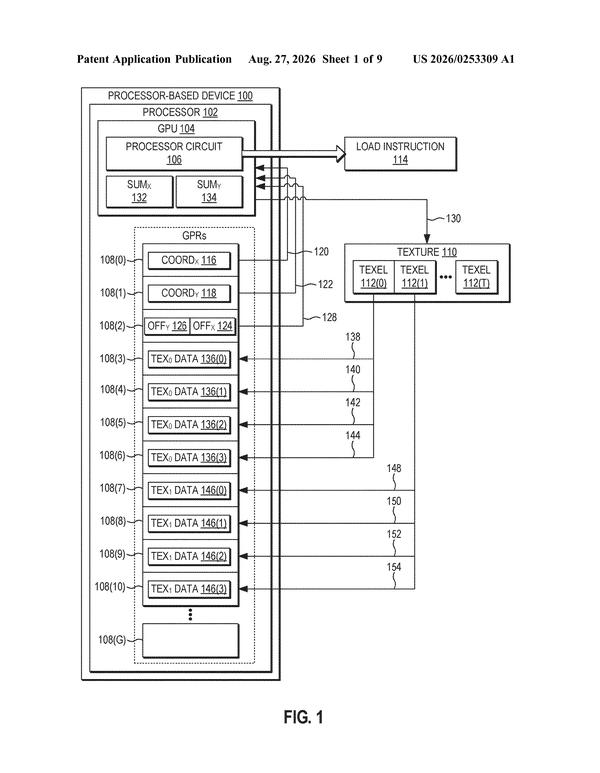
A trained model predicts optimal texture compression formats per tile, replacing brute-force format testing. This cuts the computational cost of texture conversion, a known bottleneck in real-time rendering pipelines.
Distributed rendering between client and server lets a phone offload frame computation to network resources in real time, extending battery life during intensive 3D playback without the latency penalty of traditional cloud rendering.
Variable-resolution rendering based on surface complexity lets the engine skip detail work on smooth areas and concentrate samples where geometry gets tangled, speeding up per-frame computation without losing visual fidelity in high-variance regions.
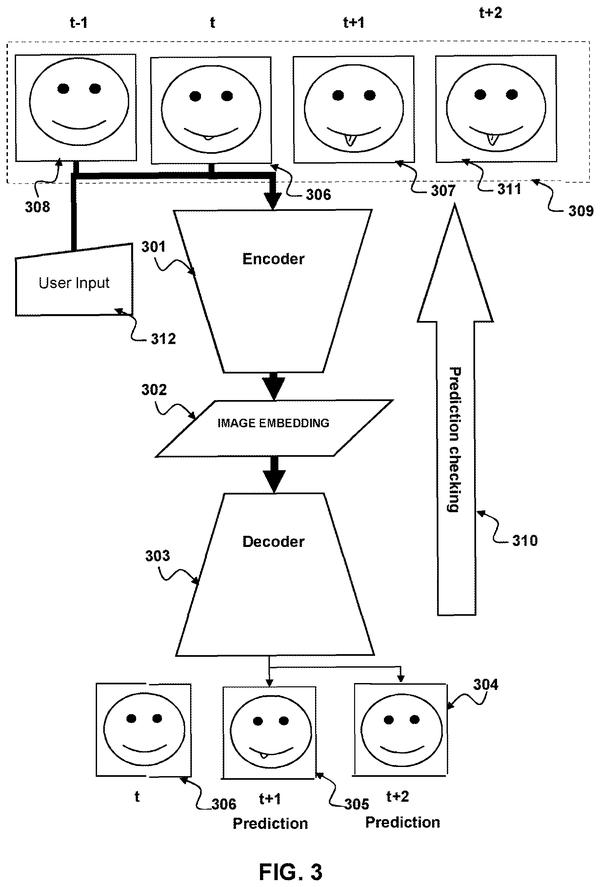
AI prediction of intermediate frames during rendering cycles could reduce perceived lag by displaying speculative output while hardware completes the actual frame, shifting the bottleneck from raw rendering speed to prediction accuracy.
A capability query sent from game to GPU before frame interpolation activates, confirming hardware readiness before attempting AI upscaling or motion generation.
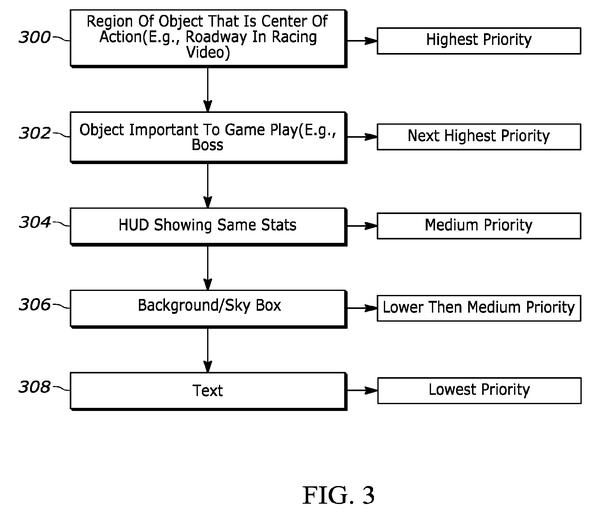
A machine learning model identifies which screen regions demand high frame rates during gameplay, letting the system allocate bandwidth to motion-critical elements like track geometry while reducing refresh rates for static UI elements.
Hardware-managed attention to facial regions cuts the per-frame overhead of adaptive quality allocation, moving allocation logic into the chip rather than forcing repeated software recalculation across texture blocks.
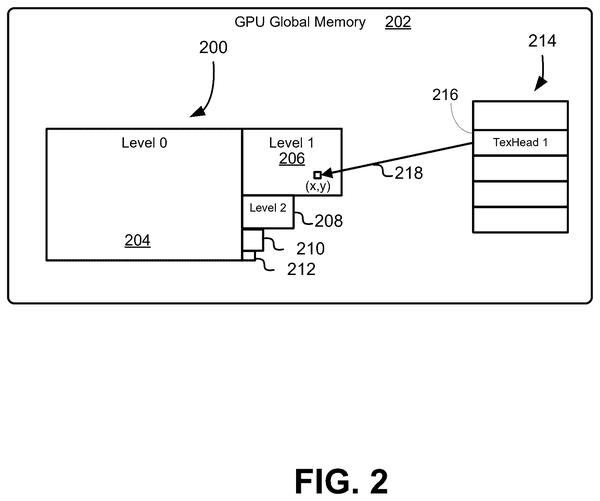
Direct GPU texture fetching from storage eliminates the CPU intermediary, reducing latency in streaming high-detail assets during fast camera movement, a efficiency gain for ray-traced scenes with unpredictable memory access patterns.
Synthetic blur generation sidesteps the training bottleneck by having one AI create matched blurry counterparts, letting upscaling models learn from unlimited paired data instead of hunting for naturally degraded frames.
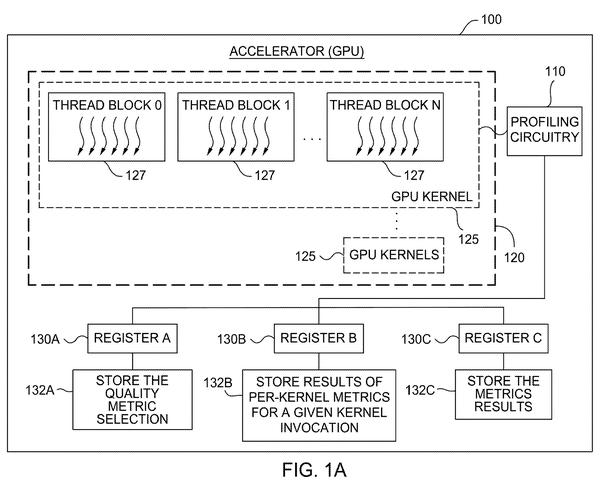
Runtime kernel selection hardware that picks optimal code paths based on job size and data characteristics, rather than relying on compile-time guesses or manual tuning.
Within the upscaling and efficiency category, this extends beyond real-time compilation by moving shader prediction upstream to the cloud, eliminating stutter before it reaches the client device.
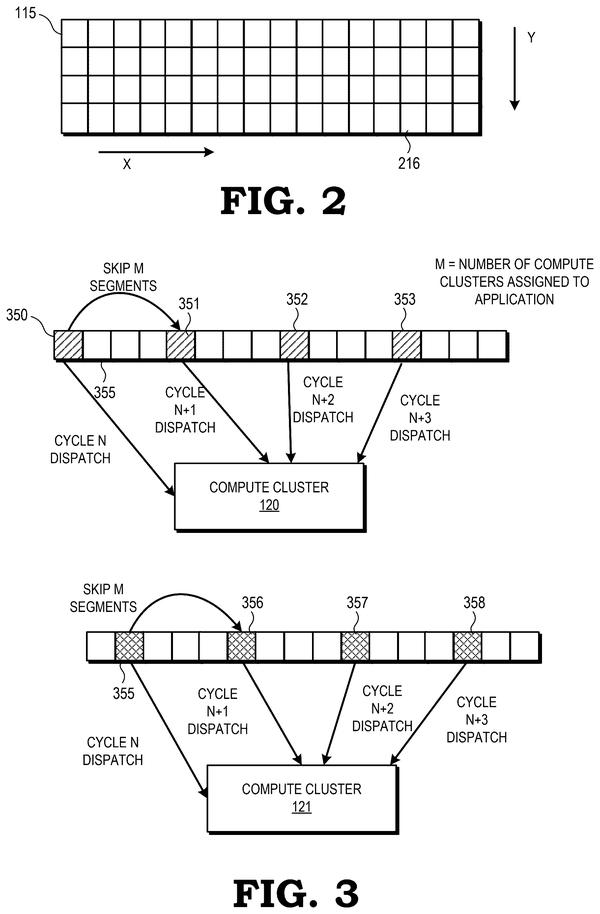
Direct dispatch routing lets each GPU cluster grab its next work assignment without scanning past tasks meant for other processors, cutting latency between cycles and improving throughput on parallel workloads.
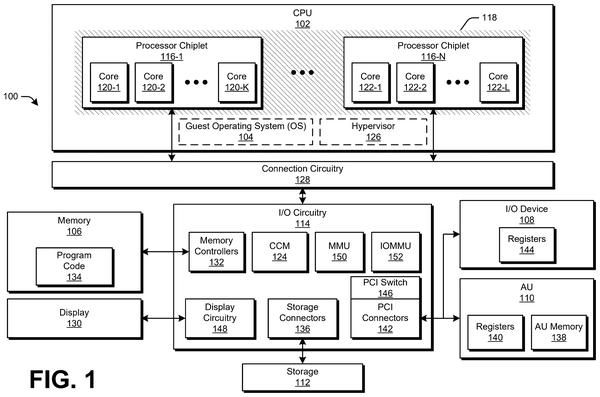
Memory isolation has mostly relied on software checks that slow GPU workloads. AMD's hardware circuit moves the verification into silicon, potentially eliminating that bottleneck when programs share rendering resources.
Motion-vector upsampling to reconstruct missing frames cuts the computational load of full rasterization, pushing efficiency gains in real-time rendering where frame interpolation matters most.
Caching decompressed texture data at the shader stage eliminates redundant decompression cycles when rendering surfaces with repeated textures, freeing GPU compute for other rendering tasks.
Shifts focus from texture and edge problems to ray tracing's memory bottleneck: AMD proposes borrowing buffer space to keep the ray tracking unit active instead of stalling when its dedicated memory fills up.
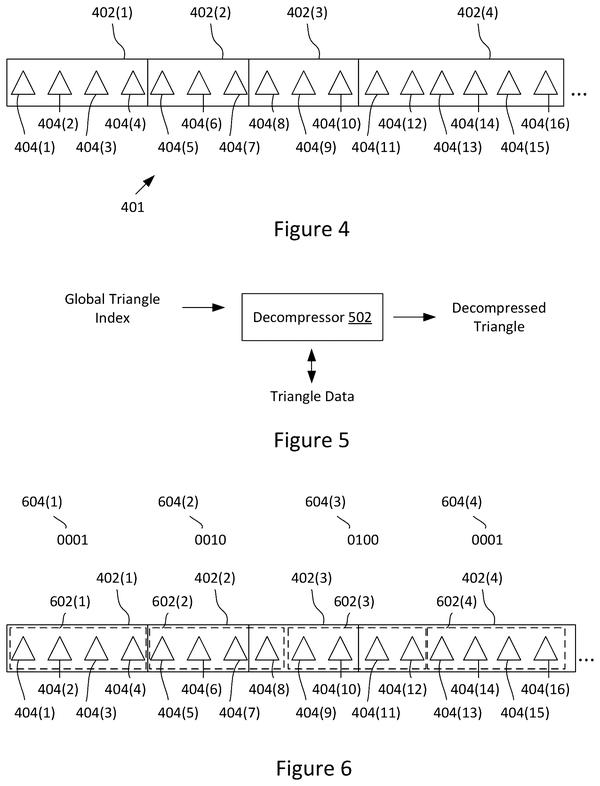
The geometry unpacking bottleneck gets a direct hit: AMD's indexing scheme cuts the search time GPUs spend locating triangles in compressed meshes, removing a step that currently forces serial scanning through variable-length data blocks.
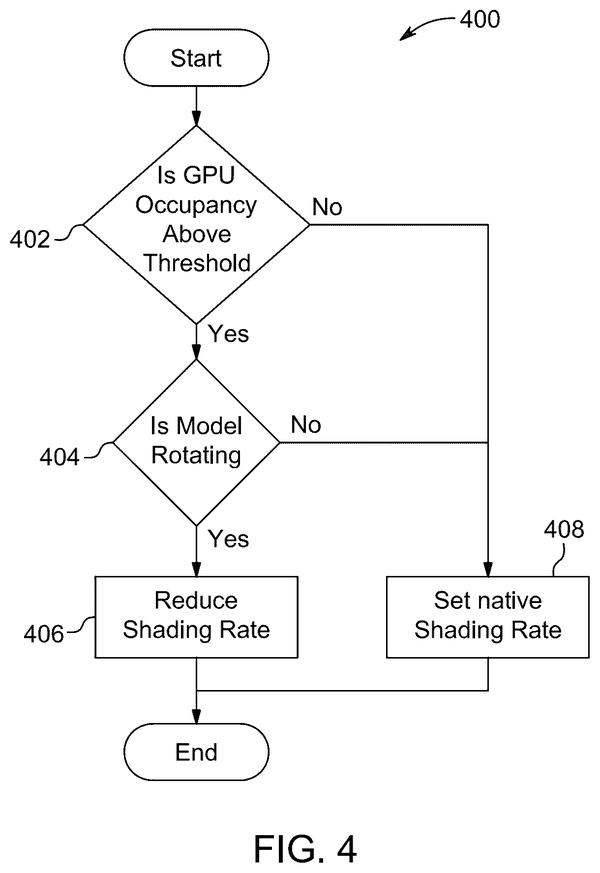
Variable shading rates that drop during camera motion exploit the perceptual blind spot created by movement itself, freeing GPU cycles when load is highest and detail matters least.
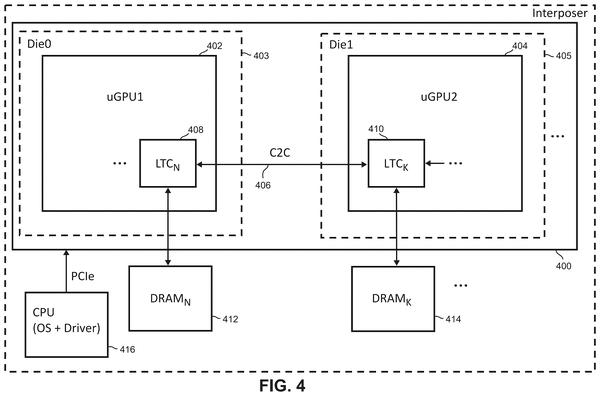
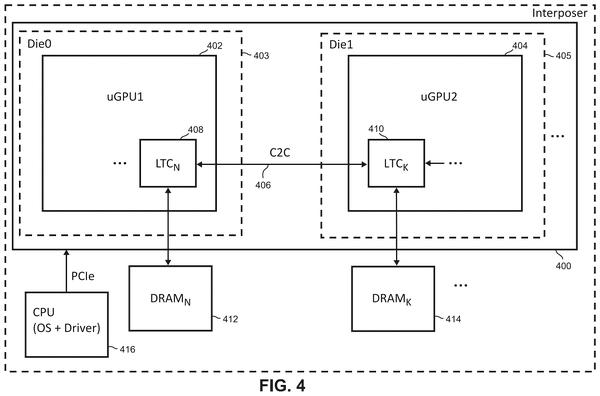
Partitioning screen regions to individual chips reduces cross-chip data movement in dual-GPU rendering, confirming a localization approach to the bandwidth bottleneck that plagues multi-chip card architectures.
Where AI-driven lighting gains traction, this patent shows how compact models can replicate material properties at runtime instead of relying on pre-baked approximations, pushing film-grade surface realism into interactive frame rates.
Extends the self-correction theme: GPU renders a frame, measures it against photorealism targets, then rerenders to fix detected flaws in one closed loop.
Automated dataset generation from the game engine itself sidesteps the manual labor of collecting matched image pairs, letting the training pipeline scale without human curation bottlenecks.
Within the multi-chip coordination problem, this patent reduces inter-chip communication by letting each chip maintain its own rendering state instead of constantly syncing updates across the boundary.
A neural network gates ray tracing to specific objects rather than running it globally, trading full-scene accuracy for selective application where it matters most to perceived quality.
Developers can now lock texture filtering modes per-asset instead of globally, preventing unwanted smoothing on elements like UI overlays or pixel art that need pixel-perfect consistency across frames.
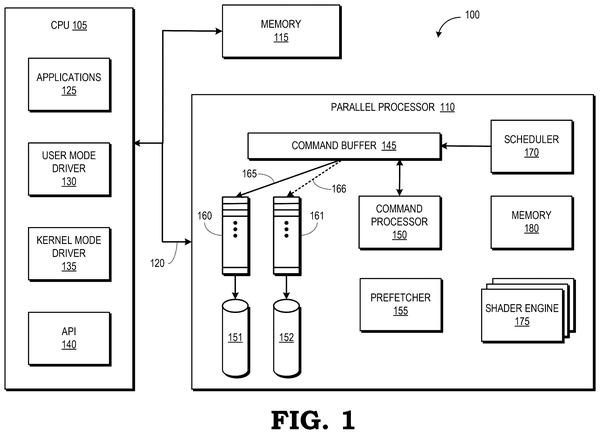
Within the race to eliminate memory stalls, AMD targets the gap between instruction execution and data arrival by embedding prefetch requests into the command queue itself, keeping shader cores productive during the memory fetch window.
Within the efficiency and optimization corner of the race, Nvidia's tool cuts the time needed to spot matching rendering errors across systems, moving comparison work from manual video review to automated detection.
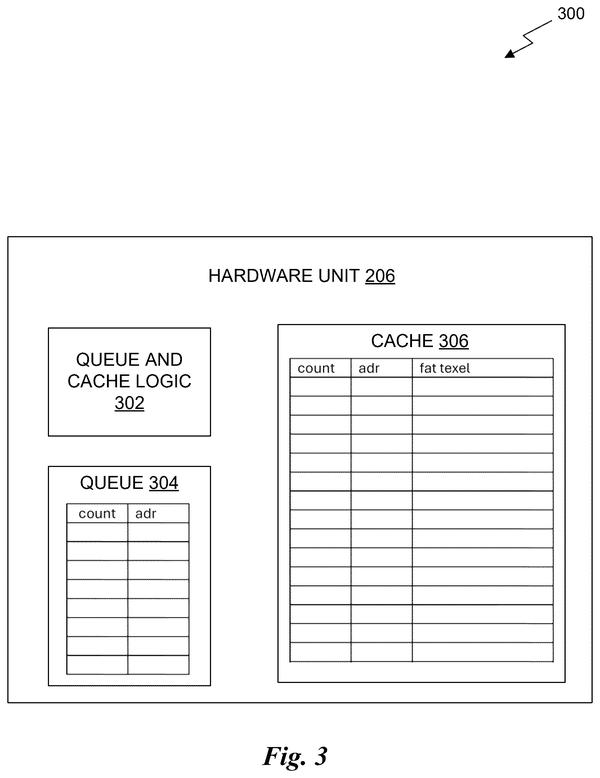
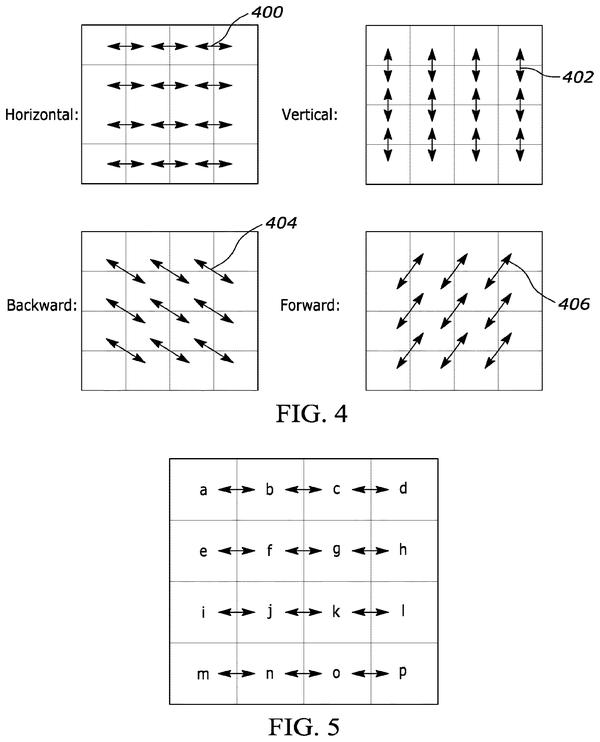
Within texture conversion, Nvidia moves beyond simple tiling by using neural networks to generate seamless expansions from small samples, sidestepping the need for larger source images.
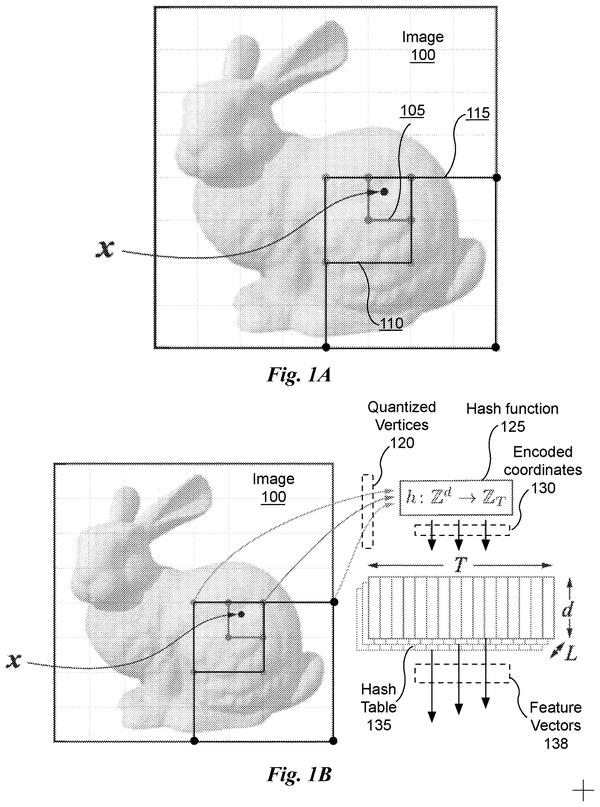
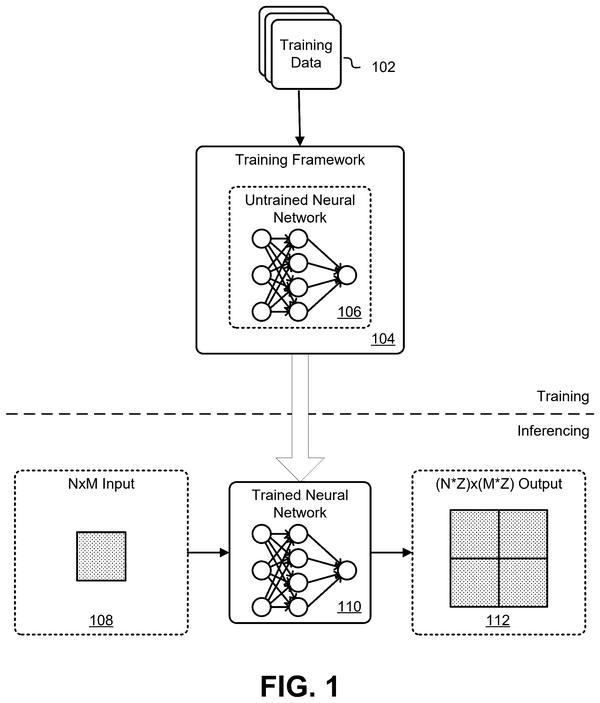
Where texture compression has relied on fixed formulas, AMD proposes learned neural networks that could preserve detail while shrinking memory footprint. Confirms the direction toward AI-optimized asset handling in rendering pipelines.
Ray tracing efficiency: uneven task completion times force fast geometry builds to stall at synchronization barriers. AMD's method lets quicker scene elements proceed without waiting for slower ones.
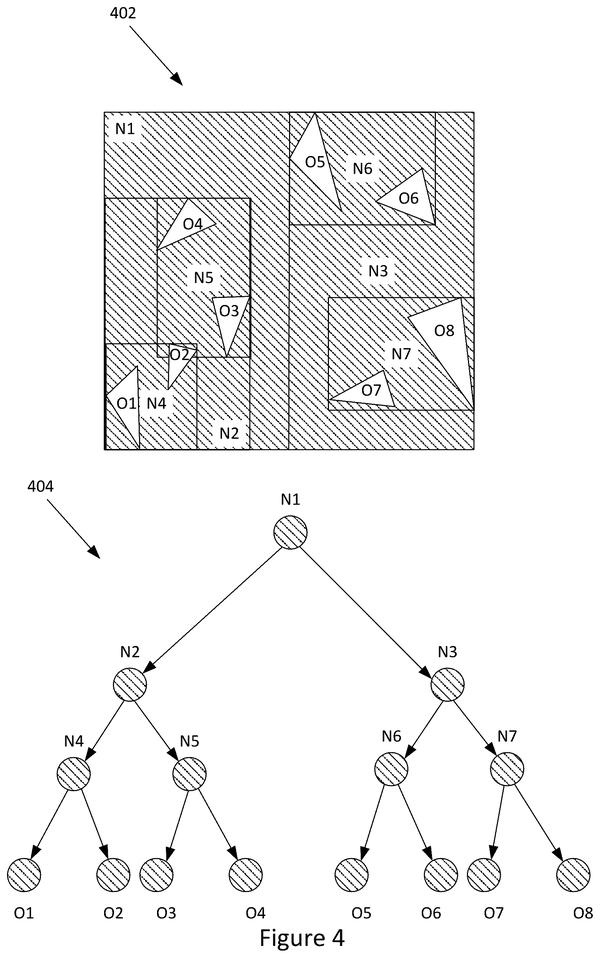
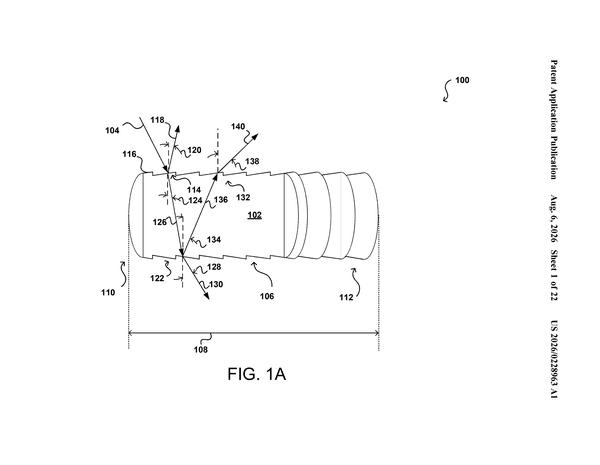
Better bounding boxes mean ray tracing can skip checking objects that don't matter, cutting the math overhead that currently makes real-time lighting so expensive.
Distributing individual rendering tasks between local and cloud processing based on real-time network conditions, rather than offloading entire frames. Extends the efficiency question beyond texture and ray tracing into dynamic workload balancing.
Multi-stream rendering from a single pipeline sidesteps the computational cost of parallel renders, pushing efficiency gains into personalized output rather than raw performance.
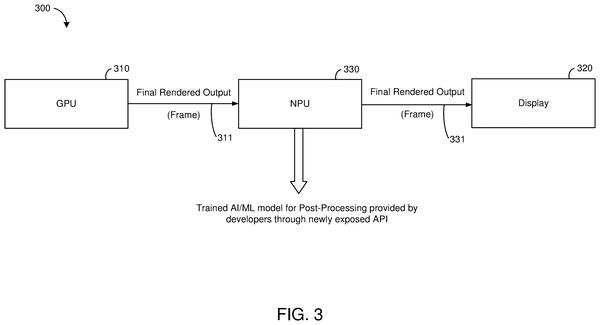
Within texture conversion efficiency, Sony's approach sidesteps the decompress-recompress cycle by having AI infer high-res detail directly from compressed files, potentially cutting memory overhead during mipmap generation.
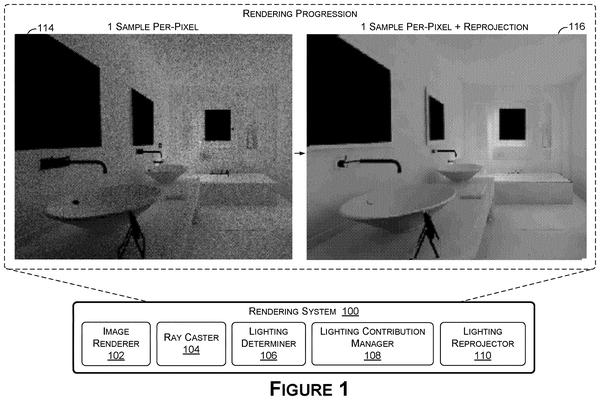
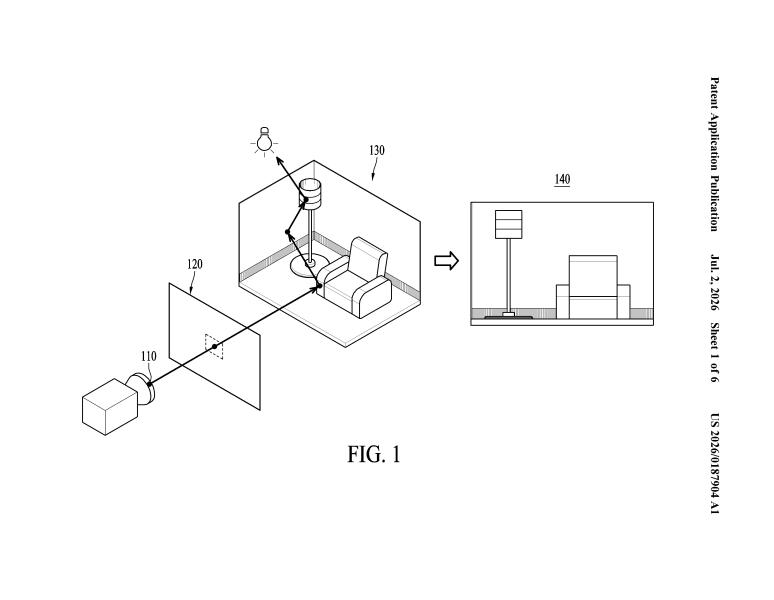
Caching ray-bounce calculations across nearby pixels cuts redundant computation in path tracing, speeding up the per-frame math that makes real-time light simulation expensive.
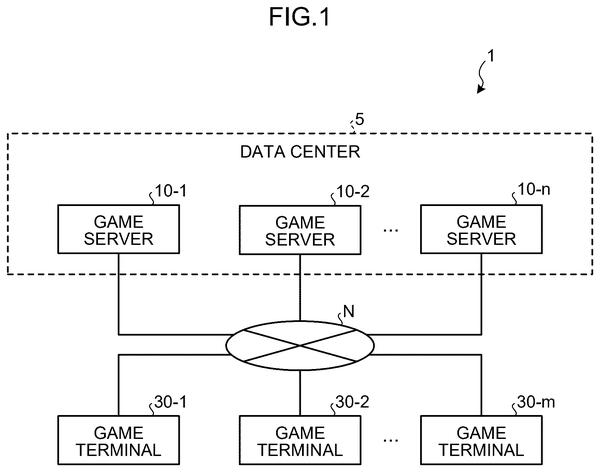
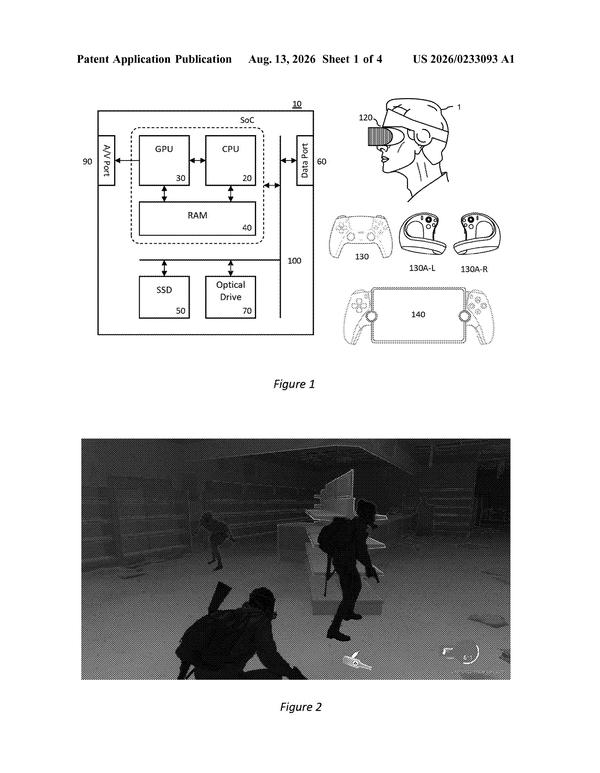
Every cloud gaming system picks one place to draw the picture: the server or your device. Sony's new patent describes a way to choose on the fly, frame by frame, based on what you're actually looking at.
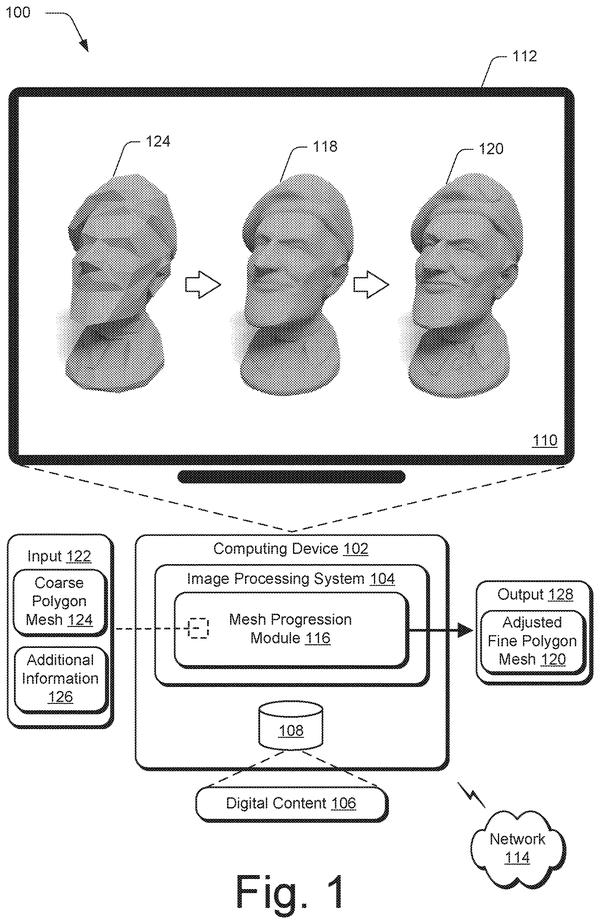
Loading a complex 3D model over a slow connection usually means waiting for the whole thing or staring at a blocky placeholder. Adobe's new patent describes a system that sends a usable shape first, then layers in the fine detail as it arrives.
What if every player's screen was teaching a server how to reconstruct a game world in three dimensions, so anyone could rewatch any moment from any angle? That is exactly what Sony's latest PlayStation-linked patent describes.
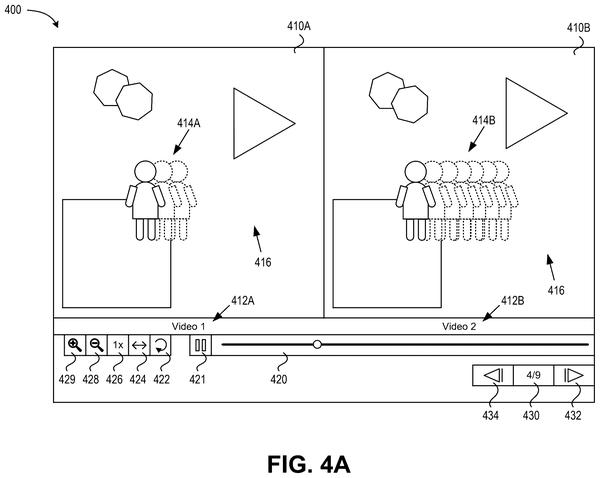
Sony has filed a patent for a system that lets you pause a moment in a game and then replay it from a completely different camera angle, without the original game having to store that footage at all.
Texture memory bloat during ray tracing stems from loading full banks when only small portions hit the final image. Intel's tile-based fetch system cuts waste by pulling only the chunks each frame actually renders.
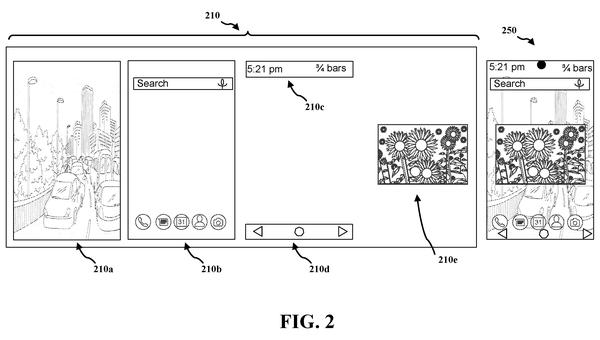
Mixing flat icons with three-dimensional scenes on a screen sounds simple until you realize the two graphics systems powering them barely speak the same language. Apple's new patent describes a way to make one animation definition drive both at once.
Streaming a 3D game means sending an enormous amount of visual information just to make surfaces look correct from where you're standing. Sony's new patent tries to shrink that problem by shipping a tiny trained AI model instead of raw image data.
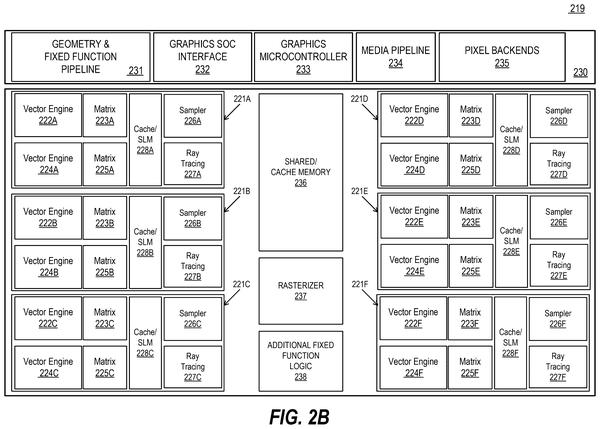
GPU upscaling and cleanup could run on separate silicon instead of competing with rendering for resources, freeing the main graphics processor to focus on frame generation alone.
Sony has filed a patent for a system that trains an AI model on a running game, teaching it the full three-dimensional shape of the game world so it can generate views the game engine itself never explicitly drew.
Streaming a full 3D scan of an object every single frame is expensive. Sony's new patent cuts that cost by flagging the parts of the scene that haven't moved and telling the player it can skip re-downloading them.
Smoother interpolated video requires the AI to know frame dimensions upfront. This patent covers the input specification layer that prevents mismatched output artifacts like ghosting.
Memory bandwidth constraints in pixel movement operations. Qualcomm's approach optimizes how processor cores relocate pixel data during frame assembly, reducing the overhead that slows refresh cycles on mobile displays.
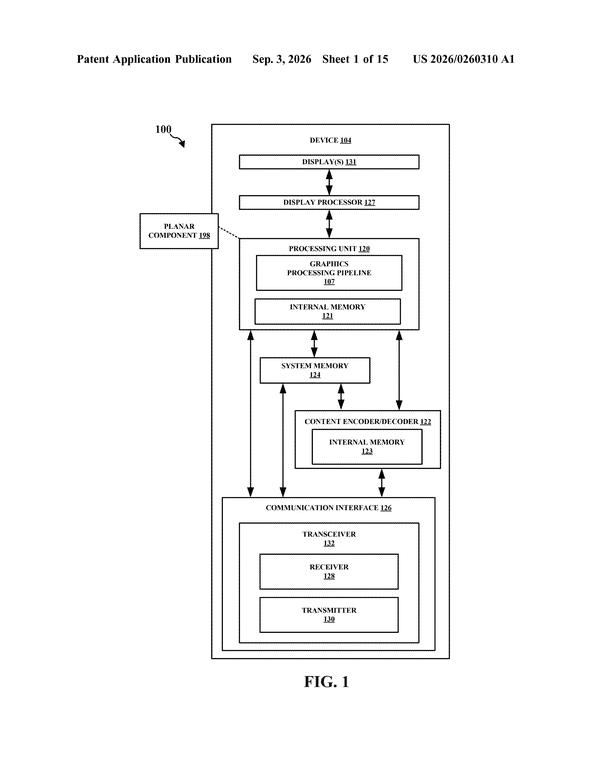
Games and apps could render continuously without stalling for format conversions between interleaved and planar memory layouts, letting the GPU pipeline stay fully loaded instead of pausing for reformatting overhead.
Geometry clipping redundancy: Intel proposes caching setup state across adjacent triangles to eliminate duplicate culling operations in rasterization pipelines.
Faster games on mobile devices depend partly on cutting instruction overhead in texture sampling. Qualcomm's approach batches two pixel lookups into a single GPU command, reducing the per-texel cost that currently limits scene complexity and frame rates.
Games that stutter when rendering lags could run smoother if the GPU predicts frame delays and synthesizes replacements on the fly. Intel's filing points toward real-time frame interpolation as a way to mask the rendering bottleneck rather than eliminate it.
Smoother video on phones means prefetching the next filter instruction set while the current frame renders, eliminating the memory-fetch delay between frames.
Faster display refresh could cut power drain by skipping static areas of the frame, shifting the bottleneck from brute-force pixel processing toward prediction algorithms that track where user attention actually lands.
Rotation blur during animations stems from uniform layer handling. Qualcomm's method analyzes each on-screen element to route rotating objects through specialized rendering paths, leaving static content unchanged.
Smaller screens force UI elements below legibility thresholds mid-session. Sony's AI detects which game objects have shrunk past usability and rescales them automatically, keeping critical information readable across device transitions.
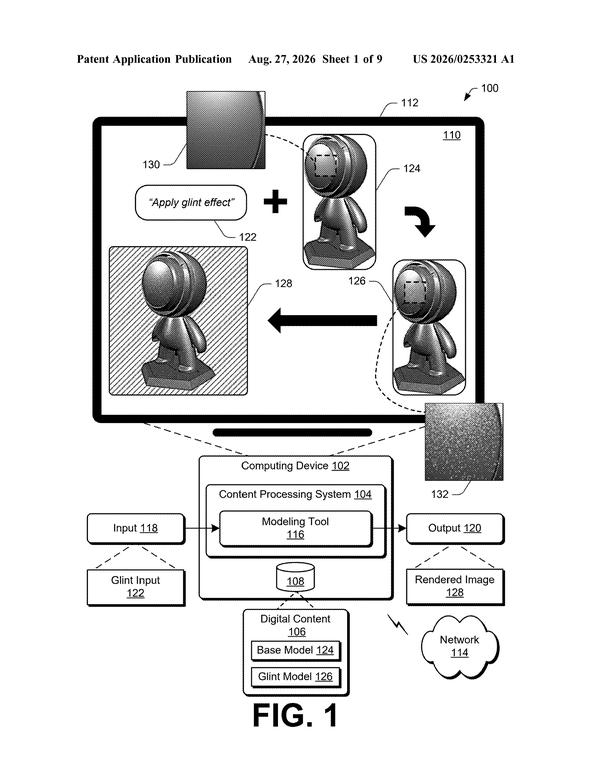
Real-time sparkle rendering on metallic and glittery surfaces moves from post-processing trick to built-in surface property, cutting the compute cost that has made this effect prohibitively expensive in interactive rendering pipelines.
Preparing multiple render candidates during frame N and selecting based on frame N+1 data shifts prediction burden from real-time guessing to staged preparation, cutting wasted computation cycles on discarded work.
Moving mesh topology analysis onto the GPU itself rather than handling it on the CPU sidesteps a known bottleneck in character rendering pipelines, letting parallel hardware do what serial preprocessing currently does.
The ray tracing efficiency track gains a culling mechanism: Qualcomm's method lets GPUs identify and skip redundant pixel quads before shading, reducing wasted computation on invisible or duplicate fragments.
Offloading static backgrounds to a server lets consoles skip expensive full-scene rasterization and focus compute on dynamic objects, reducing the per-frame workload that typically dominates rendering bottlenecks in complex environments.
Every 3D character you've ever seen in a game or app is secretly held together by an invisible skeleton, and most graphics hardware has a strict limit on how many bones it can process at once. Google's new patent describes a way to work around that limit without sacrificing detail.
The ray tracing efficiency angle gains a hardware-level frame insertion layer that operates outside game logic, letting older or compute-heavy rendering pipelines hit display refresh rates without architectural redesign.
Faster cache decisions during ray tracing would cut the memory stalls that currently force GPUs to idle between light-bounce calculations, directly speeding up frame rates without needing more raw compute power.
Better compression starts with smarter input: game engines can now mark which regions matter most during rendering, so the encoder knows where to spend its bitrate before the frame even gets compressed.
Splitting light behavior into separate scattering modes lets the renderer compute subsurface effects inside each strand without simulating every photon path, making realistic hair feasible at production frame rates.
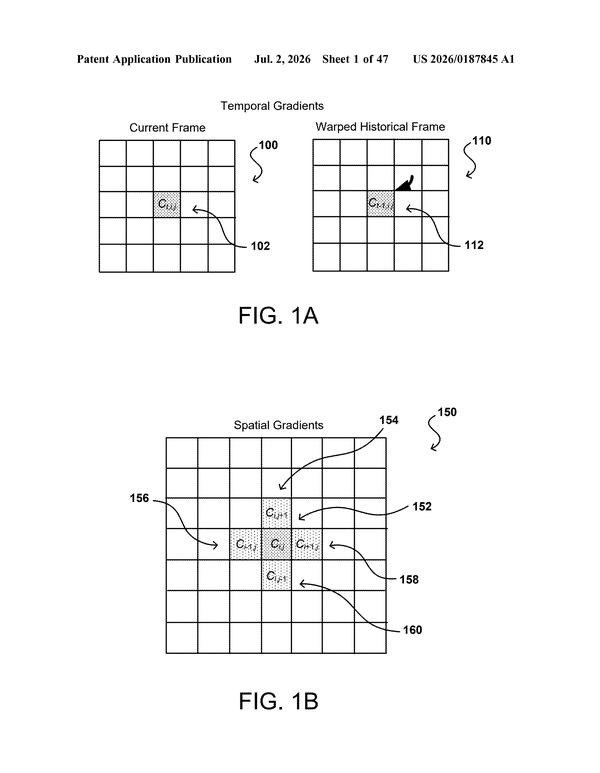
Locked reference points across frames eliminate the calculation drift that causes lighting and detail jitter in real-time rendering, confirming the shift toward temporal stability as a core efficiency gain.
Distributing lighting calculations across networked GPUs while preventing redundant ray bounces confirms the watchlist's focus on ray tracing efficiency at scale, addressing the overlap problem that emerges when splitting scenes across multiple processors.
The AI-driven lighting track expands beyond single-model approaches: Samsung's dual-network system distributes the light-scattering computation to balance speed and surface realism in real time.
Denoising curved surfaces by tracking their motion between frames sidesteps the blur problem that flat-surface cleanup creates, letting ray-traced reflections on organic geometry stay sharp.
Optical refraction breaks motion vector tracking when light bends through glass or water surfaces. Nvidia's solution applies light simulation to recalculate object positions correctly, sharpening motion estimation in scenes with refractive materials.
Reconstructing occluded geometry from scene depth maps lets the frame generator predict what's behind obstacles, reducing the redraw cost when hidden objects reappear and stabilizing frame output under load.
The ray tracing bottleneck shifts from blind light sampling to predictive selection. Nvidia's caching approach lets renderers reuse visibility data across frames instead of recalculating which lights matter.
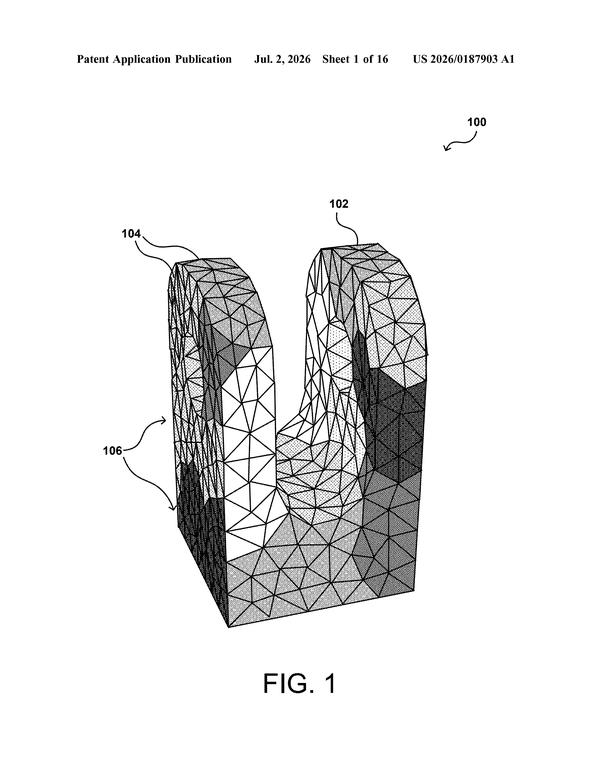
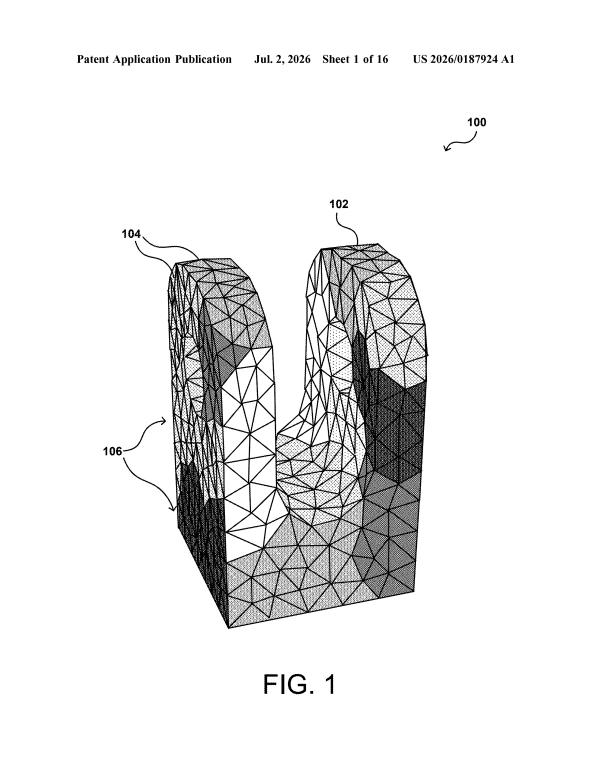
Parallel edge collapse lets the system simplify millions of triangles in one pass instead of sequentially, directly speeding up the mesh reduction step that currently bottlenecks scene loading and real-time LOD switching.
A translation layer that converts graphics API calls on the fly lets developers write rendering code once instead of maintaining separate versions for DirectX, Vulkan, and Metal, reducing fragmentation across competing GPU platforms.
Reusing existing FMA engines for logarithms and reciprocals cuts the math overhead that slows rendering pipelines, particularly for ray tracing calculations that demand these operations repeatedly.
Caching intermediate pixel data across multiple viewpoints cuts redundant shading work in light field rendering, a technique critical for VR and holographic displays where dozens of near-identical angles must render in parallel.
A neural network trained on rendered scenes learns to predict which light ray paths actually matter, cutting the number of simulations needed per frame in ray tracing workflows.
Splitting small and large triangle processing into separate pipelines lets Qualcomm avoid forcing diminishing returns on hardware designed for bulk geometry, freeing up resources currently wasted on oversized operations for fine detail work.
Automatic culling of terrain geometry beneath high-detail objects prevents z-fighting artifacts in layered scenes, confirming the shift toward geometric preprocessing rather than post-render fixes.
Rendering pipeline flexibility lets GPUs shift execution strategies mid-frame on mobile hardware, potentially recovering performance when scene complexity or power constraints change during runtime.
Games could render ray-traced frames and denoise them in one pass instead of two, cutting latency while preserving fine texture detail that sequential processing currently loses to filter blur.
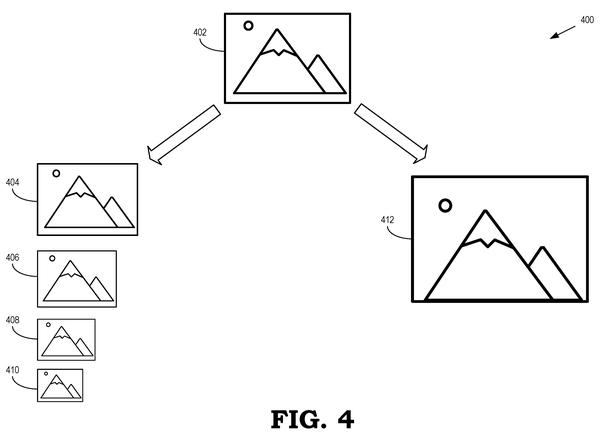
Texture detail scaling removes the per-frame guesswork by automating mipmap level selection based on viewing distance and angle, cutting wasted processing on invisible detail.
Faster frame output means organizing tile groups before rendering starts, which cuts the overhead of shuffling data between GPU cores mid-draw. This confirms the watchlist's focus on reducing the pipeline delays that slow down frame completion.
Better ray-traced images without maxing out GPU load confirms the race is moving past raw computation toward post-render cleanup. AI denoising lets chips cut corners on light sampling and still hit visual quality targets.
Selective rendering plus neural inference lets the GPU skip expensive pixel work and have AI fill occluded or low-priority regions, shifting compute from rasterization to prediction.
The ray tracing efficiency segment gains a pruning mechanism: Intel's method eliminates geometry checks that can't possibly intersect with a ray's path, cutting useless computation before it starts.
The ray tracing efficiency thread gains a learning mechanism: Intel's approach caches hit patterns to prioritize search space, cutting wasted intersection tests on subsequent frames.
Caching shader results for transparent surfaces reduces redundant opacity calculations in ray tracing, letting GPUs skip recomputation when rays repeatedly sample the same geometry positions.
Organizing triangles into hierarchical bundles shrinks the lookup space ray tracers must search, cutting the overhead that makes real-time shadows and reflections prohibitively expensive.
Automating bounding box detection with a trained network cuts the overhead of manual spatial annotation, letting the rendering pipeline spend more cycles on lighting and reflection rather than geometry preprocessing.
The ray tracing efficiency thread now includes a fix for acceleration structure decay during dynamic scenes, letting the renderer patch localized changes instead of rebuilding from scratch.
Reusing color inference from upscaling to seed lower-resolution frames cuts redundant AI computation in the rendering pipeline, tightening the math where neural networks traditionally run multiple passes.
Adaptive detail culling during ray tracing calculation lets the engine render distant geometry at lower resolution without manual artist intervention, cutting processing load during the per-ray phase where most bottlenecks occur.
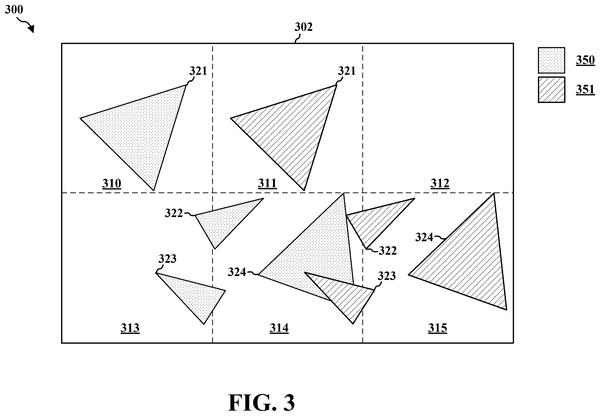
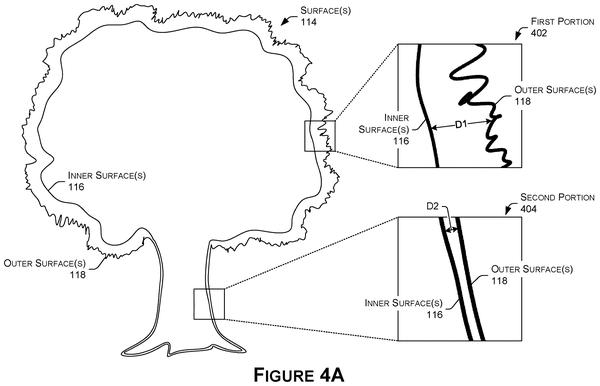
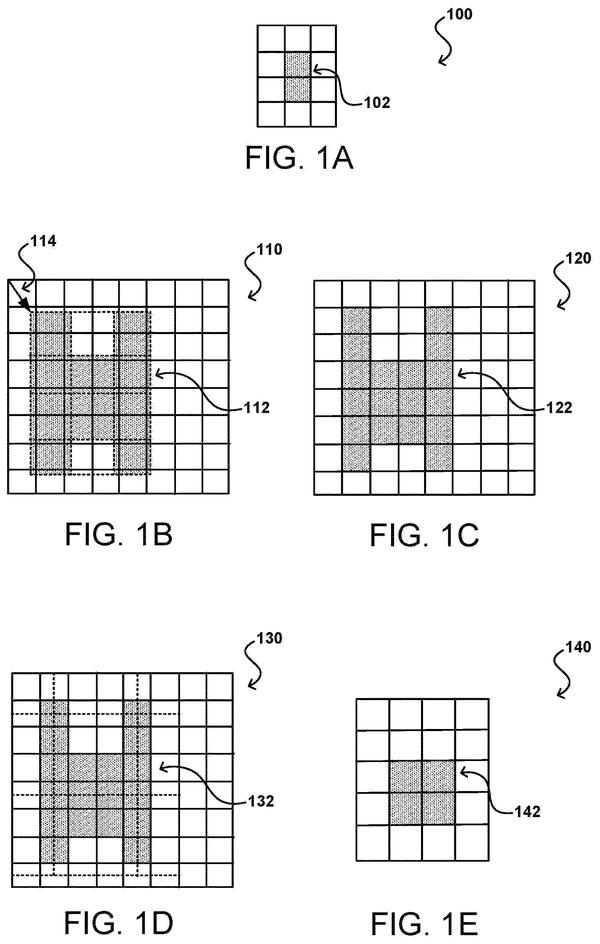
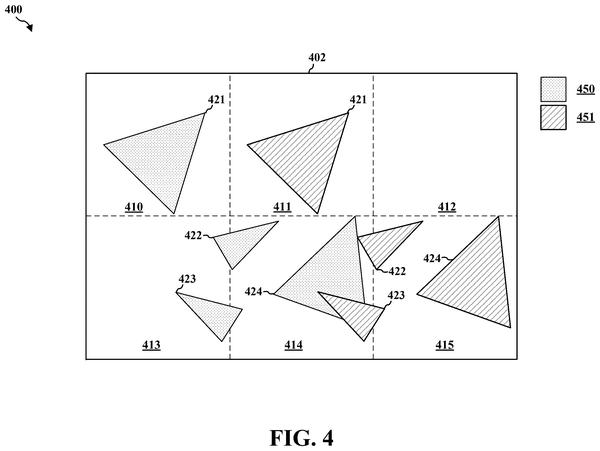
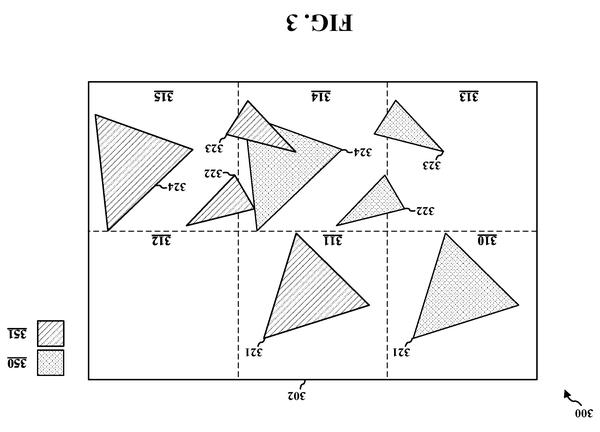
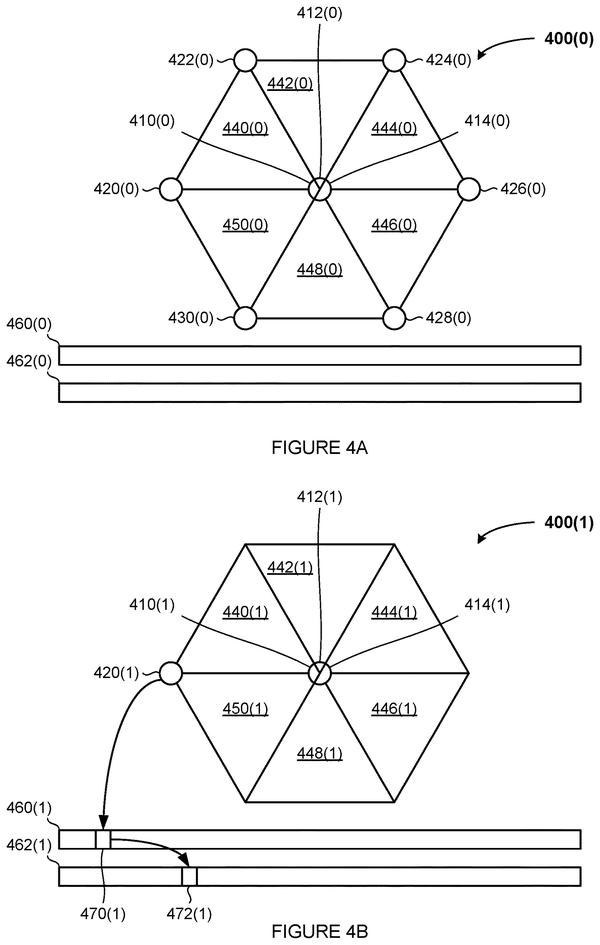
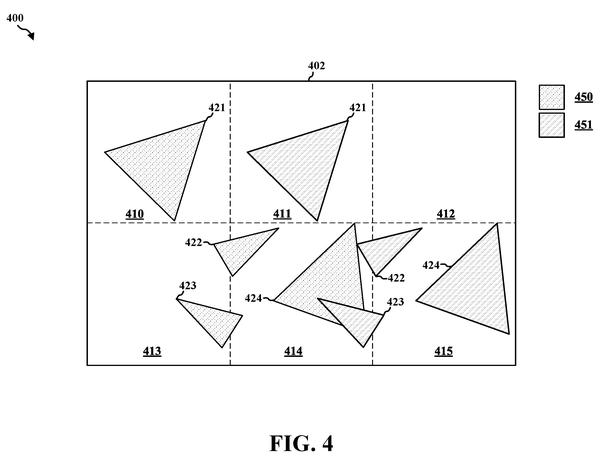
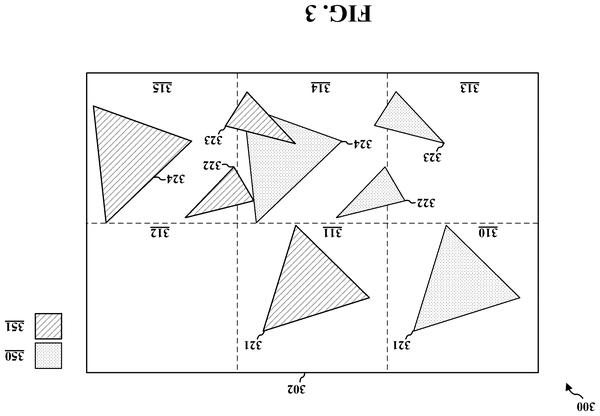
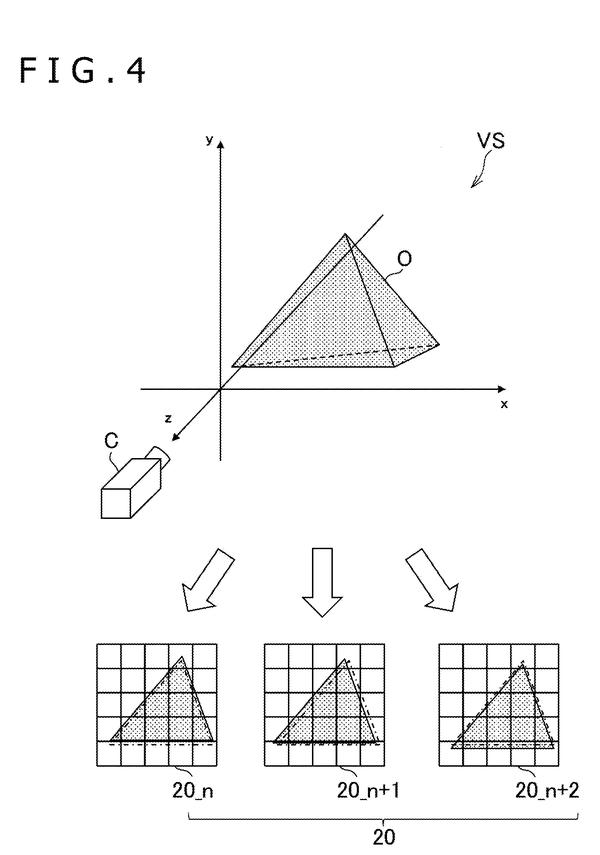
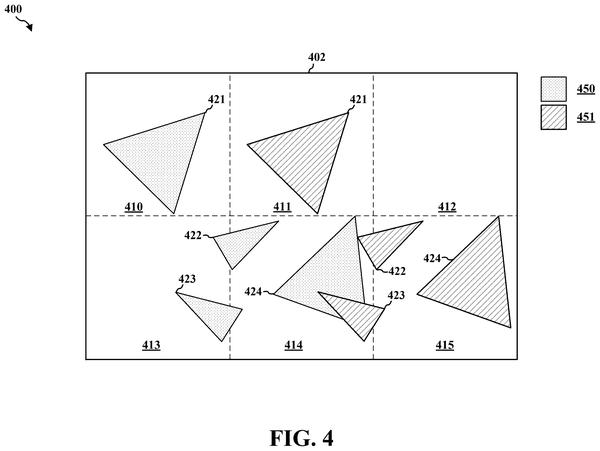
Within the edge-smoothing category, this filing extends the layered-triangle approach to opacity blending, suggesting a path to sharper geometry at lower computational cost than traditional antialiasing methods.
Driver-level frame interception lets Nvidia adjust rendering parameters per-scene without app involvement, shifting upscaling and enhancement decisions from game developers to runtime hardware analysis.
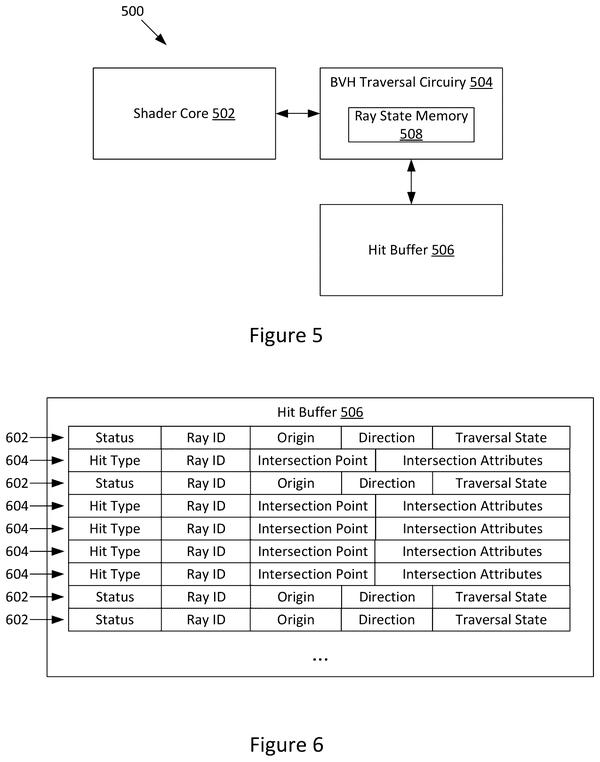
Hierarchical bounding box compression cuts the memory footprint of ray tracing acceleration structures, letting GPUs store more geometric culling data on-chip instead of fetching from main memory during intersection tests.
Caching acceleration structures offline shifts the ray tracing bottleneck away from real-time geometry organization, letting GPUs focus compute on light simulation rather than data structure assembly during frame rendering.
Neural network color inference across frame sequences targets the reconstruction gap in sparse rendering, where temporal color patterns replace exhaustive per-pixel calculation to reduce flicker and color discontinuity artifacts.
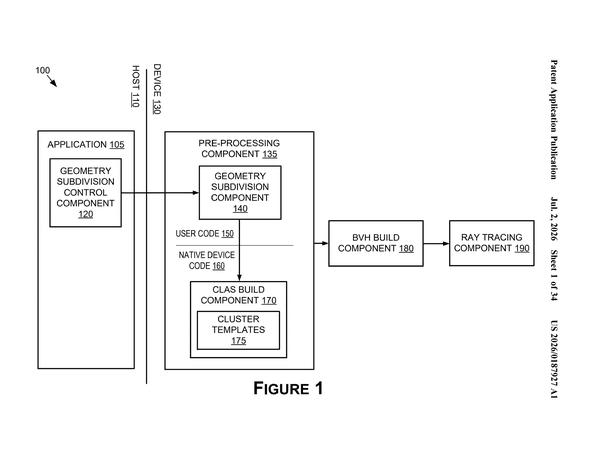
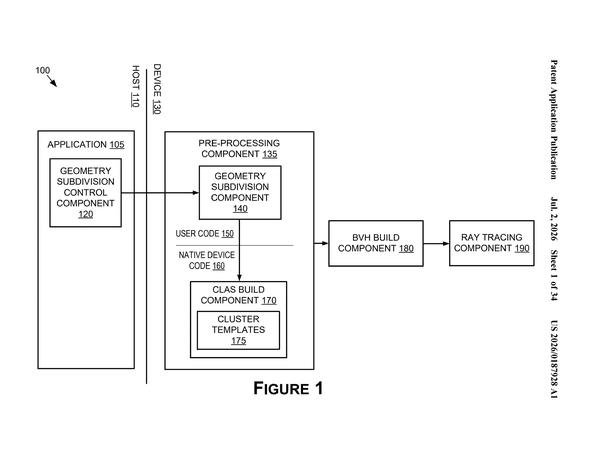
The ray tracing and edge-smoothing work in this race assumes triangles are already grouped sensibly in memory. Nvidia's filing describes organizing mesh data before rendering even starts, removing a major sorting bottleneck upstream.
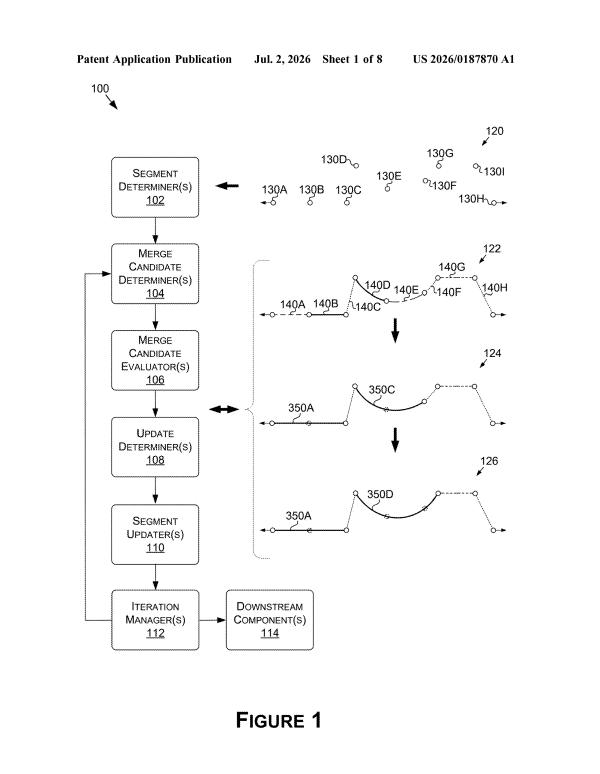
Bulk merging of adjacent curve segments eliminates redundant geometry work, speeding up the tessellation stage where curved paths convert to renderable polygons.
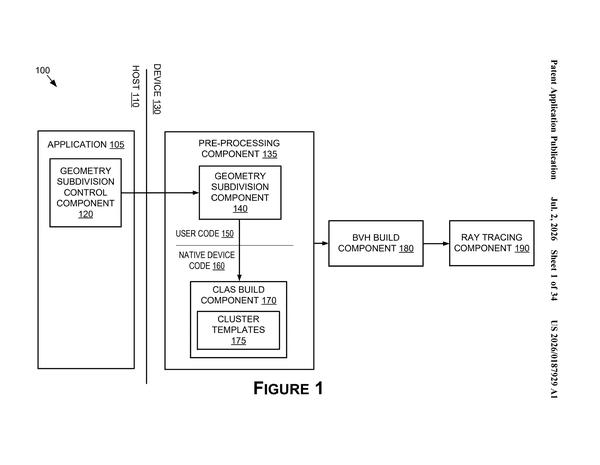
Caching pre-computed spatial maps for recurring triangle patterns cuts the per-frame geometry sorting work that currently consumes significant GPU cycles before ray calculations begin.
The texture conversion and edge smoothing work in this watchlist now has a prerequisite: organizing triangle data spatially so the GPU wastes less time hunting for nearby geometry during rendering operations.
Caching pre-computed geometry solutions lets the GPU reuse lighting and shape data across repeated scene elements rather than recalculate from scratch, reducing one of rendering's most expensive bottlenecks.
Precaching geometry layouts during asset compilation rather than computing optimal memory packing on each render call. Addresses a bottleneck in the ray tracing efficiency category by shrinking per-frame overhead for scene traversal.
Selective pixel weighting during upscaling preserves edge definition by filtering out distant neighbors that contribute noise rather than useful detail, sharpening text and fine lines in enlarged images.
Within the ray tracing efficiency focus, this confirms movement toward separating surface and subsurface light behavior rather than approximating both with single calculations, reducing compute load for translucent materials in real-time rendering.
Games would render with upgraded textures and models without developers rewriting code, letting Intel's hardware handle the visual modernization layer between game engine and screen output.
Filtering protected content per-display rather than system-wide lets GPUs serve streaming video to compliant monitors while blocking older screens, solving a compatibility problem when mixed-generation displays connect to one PC.
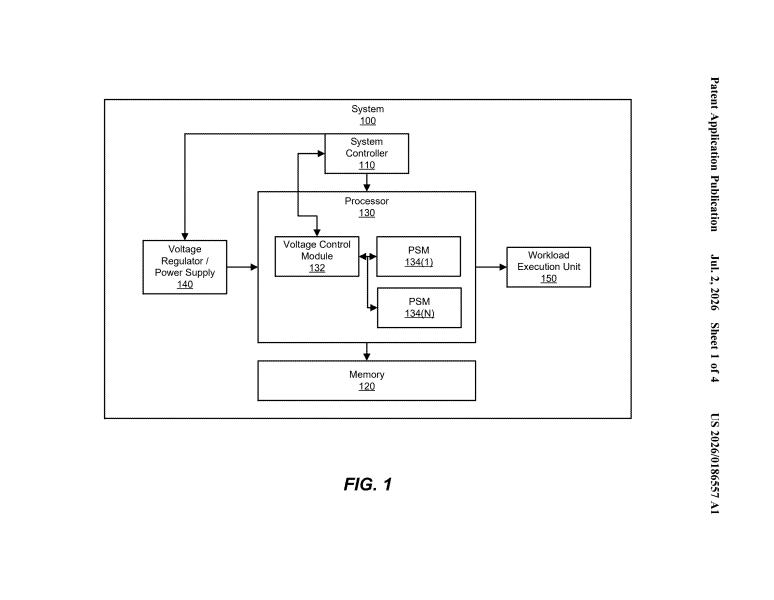
Monitoring actual voltage demands in real time lets the chip trim its safety margin down from a fixed overhead to a dynamic one, freeing up power budget that rendering workloads can claim instead.
Voxel-based light sampling replaces traditional ray marching with discretized spatial queries, streamlining the per-pixel color calculation that bottlenecks real-time ray tracing in competitive rendering.
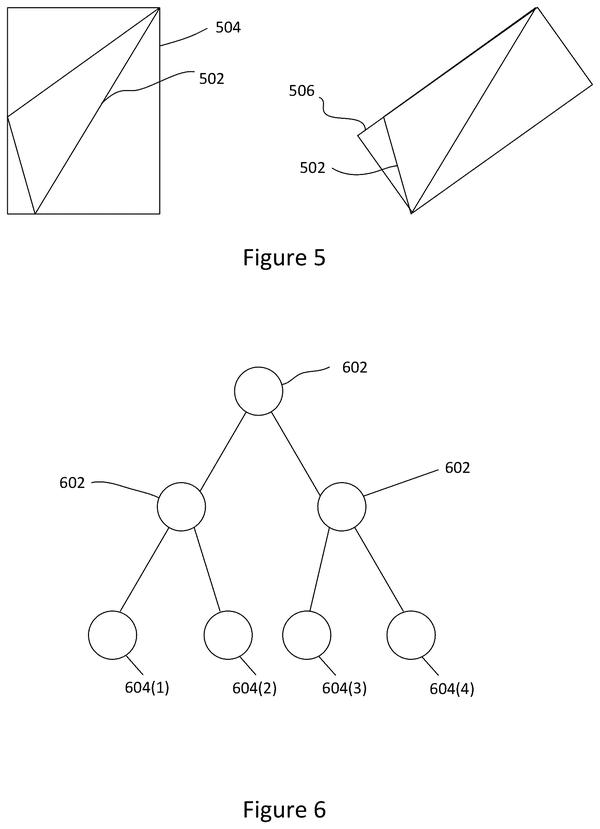
Faster ray tracing means games stay sharp during action scenes without frame drops. AMD's patent rotates the bounding boxes around diagonal objects to cut wasted computation that currently slows rendering.
Preprocessing overhead in AI inference pipelines gets cut by routing simple images through faster resize paths while reserving expensive algorithms for complex scenes.
After texture memory emerged as a bottleneck, AMD targets redundant requests hitting the same surface simultaneously, deduplicating them before they consume bandwidth.
Ray tracing math overhead shrinks when a GPU pre-filters using compressed triangle data on idle matrix hardware, eliminating some of the full-precision calculations that currently bog down rendering.
A trained neural network predicts which light sources reach each surface point, replacing per-frame visibility calculations that consume GPU cycles on complex shadow geometry.
Hierarchical spatial filtering lets the GPU skip ray tests against geometry tucked inside boxes marked as non-essential, cutting the math load that normally balloons when precision suffers.
Automated camera repositioning within the GPU pipeline generates training data from single scenes by capturing multiple viewpoints, reducing the manual work needed to build datasets for AI graphics models.
Games could render fine lines without the jagged staircase effect, removing one visual compromise that currently requires either expensive anti-aliasing passes or accepting visible artifacts on thin geometry.
After texture memory bottlenecks, AMD is now carving out dedicated silicon for AI upscaling math, moving the workload off general-purpose cores to stop image sharpening from competing with frame rendering.
Repeated texture conversion wastes GPU cycles during rendering. Intel's filing caches transcoded textures in hardware so the GPU skips redundant format conversions on reused assets.
Questions readers ask
Are Intel and AMD actually building these GPU features, or are these just patents?
These are patent filings, which describe inventions a company wants to protect, not confirmed products. Filings from Intel and AMD around texture conversion, ray tracing, and AI-driven lighting show where engineering teams are focused, but a patent alone does not guarantee the feature will ship in a real GPU.
Why do so many of these patents focus on ray tracing?
Ray tracing is computationally expensive, and several filings, including AMD's work on bounding boxes, repeated data requests, and borrowed math hardware, plus ATI's patent on wasted ray tracing tests, all try to cut steps the GPU doesn't need to repeat. That concentration suggests ray tracing efficiency remains an unsolved cost problem for chipmakers.
What's the difference between Intel's and AMD's approach in these filings?
Based on this batch, Intel's filings lean toward texture handling, AI training tools, and making older games look sharper on modern hardware. AMD's filings concentrate more on ray tracing performance and AI-assisted upscaling and lighting. Both aim at squeezing more visual quality out of existing GPUs rather than requiring new chips.
Will these patents make my games run faster?
Not directly and not immediately. A patent filing is a legal claim on an idea, and the timeline between filing and any real product is unpredictable. What these filings show is that Intel and AMD are both spending research effort on cheaper lighting, sharper upscaling, and faster ray tracing, which are the kinds of gains that eventually reach consumer GPUs.
Want this weekly breakdown for a company we don't cover?
Patentlyze Pro →
The weekly email: the best of Big Tech's filings, in plain English. Free.