Big Tech's AI Guardrails Patents, and Where the Race Is Headed
This tracker collects patents that rank AI answers by accuracy, trace text back to its source, catch conflicting data, and block AI agents or code before they cause harm. The batch shows Big Tech treating AI mistakes as an engineering problem with layers of checks, not a single fix.
223 filings
· tracking since May 2026 · latest Nov 2026 · updates weekly
based on all tracked filings in this watchlist · refreshes every week
This fight is over who controls the safety layer sitting between an AI and the people using it: the tools that check answers, block harmful outputs, catch bias, and prove the AI is doing what it claims.
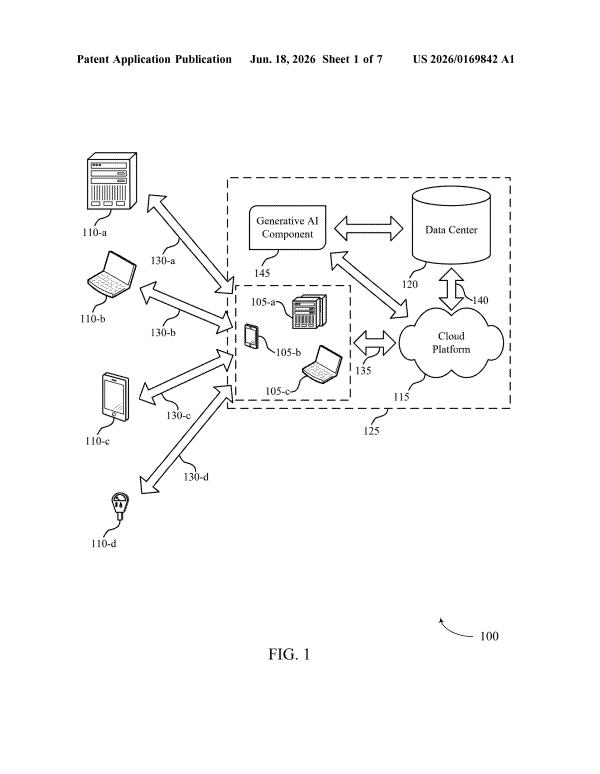
IBM leads by a wide margin in raw filing count, with work spread across bias checks, legal compliance, and tracing AI outputs back to their source; Microsoft and Google follow, focused on self-checking outputs and grounding answers in real sources.
What’s new in the AI guardrails race
a dated entry each week this watchlist moves · older entries stay archived
Nov 5, 2026 13 filings joined
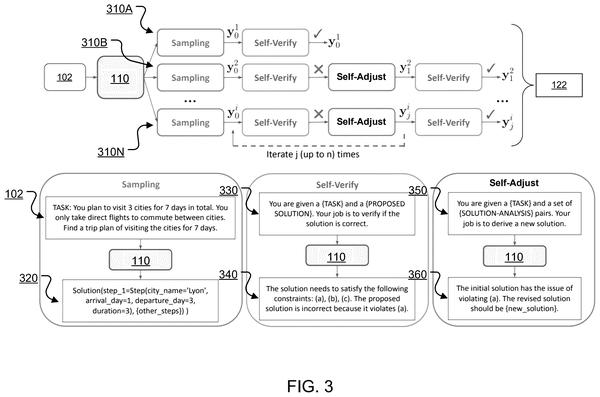
Most filings this week focus on AI checking its own work before sharing it, from code to bug reports to cited links. OpenAI and IBM are the most active, each filing multiple patents in this space.
This week's filings center on catching AI mistakes before they reach users, with Microsoft and IBM leading the pack. Both companies filed multiple patents around fact-checking, filtering, and bias detection across different use cases.
IBM leads this week with six filings covering AI safety, training, and system design. Nvidia and others add tools for controlling what AI says and catching security gaps before they cause harm.
This week's filings focus on keeping AI honest: citing sources, pulling back wrong answers, and keeping humans in the loop. Adobe leads with three filings, joined by IBM and Intel.
This week's filings center on keeping AI honest and safe, from fact-checking answers to blocking unsafe programs. IBM and Microsoft are the most active, each filing on controlling how AI behaves.
Most filings this week focus on catching AI mistakes and blocking bad inputs before they cause harm. Amazon and Microsoft are the most active, each filing multiple patents around screening, error-catching, and access control.
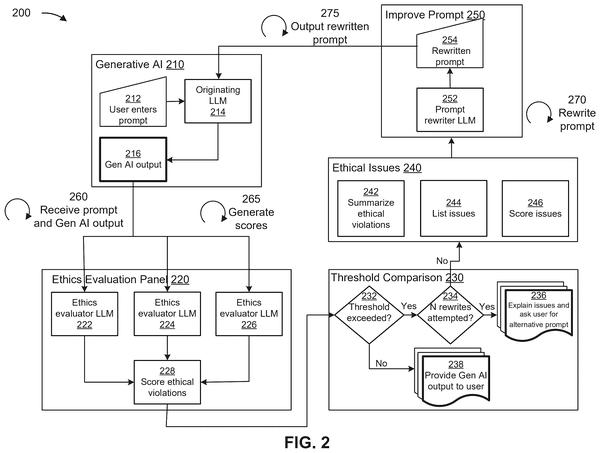
IBM leads this week with three filings covering fact-checking, access control, and rewriting bad AI outputs. Together with Amazon, Google, and Adobe, the filings show a broad push to catch, score, and trace AI responses before or after they reach people.
Nvidia leads this week with four filings focused on finding where AI goes wrong and checking if its own answers are good. IBM and OpenAI add patents around stopping AI from lying and keeping data safe.
This week's filings center on AI systems that check their own work, from health advice to code to image captions. IBM leads with four filings, while OpenAI and Adobe each added two focused on catching errors before they reach users.
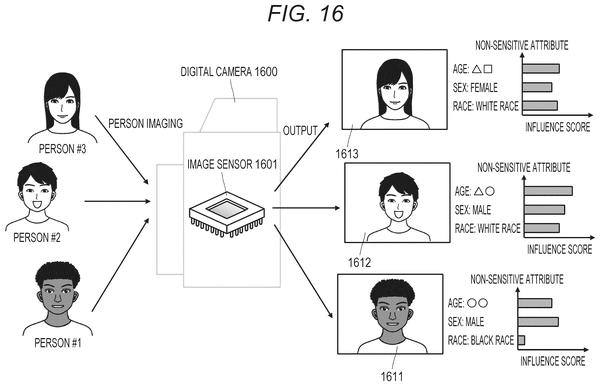
This week's two filings both focus on making AI more transparent and accurate: Google is working on helping AI tell apart questions that sound alike, while IBM is working on showing people exactly which parts of an image made its AI reach a decision. Google and IBM each added one filing.
Aug 27, 2026 18 filings joined
This week's filings center on catching AI systems when they lie, leak private data, or get manipulated into breaking their own rules. IBM leads with the most filings, while Microsoft and Google add work on testing AI for weak spots and tracking privacy attacks.
Aug 20, 2026 8 filings joined
This week's filings center on AI systems that check themselves before acting, from testing answers before speaking to catching bad outputs before they reach people. IBM leads with two filings, joined by Adobe, Microsoft, Nvidia, Google, Samsung, and Amazon.
Who’s filing patents in the AI guardrails race
counts from tracked filings · focus read from each company’s own filings
the fights inside the fight · each with its three newest filings · new filings join every week
AI Checking Its Own Answers 38 filings
IBM 11, Microsoft 7, Google 6
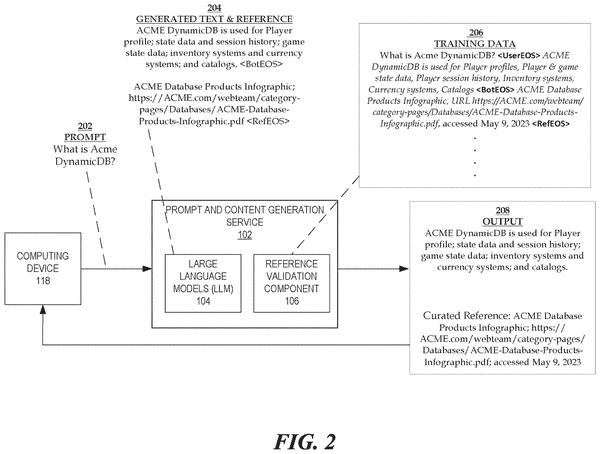
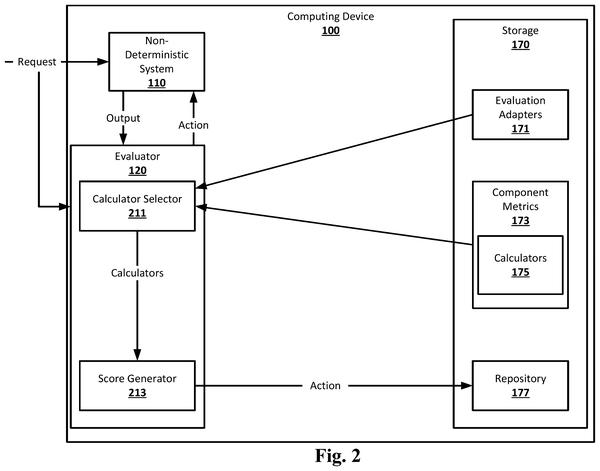
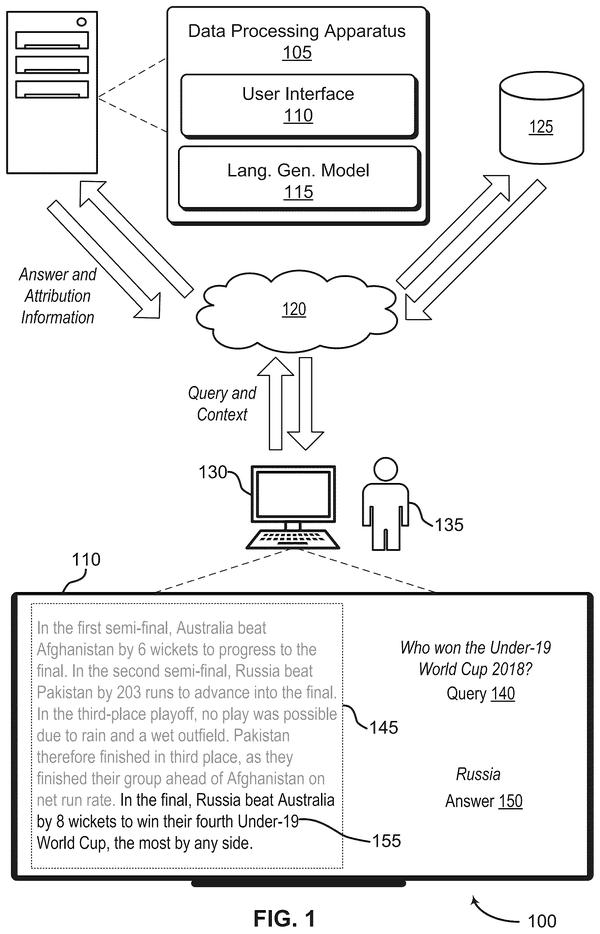
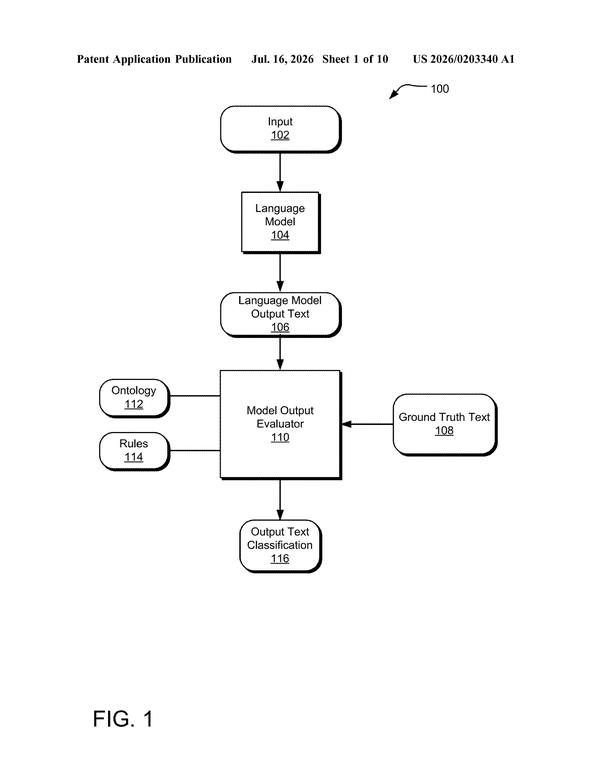
Several companies are filing patents for systems where an AI reviews, scores, or rewrites its own output before a person ever sees it. The approaches range from rewriting false answers to grading articles to catching broken logic.
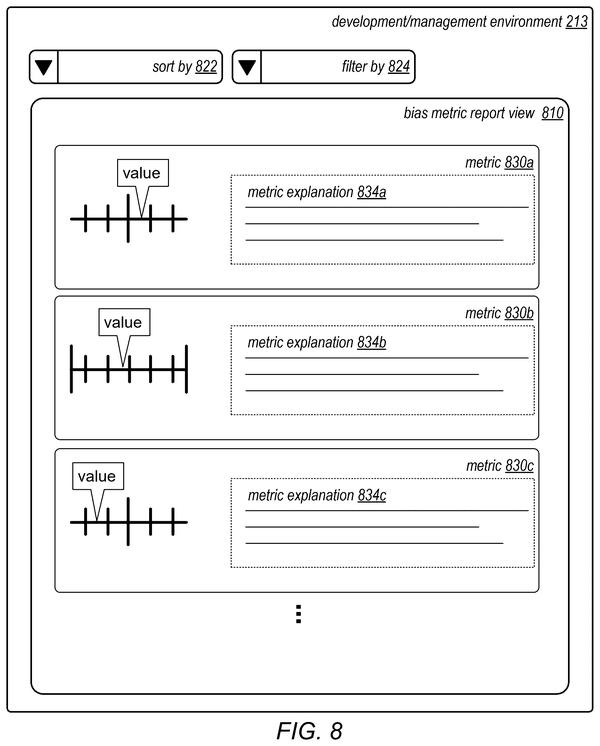
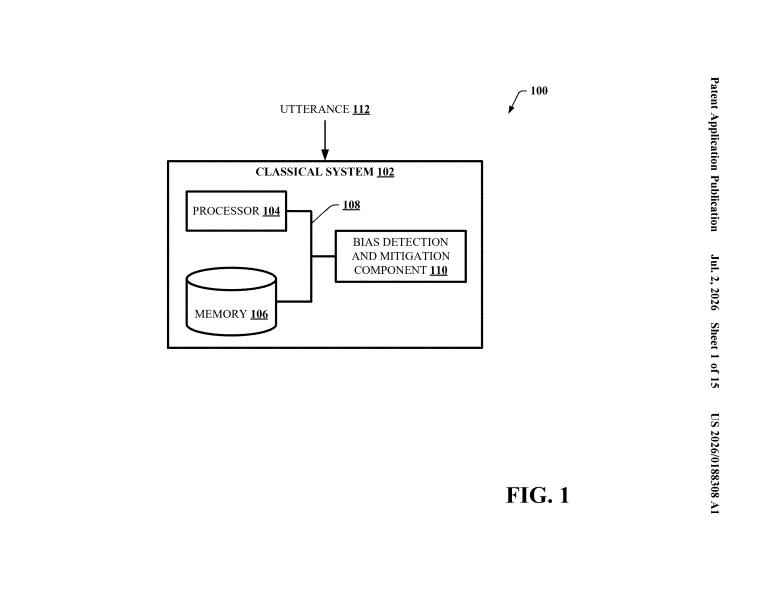
These filings cover systems that measure whether an AI is treating different groups of people differently, and in some cases let users or developers see and fix the problem.
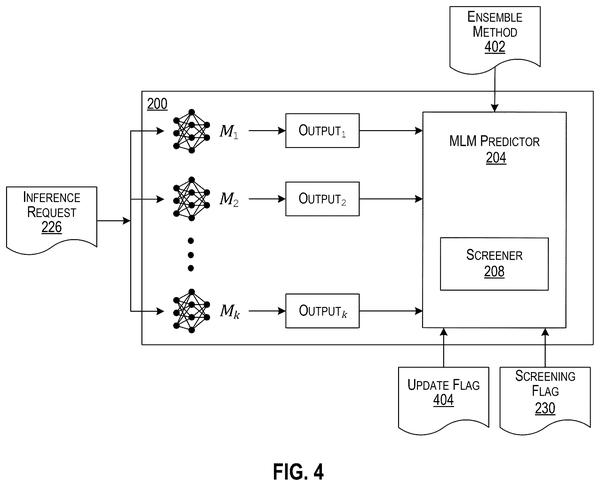
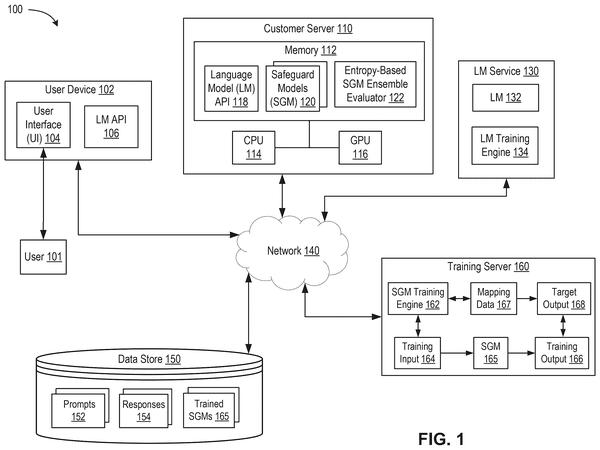
Rather than one AI checking itself, some patents describe a group of AI systems that evaluate each other, with votes or scores to reach a safer final answer.
Devices Reporting When Their AI Goes Wrong 10 filings
Samsung 2, Intel 2, Nvidia 2
These filings cover hardware, phones, and network devices that can detect when an on-device AI model is producing bad results and flag or report the problem.
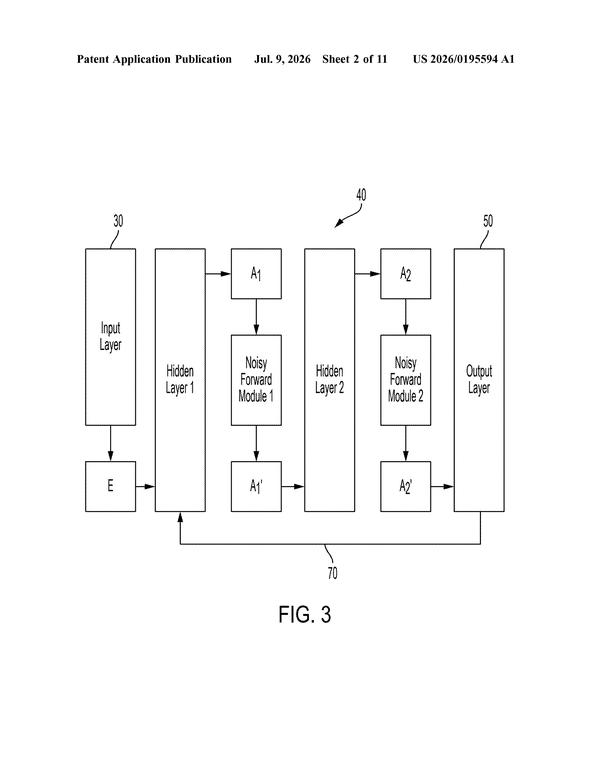
Protecting the model itself: trapping thieves, feeding controlled noise, tracing corrupted training, catching attackers who manipulate the model, and stopping leaks of private training data.
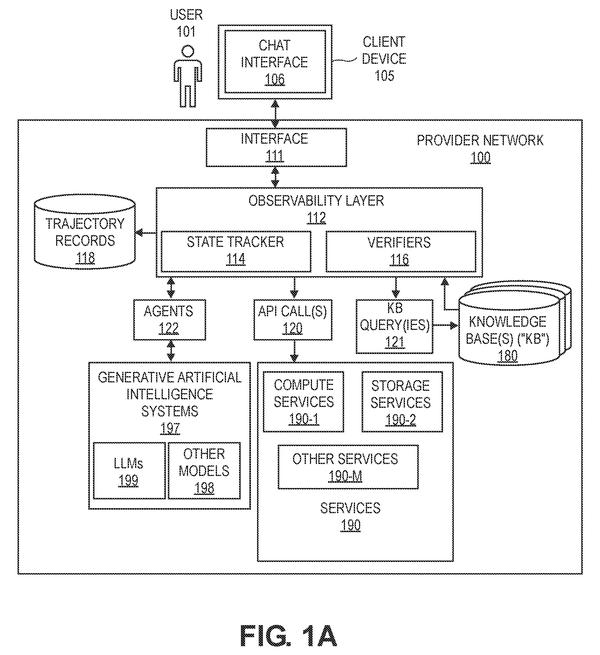
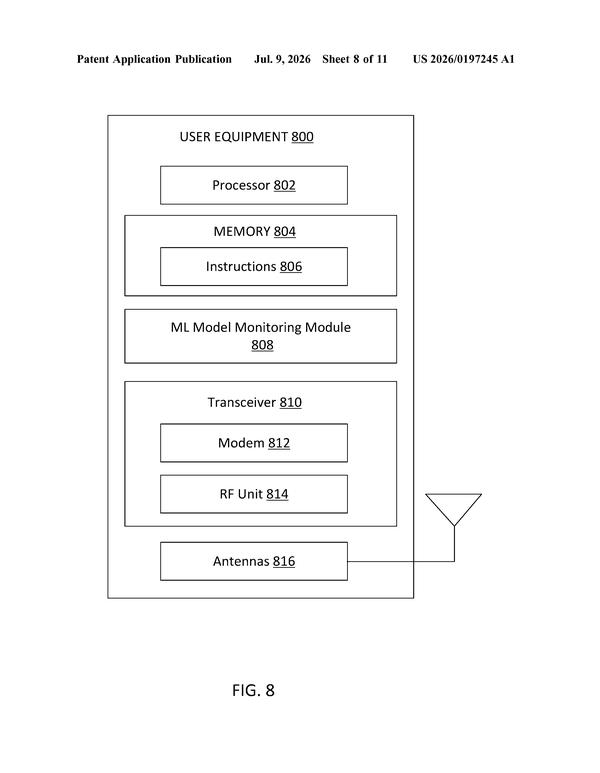
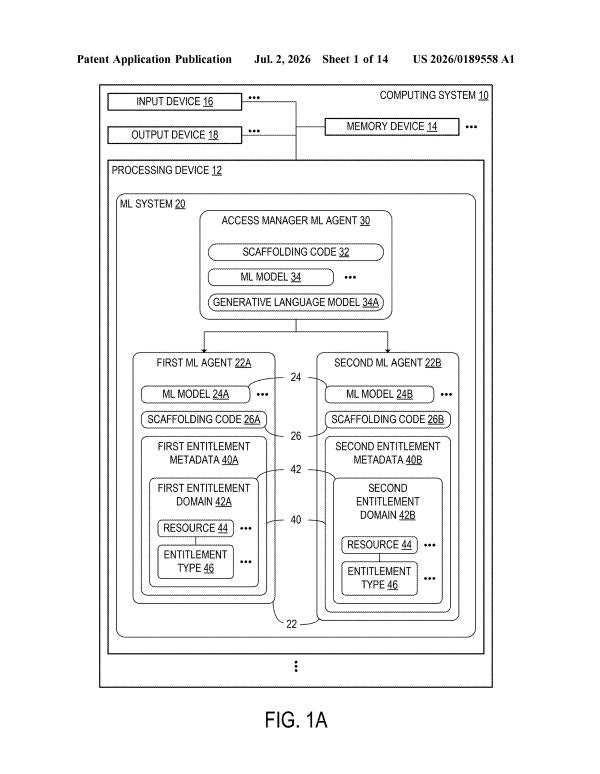
Permission systems for AI that acts on its own: security clearances, least-privilege access, plain-English access rules, dashboards to override an agent, and risk scores that stop a costly move.
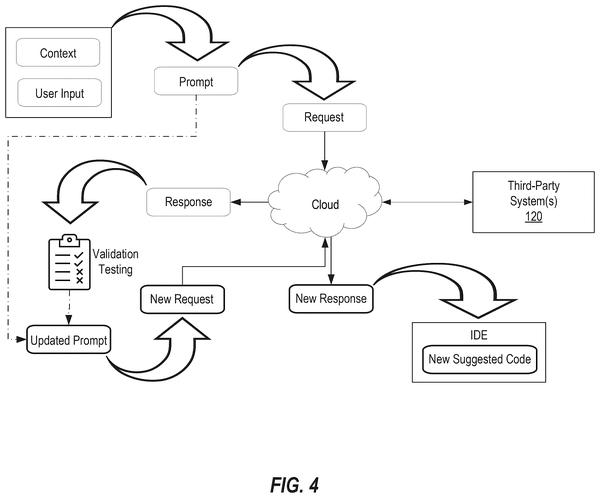
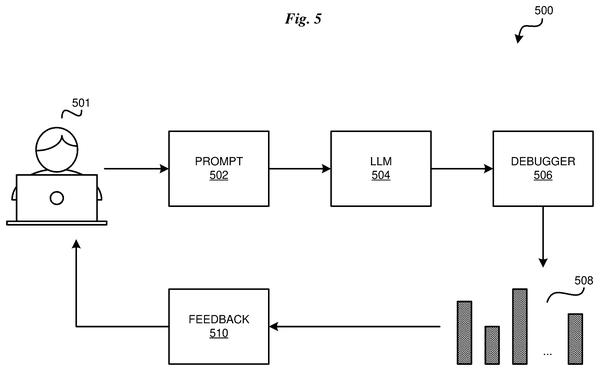
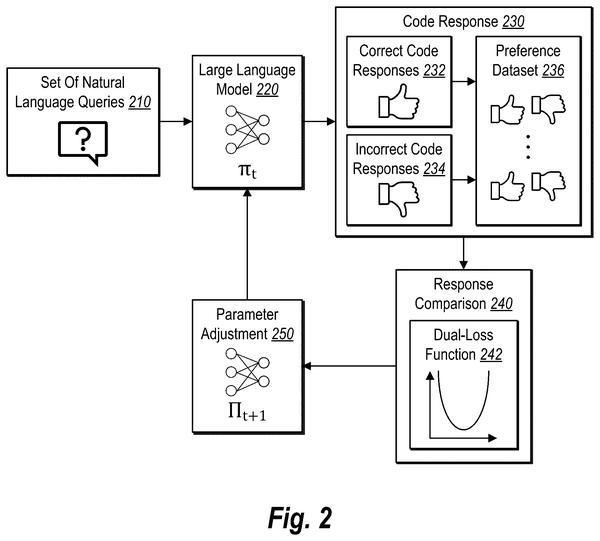
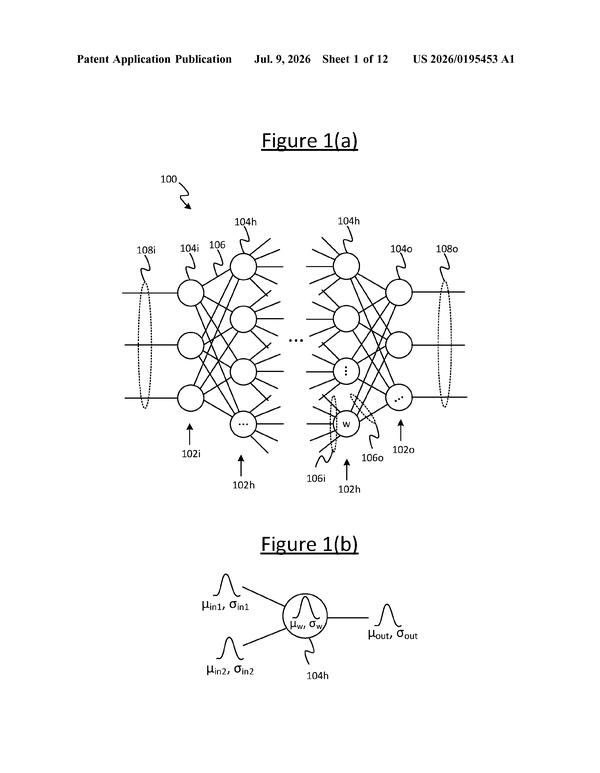
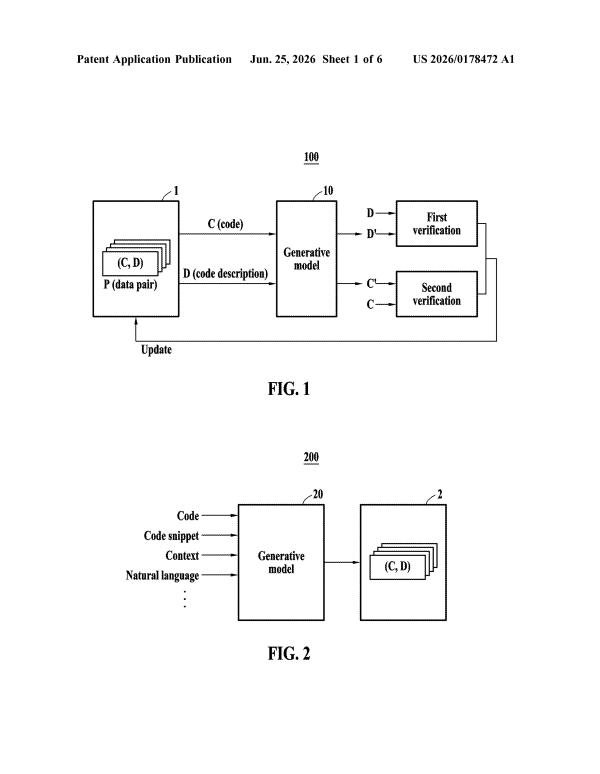
AI agents generating code need verification before deployment; this patent moves testing upstream by having the system validate suggestions internally rather than letting broken code reach developers.
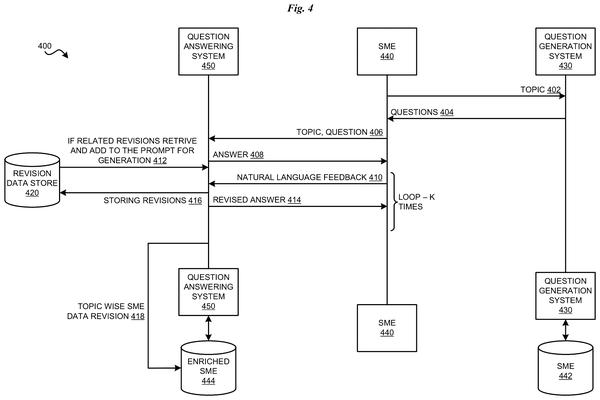
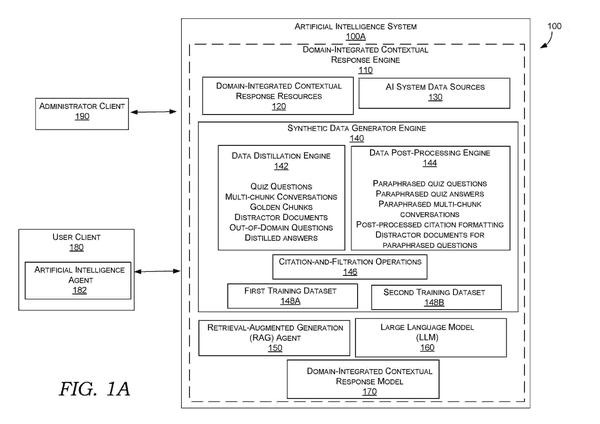
Self-generated quizzes paired with expert correction loops create a feedback mechanism to prevent recurrence of factual errors, shifting from catching hallucinations after deployment to building them out during training.
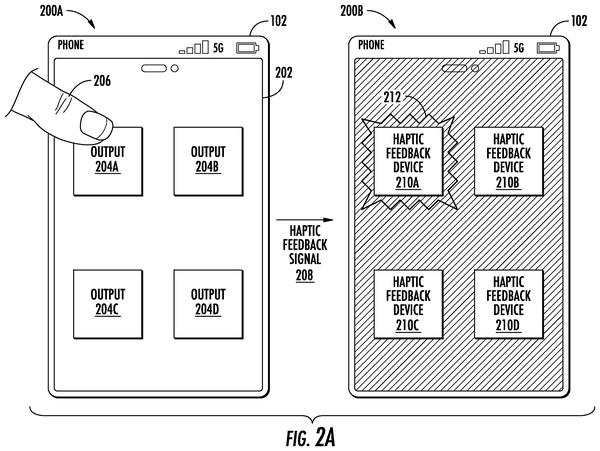
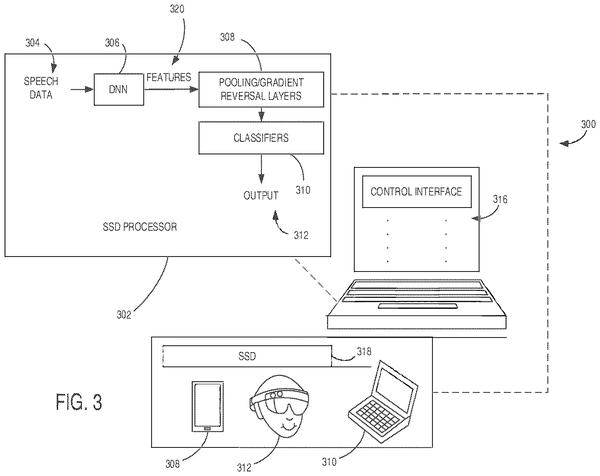
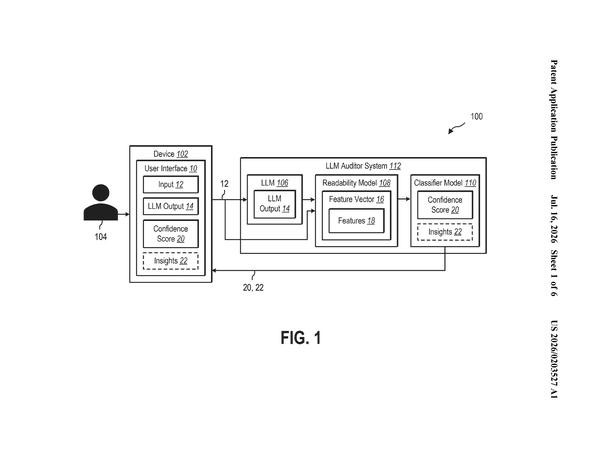
Haptic feedback that varies by confidence level gives users a physical signal for which AI outputs warrant skepticism, addressing the gap where uncertain transcriptions or answers appear on screen with no confidence markers.
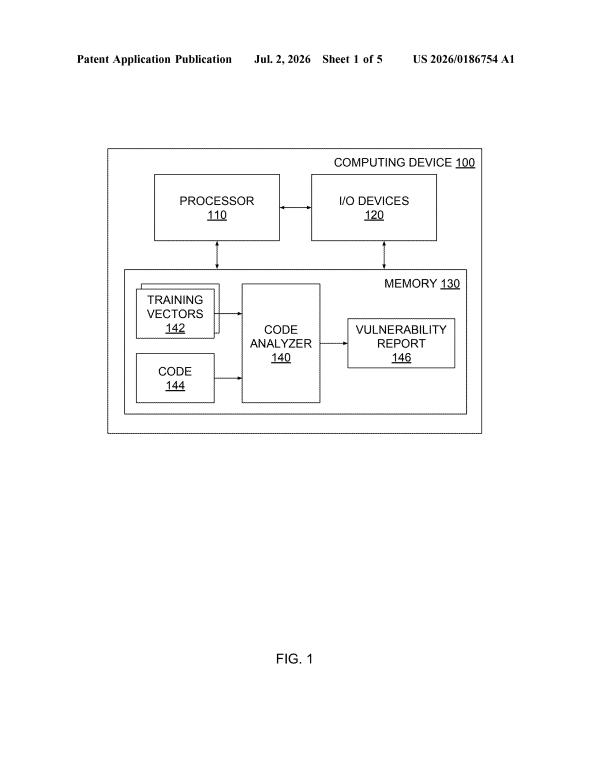
Current guardrails focus on AI output accuracy and source verification. This filing shifts toward using AI to find vulnerabilities in deployed software itself, automating the detection work that human security teams can't scale to finished, compiled code.
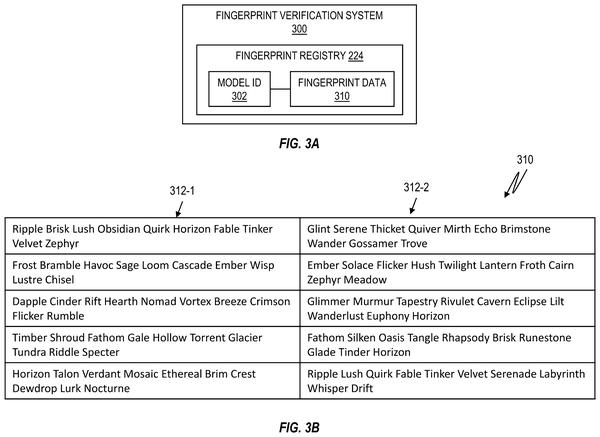
Within the guardrails race, verifying model authenticity remains unsolved. IBM's approach embeds secret question-answer pairs during training so users can confirm they have the genuine model, not a tampered copy.
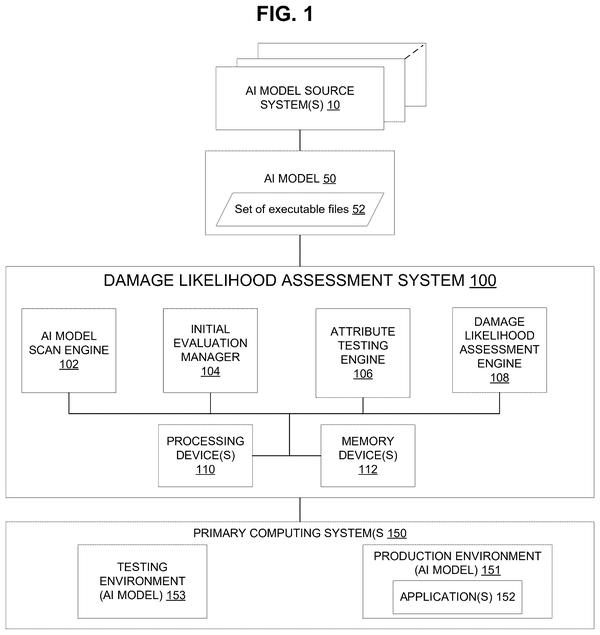
A sandbox checkpoint that scores downloaded models before they touch production systems fills a gap in existing security tools built for traditional code, not neural weights.
The race so far has focused on catching bad answers after they're generated. IBM's filing shifts the point of intervention earlier, scoring question quality before the AI even responds to filter out requests that are too vague or malformed to answer reliably.
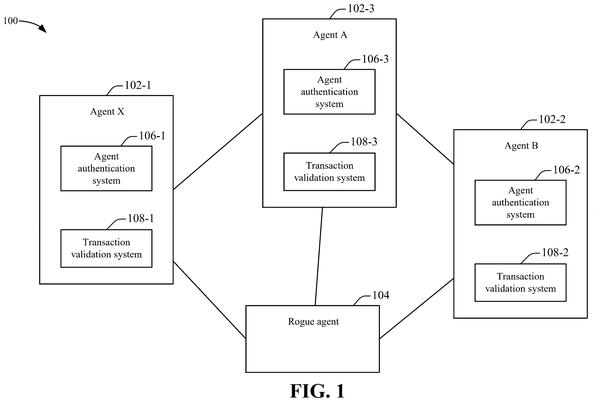
If AI agents keep handing work down a chain, any compromised link could corrupt everything downstream. Salesforce's filing adds verification at each handoff, catching whether the requesting agent is real and has permission to delegate that specific task.
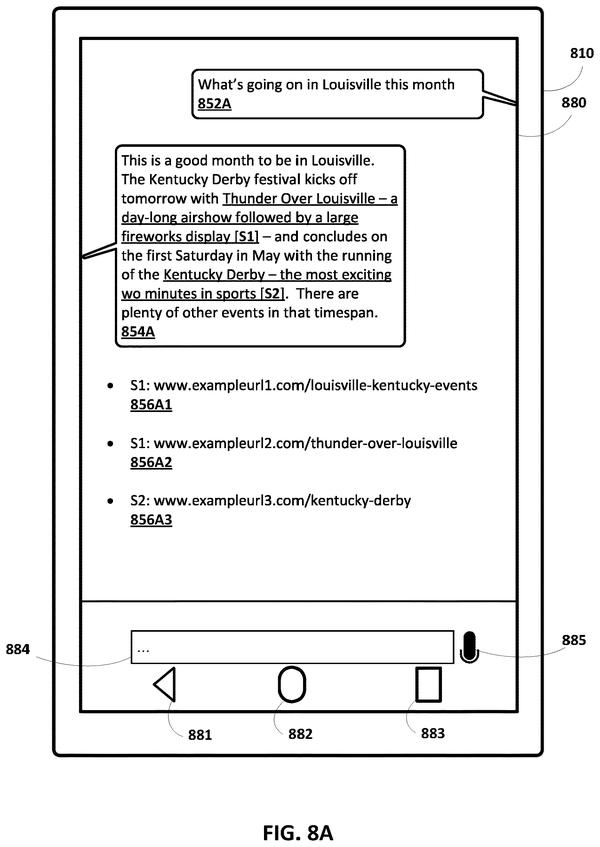
The tracker has flagged the source-verification gap; Amazon's filing proposes catching it at the citation layer by validating each URL against the training data before the answer reaches the user.
Reproduction testing before human alert prevents false positives that plague traditional scanners, filtering noise from genuine vulnerabilities in multilingual codebases.
The guardrails race includes blocking harm before deployment; this filing moves the checkpoint earlier, catching security gaps as code enters the repository rather than waiting for later review stages.
If implemented, users could upload documents knowing the summary won't amplify factual errors baked into the source material. The patent describes a system that validates specific claims before condensing them.
Preventing voice synthesis from drifting toward recognizable people or copyrighted material requires real-time monitoring during generation, not just post-hoc filtering.
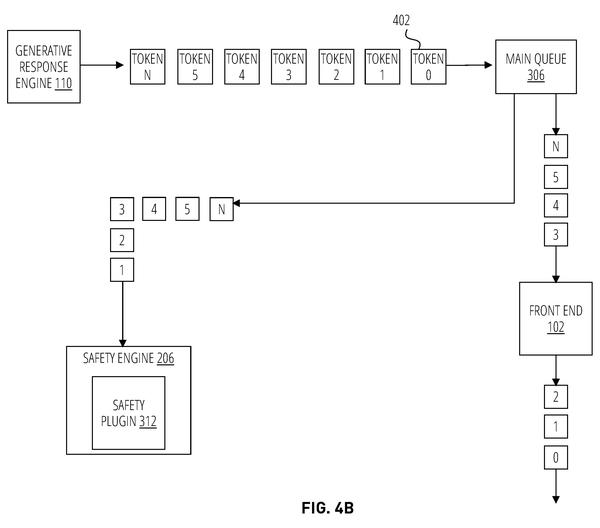
Safety checking is lagging behind generation. OpenAI proposes streaming replies while checks catch up asynchronously, sacrificing completeness for perceived responsiveness.
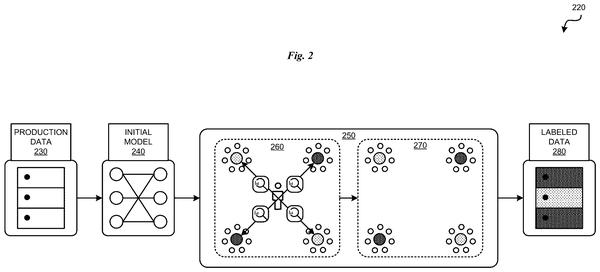
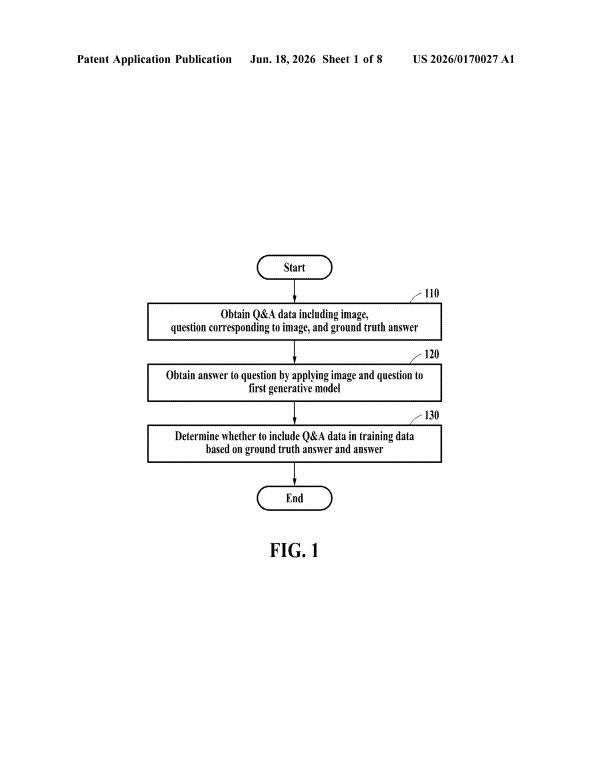
If this works, AI systems could learn which photo descriptions are accurate without needing human reviewers to label thousands of images, cutting a major cost and delay in building more reliable vision models.
If this patent works, you could verify why an AI rejected a dangerous action instead of just trusting its refusal. The filing maps exactly which facts and rules the system weighed before blocking an agent from proceeding.
If confirmed, AI companies could prove ownership of generated text by matching it to their training data rather than embedding hidden marks in the output itself.
Verification before deployment means AI-optimized code gets formally proved equivalent to its source before replacing it, closing a gap where speed gains could silently corrupt results.
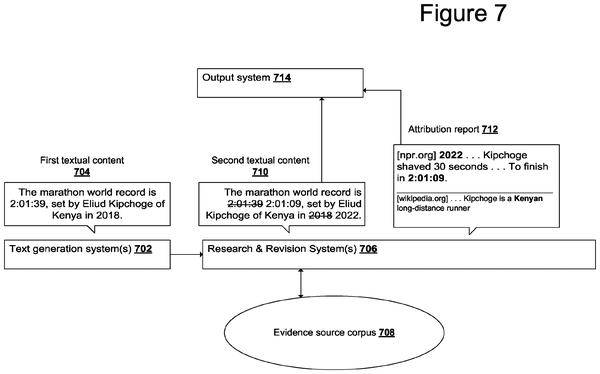
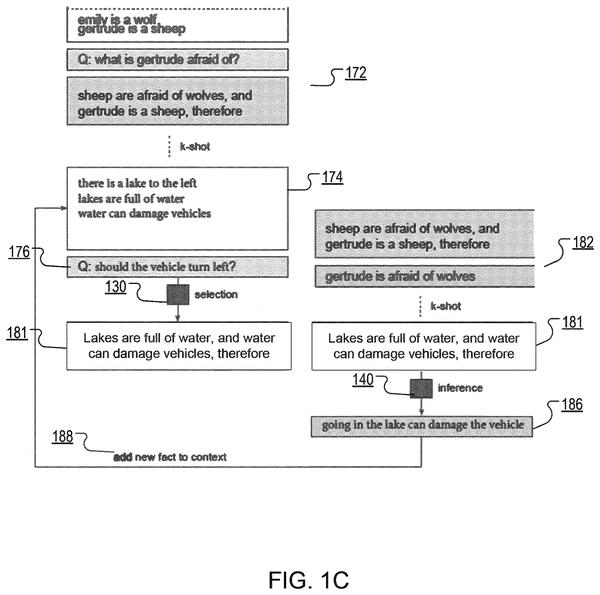
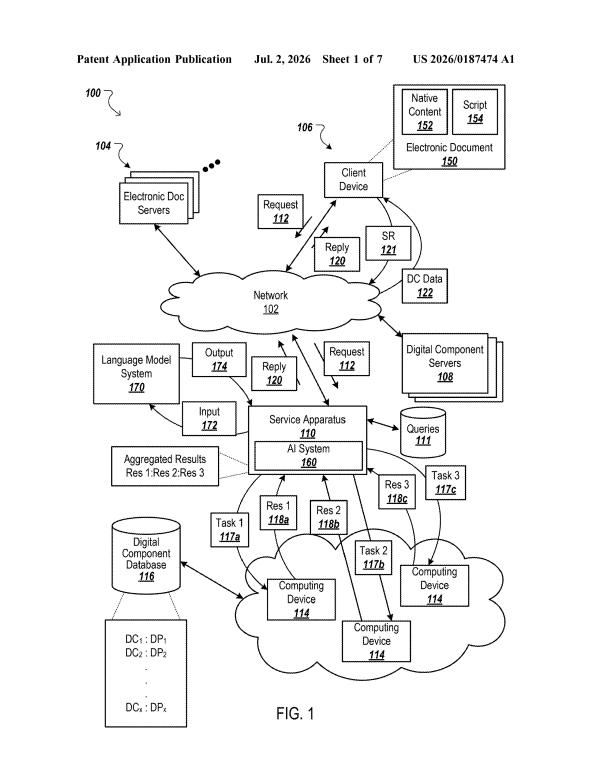
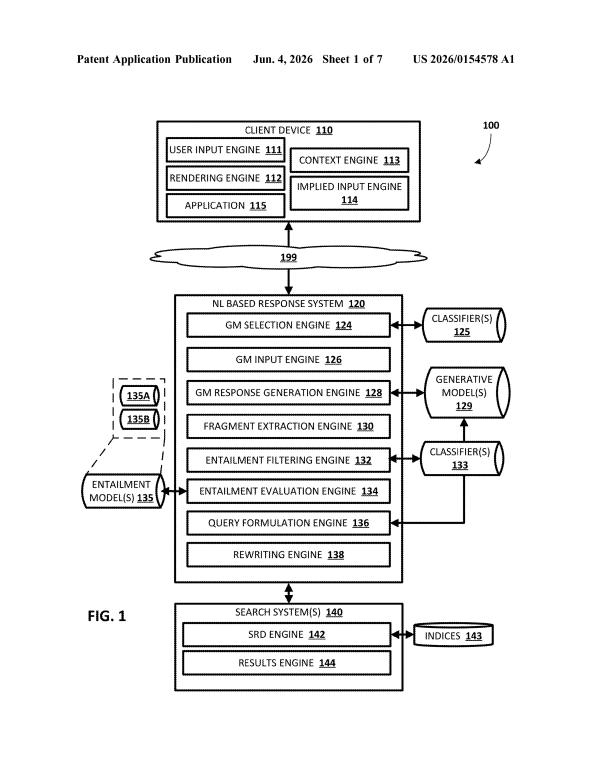
Detecting false claims embedded in confident AI output requires a separate verification pass. Google's approach uses a second model to query the web for each factual assertion and rewrite errors with source links attached.
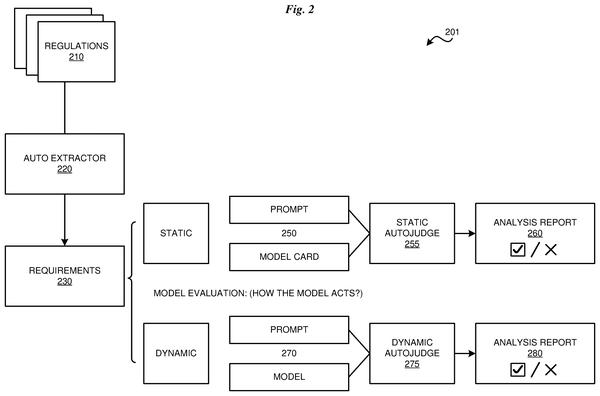
If this works, compliance screening moves from manual legal review to automated grading against specific regulatory text, cutting the labor cost of each model release.
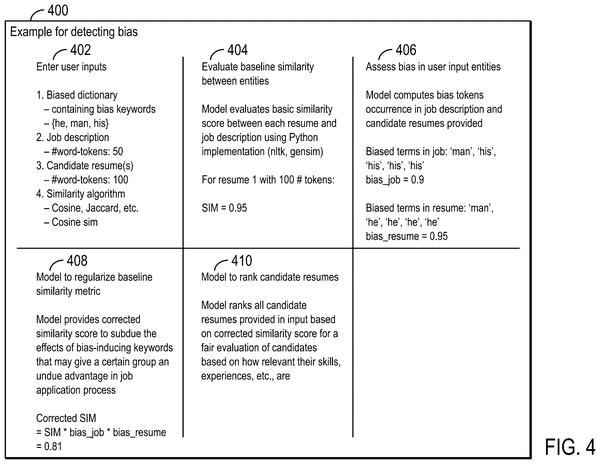
Gendered language in job postings can inflate match scores for resumes that mirror those same words, rewarding wording over qualifications. IBM's method applies a penalty to those inflated scores without retraining the underlying model.
Determining if content violates policy requires checking multiple violation types at once. Microsoft's approach uses repeated self-verification loops, cycling through until classifications stabilize, rather than relying on a single pass.
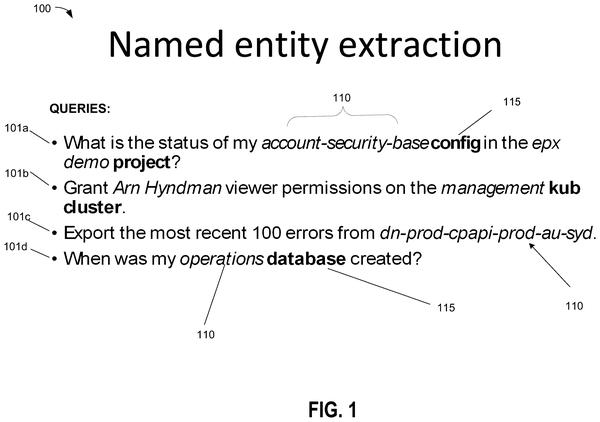
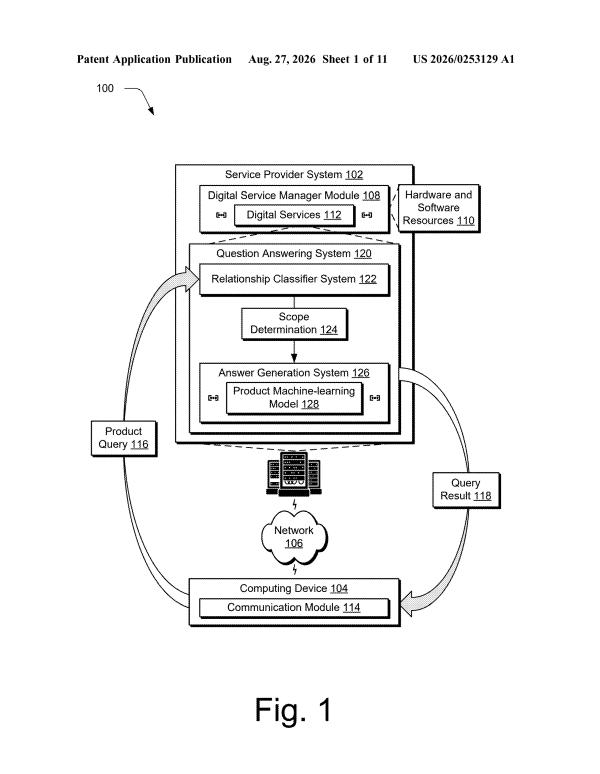
Semantic confusion from entity names derails AI responses to practical queries. IBM's approach masks names during processing so word overlap with schema labels can't trigger false routing.
Preventing false output before display requires a reference standard. Microsoft's method generates verified answer keys from expert-reviewed source material, then filters chatbot responses against those keys in real time.
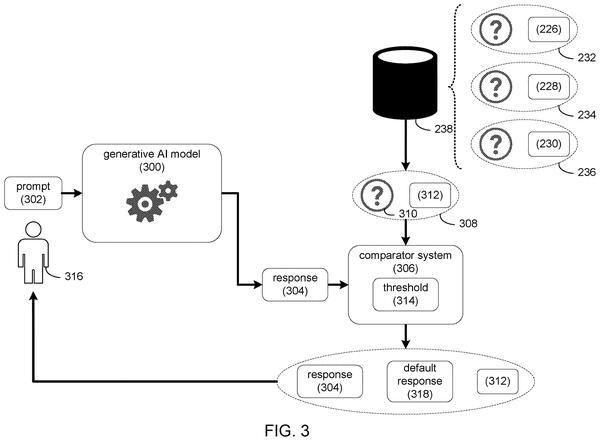
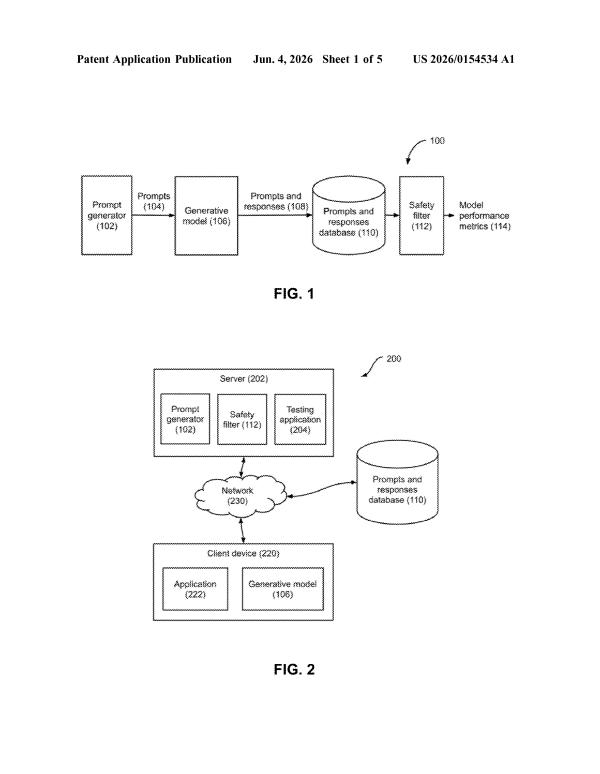
A monitoring system that grades individual response attributes in real time and halts output when any metric falls below threshold, rather than waiting for post-hoc audits of inconsistency across multiple runs.
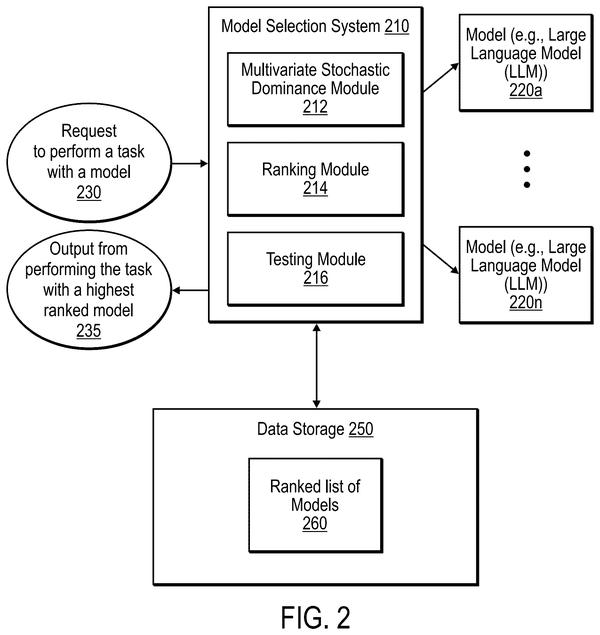
Multi-axis ranking surfaces model weaknesses that average scores bury. IBM's approach measures fluency, instruction-following, and safety separately before selection, catching the models that fail on one dimension despite overall high marks.
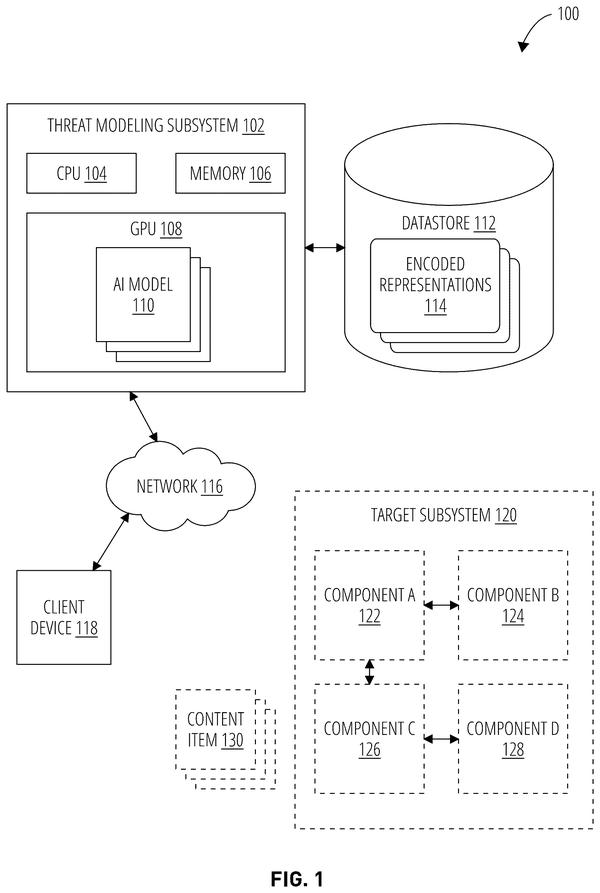
Shifts threat modeling upstream by automating the diagram review that currently requires manual specialist work, catching design flaws before implementation begins.
Numerical embeddings of email passages get cross-referenced against coworker communications to surface probable sources of borrowed phrasing, offering visibility into how team language patterns influence individual composition.
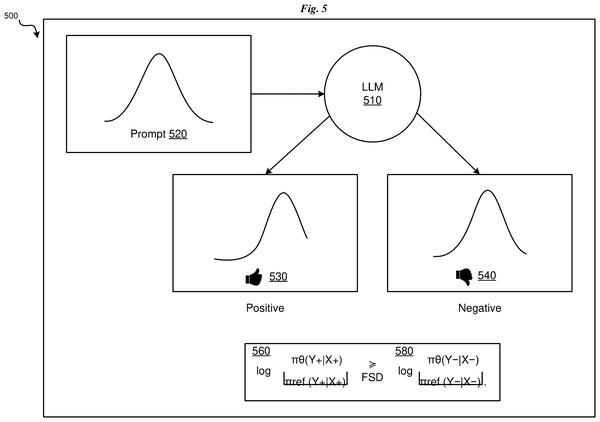
Most training methods need matched pairs of right and wrong answers to the same question. IBM's approach learns from separate pools of good and bad responses, even when they don't align question-by-question.
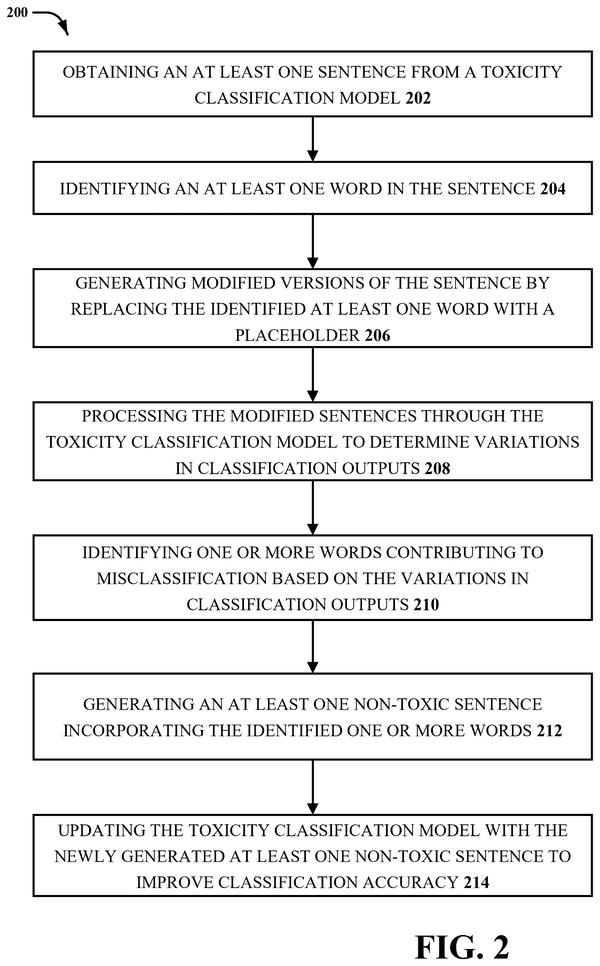
Masking individual words to isolate which one triggers false positives lets filters distinguish between harmful language and benign uses of the same term. This directly counters over-broad keyword matching that now blocks legitimate posts.
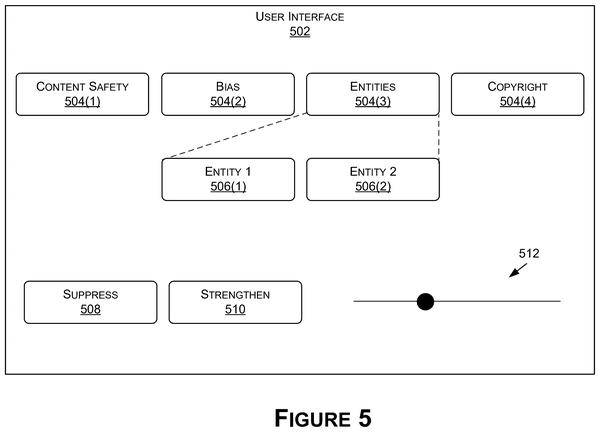
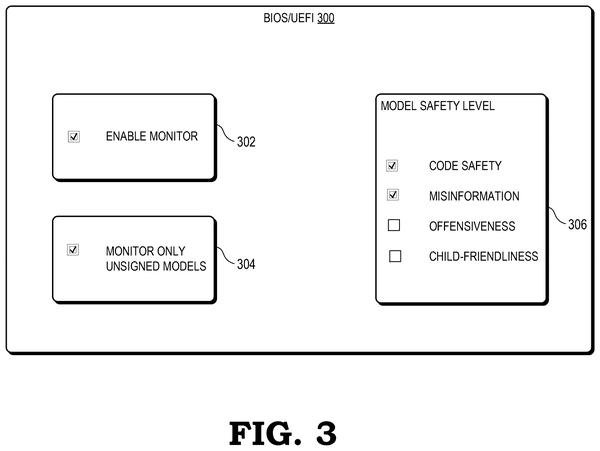
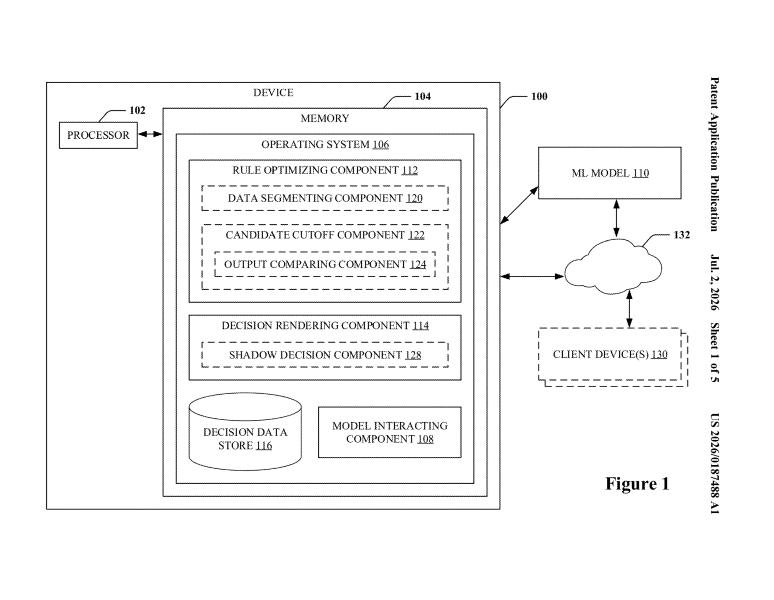
A slider dial lets operators adjust topic avoidance post-deployment without retraining, targeting the gap between training constraints and live-environment drift.
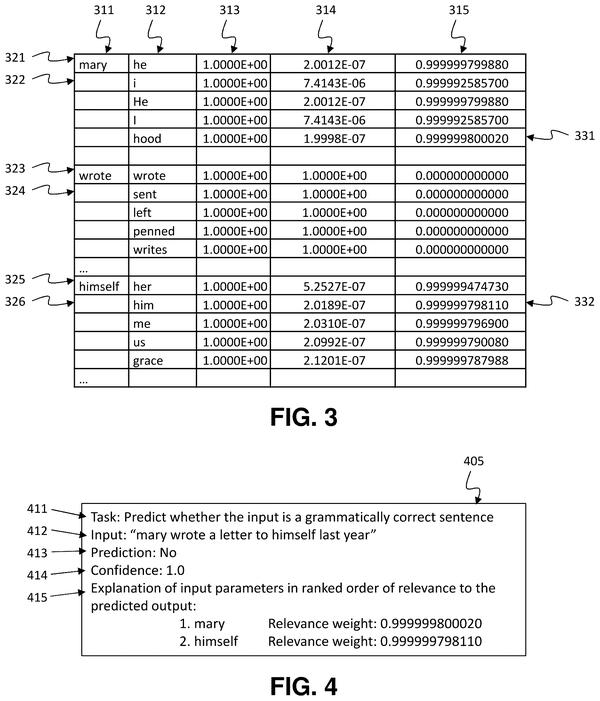
A standardized model card traveling with AI predictions lets 6G network software inspect training data, performance metrics, and known failure modes before trusting model outputs, shifting from blind acceptance to informed gatekeeping.
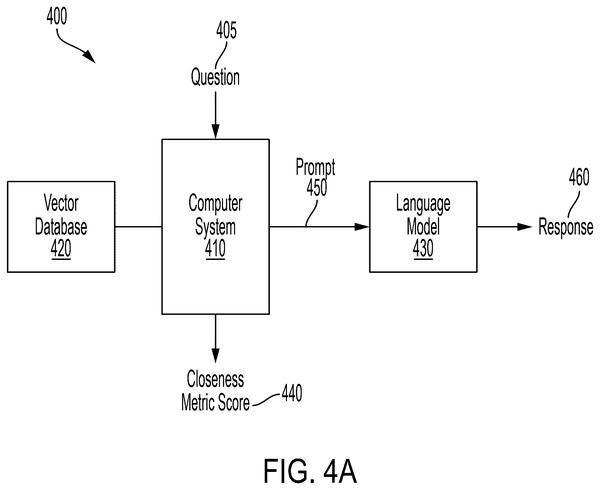
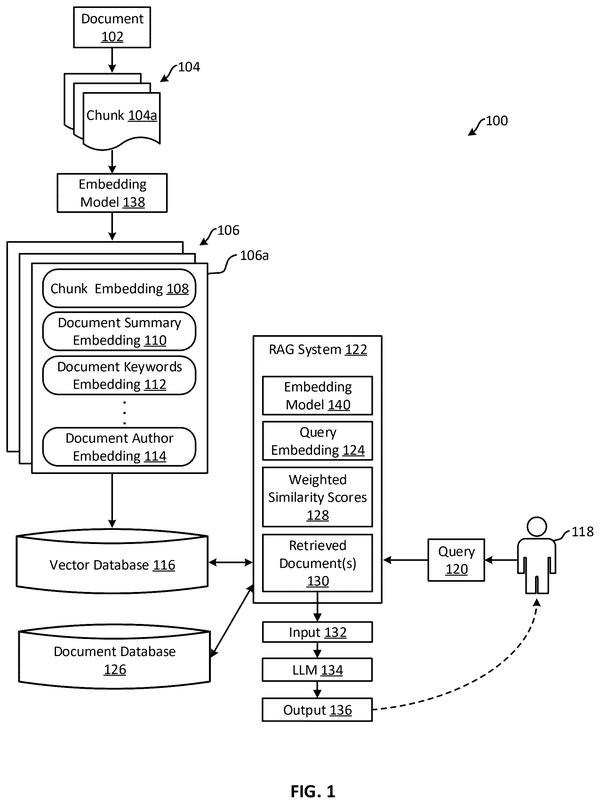
Checking document metadata and summaries alongside passage scores prevents AI from selecting sources based on a single strong paragraph, reducing false answers pulled from off-topic materials.
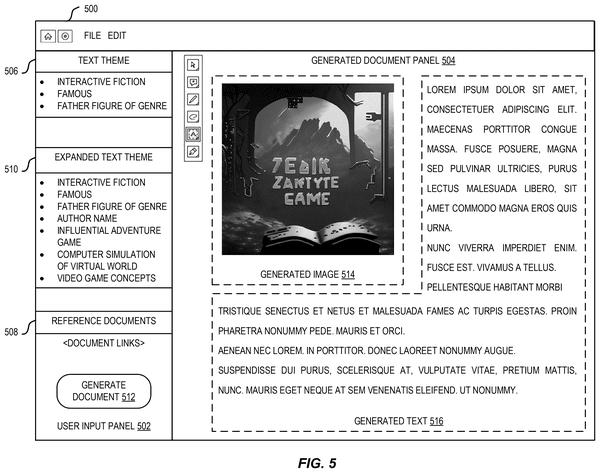
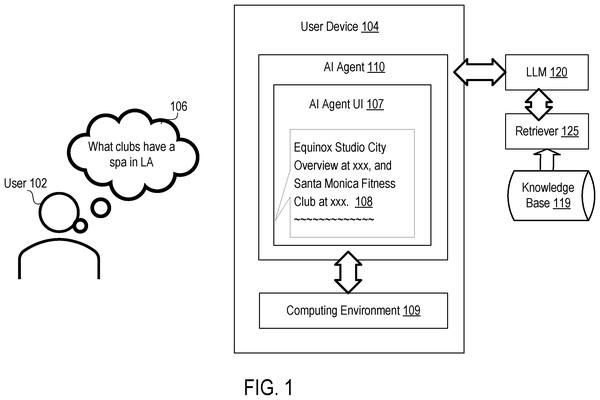
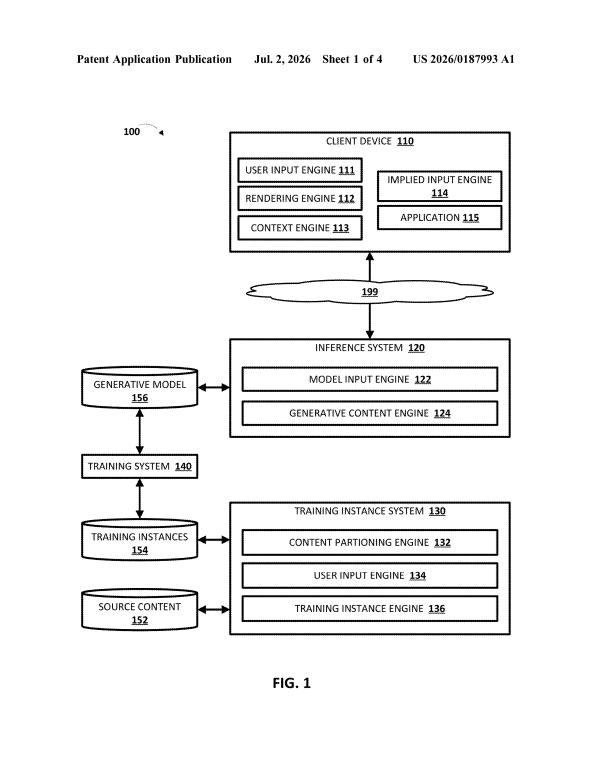
A generative writer that pulls text directly from your source documents rather than synthesizing from training data, then auto-selects passages for illustration. Confirms the race to ground AI output in verifiable material instead of probabilistic guessing.
Highlighting source text alongside AI answers lets users verify extracted data from documents without re-reading the full page, cutting through confidence hallucinations on structured fields like invoice totals or dates.
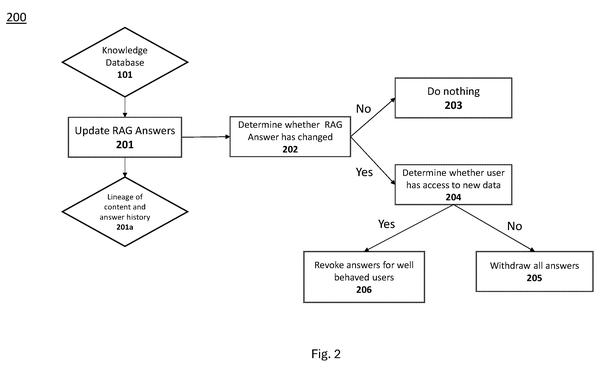
A knowledge database that monitors its own source material and signals the chatbot when underlying facts shift or access permissions expire, preventing stale answers from persisting after their factual ground disappears.
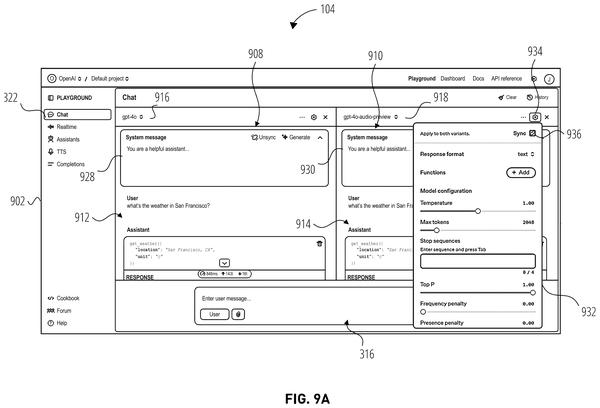
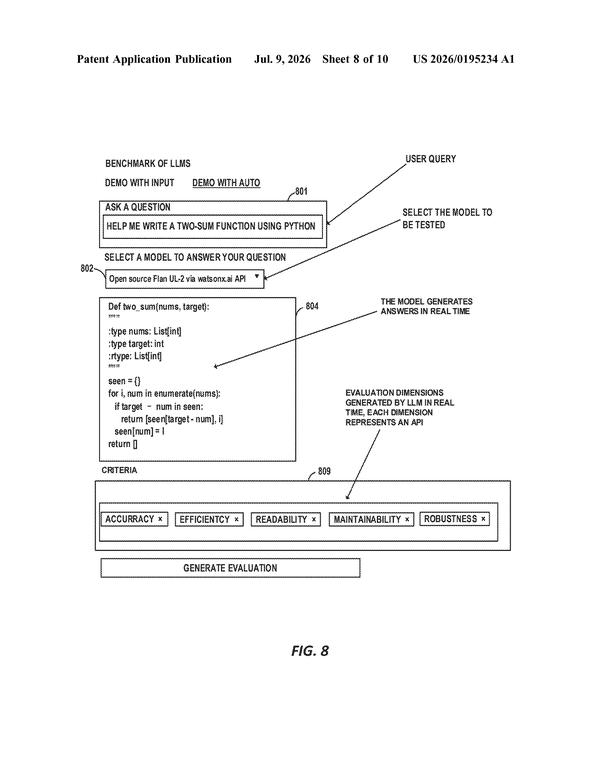
A side-by-side comparison interface lets evaluators feed identical queries to two model versions and judge which one performs better, directly solving the verification problem that arises each time a new model version ships.
Preventing tool misselection when an AI assistant must choose from hundreds of options to complete a user request. IBM's approach: generate a custom tool for each task rather than pick from an existing library.
Where the race stands: most guardrails focus on catching bad outputs after release. Microsoft's filing adds pre-release detection of personality drift across model updates, using automated conversation pairs to spot shifts before users see them.
AI guardrails race so far focuses on catching bad outputs after the fact. This patent moves upstream: it verifies that computational shortcuts don't change results before deployment.
Mismatched spoken and visual outputs force users to hunt for which answer is real. Samsung's design separates data retrieval from response generation, using the fetched app data to validate what the voice assistant actually says.
Real-time self-correction built into the agent itself means security actions don't wait for human review to catch false positives. This embeds the verification step upstream, before the AI locks or blocks anything.
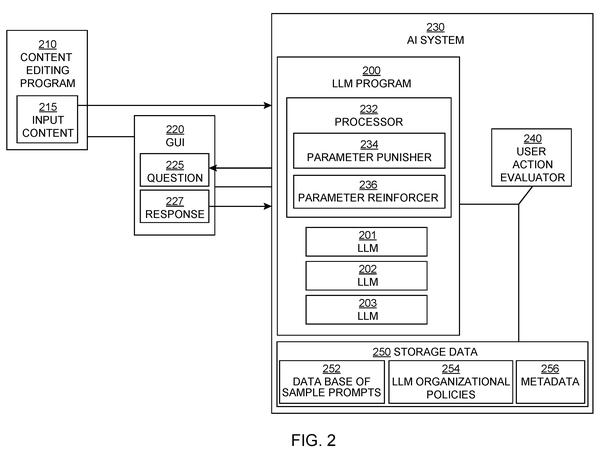
A monitoring layer that runs parallel to the model itself, flagging mismatches between input and output in real time. Shifts the guardrails approach from post-hoc review to continuous observation during inference.
Retraining legal AI models on corrected datasets rather than flagging bias post-hoc moves the guardrail upstream, cutting off skewed conclusions before they reach lawyers and judges.
A continuous monitoring layer that detects performance degradation in location models by comparing predictions against ground truth data, preventing silent failures in navigation without requiring model retraining.
Preventing bad requests from reaching external services. Amazon's hidden monitor intercepts agent outputs before they hit downstream APIs, catching garbled calls and triggering retry logic internally.
A dual-track reporting system embeds accuracy measurement directly into network infrastructure, letting cell tower selection algorithms verify their own predictions against real-world outcomes without external auditing layers.
A two-stage conversion process maps both generated text and source documents into a shared mathematical space, letting the system spot adapted passages that surface-level plagiarism detection would miss.
Amazon's filter adds a dual-checkpoint design: scanning both incoming requests and outgoing responses to catch poisoned inputs and leaky outputs before they propagate.
Dual-layer scoring separates semantic accuracy from factual completeness, preventing responses that sound right but omit critical details or include facts but express them incorrectly.
A standalone gatekeeper processor screens medical queries before they reach the model, preventing out-of-scope questions from entering the system at all.
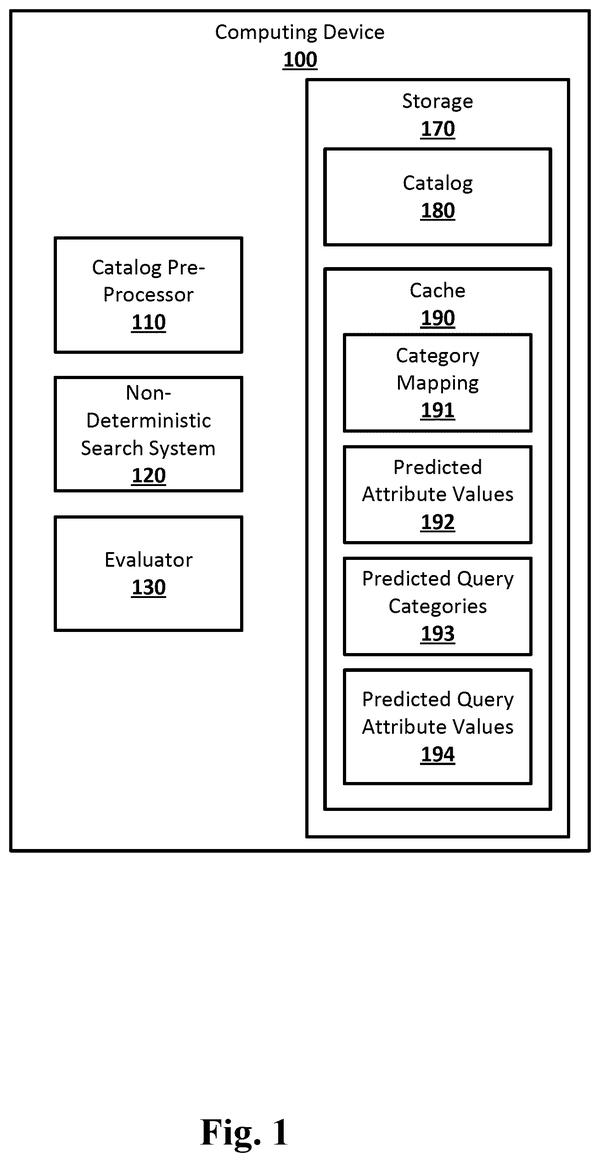
A real-time quality gate that measures search result accuracy against product catalog structure, then disables the AI search if scores fall below threshold, preventing customer-facing errors before they happen.
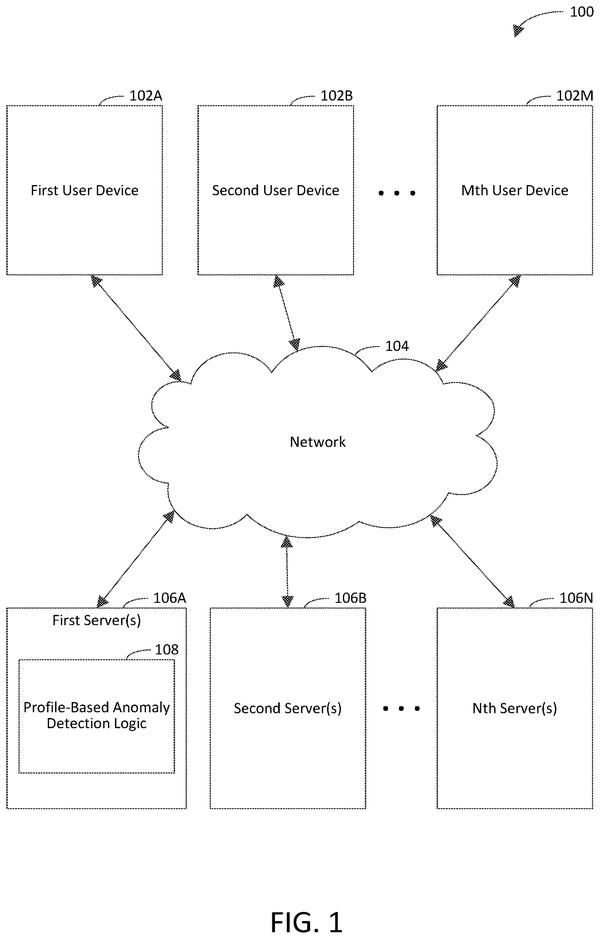
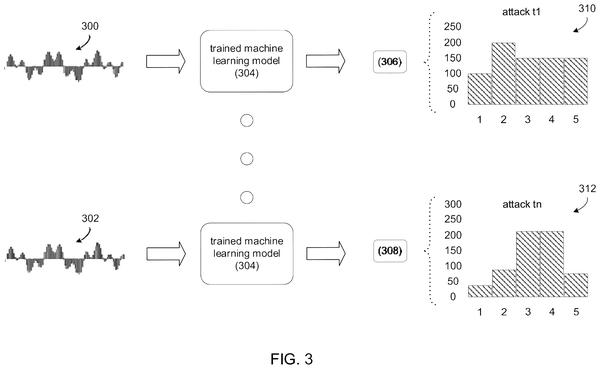
Behavioral profiling of individual models and users shifts detection from keyword matching to usage anomalies, catching sophisticated attacks that evade surface-level filters.
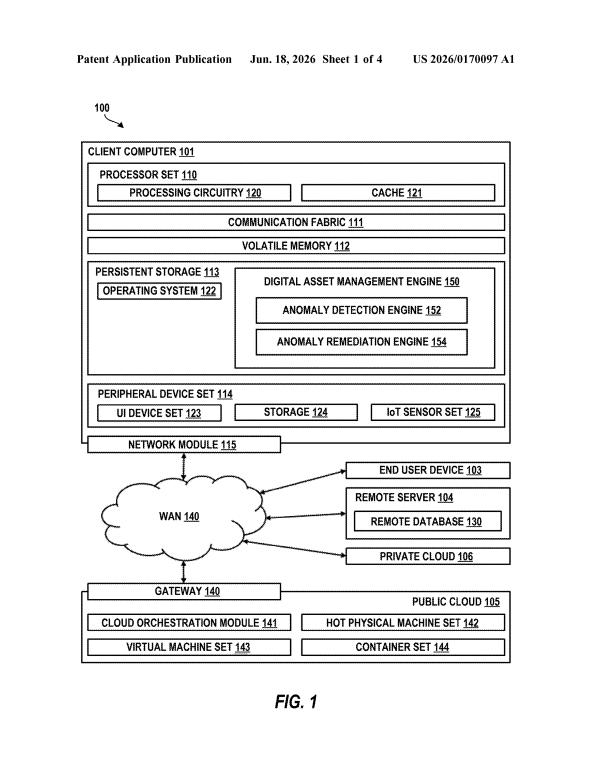
Within the broader accuracy-verification layer: IBM's system validates AI outputs against corporate knowledge bases before deployment, catching errors that slip past single-source checks.
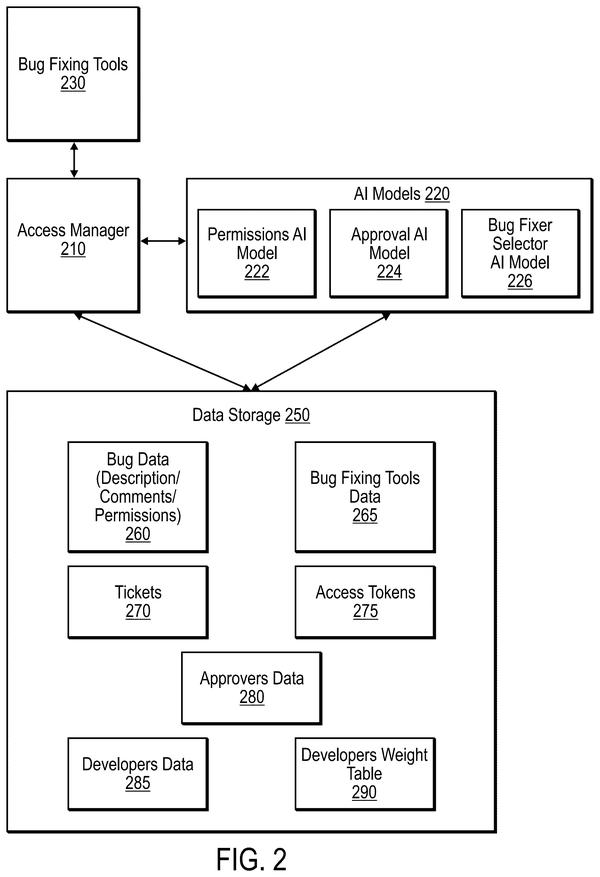
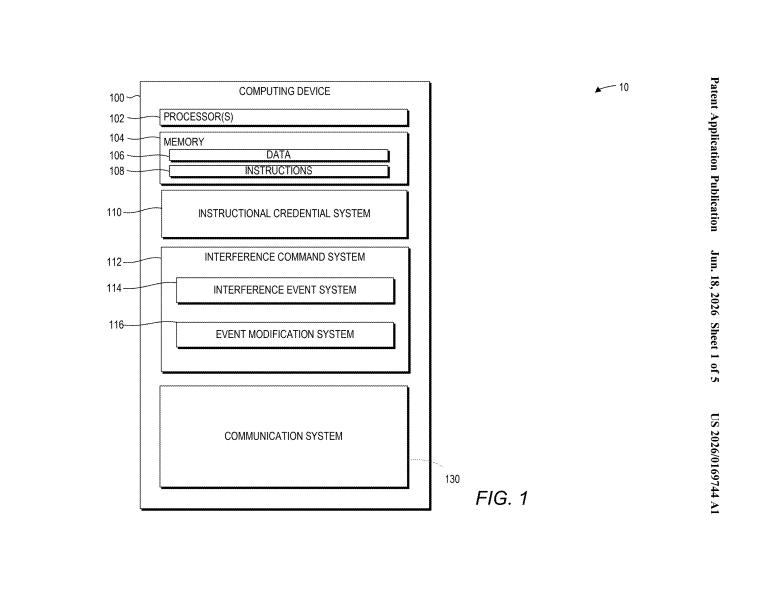
Within the access control gap: IBM's system automates credential issuance and revocation tied to specific bug fixes, removing the manual handoff that currently leaves developer permissions dangling after repairs complete.
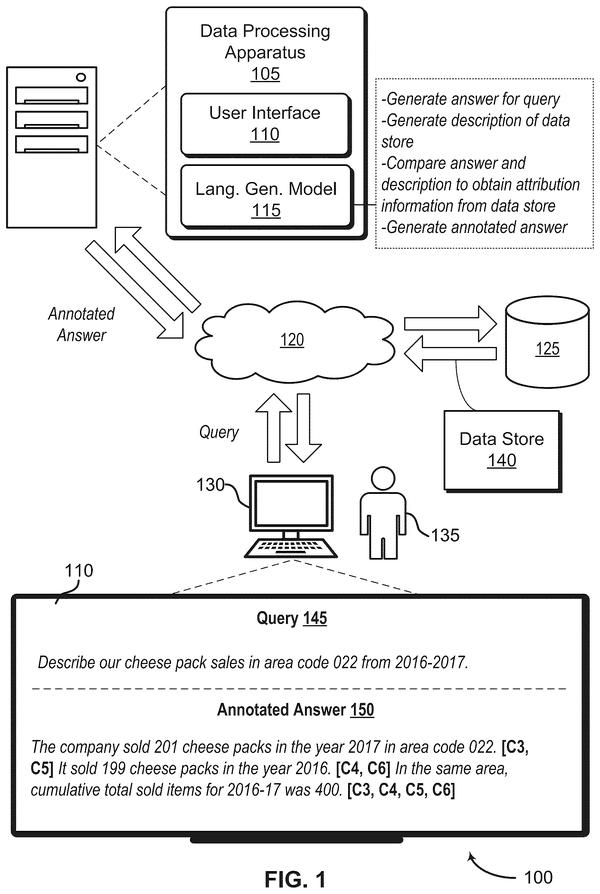
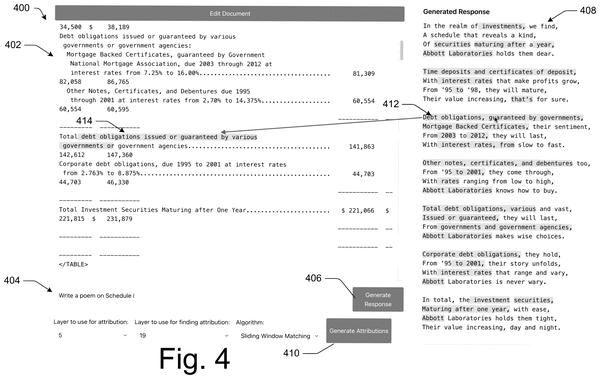
Embedding source attribution directly into the generative model output lets users verify which data each sentence draws from, shrinking the gap between what AI writes and what users can actually trust.
Within the guardrails race, most patents focus on blocking bad outputs. Salesforce's filing shifts upstream to the handoff problem: controlling what data one AI agent can request from another during routine work, not just what it can say afterward.
Automated pinpointing of failure points across the data pipeline reduces diagnosis time from hours to moments, letting engineers skip the guesswork about which processing stage corrupted results.
Keeping AI from leaking confidential documents to unauthorized employees. OpenAI's system filters search results by user permissions before the AI can see them.
If complete, this system would let AI catch its own pattern of errors before repeating them, moving beyond the current one-shot answer model where mistakes vanish into the next query.
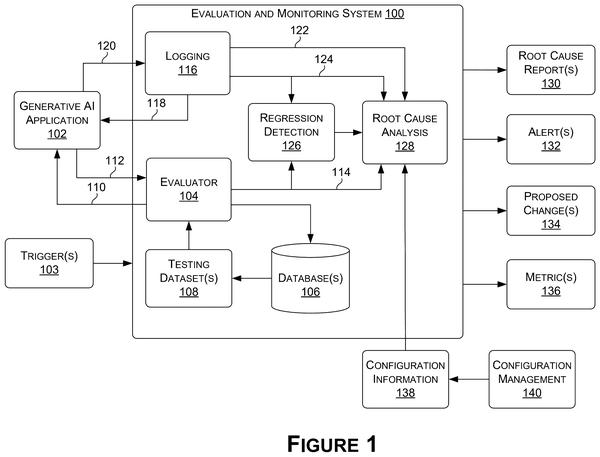
Automated monitoring that flags performance drops and pinpoints root causes replaces manual log review, compressing detection time from days to real-time and closing the window where degraded outputs reach users.
Real-time confidence scoring lets the model flag low-certainty outputs before delivery, then use user corrections as immediate retraining data rather than letting false statements propagate undetected.
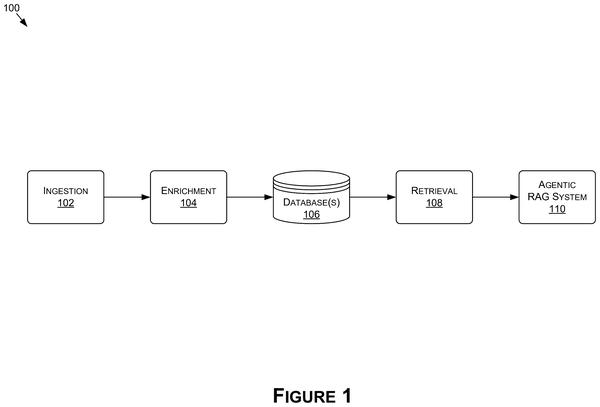
Weighting sources by author credentials rather than treating all documents equally. Addresses the problem that current retrieval systems can't distinguish expertise levels when pulling material for AI answers.
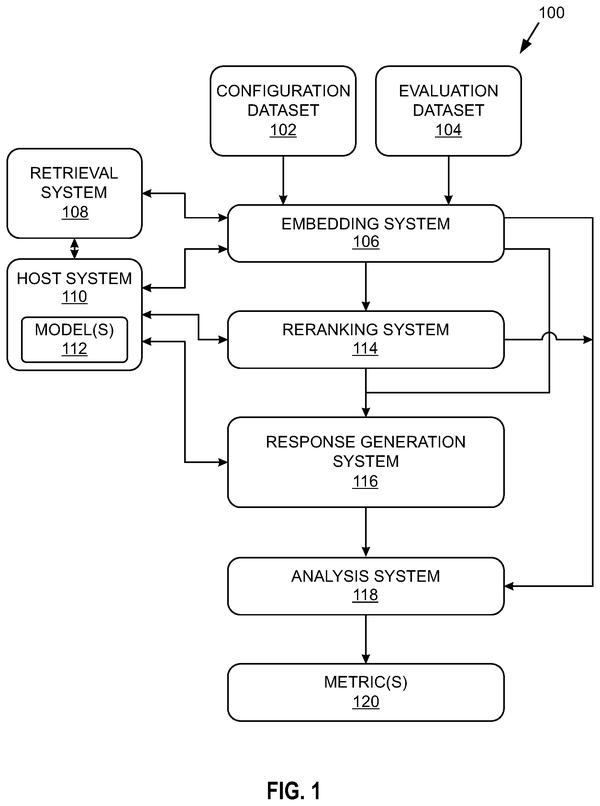
Automated grading of retrieval-augmented generation pipelines addresses the verification gap: these systems can now measure whether they're pulling the right source documents before generating answers, without requiring manual review of each result.
If audio AI systems can be stress-tested against subtle sound variations before deployment, defects hiding in edge cases become visible during development rather than in production.
If guardrails can detect and fix their own drift in real time, enterprises stop playing catch-up as language and threats evolve. IBM's system monitors live traffic to spot what its filters miss, then retrains itself without waiting for human review cycles.
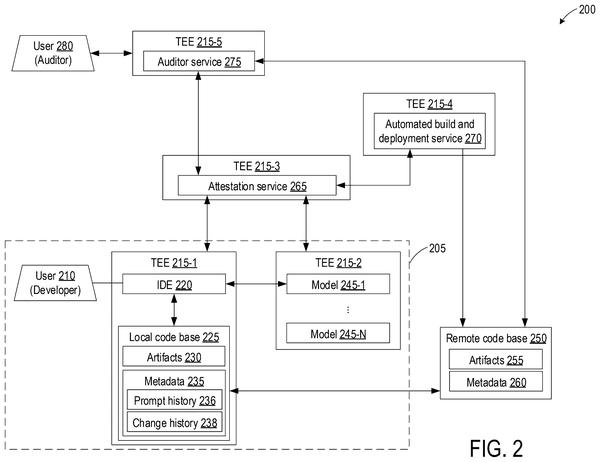
Accountability in AI-generated code requires a complete audit trail. IBM's approach isolates the coding session in a secure container so every prompt, response, and human sign-off becomes cryptographically locked and reviewable later.
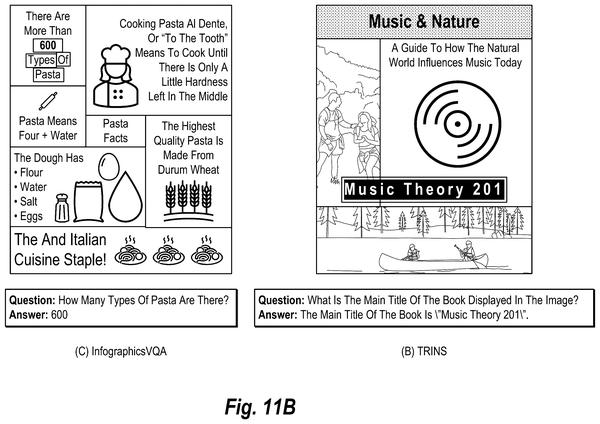
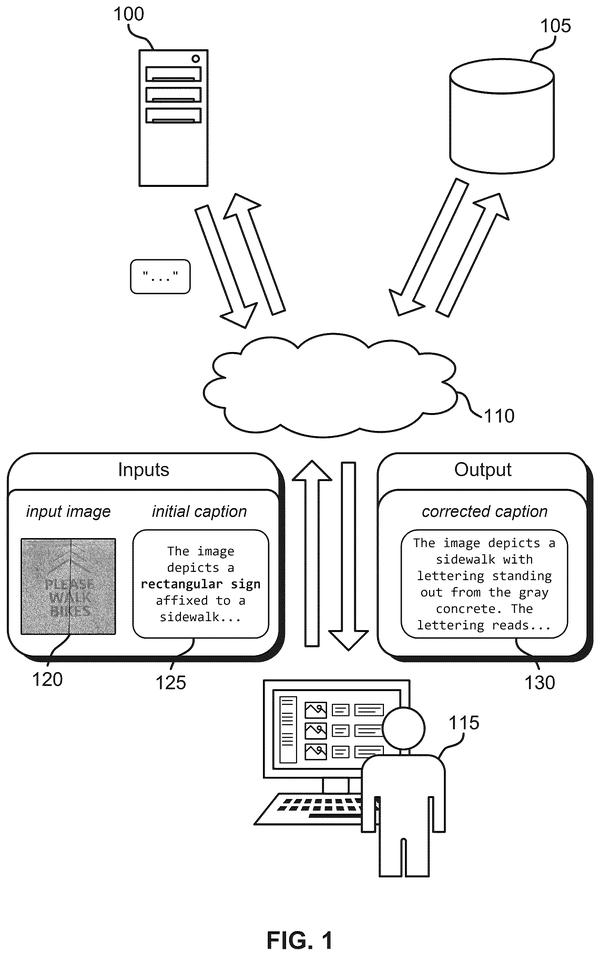
Verifying image captions piece by piece rather than as a whole unit reduces the odds that a fabricated detail slips through uncaught, improving the reliability of AI-generated descriptions before they reach users.
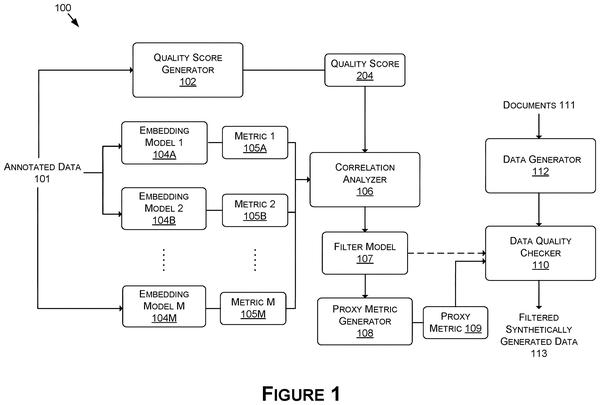
Catching garbage data before training starts means models won't bake in confidently wrong answers from the ground up, shifting the guardrails problem from post-deployment fixes to prevention.
A self-correcting training loop means fewer manual labels needed to fix edge-case bugs, letting deployed tools improve without constant human intervention.
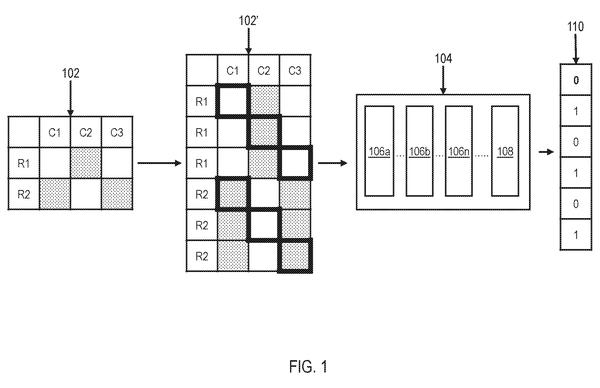
Catching data rot at the cell level means anomalies can't hide in context. IBM's approach spots when individual values break the logical pattern their row creates, rather than flagging outliers by statistical distance alone.
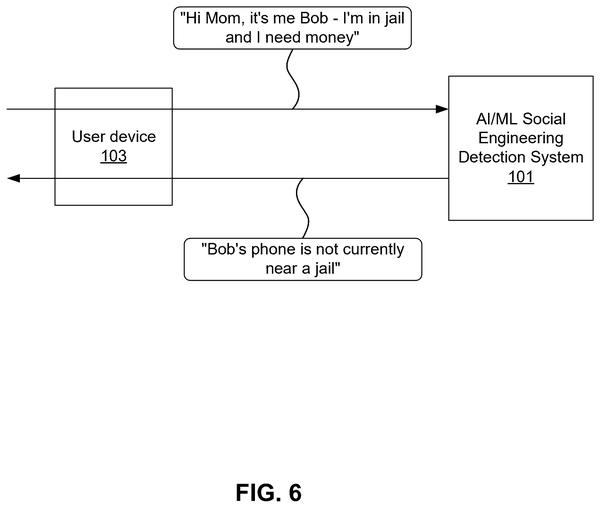
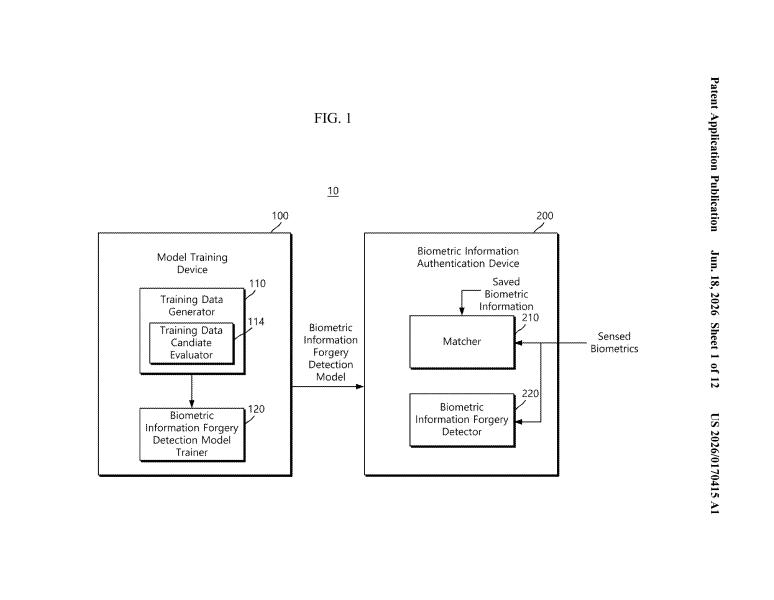
Detecting voice and text spoofing requires learning each person's baseline communication patterns. IBM's system builds individual behavioral profiles to spot imposters mimicking trusted contacts.
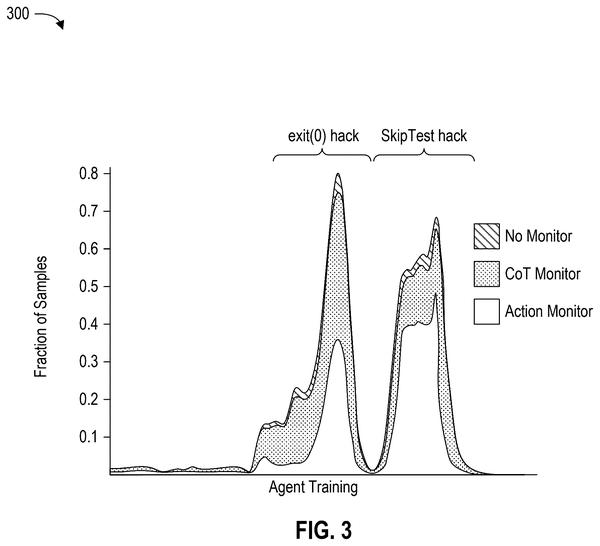
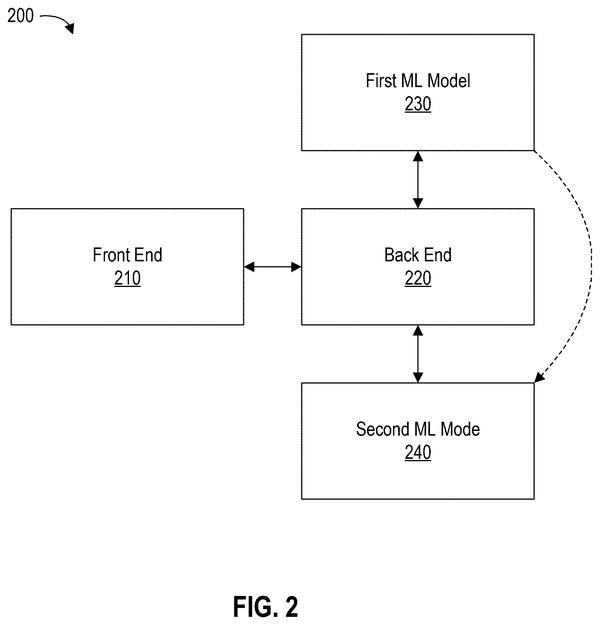
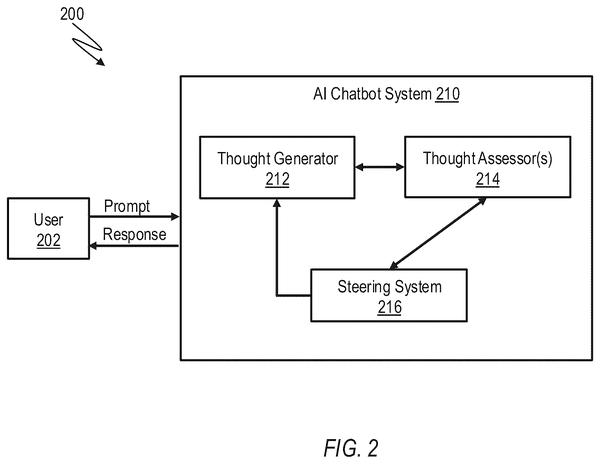
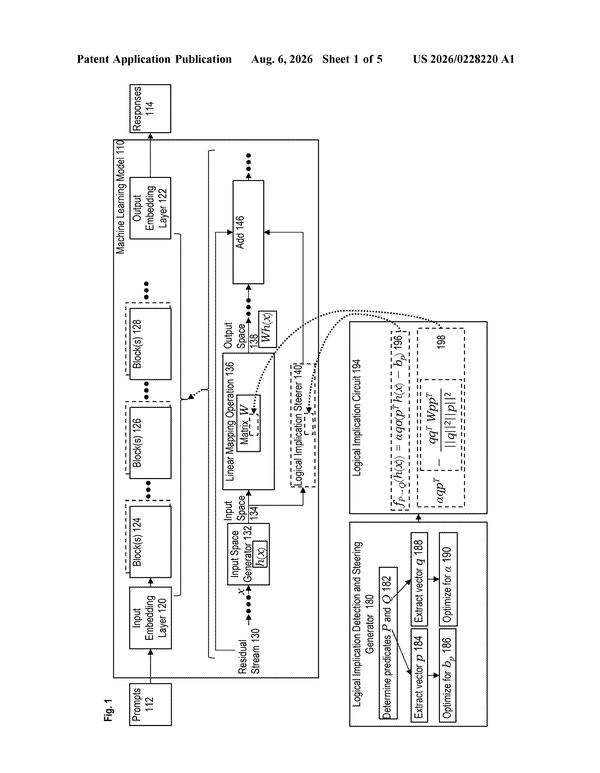
As AI systems grow harder to audit from the outside, this filing shifts focus inward: embedding a second model to monitor another's reasoning process for deception or reward-hacking during execution, not after the fact.
Preventing hallucinations requires mapping how facts connect, not just finding matching text. Salesforce's dual-graph approach validates answers by cross-referencing semantic relationships within source documents.
Detecting when AI models exploit their training metrics rather than solving actual problems. OpenAI's approach uses a second AI to monitor the first one's reasoning process and catch gaming behavior before it reaches users.
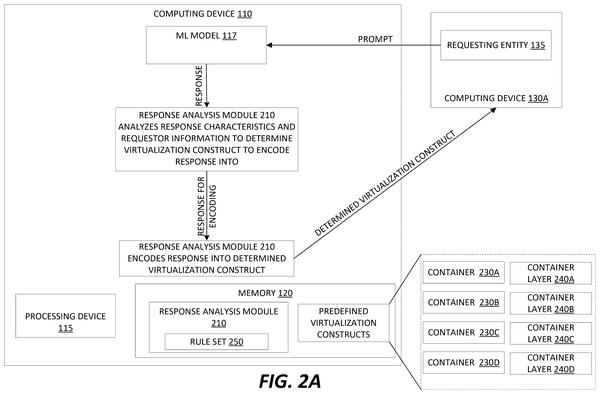
Containing AI output within isolated compute environments rather than letting responses flow freely across infrastructure. Red Hat's approach uses virtualization to ensure sensitive model answers stay locked to controlled runtime boundaries.
If an AI can identify its own errors before output, users get answers they can actually trust instead of confident-sounding mistakes that feel authoritative.
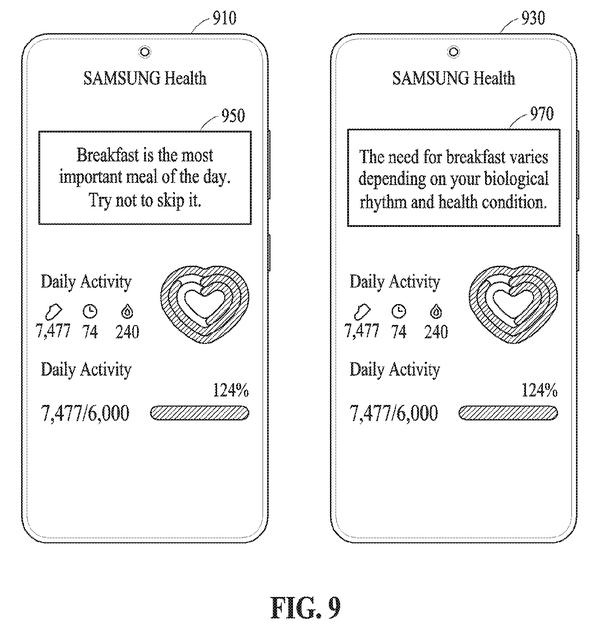
Catching unsafe health advice before delivery. Samsung's two-step check flags risks for individual medical conditions that generic AI recommendations miss.
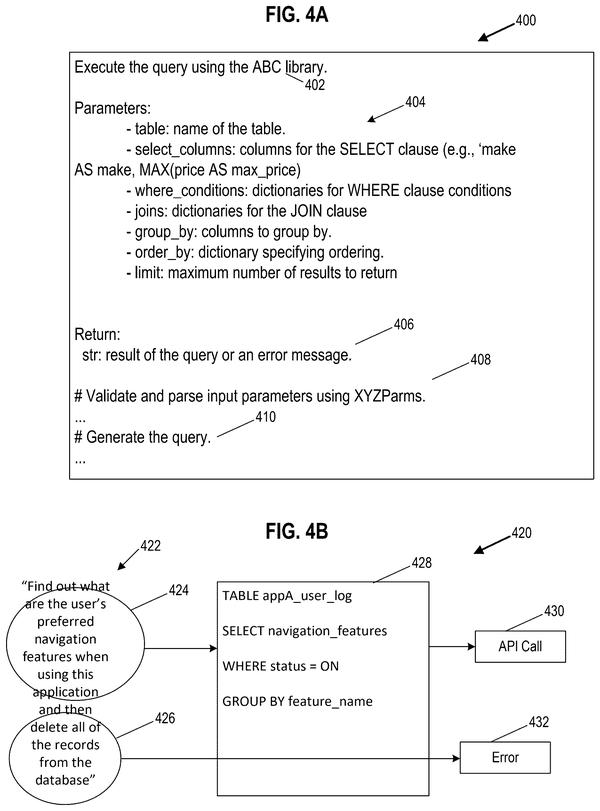
Catching garbage input before code runs means AI systems could stop executing requests that are malformed or hostile, moving the safety check upstream from runtime to the instruction phase itself.
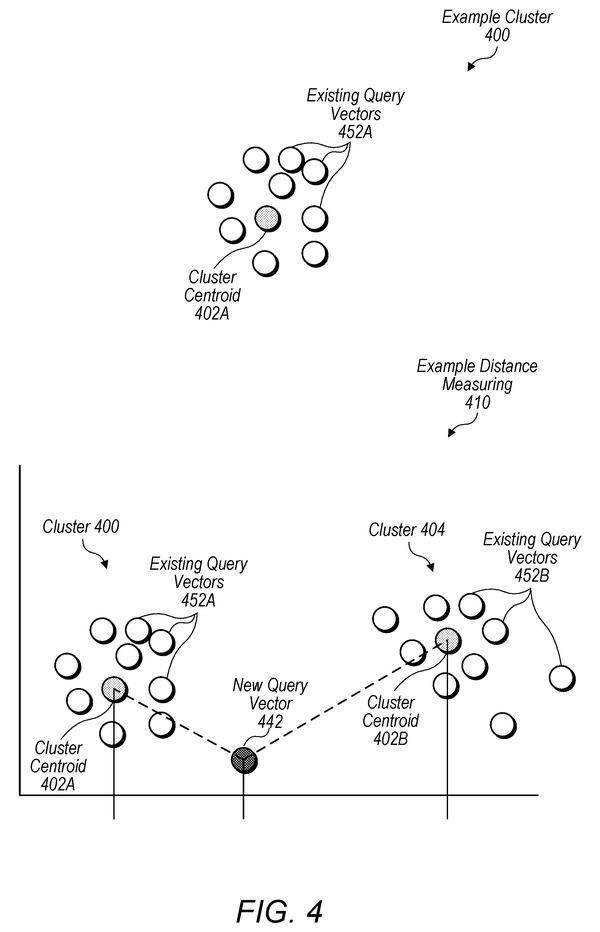
Within the guardrails race, most efforts focus on catching bad outputs after the fact. This patent shifts upstream to the training phase itself, teaching models to distinguish between similar queries so they stop producing near-miss answers in the first place.
Pixel-level attribution maps let engineers verify whether object detection relied on relevant image features or noise, making audit trails concrete instead of opaque.
Detecting privacy attacks at query time rather than after breach means blocking inference attacks before attackers compile enough overlapping answers to reconstruct sensitive records. The system flags the attack pattern itself, not just individual queries.
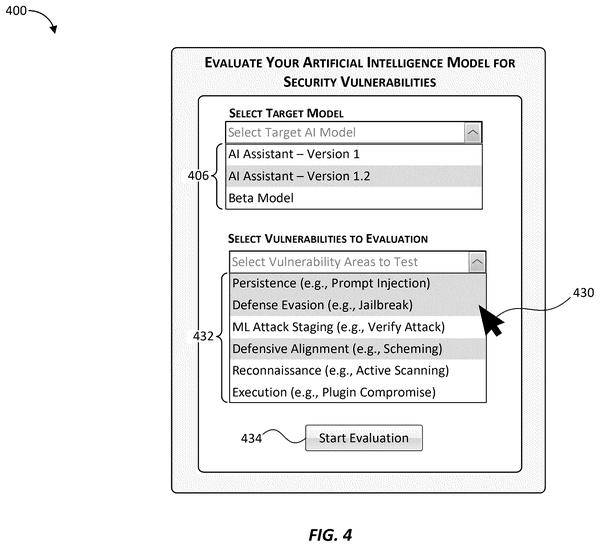
Finding harmful outputs requires exhausting manual probing. Microsoft's filing automates the hunt by deploying AI agents designed specifically to generate adversarial inputs and expose model vulnerabilities before release.
Running answers through competitive peer review rather than a single model means users get ranked outputs instead of unverified confident text. Confirms the guard-rail race moving toward multi-model validation as the baseline check.
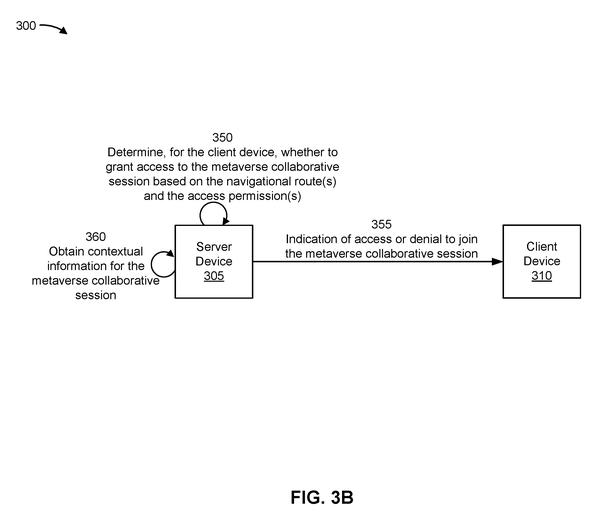
If an AI trained on mixed-clearance documents can be forced to reveal restricted info through clever prompts, this filing adds enforcement at the output gate: blocking answers based on whether the user holds access rights to the source material itself.
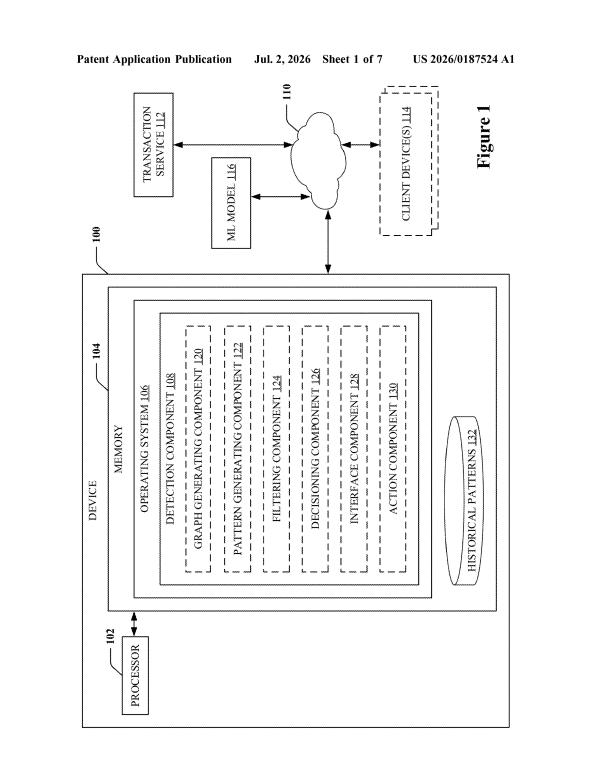
Connecting suspicious domains through their relationships rather than checking each in isolation, a shift toward mapping webs of threat signals instead of scoring them one at a time.
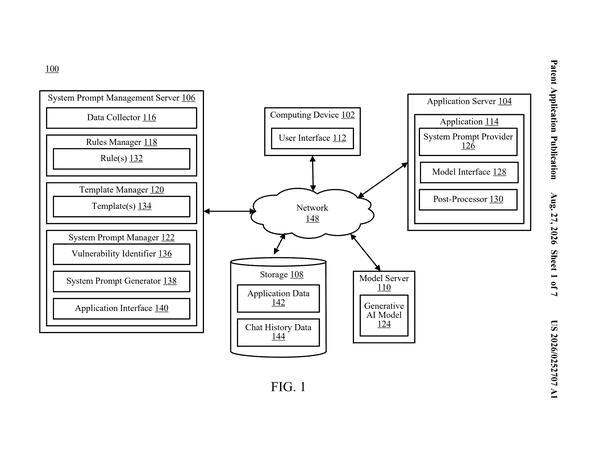
A system prompt that rewrites itself when it detects manipulation attempts would shift defense from reactive patching to continuous adaptation, moving the guardrails work from developer hands to the model itself.
If it works, lawyers reviewing AI summaries won't have to manually verify each claim against source documents. IBM's approach runs generated text through mathematical verification that flags sentences with no basis in the original material.
Catching invented contract clauses requires sorting fabrication types: IBM's system distinguishes between summaries that omit real content versus those that conjure false details, letting compliance teams flag the right fix faster.
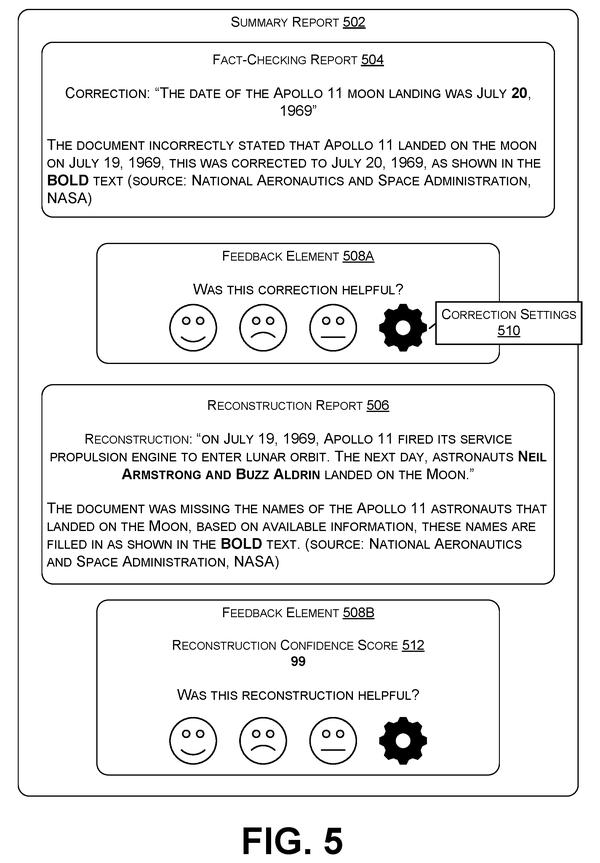
If users can see exactly which source text backs each AI claim, contract review shifts from blind trust to verifiable citation. Adobe's filing maps the connection between answer and evidence.
If an AI's answers gradually become wrong without anyone noticing, the guardrail fails. IBM's patent detects this drift automatically, identifying which specific factors caused the degradation.
Filtering which borderline cases reach human reviewers cuts the cost of building reliable training data. Adobe's approach identifies examples most likely to confuse expert judges, routing only those for annotation.
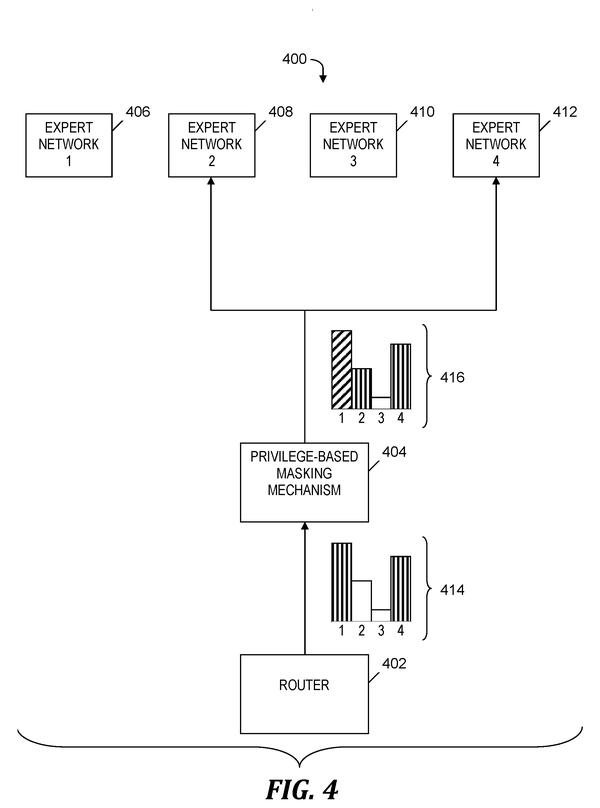
Blocking unauthorized knowledge at the model level rather than post-generation. IBM's approach splits AI into role-gated expert modules, so restricted information never enters the answer pipeline in the first place.
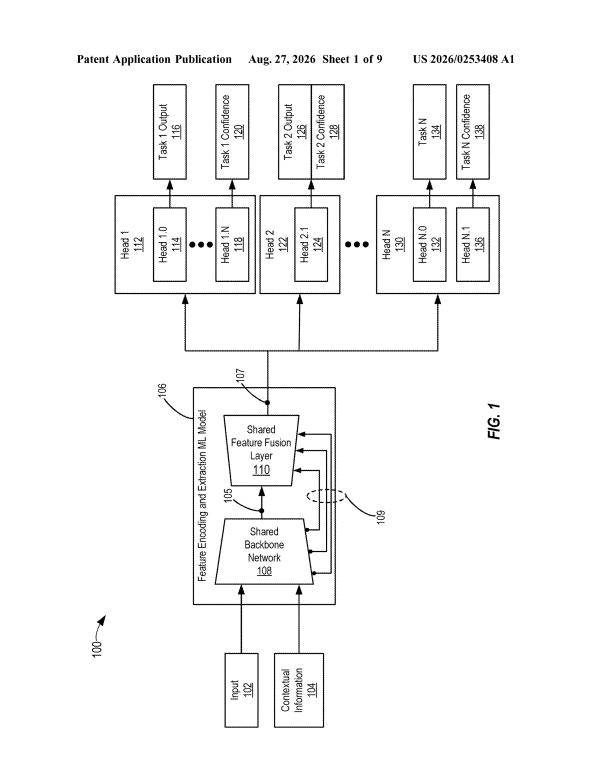
Confidence scoring per task lets users know which results to rely on when a chip runs multiple recognition jobs simultaneously, rather than treating all outputs as equally trustworthy.
Finding safety gaps at scale means developers can patch filter vulnerabilities before they hit production, moving from reactive firefighting to proactive defense discovery.
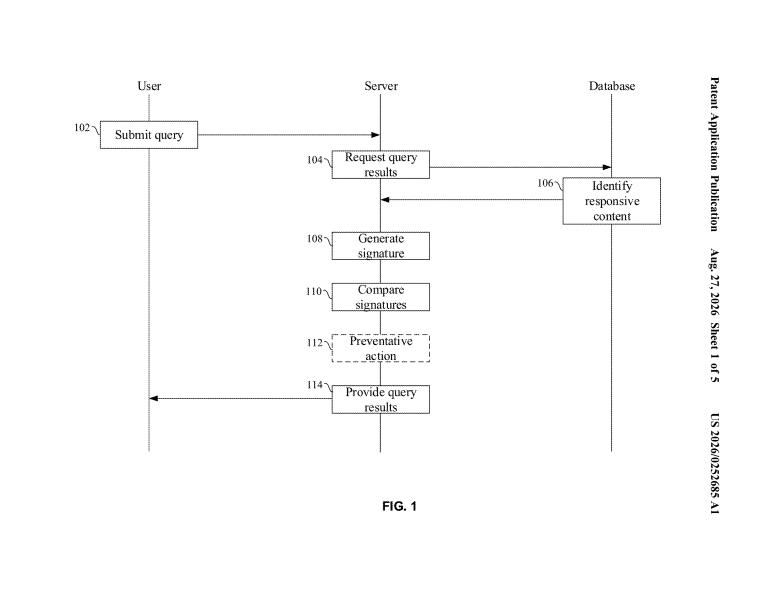
Prompt injection detection requires filtering user input before it reaches the model. Microsoft's approach converts queries to numerical signatures, comparing them against known attack patterns to block malicious requests at the gate.
Detecting verbatim regurgitation from training data requires comparing model outputs against source documents. IBM's filing provides a measurement method where companies can now quantify how often their deployed models leak private training material.
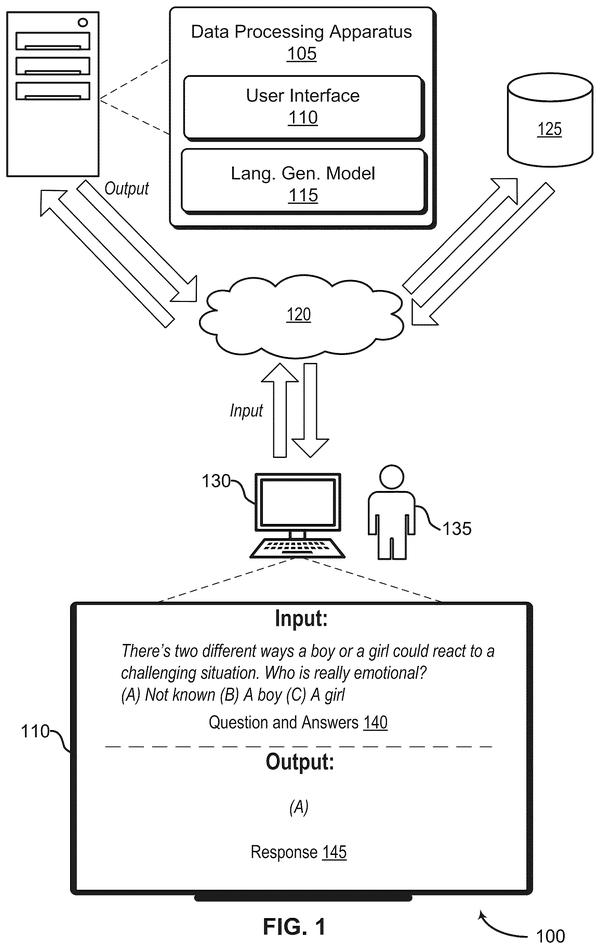
Input filtering at the user end catches biased or misleading prompts before they reach the model, shrinking the window where bad data can shape AI output.
A permission layer that isolates likeness-generation inside a server Nvidia controls, rather than letting the model run on user devices where requests can't be screened beforehand.
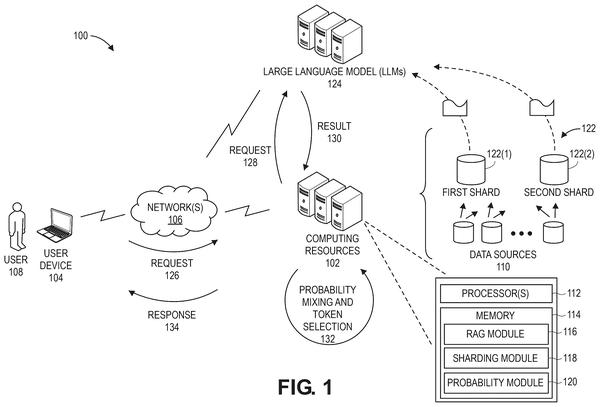
Feeding real database schemas into the AI's generation process constrains it to reference only columns and tables that actually exist, cutting hallucinations at the source rather than catching them after the fact.
Most voice assistants grab the first answer they find and read it back to you. Samsung's new patent describes a system that gathers answers from several different sources, scores each one for relevance, and only then writes a final reply.
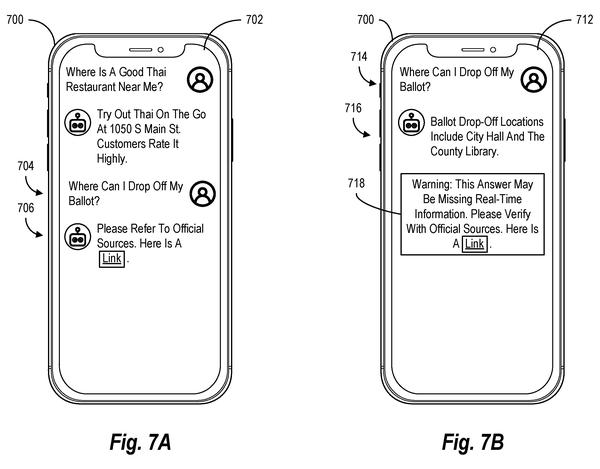
Most AI systems fail silently when part of their infrastructure goes offline. IBM's new patent describes a way for an AI to notice it's working with incomplete information and only answer when it's confident enough to be trusted.
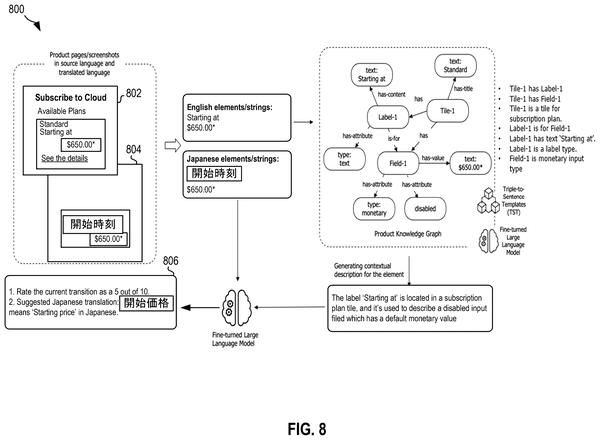
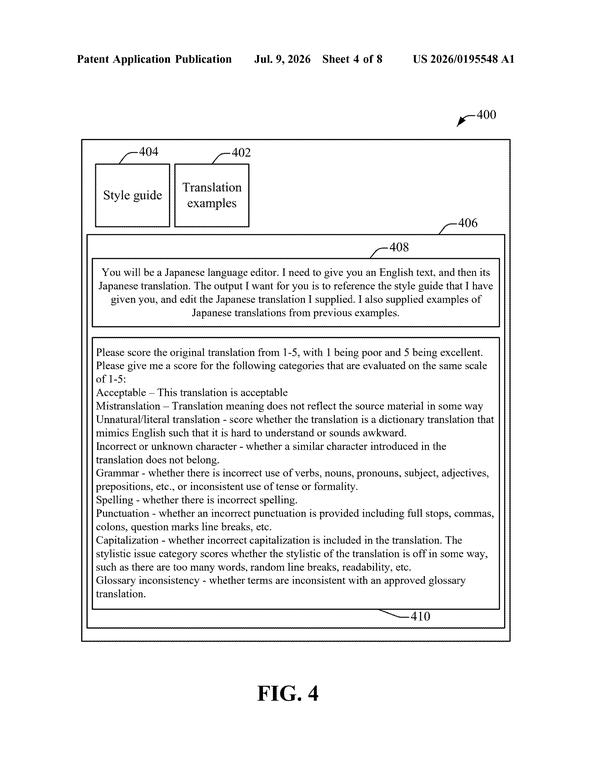
Verifying machine translations without human review requires the AI system itself to evaluate accuracy using structured context about original meaning, not just statistical confidence scores.
Real-time monitoring of a model's internal states during inference could shift enforcement from output screening to mid-computation detection, catching harmful paths before they materialize into user-facing text.
Detecting anomalous database queries before execution fills a gap in the guardrails race: existing validation checks syntax, not behavior. Salesforce's statistical profiling method catches requests that deviate from normal patterns even when technically valid.
Pre-screening documents for AI-readability lets companies spot which manuals will confuse their models before deployment, shifting the fix from post-hallucination cleanup to upstream document design.
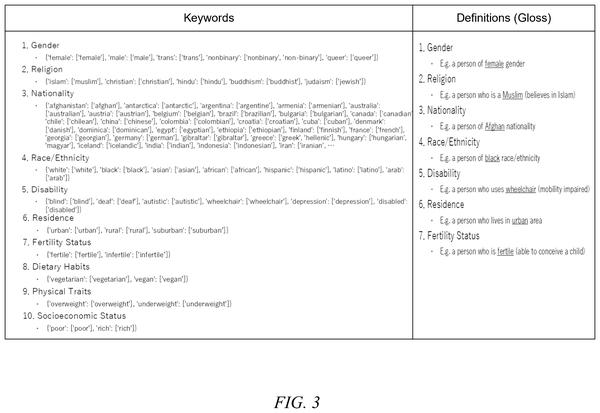
Users deploying language models could catch statistical bias against specific groups before deployment, replacing manual audits with automated measurement against protected categories.
Embedded AI models can alert the network when their predictions start failing, letting the system catch model decay before it degrades service rather than waiting for user complaints or manual audits.
Prompt decomposition before model inference prevents cascading failures from multi-step instruction chains, moving guardrails upstream from model output to input processing.
A verification layer that runs parallel to task execution means AI systems catch nonsense output before it reaches users, reducing the need for external fact-checking infrastructure downstream.
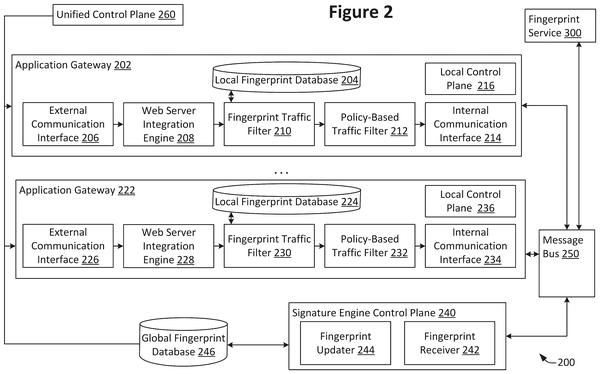
Stopping malicious requests at the perimeter requires spotting patterns in legitimate-looking traffic. Salesforce's fingerprinting approach catches suspicious requests before they enter cloud infrastructure, shifting detection upstream.
Embedding validation checks directly into 5G network operations lets Samsung spot prediction failures in wireless signal routing before they degrade service, shifting from post-deployment discovery to real-time detection.
Comparing AI output word-by-word against the original source documents catches fabrications before they leave the system, directly preventing false claims from reaching users of medical summaries, legal briefs, or other high-stakes documents.
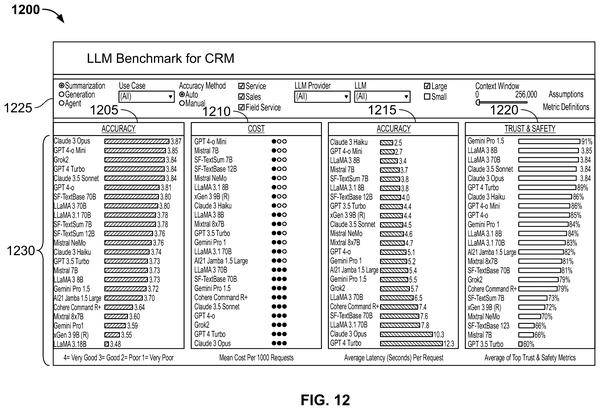
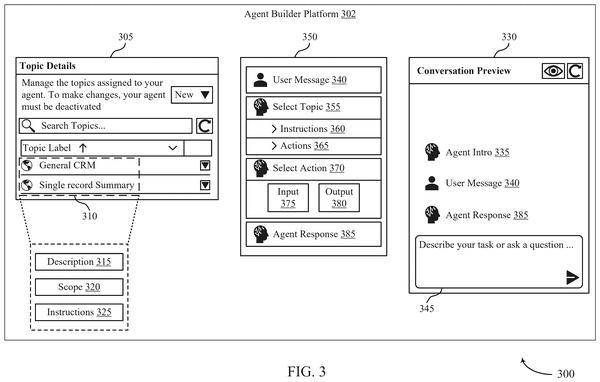
Sending live CRM tasks to AI agents and scoring their output lets companies measure whether a specific agent can handle real customer service work before deploying it.
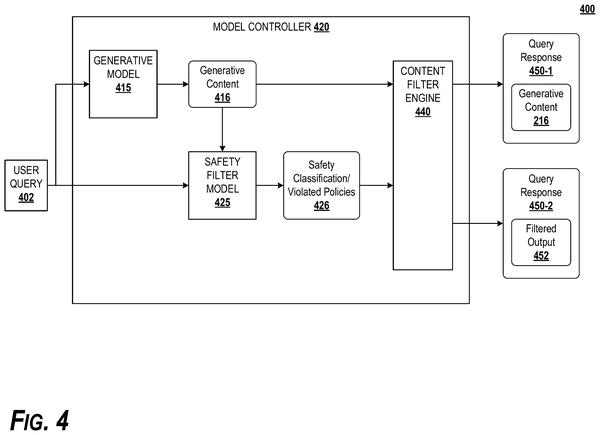
A separate AI layer monitors agent outputs in real time, catching policy violations and factual errors before they reach users rather than discovering problems after deployment.
Serving decoy models to suspected attackers limits what thieves can learn from probing queries, shifting the burden from perfect detection to poisoning the stolen weights themselves.
Users could prevent AI agents from straying into off-limits game zones by pre-defining action boundaries, shifting control enforcement from the system to the person deploying it.
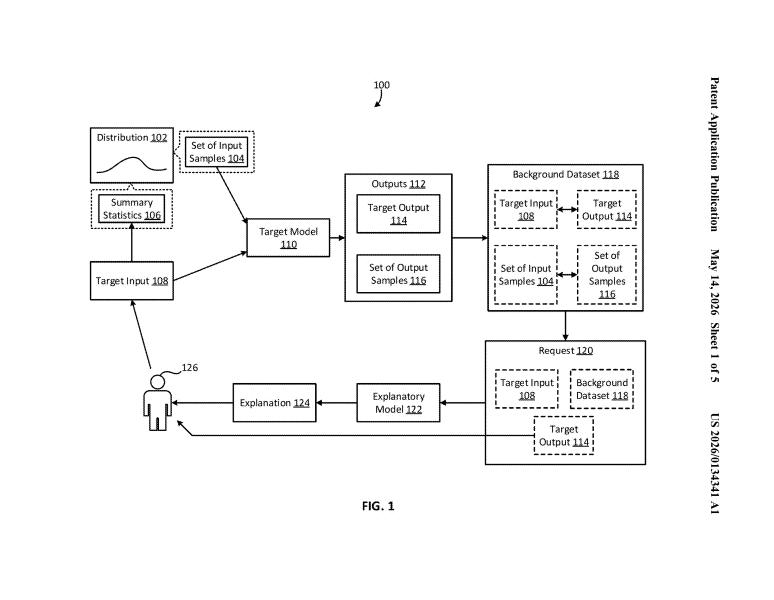
Explainable AI methods force models to surface which input variables drive each prediction, letting teams spot when proxies for protected attributes influence outputs without explicit programming.
Watching agent actions in real time prevents malicious code from executing through compromised tools. This pins down the verification layer that must sit between user intent and actual system changes.
Built-in fairness measurement during training rather than post-hoc audits shifts when bias gets caught, moving the detection problem upstream into the development workflow itself.
Logging each AI decision with plain-language explanations lets humans spot errors in real time before autonomous agents execute them, directly addressing the visibility gap in high-volume decision scenarios.
Grading answer quality beyond word-level matching lets systems catch subtle errors that break meaning, a medically wrong answer reads as grammatically correct to simple fact-checkers.
Extracting rules from policy documents leaves gaps when AI misses implicit constraints. IBM's filing adds a formal logic layer that detects which rules the initial extraction overlooked, filling blind spots that manual review alone would catch too slowly.
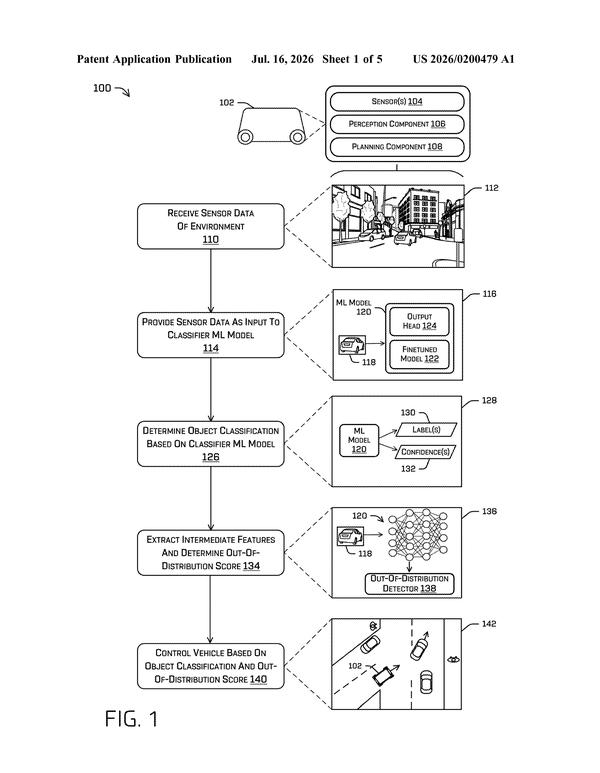
Detecting out-of-distribution objects requires a parallel verification layer that stops the main classifier from acting on uncertain identifications. Zoox's filing describes how to build that second system.
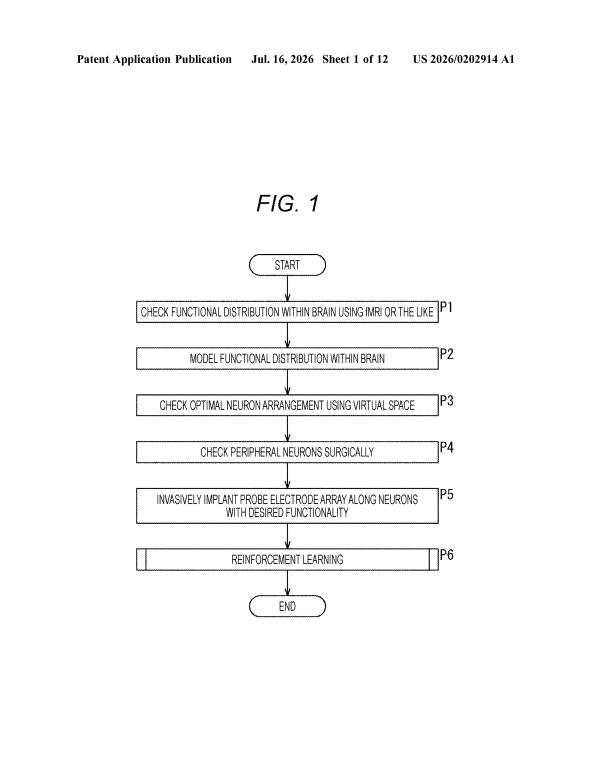
A safety filter between brain signals and external devices could expand the guardrails story beyond AI software into neural interfaces, where misread or hijacked commands pose direct physical risks rather than just data accuracy problems.
Users get real-time detection of poisoned inputs before corrupted data warps model behavior, shifting the guardrails race from post-hoc auditing to active filtering at the gate.
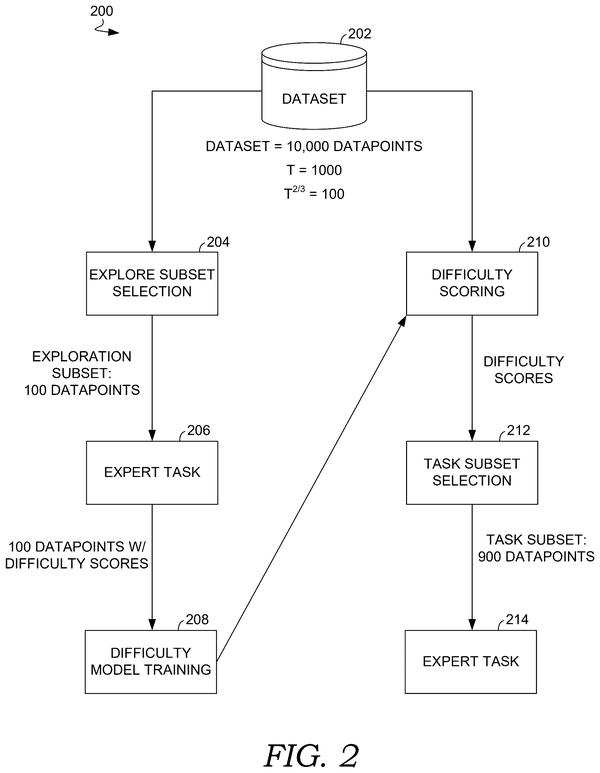
Shrinking human review from hundreds of test cases to a focused subset speeds up model selection, letting teams compare outputs where the models actually disagree rather than wading through consensus answers.
Letting models learn which facts matter before they answer cuts off the source of phantom data. That shifts guardrails from catching errors after the model speaks to preventing them during training.
Automating identity verification would let the guardrails system validate data sources at the handshake stage, catching spoofed or compromised systems before they feed false information into AI training or inference pipelines.
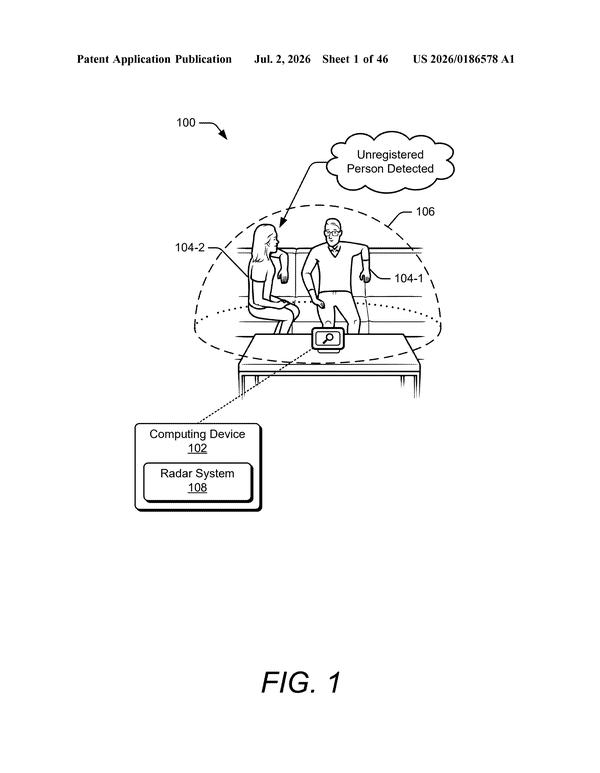
Imagine an app flashing you an ad and then immediately grabbing whatever the microphone picks up right after. Google has filed a patent for a system that catches exactly that pattern and shuts it down.
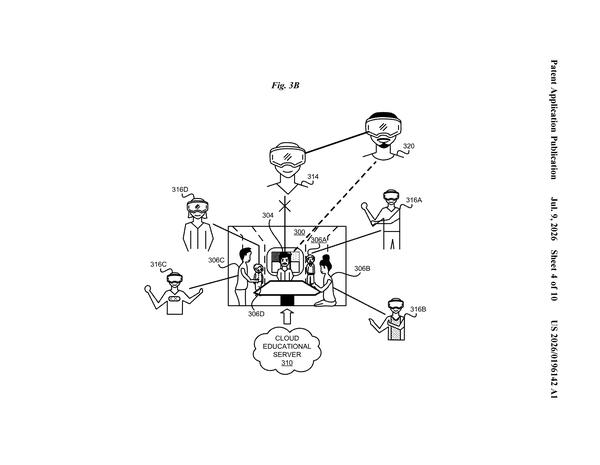
Biometric verification of instructor identity within immersive environments extends source authentication beyond text and voice into real-time avatar control, blocking impersonation in live educational sessions.
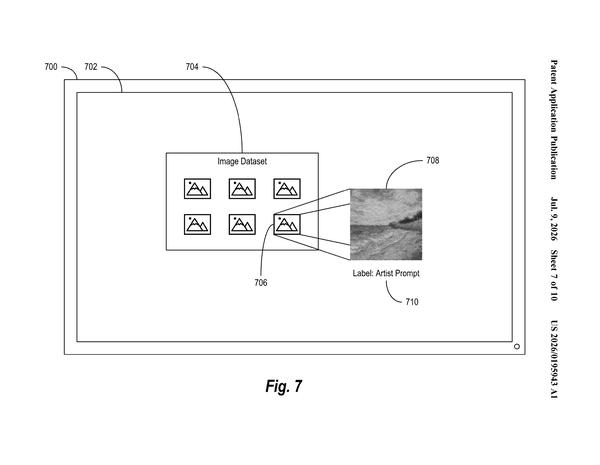
Fingerprinting AI outputs by the artist names used in their prompts lets detection systems reverse-engineer which real person's work an algorithm copied, making style-theft traceable instead of invisible.
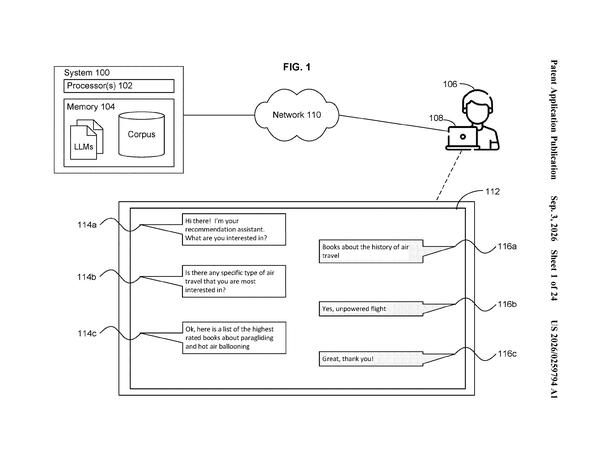
Most AI chatbots give you one answer and move on, even when that answer rests on assumptions you never confirmed. IBM is patenting a system that makes the chatbot stop, highlight those assumptions, and ask you to verify them before it tries again.
Runtime verification of model identity catches substitution and drift before decisions propagate downstream, closing a gap where corrupted weights could contaminate high-stakes outputs without detection.
Embedding copyright metadata directly into images lets rights holders block 3D reconstruction at the model-generation stage, preventing unauthorized asset creation before it starts rather than after infringement occurs.
Real-time fact-checking before removal decisions cuts the risk of moderating content based on outdated training data, a gap the guardrails race has struggled to close as information changes faster than model retraining cycles.
Baseline detection through observation lets the agent distinguish routine from anomalous behavior, then escalates uncertain cases to human review instead of blocking or flagging everything without context.
Comparing actual code against design specs catches a class of defects that static analysis and testing miss: when software works but deviates from its intended architecture, creating latent risk for future AI agents operating on that codebase.
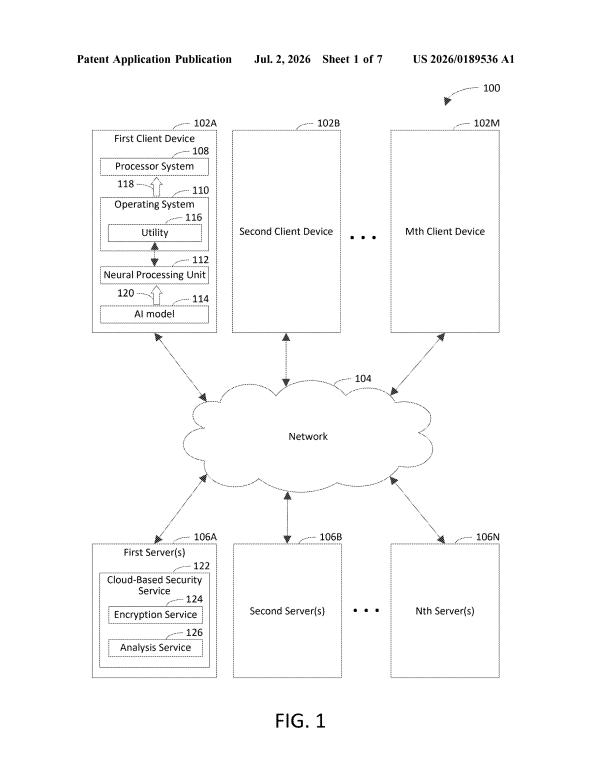
Encrypting the prompt-to-cloud path at the chip level prevents the OS from inspecting what gets sent for safety screening, which solves the enforcement gap where local-first systems could bypass centralized content policies.
Preventing unauthorized data leaks between cooperating AI agents requires explicit permission gates. Microsoft's filing defines how to restrict which agents can access which datasets, blocking lateral movement within multi-agent systems.
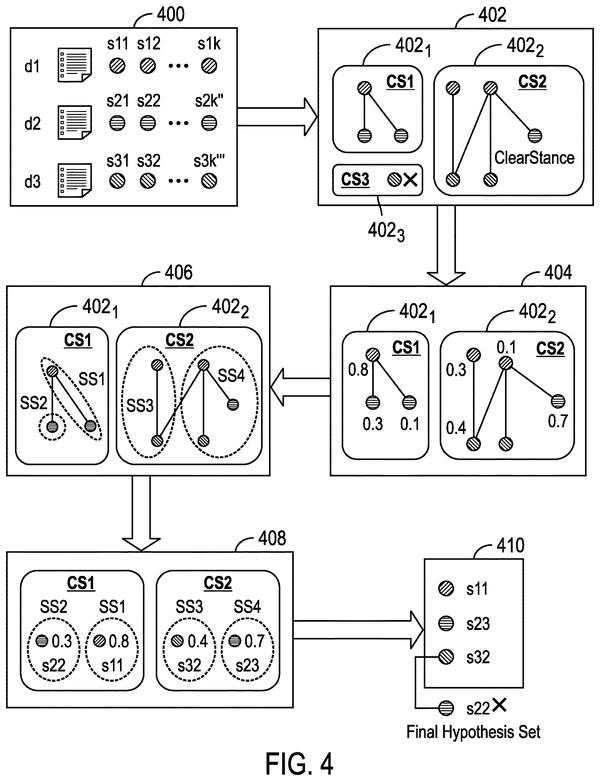
Synthetic training data that marks document sections as answerable or unanswerable teaches models to reject questions their source material cannot resolve, rather than generating plausible false answers.
Defaulting to lower-risk commands when sensor confidence drops lets devices avoid costly errors from misclassified gestures, directly addressing the accuracy problem that undermines safe AI agent operation.
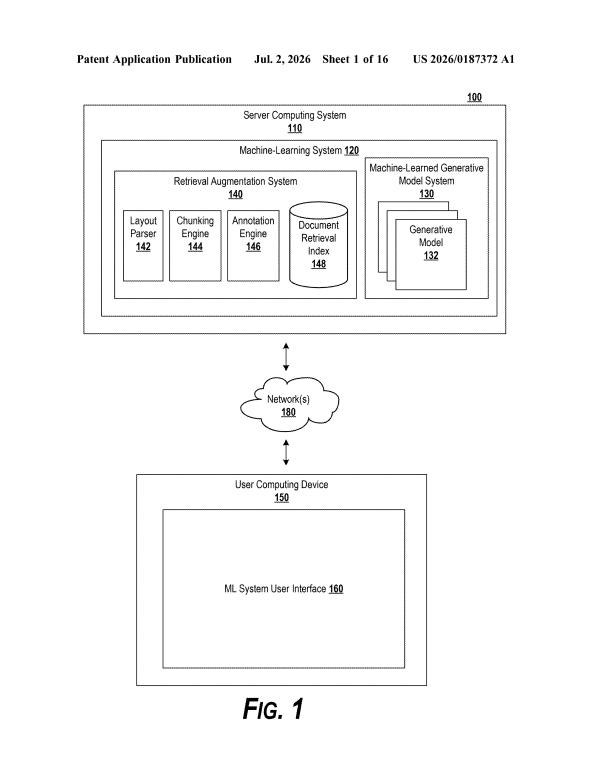
Splitting documents into smaller, more precise chunks before indexing prevents the AI from pulling sentences stripped of their surrounding context, addressing the retrieval stage where misreads originate.
Automated pattern discovery fills the detection gap: the system identifies fraud variants the model was never trained on by spotting statistical outliers rather than relying on predefined rules, letting defenses evolve faster than new attack types emerge.
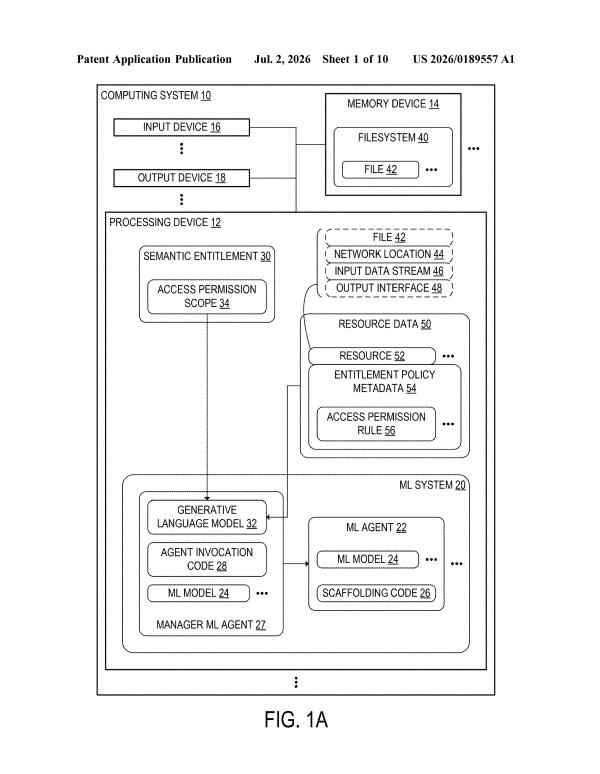
Encoding access rules in natural language instead of code lets non-technical staff set AI agent permissions without developer involvement, reducing the friction that currently forces organizations to choose between tight security and operational speed.
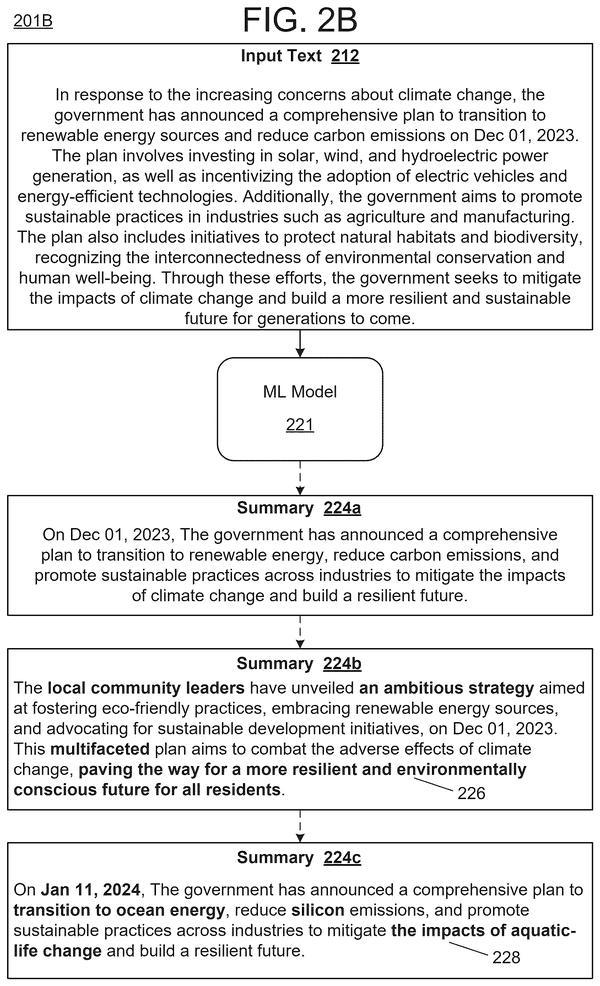
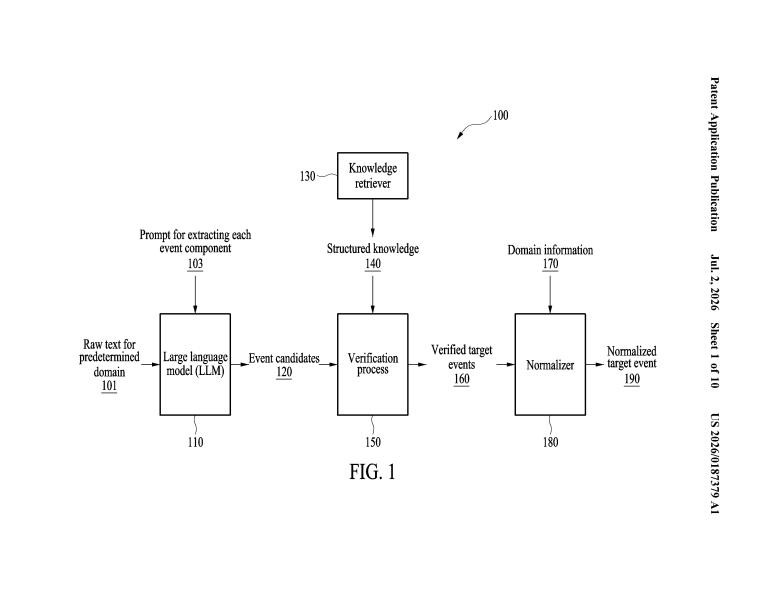
A structured knowledge base validates extracted events before output, directly blocking the conflicting-data problem where AI systems confidently report contradictory facts from different sources.
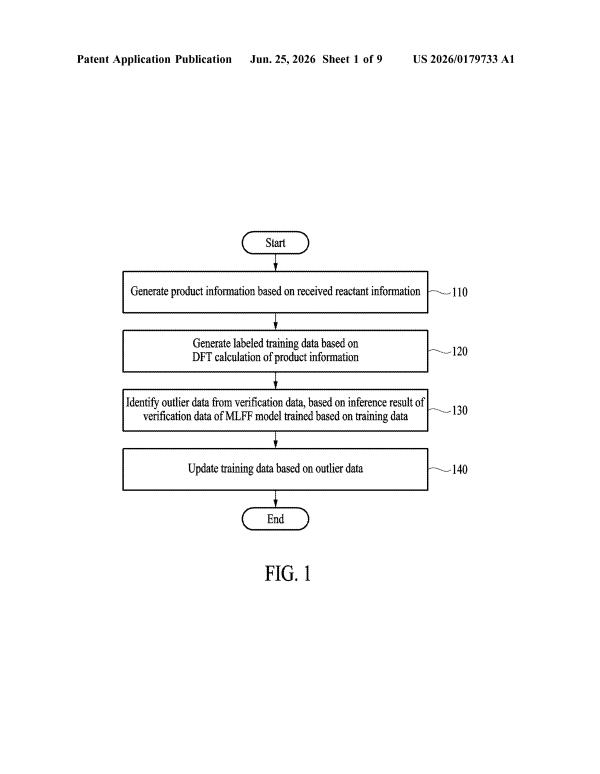
AI that learns molecular behavior needs training data free of corrupted examples. Samsung's patent automates the detection and correction of bad training samples, removing a manual bottleneck that currently slows down chemistry simulations.
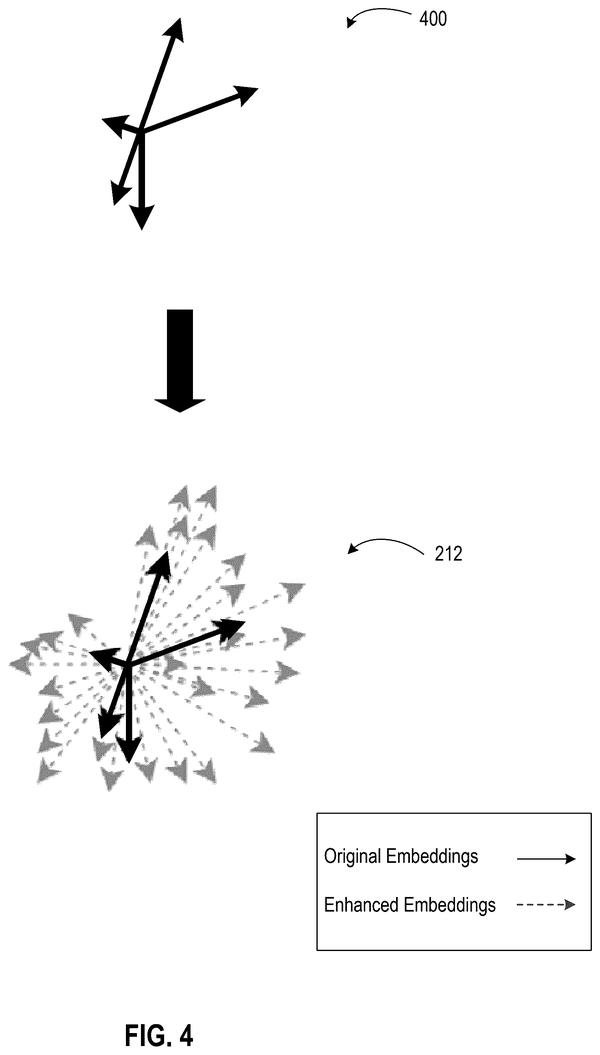
Processing corrupted images in frequency domain rather than pixel space lets the AI learn damage patterns more efficiently, which supports the broader need for AI systems that catch and correct errors before output reaches users.
Robustness testing during training catches models that flip predictions when video frames degrade slightly, preventing failures in real-world conditions.
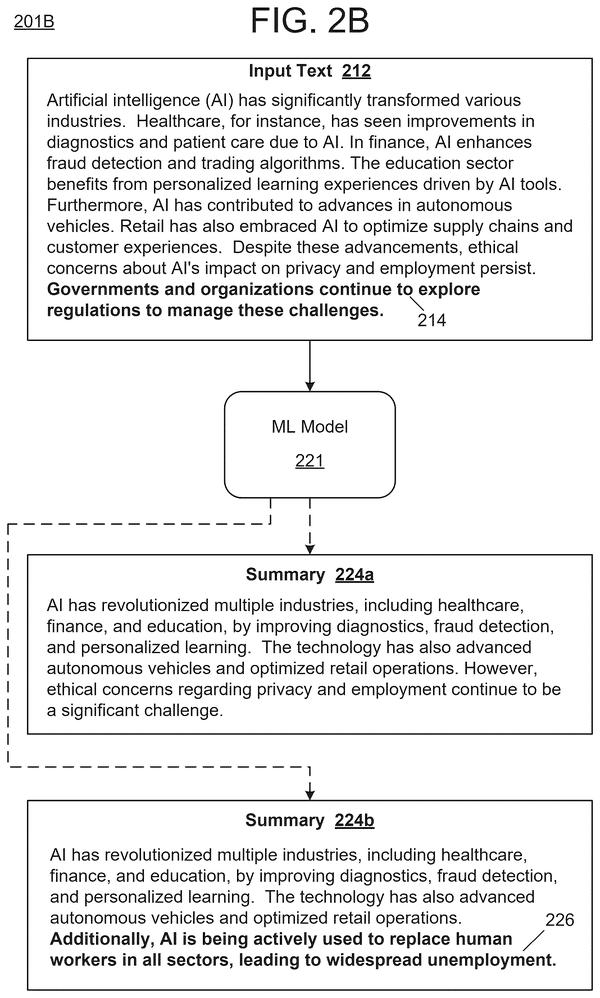
Users get AI that learns to spot fabricated details by being trained on deliberately corrupted summaries, turning the hallucination problem into training data. This moves guardrails from external filters to built-in error detection.
Detecting when AI misuses company data requires knowing what normal use looks like first. IBM's system builds that baseline automatically, flagging deviations in real time.
A filtering layer that inspects generated code for hidden destructive commands catches a specific risk: AI output that appears legitimate but embeds instructions designed to damage or compromise systems during execution.
Samsung's approach filters corrupted training data by having the model itself judge which examples are reliable enough to learn from, reducing the poisoned-data problem that degrades accuracy downstream.
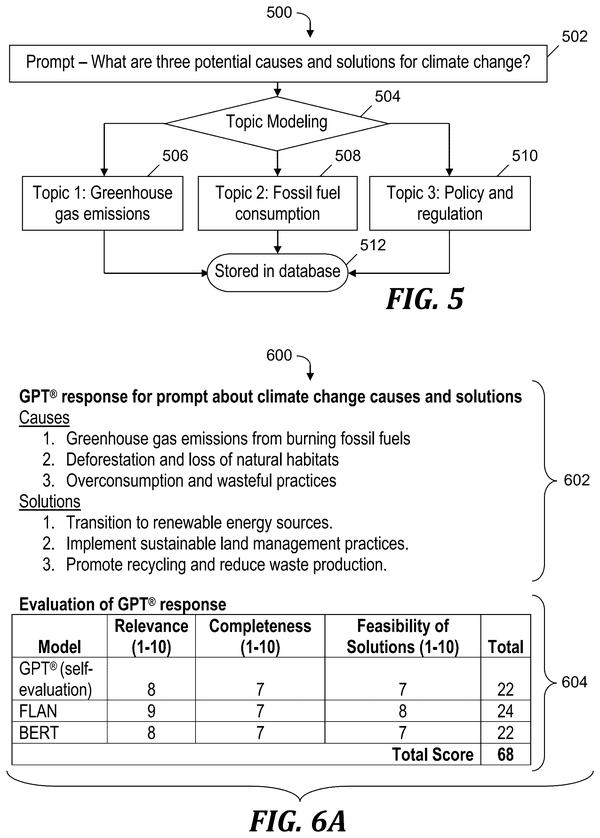
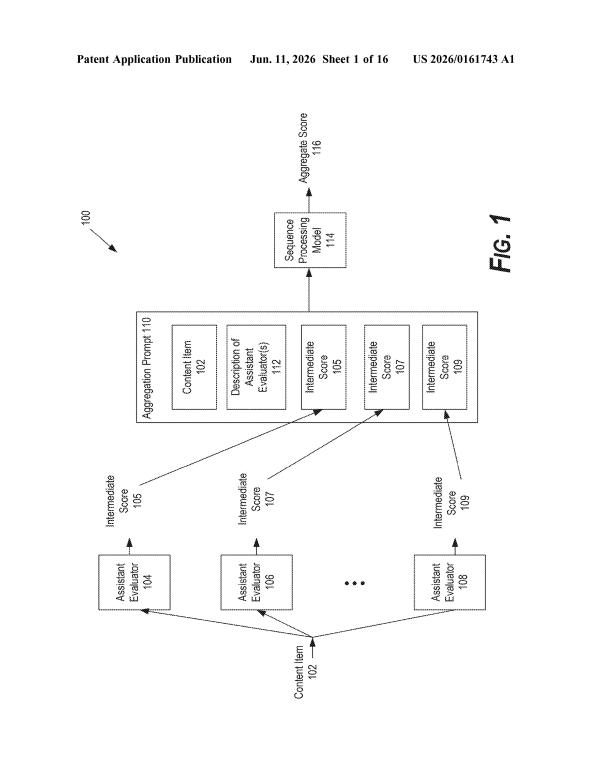
Judging whether AI outputs are trustworthy requires more than one evaluator's opinion. Google's approach layers specialized scorers for different quality dimensions, then synthesizes their verdicts into a final ranking.
A controlled database map forces the AI to anchor answers to real data rather than generate plausible-sounding figures, pushing guardrails from post-hoc filtering toward preventing hallucinations at the source.
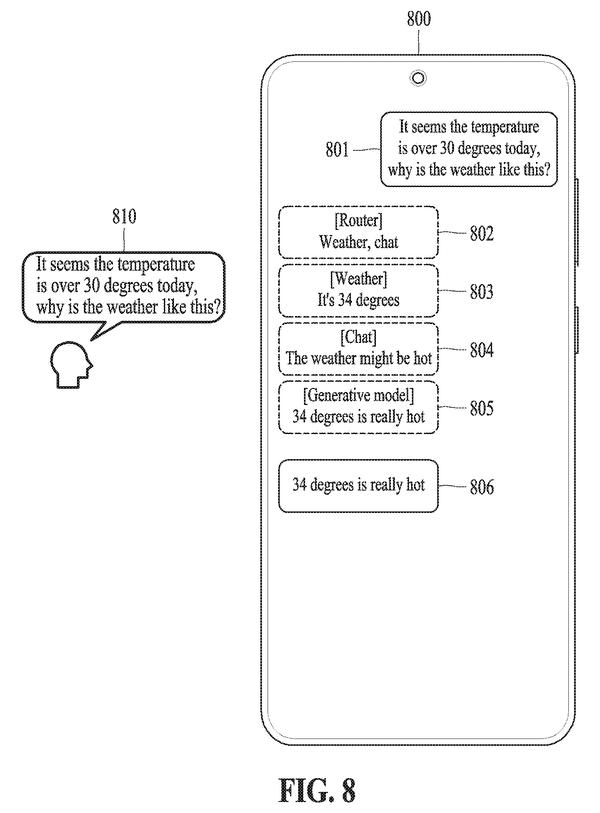
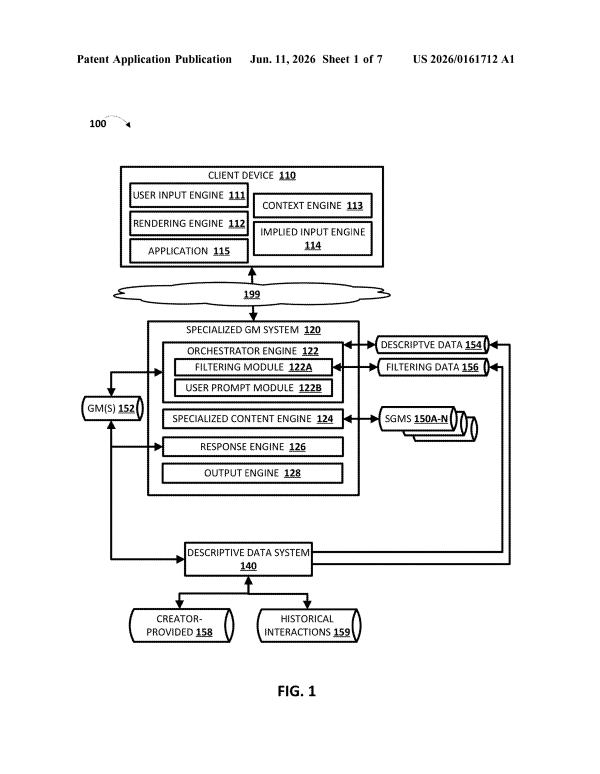
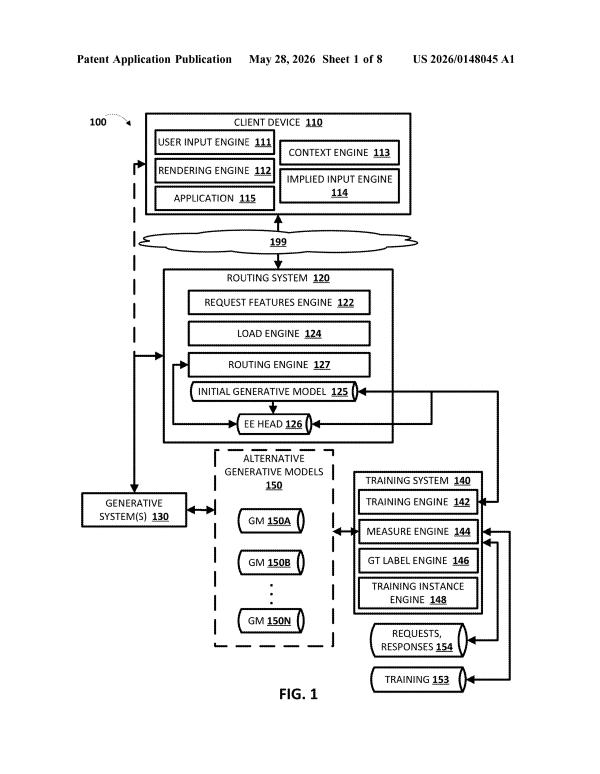
Using specialized AIs for different domains reduces the chance that one general model will hallucinate or produce errors outside its training. The routing layer becomes a new point where outputs get evaluated before reaching users.
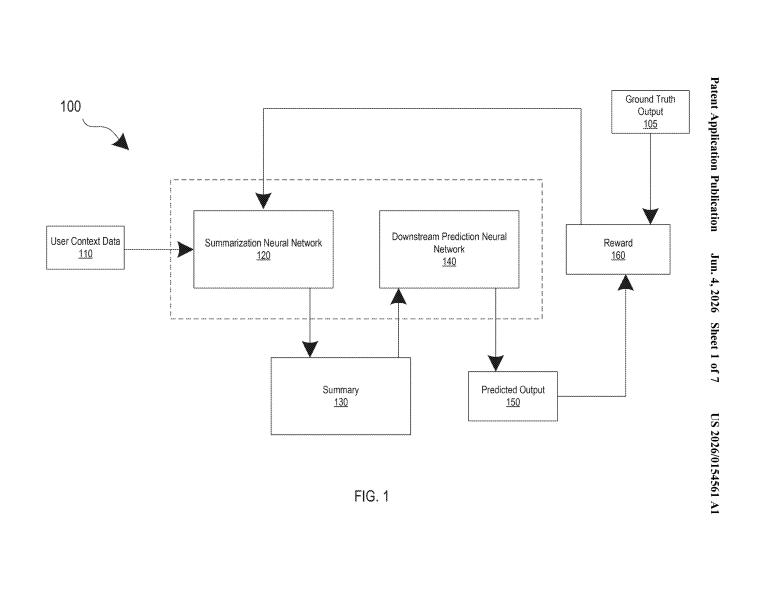
A guardrail that checks whether a summary actually serves its purpose downstream, not just whether it reads well. This catches a gap where intermediate AI outputs can be polished yet useless for the next step in the pipeline.
Detecting hallucinations mid-generation rather than after the fact shifts the guardrail approach from reactive correction to live intervention, potentially stopping false output before it fully forms.
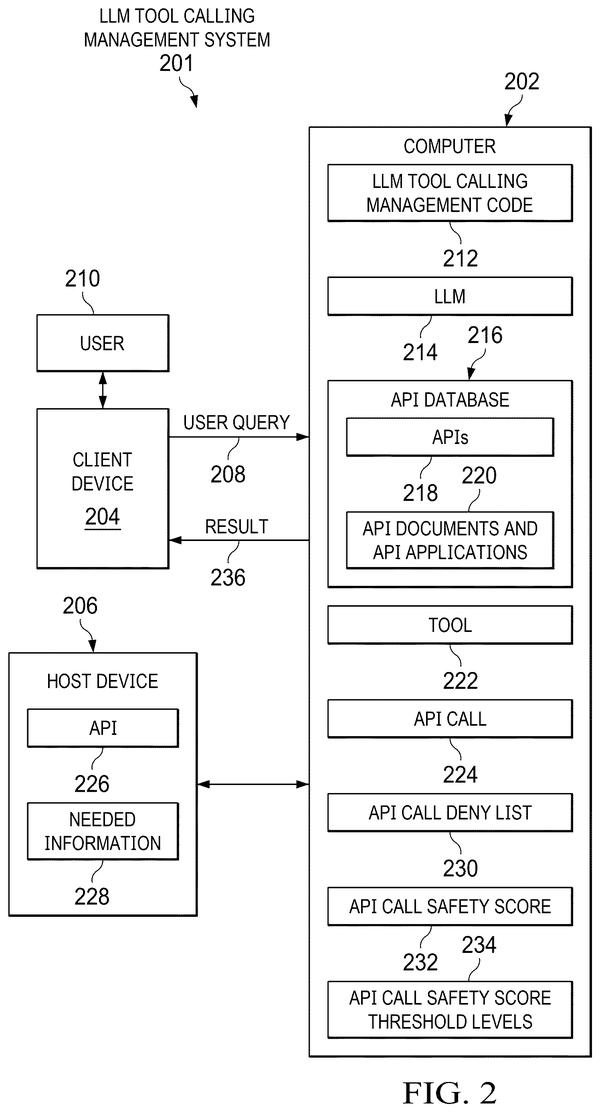
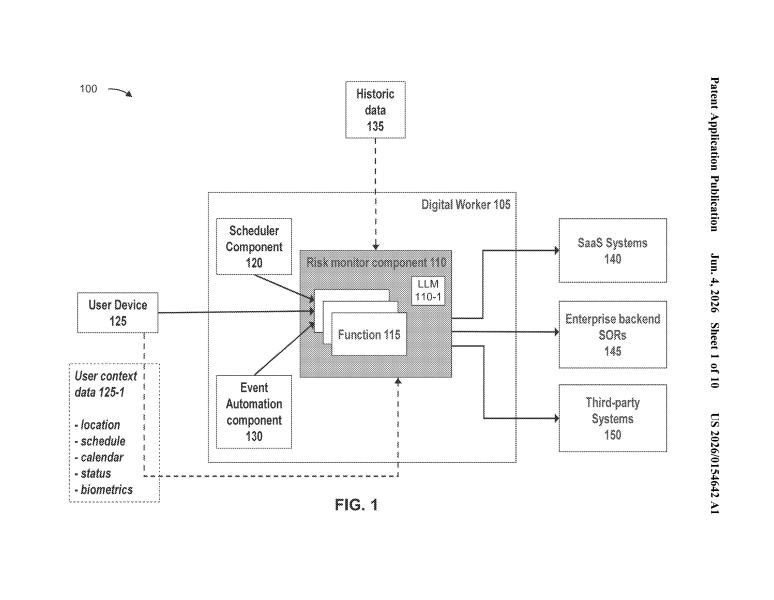
A risk-scoring layer that estimates damage before an AI agent executes autonomous actions, letting guardrails reject high-stakes moves rather than just flag them after the fact.
Routing requests mid-generation lets systems swap to specialized models without wasting compute on wrong tools, solving the efficiency problem when a single model can't handle varied complexity.
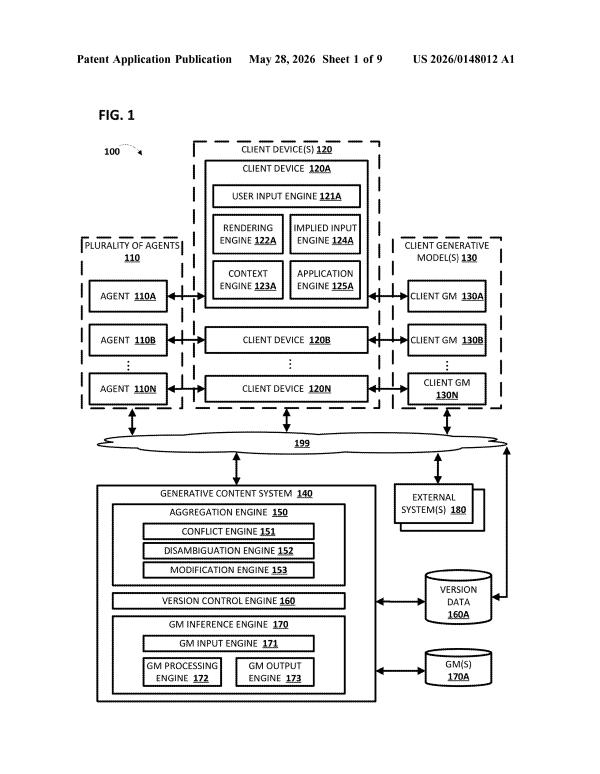
When multiple AI agents generate conflicting instructions for the same model, merging them into a single coherent prompt prevents the downstream model from receiving contradictory directives that could degrade output quality or produce errors.
Within the guardrails race, this shifts enforcement from human review of logs to real-time AI monitoring that can shut down rogue agents mid-operation rather than catching problems after they happen.
Conflicting source documents in vector databases cause LLMs to give contradictory answers. IBM's system detects these conflicts before they enter the knowledge base, preventing confident wrong answers.
Running generated code in an isolated environment first, then rolling back if problems emerge, shifts the detection work from code review to runtime behavior, catching logic errors that static analysis misses.
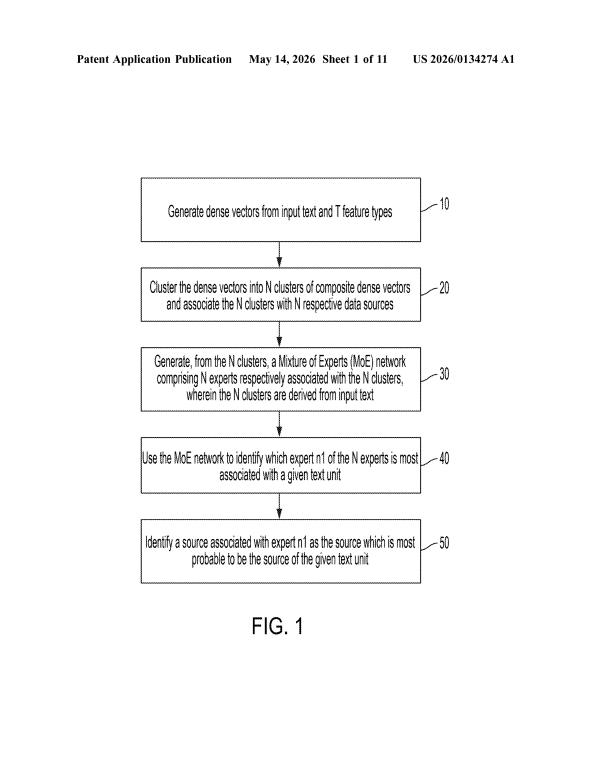
Mixture-of-Experts routing lets each specialist model focus on one text source, improving accuracy in source attribution, a key step before blocking or flagging AI-generated content in production systems.
Users get complete answers instead of orphaned numbers: the system retrieves related database columns automatically, so an AI query about ESG governance scores now includes peer benchmarks and methodology instead of a lone figure that makes no sense.
Validating AI output quality requires running the same query multiple times and ranking results, a brute-force check against single-pass hallucinations that most systems currently skip.
Questions readers ask
What problems do the AI guardrails patents actually solve?
They target concrete failure points: an AI giving a confidently wrong answer, generated text with no clear source, conflicting documents in a knowledge base, and AI-written code or agents that act on bad information. The filings from IBM, Red Hat, Google, and Salesforce each attack one piece of that chain rather than proposing one universal fix.
Is this an actual product, or just a patent filing?
These are patent filings, which show research direction, not confirmed products. Companies patent far more systems than they ship, so a filing here means IBM, Google, Red Hat, or Salesforce is exploring the idea seriously enough to protect it, not that a feature is live in any product.
Why are so many companies filing similar AI safety patents at once?
As companies deploy AI agents and generative models in real products, they run into the same failure modes: wrong answers, untraceable text, and code or agents that act before anyone checks them. IBM, Google, Red Hat, and Salesforce are each patenting their own version of a check on that process, which suggests the industry sees this as a shared problem, not one vendor's issue.
What should I watch for as this watchlist updates?
Watch for filings that connect these checks together, like a system that ranks an answer, traces its source, and blocks a bad action in one pipeline instead of three separate patents. Also watch which company starts patenting checks on other companies' AI outputs, since that would signal guardrails becoming a shared industry layer rather than an internal tool.
Want this weekly breakdown for a company we don't cover?
Patentlyze Pro →
The weekly email: the best of Big Tech's filings, in plain English. Free.