Big Tech's On-Device AI Privacy Patents, and Who's Winning the Race
This watchlist tracks patents on scrubbing personal data before it leaves a device, training AI models without exposing raw data, and filtering sensitive information before it reaches cloud AI or ad auctions. Together they show Google and Samsung racing to prove AI features can run locally without sending data to company servers.
201 filings
· tracking since Apr 2026 · latest Nov 2026 · updates weekly
based on all tracked filings in this watchlist · refreshes every week
This watchlist covers a fight over who controls personal data when AI runs on your own phone, camera, or laptop, and whether that data ever has to leave your hands at all.
Google files the most by a wide margin, about a third of all filings, with Samsung a distant second.
What’s new in the on-device AI privacy push
a dated entry each week this watchlist moves · older entries stay archived
Nov 5, 2026 11 filings joined
Google and Microsoft lead this week, each filing multiple patents around keeping data private on the device itself. The filings cover everything from locked chip storage to hiding user identities in chats and swapping out personal details before they reach advertisers.
Qualcomm leads with four filings, mostly around hiding faces and plates in video. The week's filings center on keeping private data on your device and out of the cloud.
This week's filings center on keeping personal data private during AI training and search. Google and Qualcomm led with the most new applications, covering everything from private ad-picking to cleaner AI learning over weak wireless connections.
Google and Samsung lead this week, each filing multiple patents around keeping personal data private while AI still does its job. The filings span phones, TVs, cameras, and ads, showing broad industry movement toward AI that works without exposing user information.
This week's filings all circle the same idea: train AI and share data without exposing who you are. Microsoft and Apple each filed twice, covering voice, location, and group chats.
Microsoft leads this week with four filings focused on keeping private data safe while AI runs. Sony and Google each added two filings around training AI without sharing raw personal data.
This week's filings center on keeping personal data on your device and out of shared servers. Google and Samsung led the push, covering everything from ad controls to face animation to smart speakers that go silent when privacy matters.
Most new filings focus on keeping personal data local or hidden during AI work. Microsoft and Google are the most active, each filing multiple patents around protecting private information while still letting AI systems learn and run.
Most filings this week focus on keeping data on your device instead of sending it to the cloud. Google and Apple each filed multiple patents in this space, covering everything from photo protection to facial recognition to ad targeting.
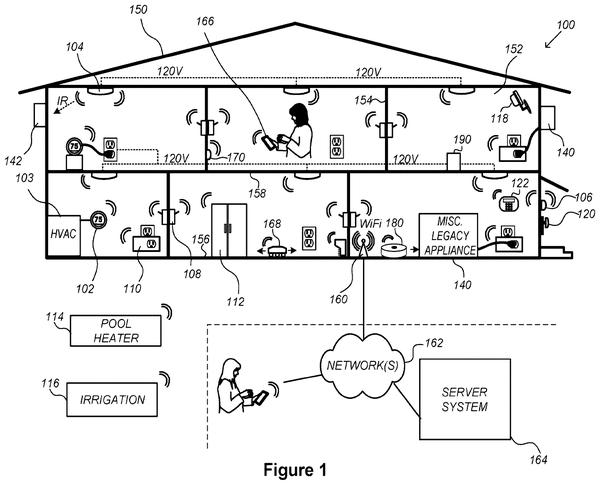
This week's filings all circle around keeping AI work on your own device rather than sending data to the cloud, covering everything from smart home updates to emergency messages to voice fixes. Google leads with two filings, while Apple, Samsung, and Sony each add their own take on handling personal data locally.
Aug 27, 2026 9 filings joined
This week's filings center on running AI directly on your device instead of sending data to outside servers, with Apple and Qualcomm each adding three new filings. Uses range from reading faces and tracking objects to showing ads without ever seeing your full personal profile.
Aug 20, 2026 11 filings joined
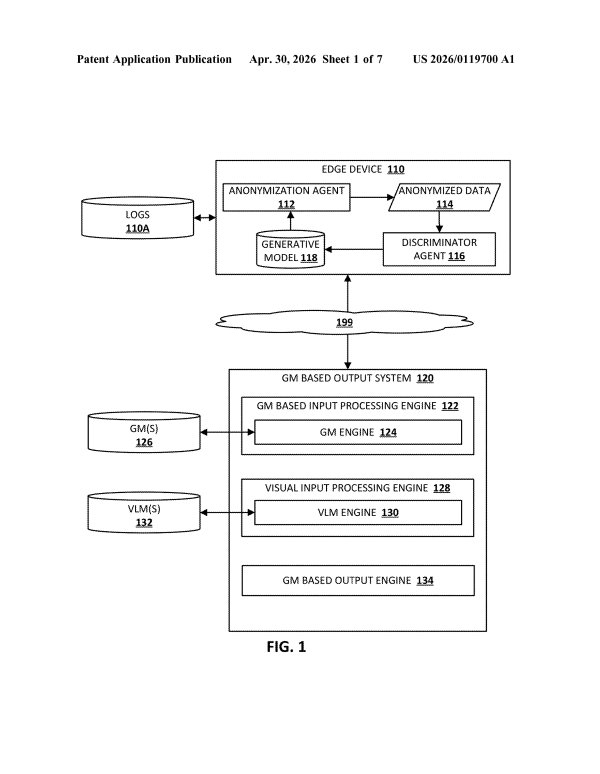
This week's filings focus on keeping personal data on the device and out of outside servers. Apple and Google led the activity, each filing multiple patents around hiding or stripping personal details before any data leaves your hands.
Who’s filing patents in the on-device AI privacy push
counts from tracked filings · focus read from each company’s own filings
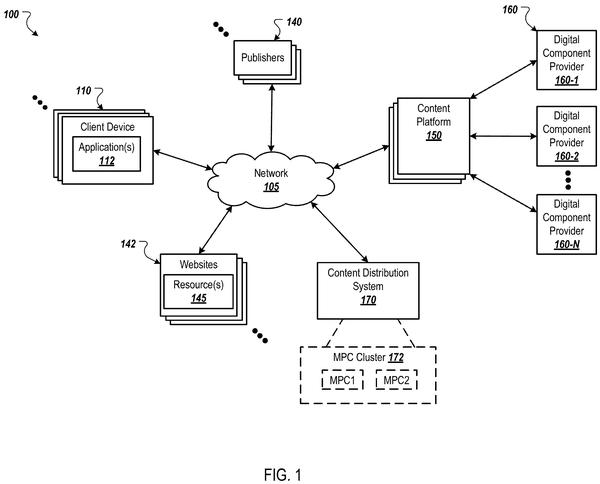
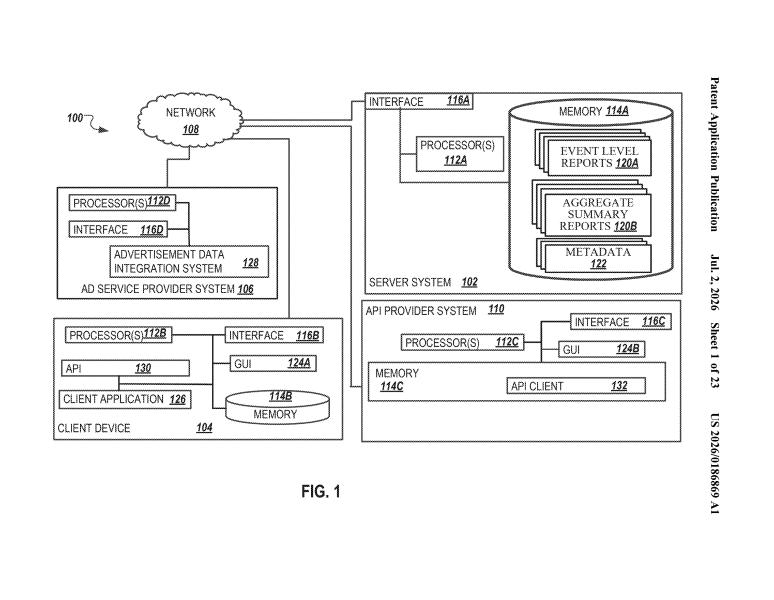
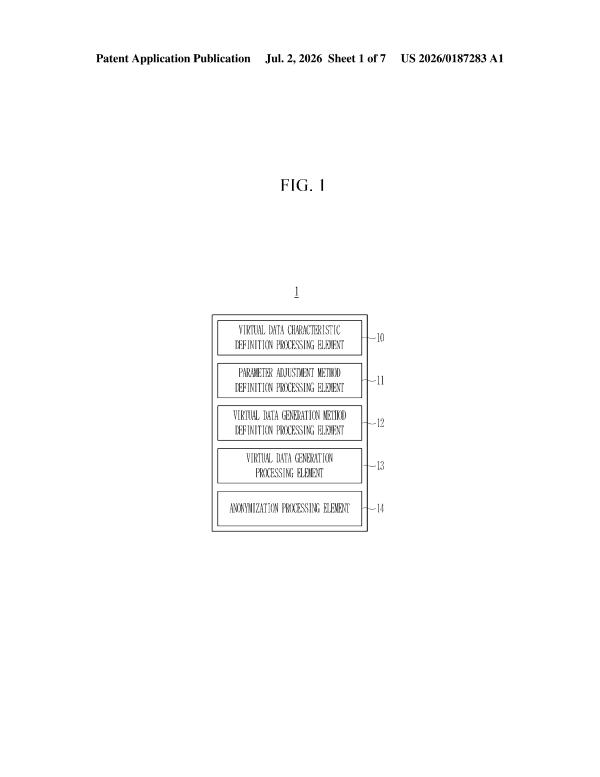
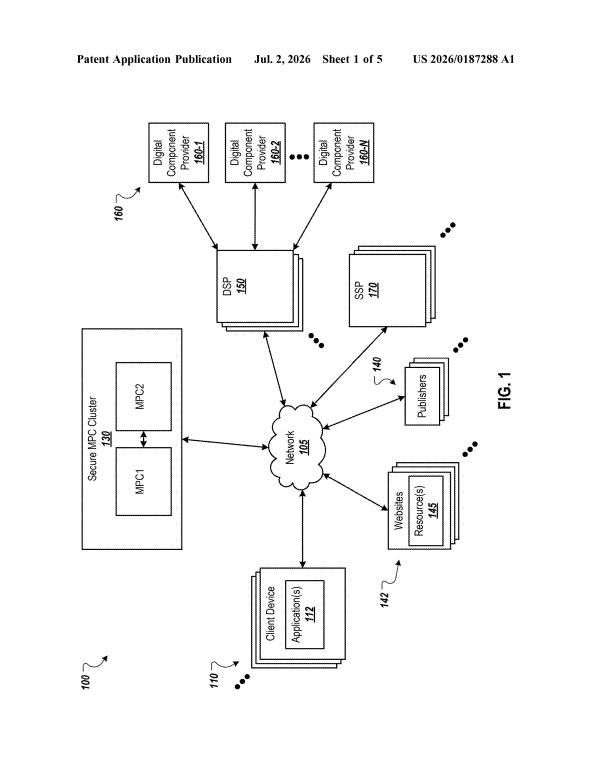
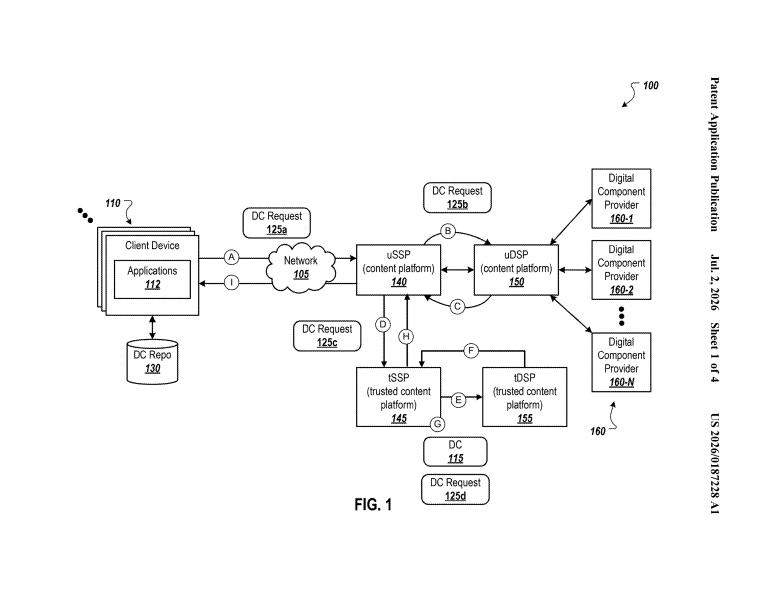
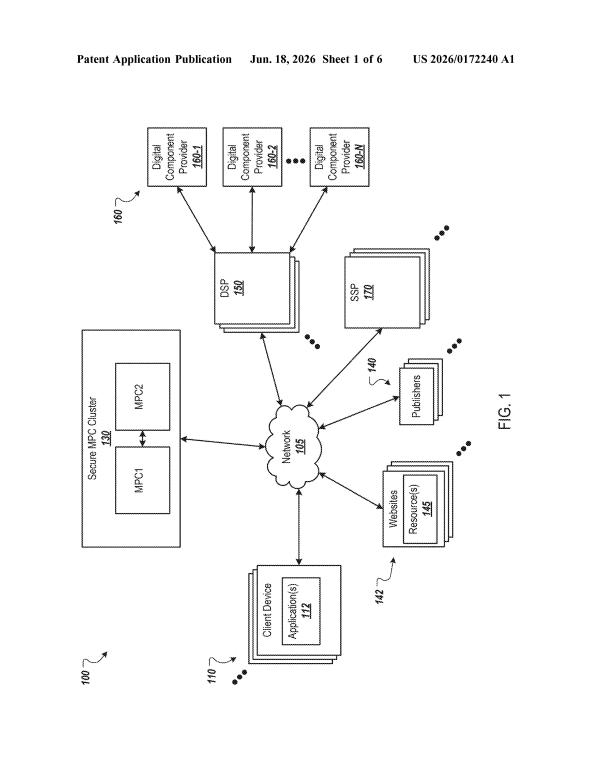
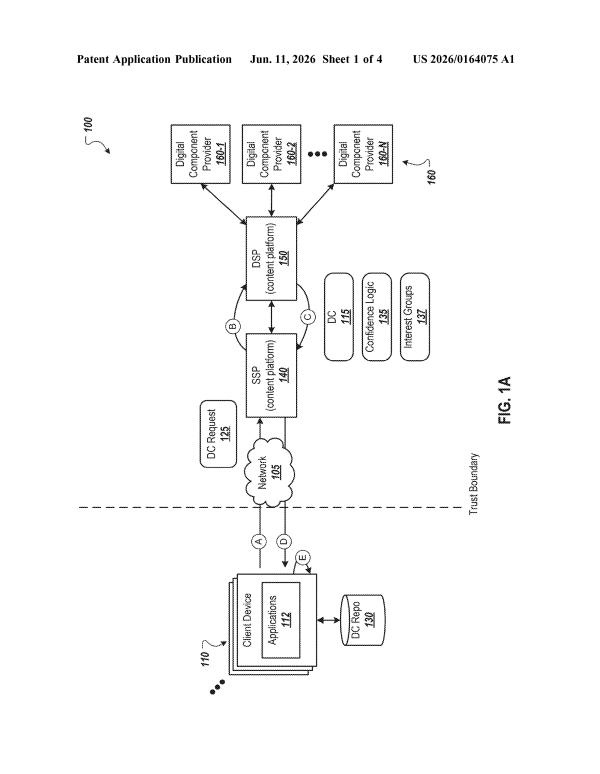
A large group of filings covers serving targeted ads without storing who you are or what you browse, doing the matching on your device instead of on a server. They range from picking winning ads to counting trends without ever seeing individual people.
Multiple companies are working on ways to stop apps and services from learning who you really are, using stand-ins, decoys, or encrypted replacements instead of your real details.
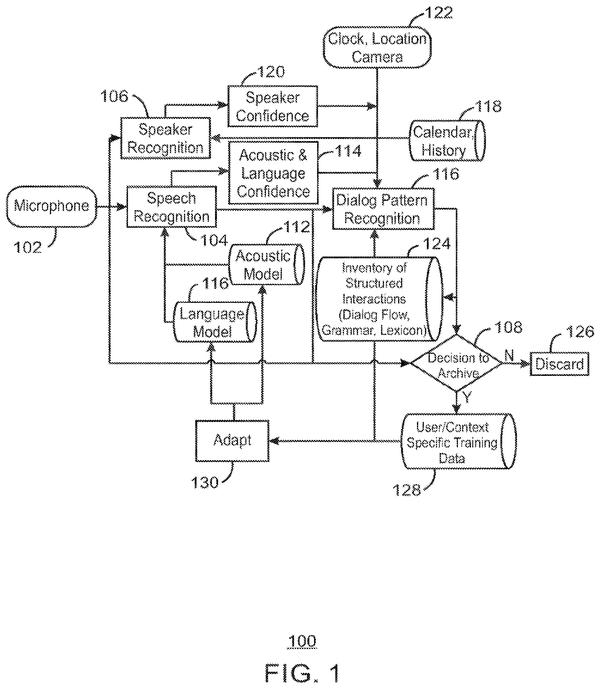
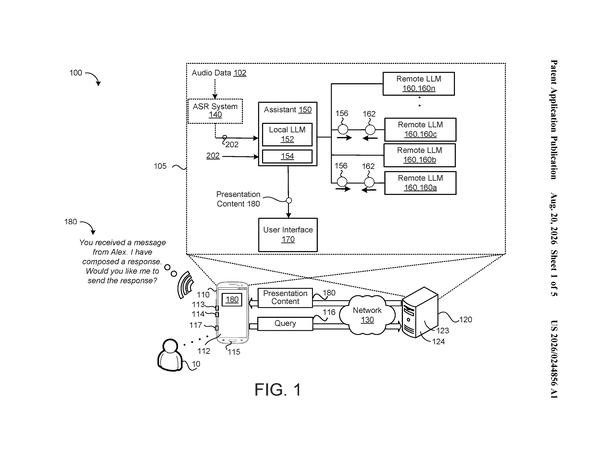
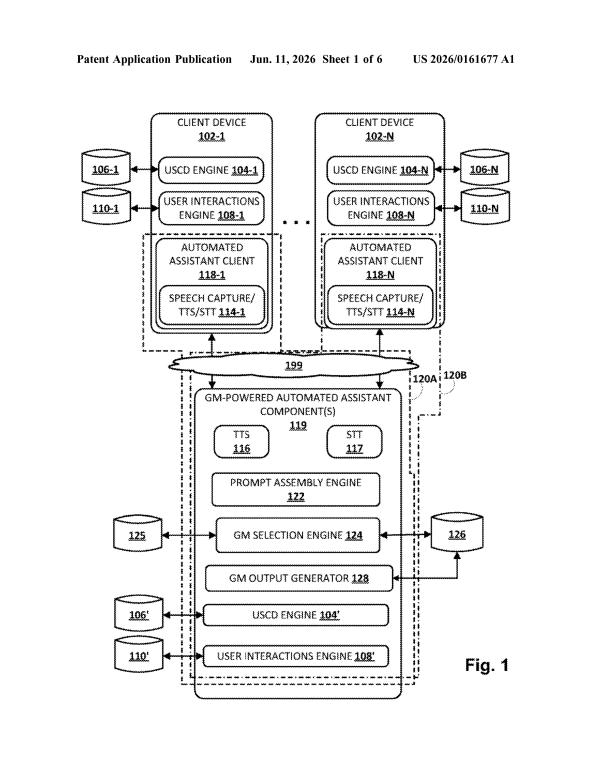
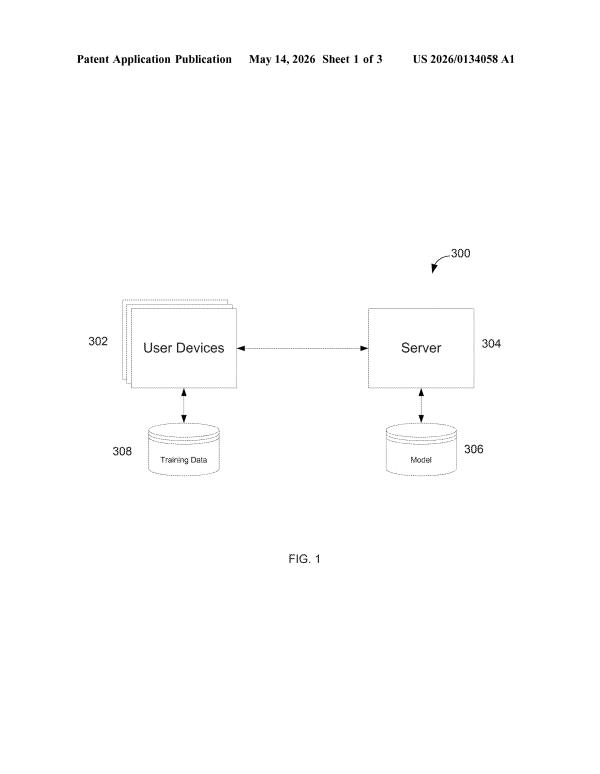
Companies are filing patents for AI that does its work entirely on your phone or computer without sending anything to a server, covering tasks like grammar checking, recommendations, and answering questions.
A cluster of patents focuses on catching and blocking sensitive data before it escapes, whether during software testing, code sharing, login flows, or blockchain transactions.
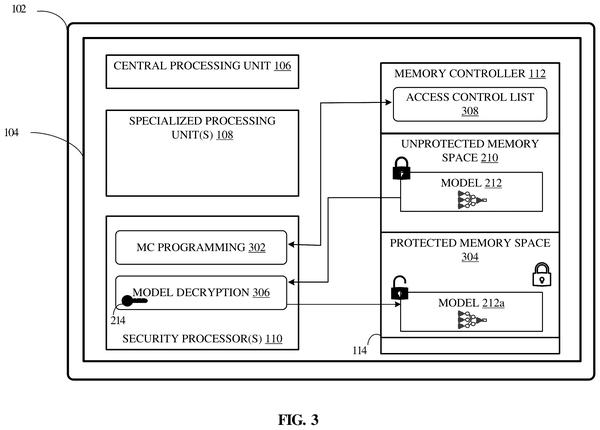
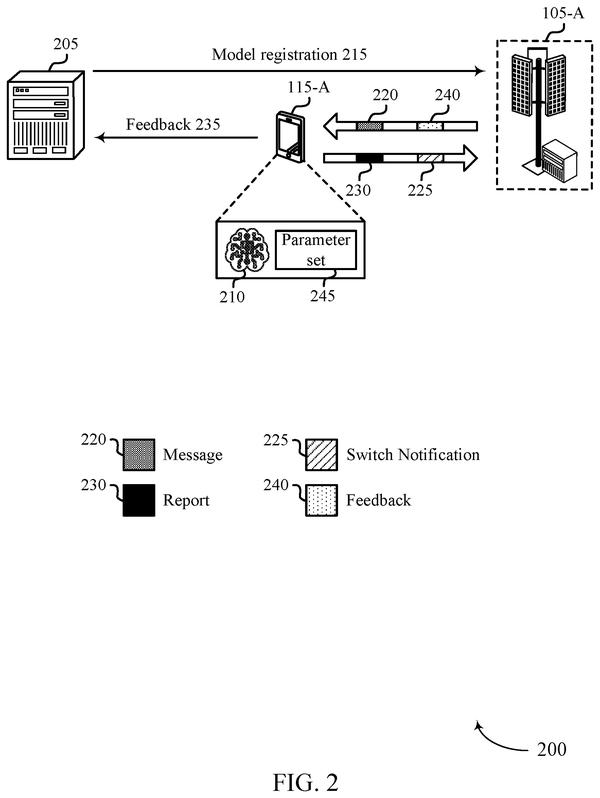
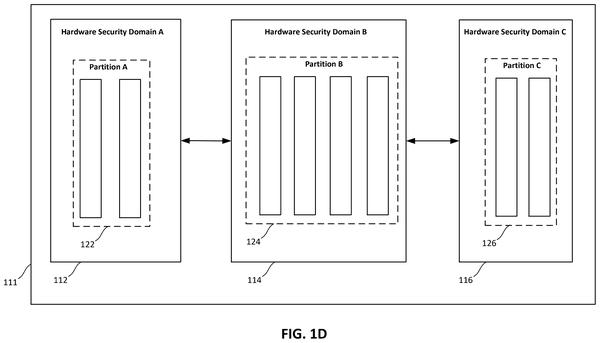
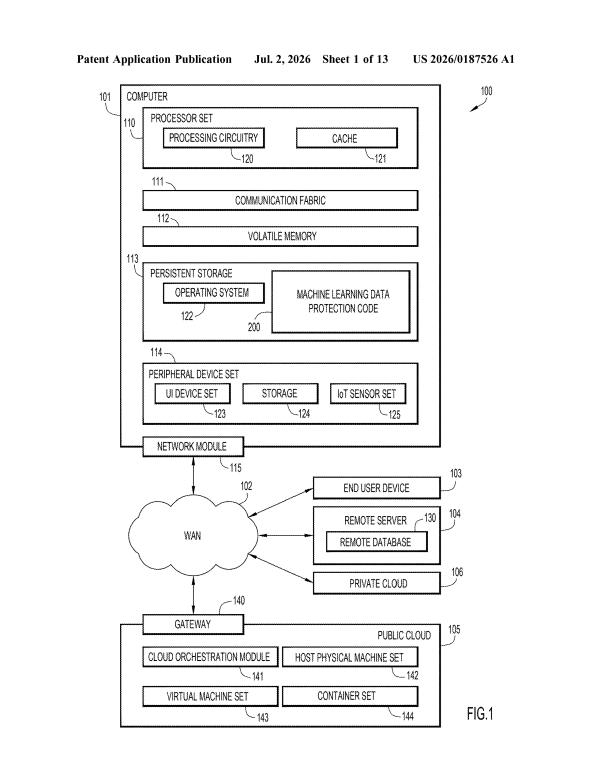
Hardware-level encryption compartments prevent copied models from running elsewhere, shifting the cost-protection problem from legal agreements to physics. This confirms the on-device route only works if the silicon itself enforces what software can't.
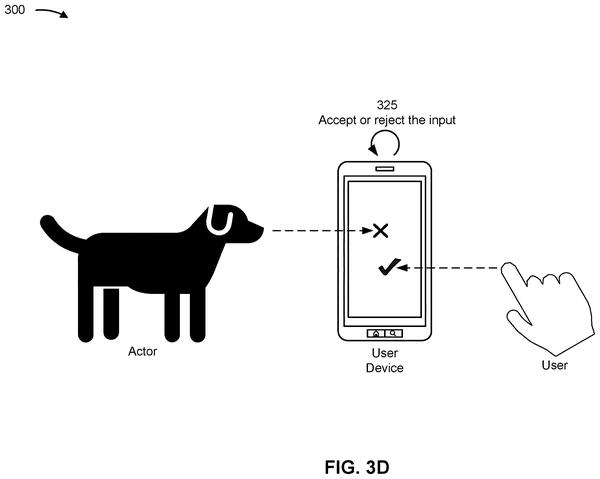
The watchlist so far covers filtering what leaves a device. This filing moves upstream: authenticating which inputs should reach the device in the first place, using presence detection to reject unintended commands before processing them.
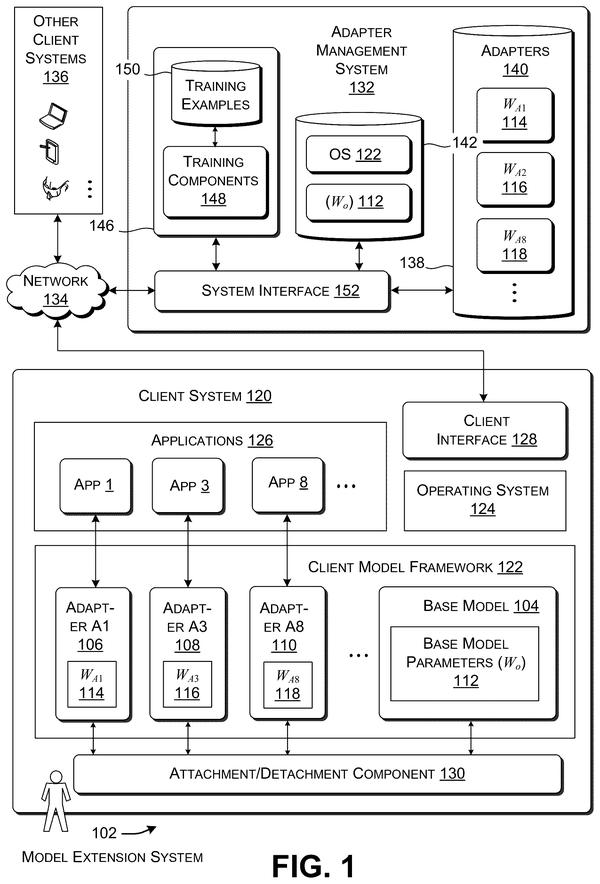
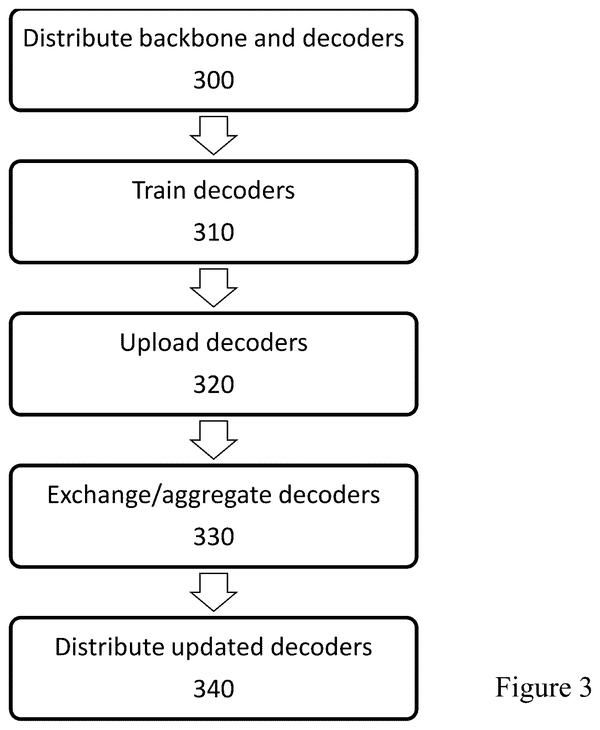
The modular approach here sidesteps the storage crunch that forces data to the cloud. One base model plus lightweight add-ons keeps computation local without duplicating massive parameter sets.
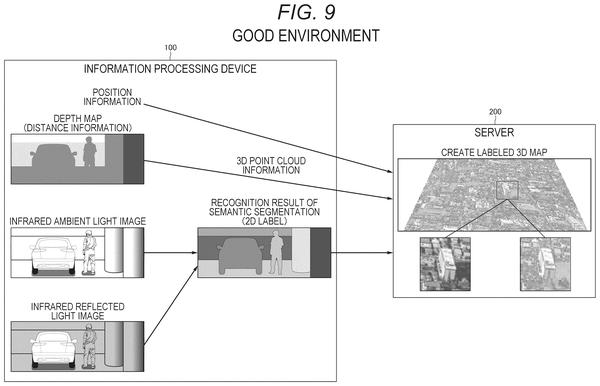
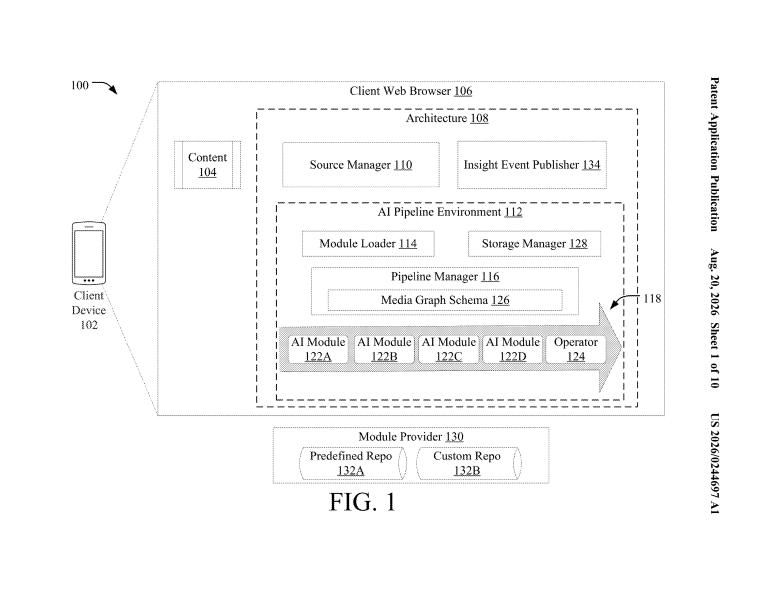
A sealed sensor that runs inference and deletes frames locally sidesteps the need to transmit or store video to count occupancy, pushing both the computation and the data destruction onto the device itself.
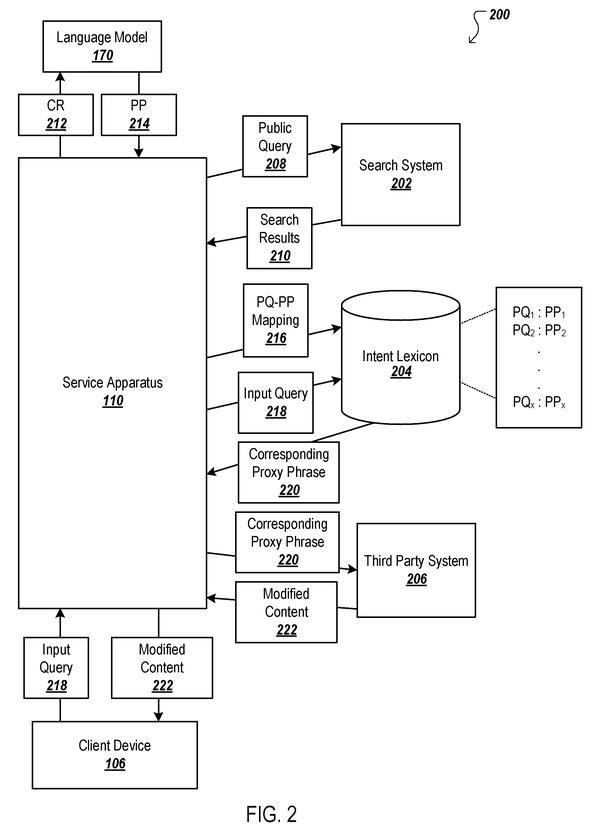
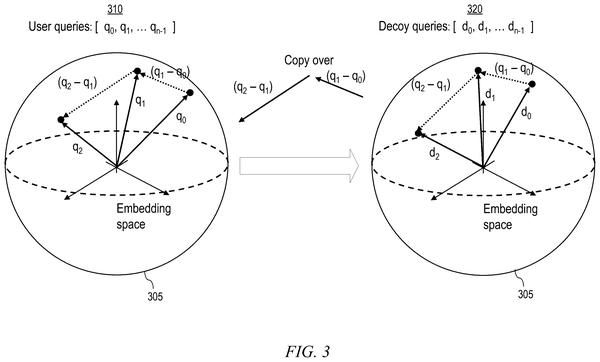
Query generalization replaces specific searches with common stand-in phrases before reaching advertisers, blocking the original language while preserving enough signal for targeting.
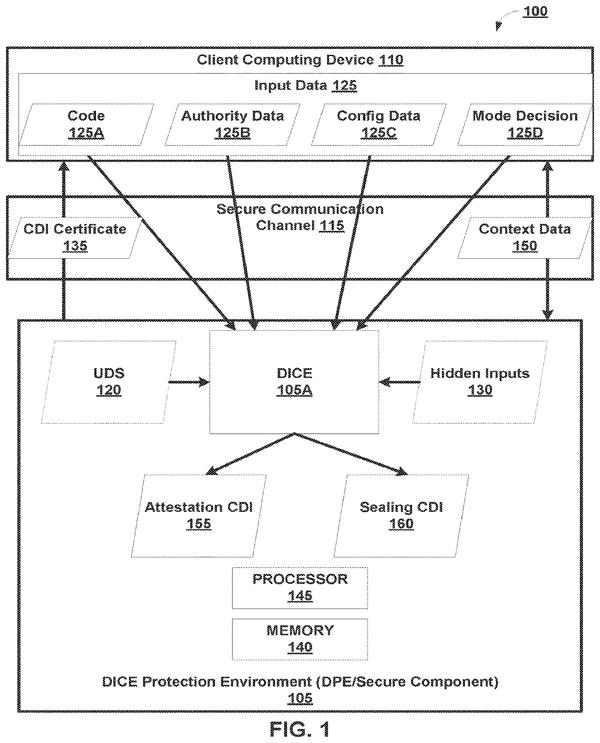
Isolating boot verification into a hardened component keeps attestation secrets confined during startup, preventing them from spreading across the normal software stack where any compromised process could expose them.
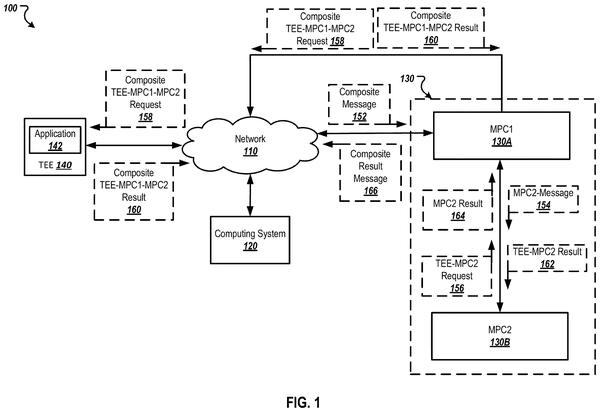
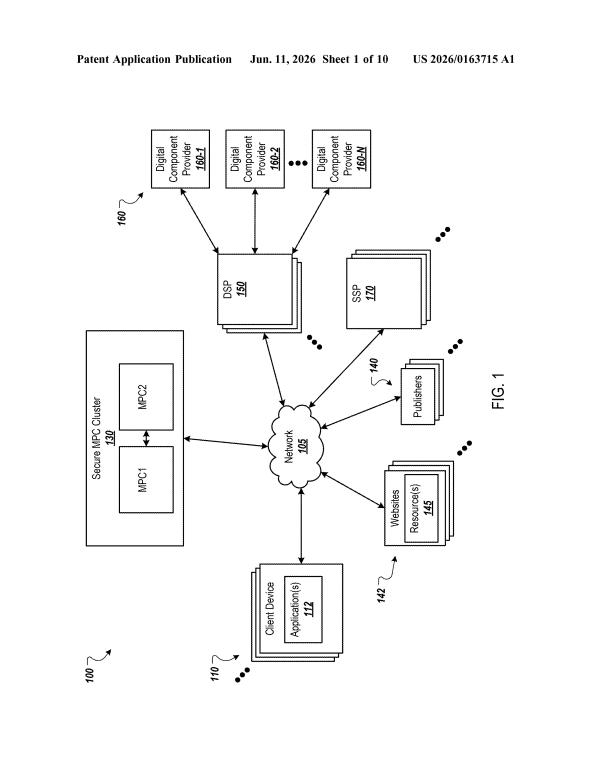
Hardware-level reconstruction inside a trusted enclave sidesteps the latency penalty of computing directly on secret-shared data, moving expensive operations into a protected chip region rather than distributing them across multiple parties.
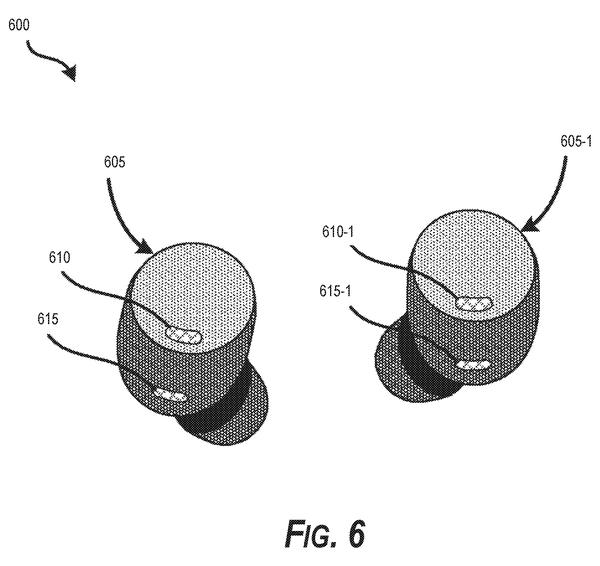
Dual-mic geometry in earbuds lets the device isolate voice from ambient noise through timing differences before audio reaches the transcription engine, sidestepping the need to send noisy raw audio to cloud processing.
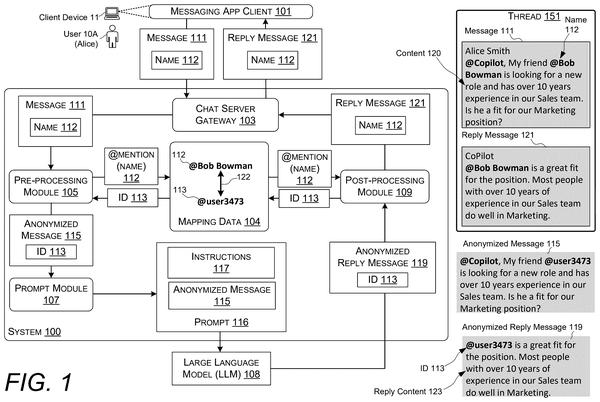
Token substitution at the message boundary lets group chat AI respond to mentions without seeing actual names, blocking a vector for training-data leakage in real-time contexts.
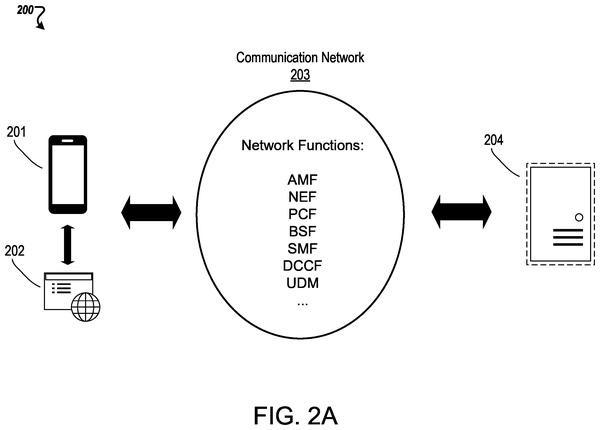
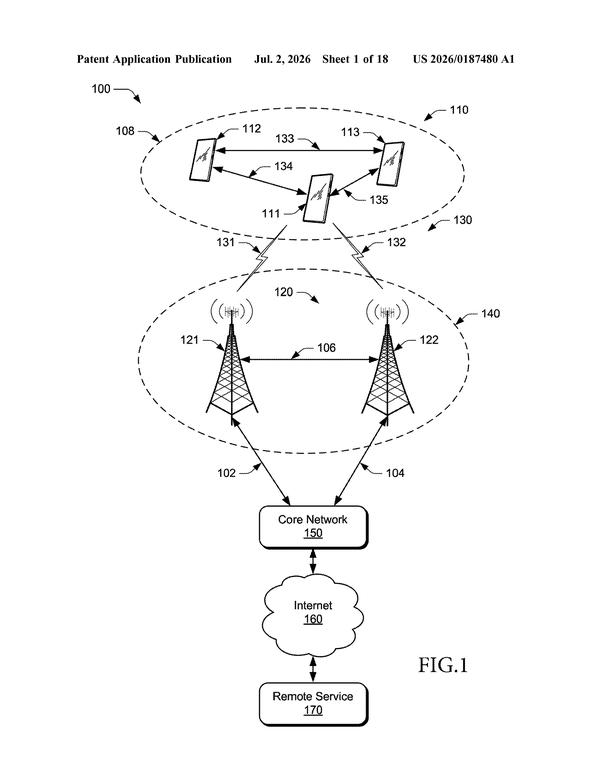
Prior filings in this watchlist focus on blocking data before it leaves the device. This one extends that control to network-level requests, letting the phone intercept and gate what cellular infrastructure reveals to apps.
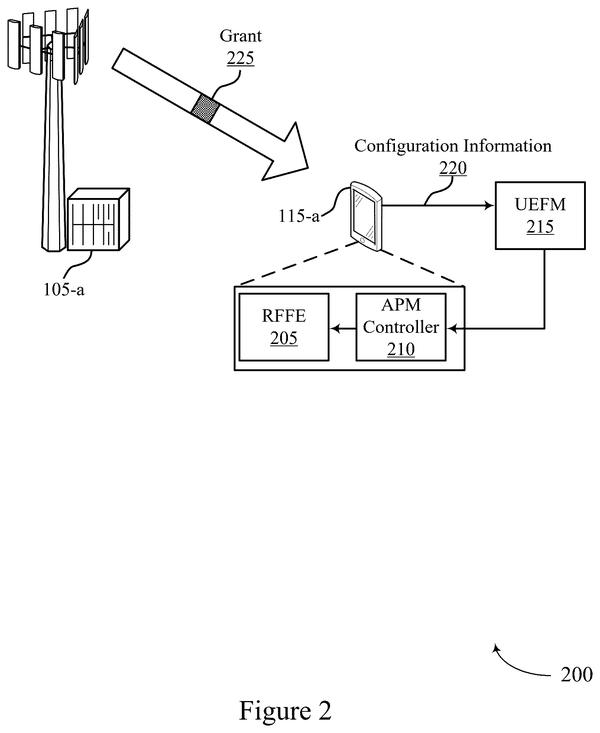
Predictive models running locally on the radio processor itself determine when to power down the modem, keeping the inference entirely on-device rather than relying on network-side signals or cloud computation to manage power states.
Passive voice enrollment sidesteps the need for dedicated training sessions. Intel's approach lets wearables build speaker profiles from ambient speech during normal daily routines, eliminating friction that typically blocks adoption of on-device voice models.
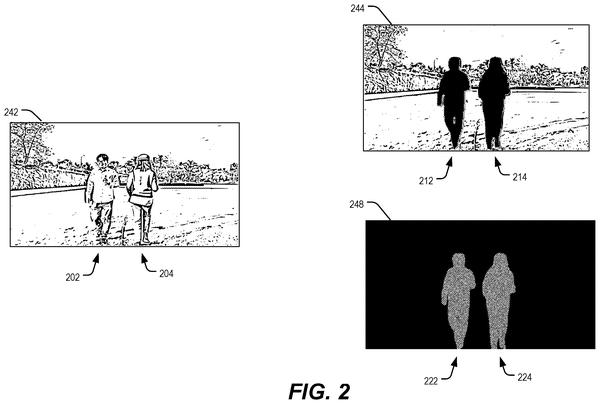
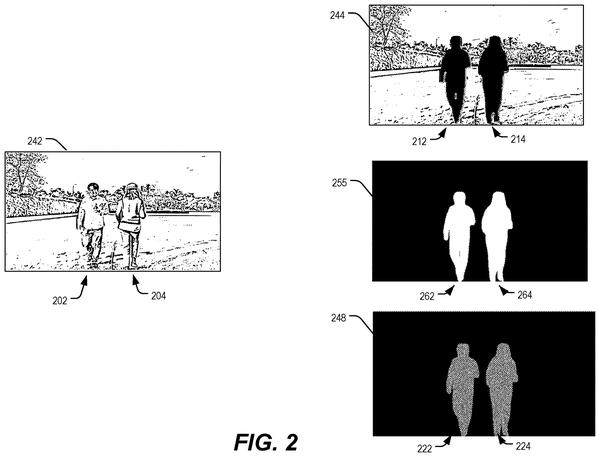
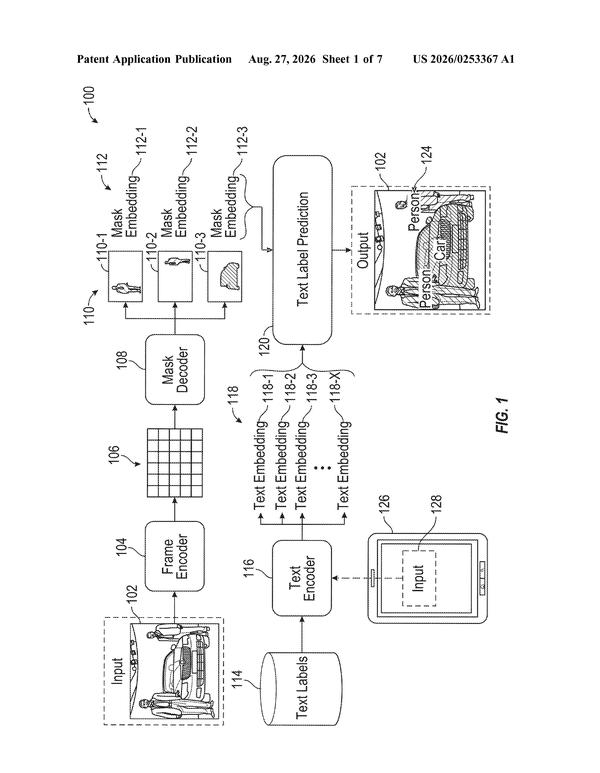
Device-side content filtering extends to video capture itself, letting cameras redact faces and license plates during recording rather than after, so shared footage reveals only what the sender intends.
Protecting only high-risk frames instead of every frame means edge devices can filter video without killing battery life, shifting the privacy work from blanket encryption to selective redaction.
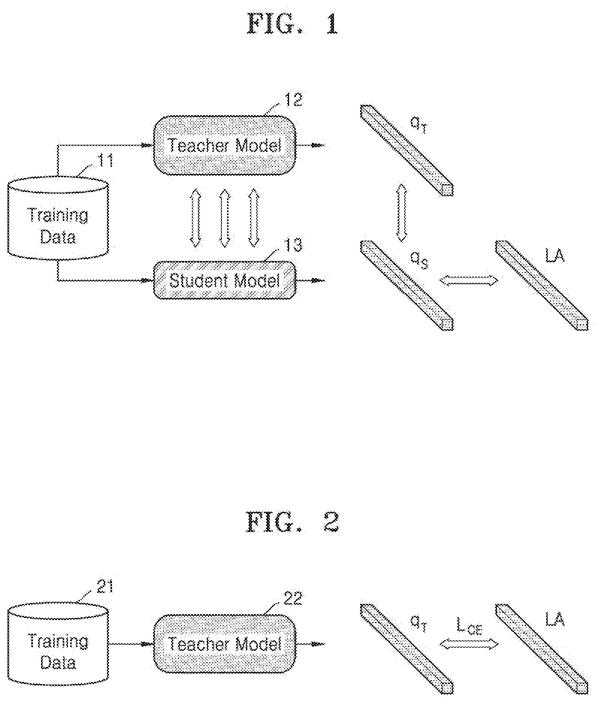
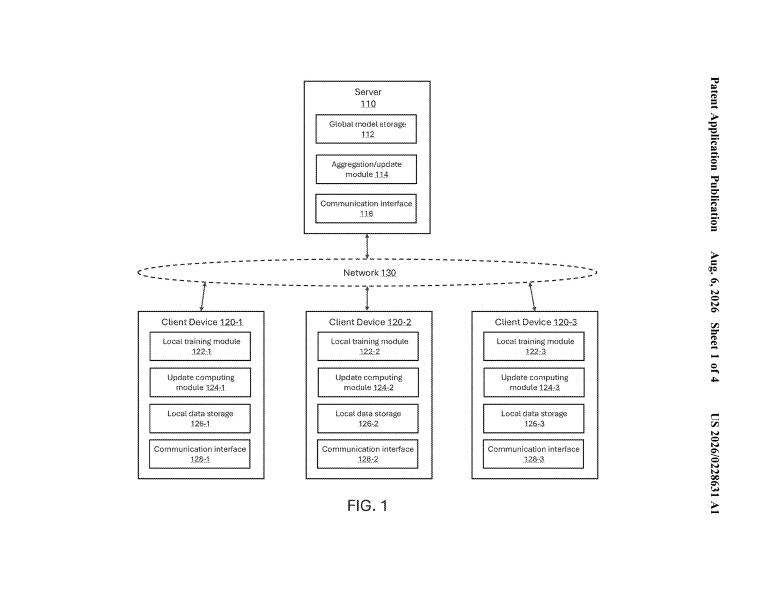
Devices could train efficient models without needing a pre-trained teacher model built elsewhere first, collapsing a two-stage process into one and keeping all training local.
Devices could run portions of AI inference without ever seeing the model weights, keeping trained models proprietary while distributing compute to the edge.
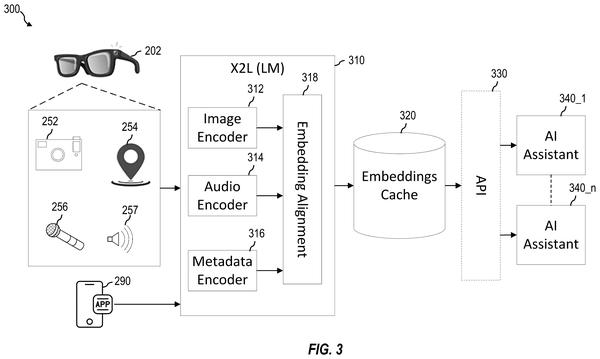
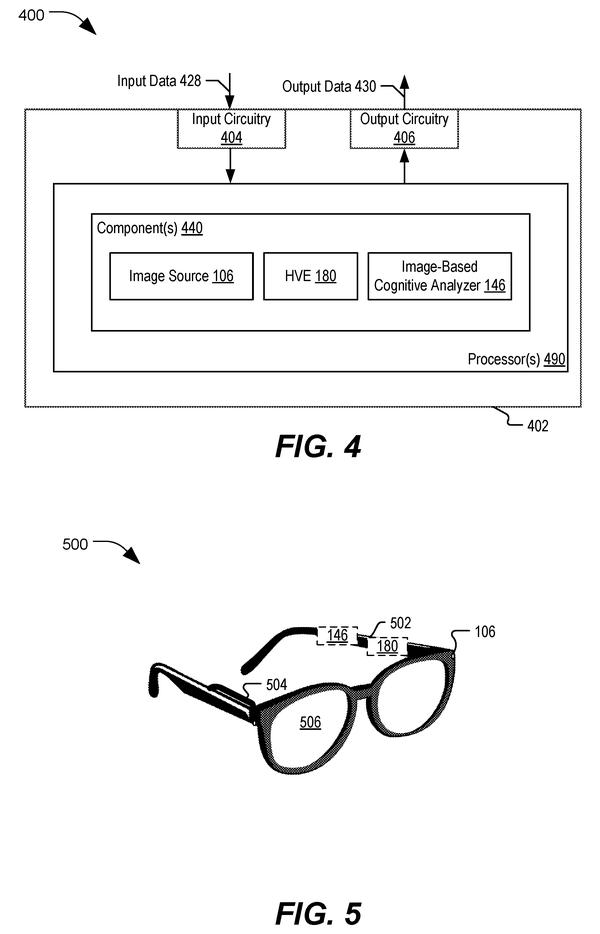
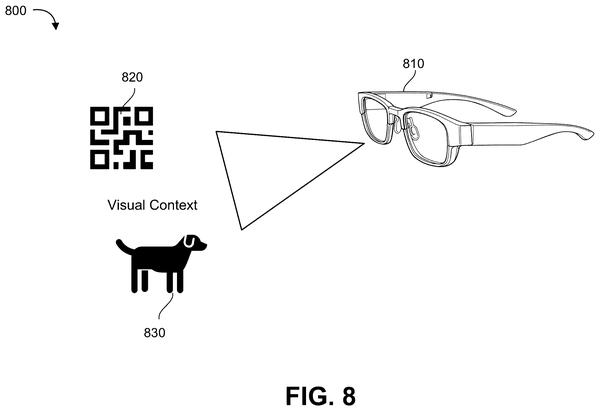
On-device memory buffer for glasses captures key moments throughout the day without transmitting raw video to cloud servers, letting users query their own visual history while leaving sensitive footage permanently local.
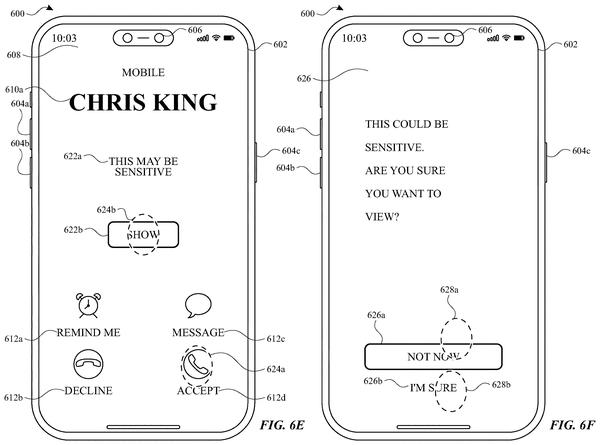
Filters sensitive video messages server-side before they reach your device, letting you preview what's waiting in your call log without downloading potentially upsetting content first.
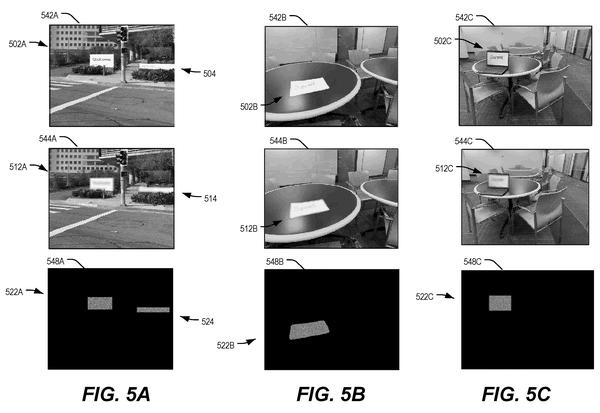
Device-side rules could let phones automatically mask sensitive content during capture based on location or network, removing the need for manual editing afterward. This shifts privacy filtering from post-production to the moment of recording.
Deduplicating training data across federated networks: Sony proposes filtering which devices contribute to shared model updates, preventing redundant information from wasting bandwidth when thousands of edge devices train one AI simultaneously.
Encrypted face redaction within a single video file eliminates the need to maintain separate blurred and unencrypted copies, reducing storage and transmission overhead for privacy-sensitive footage like dashcam recordings.
Previous efforts to keep raw network data private relied on federated learning. This patent adds a gating mechanism that decides which nodes can actually participate in the shared training.
Checksums on federated learning transmissions let the network detect when wireless interference corrupts the aggregated model updates, preventing silent data corruption across distributed training rounds.
The existing work here focuses on blocking data transmission to servers; Google's filing moves the filter itself onto the browser, letting it evaluate ad candidates locally before any selection leaves the device.
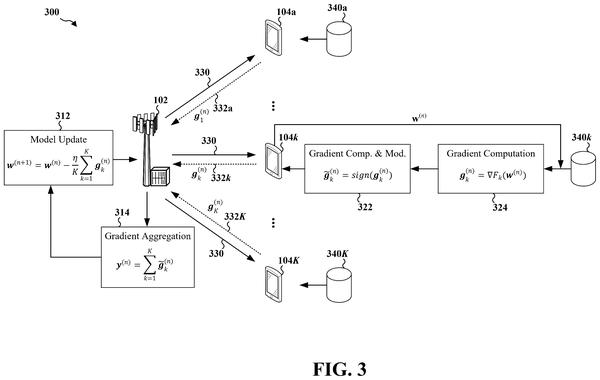
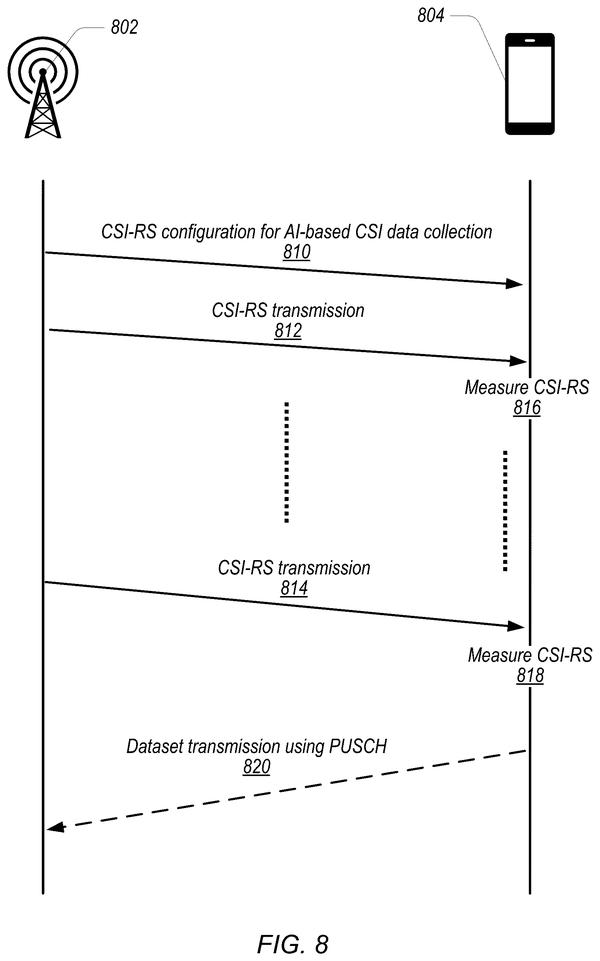
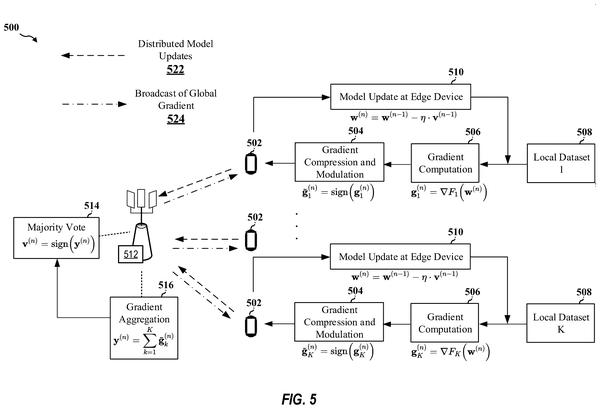
Where federated learning aggregates phone updates over wireless networks, radio noise degrades the final model. Qualcomm's approach uses a mathematical grid to filter out interference before the tower processes each device's contribution.
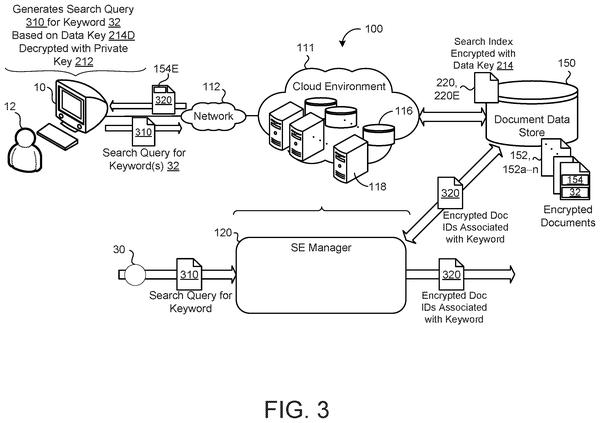
Public-key encryption lets the server index scrambled files without decryption access, preserving search functionality while blocking the platform from reading stored data.
Padding encrypted documents with random noise before AI analysis prevents inference attacks that extract meaning from search patterns alone, shifting the privacy burden from encryption to obfuscation of document characteristics.
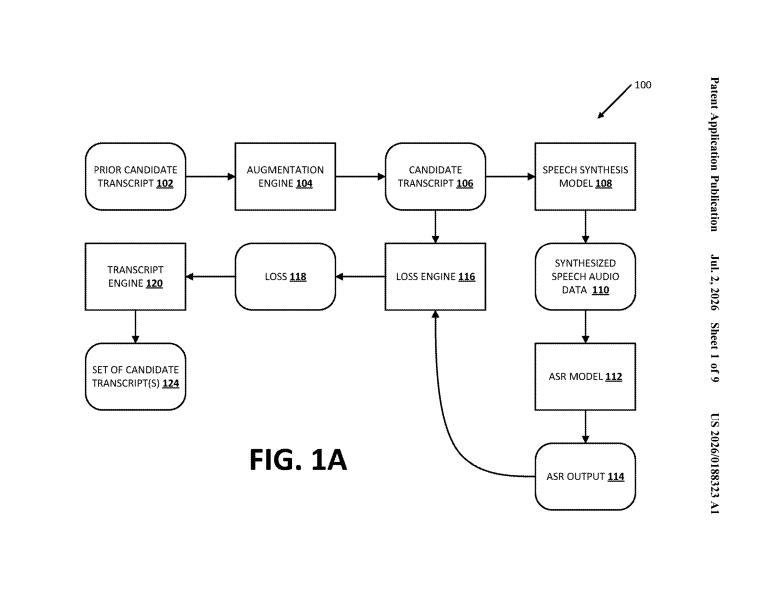
Device generates its own synthetic speech from typed wake words to train the listener, eliminating need to record and store user voice samples during setup. Shifts the training data from personal audio to system-generated reference material.
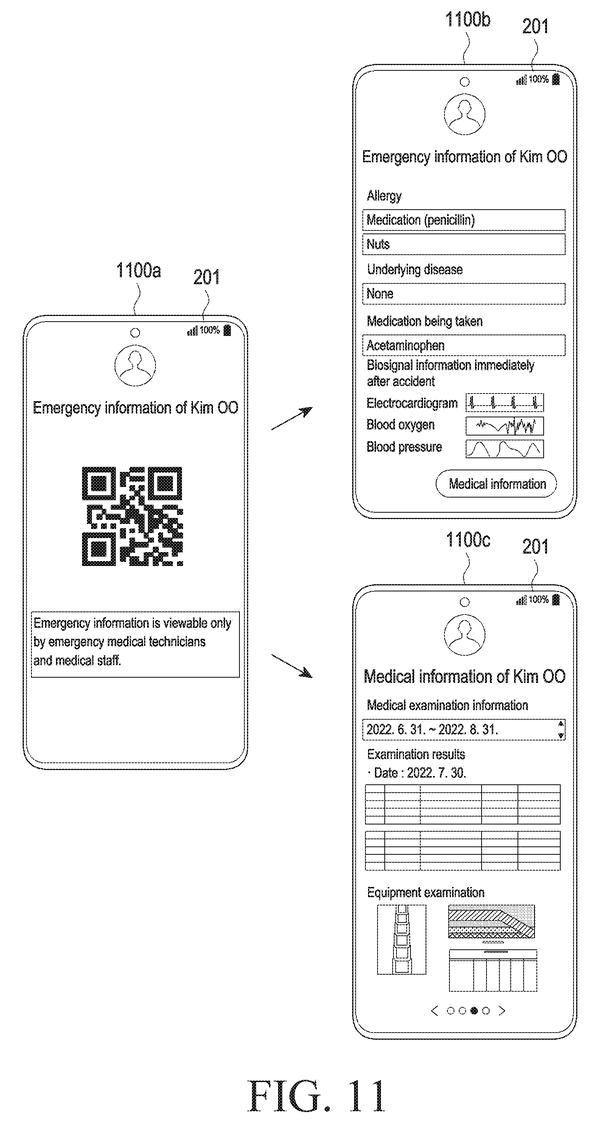
Tiered medical data release on device lets paramedics see critical allergies without unlocking full health history, handling the specific problem of emergency access without general exposure.
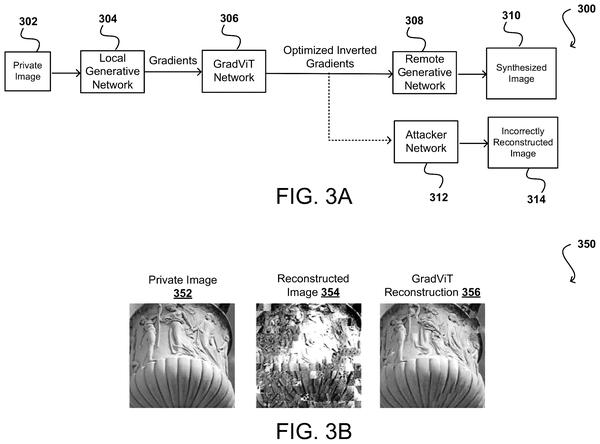
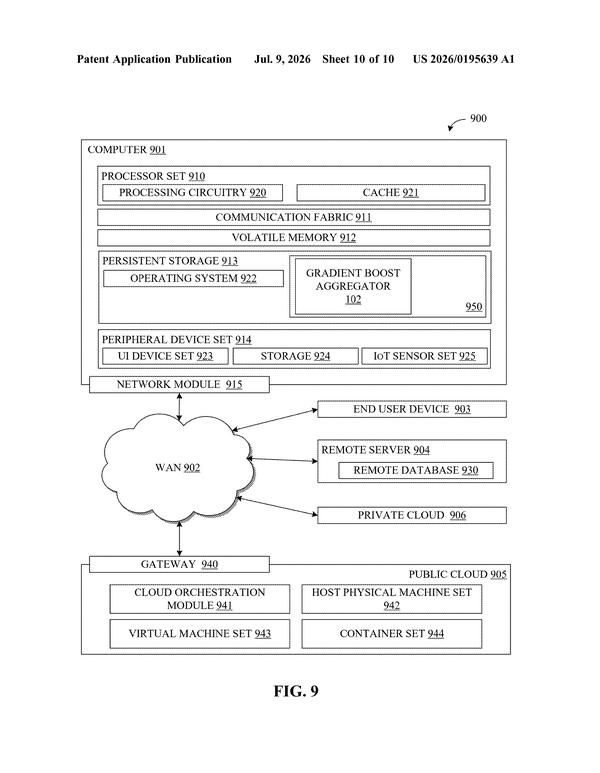
Gradient obfuscation during federated training prevents model updates from leaking enough information to reconstruct source images, moving the protection upstream from cloud storage to the exchange itself.
Qualcomm's approach keeps on-device wireless AI functional by falling back to local processing when network data unavailable, sidestepping the need to expose incomplete datasets to cloud inference.
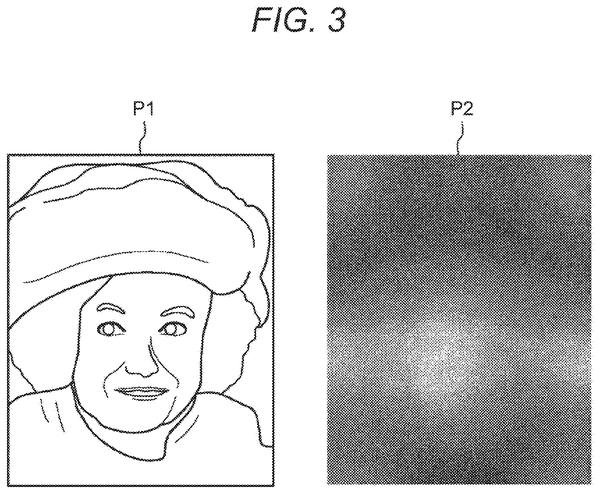
Extends the hardware approach: instead of scrubbing data after capture, Sony's optical filter garbles faces before the sensor records anything, eliminating the clearimage threat inside the device itself.
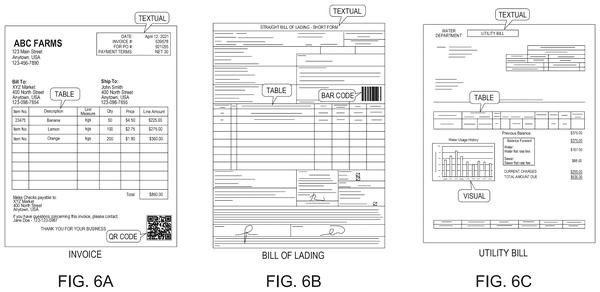
Using visual layout patterns instead of document content lets the system sort confidential paperwork without training on actual samples, sidestepping exposure of sensitive data while classifying invoices, bills, and similar records.
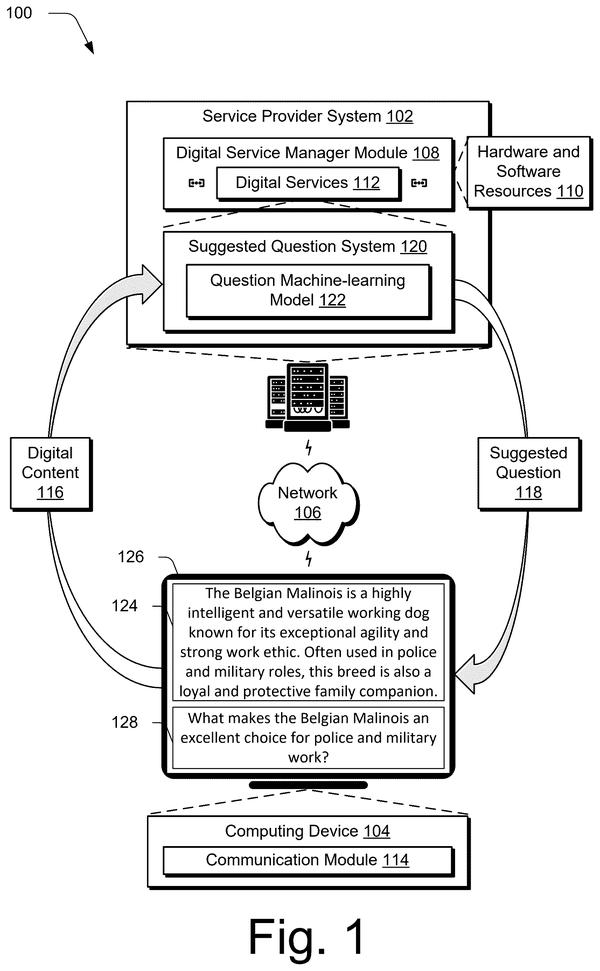
Compressing question-suggestion AI small enough for on-device execution sidesteps uploading sensitive documents to external servers, addressing user reluctance to share contracts or medical records with cloud services.
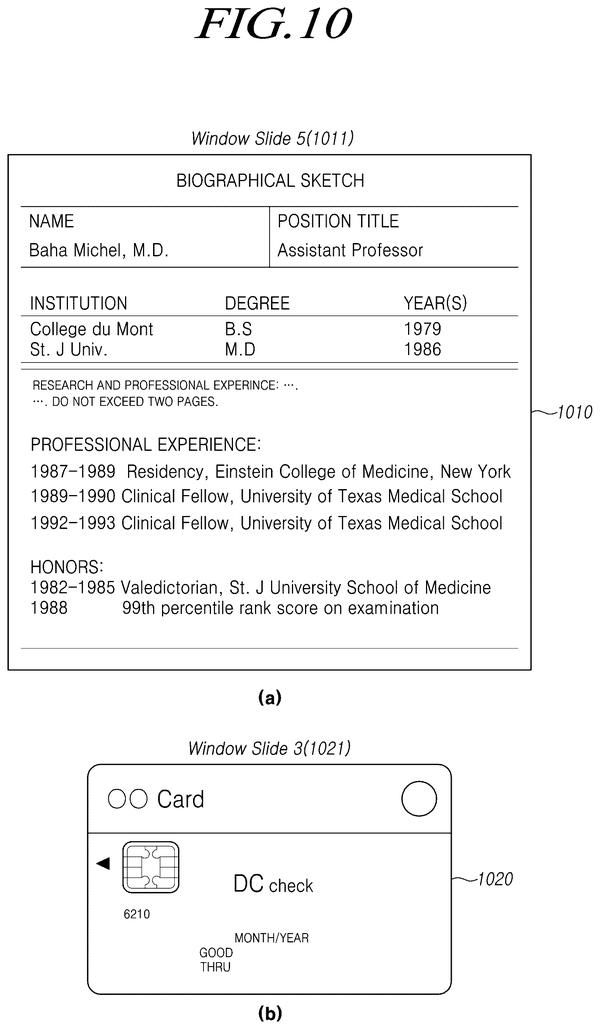
Local document classification strips away headers, footers and irrelevant text before AI processing begins, reducing noise and processing load on sensitive personal documents.
Isolating model training per advertiser through private base model copies prevents competitive designs and performance data from pooling into a shared system that all advertisers can indirectly influence.
The patent confirms the watch focuses on fitting model training itself onto edge devices, not just inference. OpenAI's approach probes available memory to pick the fastest compatible training method rather than forcing one strategy onto constrained hardware.
Routing data through the same processing layers multiple times lets smaller models match larger ones' performance without adding parameters, reducing the memory footprint needed for on-device deployment.
Shared memory workspace lets phones generate multiple AI responses without duplicating the full model, moving comparative ranking from servers onto devices.
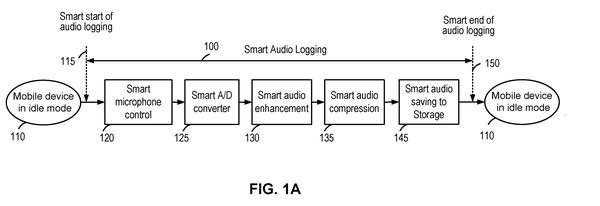
Limiting the microphone's active window to match actual user intent rather than keeping it open for a preset duration reduces the span of ambient audio captured and sent for processing.
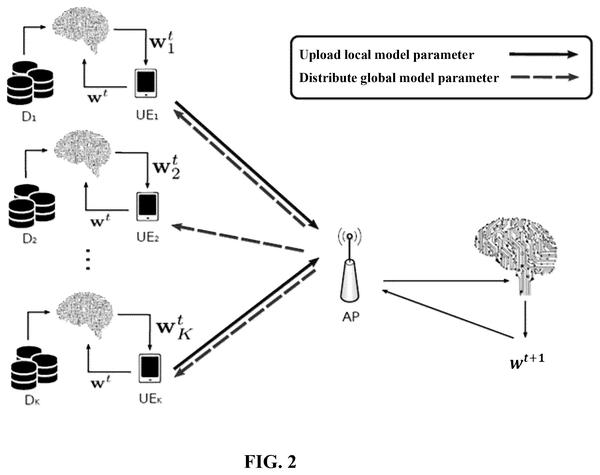
Devices compress uploads by sharing trained models locally first, then sending only the parameter changes to the server. Reduces bandwidth strain when coordinating federated learning across large device networks.
Extends the privacy perimeter to carrier-level signals: preventing telecom infrastructure from linking network quality reports back to individual devices, not just scrubbing data before cloud upload.
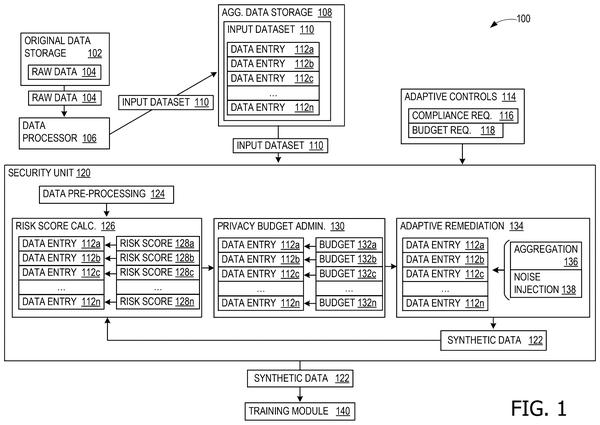
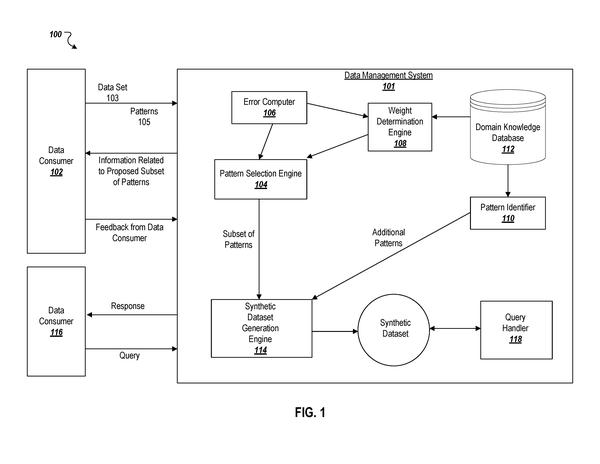
Existing approaches to synthetic data generation treat all fields equally, but this filing proposes weighted protection that focuses anonymization effort on the columns most likely to re-identify individuals.
Within the core challenge of keeping identity data off-device during cloud handoffs, this filing shows how two apps can coordinate access through cryptographic vouching rather than sharing usernames or contact info across system boundaries.
A shared on-device AI service intercepts app requests and enriches them with location and calendar data before inference, keeping raw context away from the requesting apps themselves.
Federated learning needs models that work across phones with wildly different data. Qualcomm's approach adds device-type detection so the model learns from variety without exposing which photos came from which phone.
Extends the on-device scrubbing approach by splitting computational load: the device handles data prep and filtering while offloading only the inference work to cloud servers, reducing the raw material that ever leaves local storage.
Splitting ad auctions across isolated trusted execution environments keeps user data compartmentalized during the real-time bidding process, preventing any single system from accessing the full targeting profile.
Using wireless signals to carry both data and computation simultaneously cuts the bandwidth needed to train models across distributed devices, pushing the math closer to where the data lives rather than centralizing it.
Hardware-level kill switch for face recognition processing lets users disable facial matching entirely rather than relying on cloud-side filtering, confirming a design shift toward capturing less sensitive data at the source.
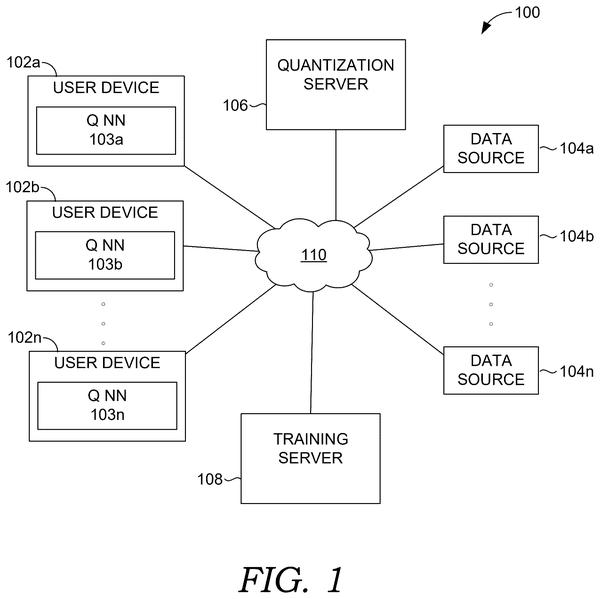
Selective compression of AI model layers preserves accuracy-critical components while shrinking less important ones, letting full-capability models run on-device without quality degradation.
Sensor gating based on environmental context filters data at collection time rather than during transmission, preventing unnecessary capture of sensitive information before any processing begins.
Pre-transmission scanning that flags personal details embedded in documents blocks leaks at the point files move between systems, shifting detection from post-breach analysis to real-time gatekeeping before data ever reaches external infrastructure.
Periodic model blending across distributed devices avoids the central aggregation step that federated learning typically requires, potentially reducing both the synchronization overhead and the window where intermediate models might leak participant data.
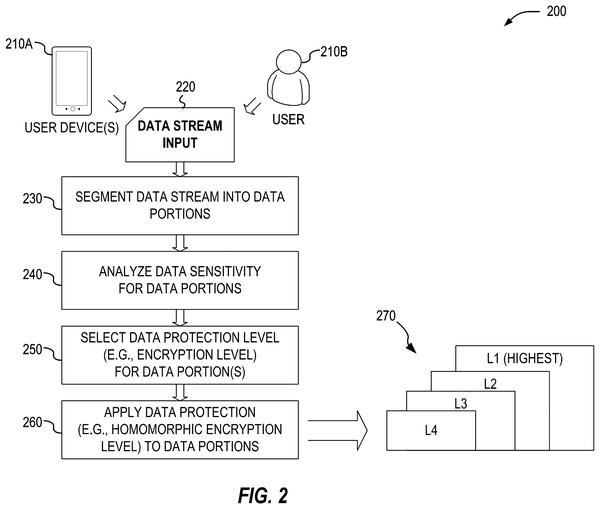
Selective layer protection within neural networks lets some computational steps skip encryption while flagging only the stages that directly process raw sensitive data.
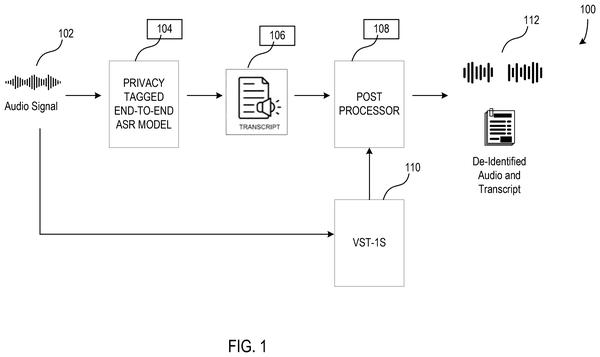
Extends the on-device scrubbing approach to medical audio by combining speech recognition with real-time redaction, keeping sensitive identifiers from ever reaching downstream systems while preserving clinical content for AI processing.
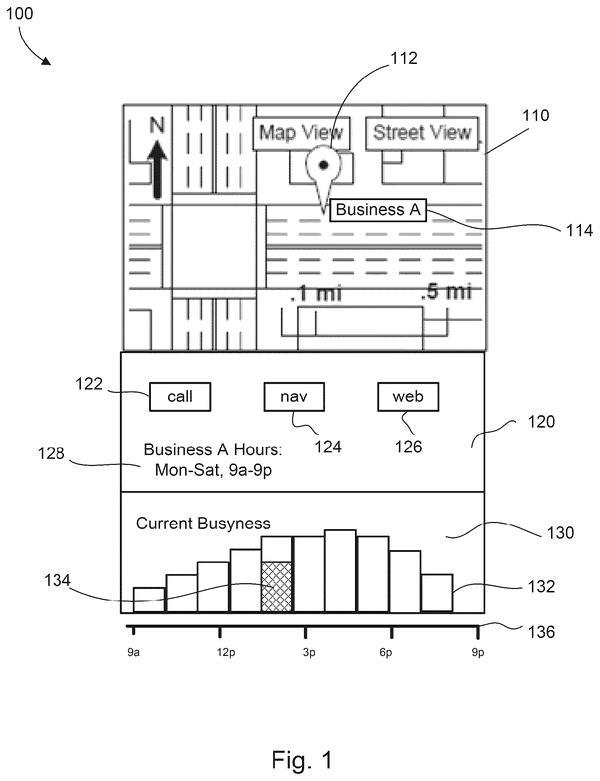
Within live location tracking, this shifts from aggregating opted-in signals to extracting crowd counts without exposing individual movement patterns to Google's servers.
Shifts focus from filtering data before transmission to processing everything, photo analysis, speech tracking, animation rendering, entirely on the device itself.
Continuous camera streaming to an AI assistant gets filtered locally before transmission, reducing both bandwidth and battery drain by processing only relevant frames on-device rather than sending raw video to the cloud.
Extends the federated training angle to biometric verification, showing how identity checks can rely on distributed models instead of centralizing face and fingerprint data during the training phase.
Running ad-request code in a restricted environment lets the browser intercept and filter data before ad requests leave the device, shifting control over what personal information reaches ad servers from websites to the user's local machine.
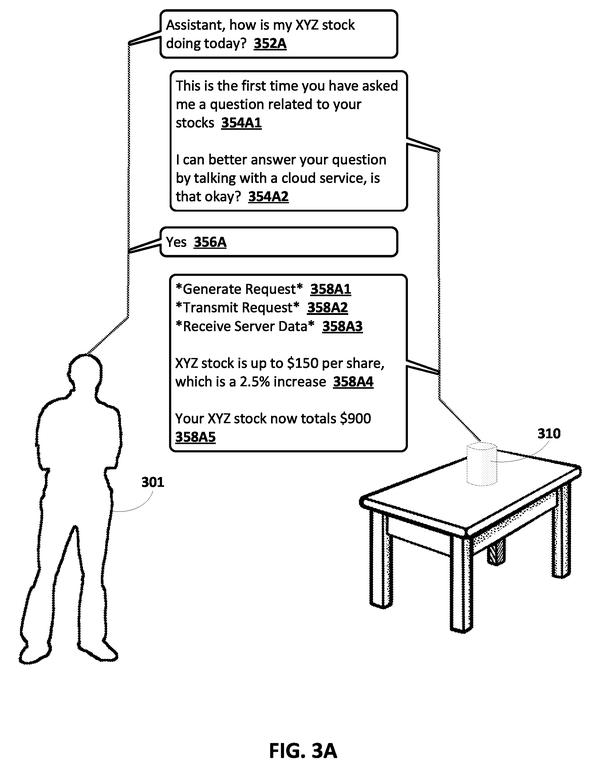
Extends the consent layer: the patent describes detecting when a request requires external services before transmission occurs, giving users a chance to opt for on-device processing or block the handoff entirely.
Federated learning on grid data lets utilities train demand-prediction models locally, then share only the learned parameters rather than raw usage records that could expose occupancy patterns or business operations.
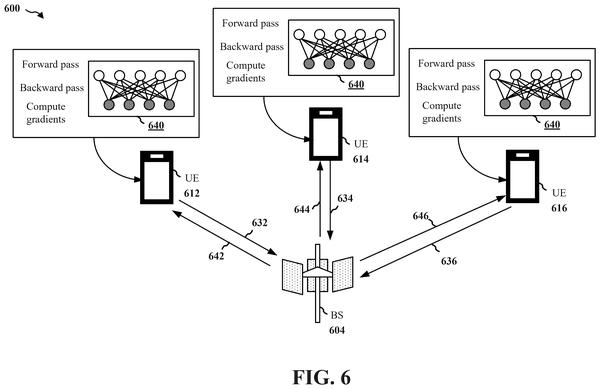
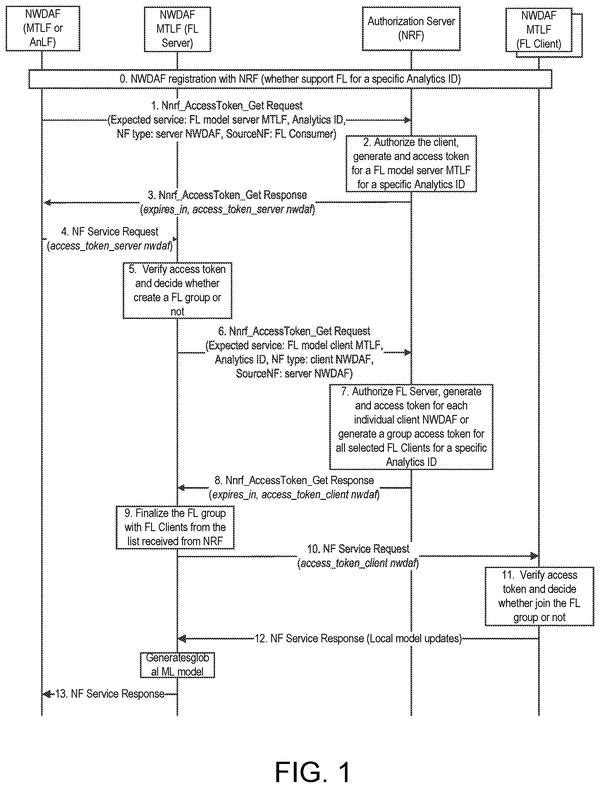
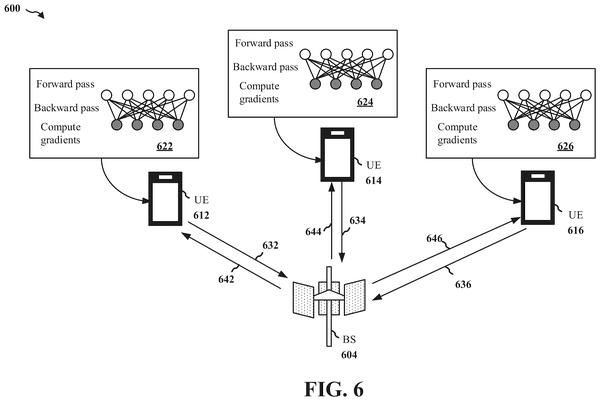
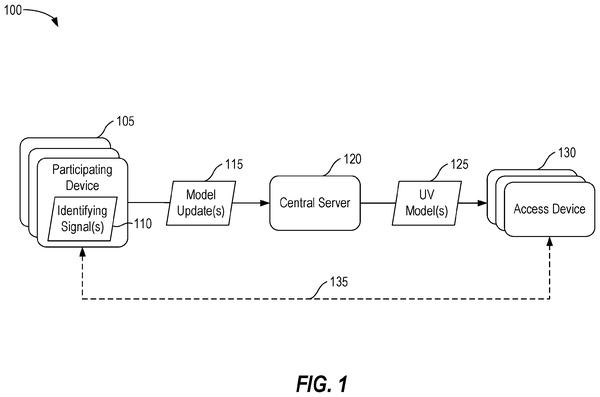
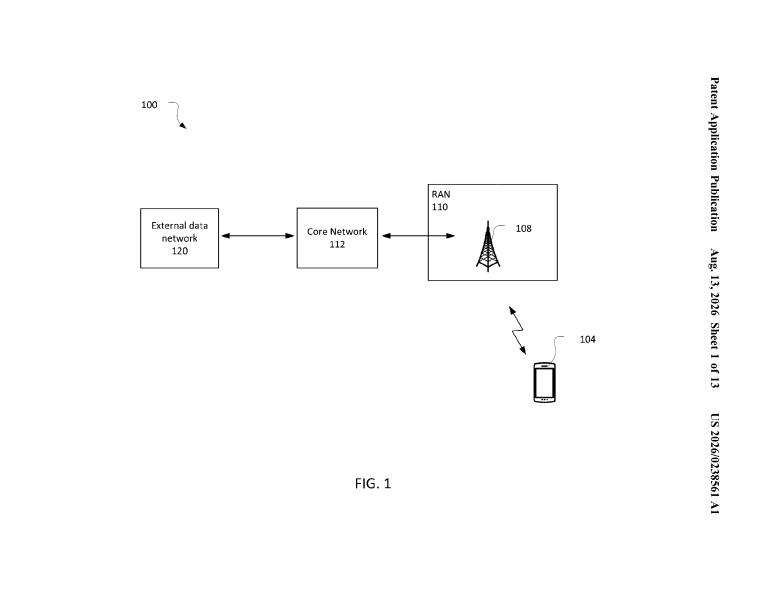
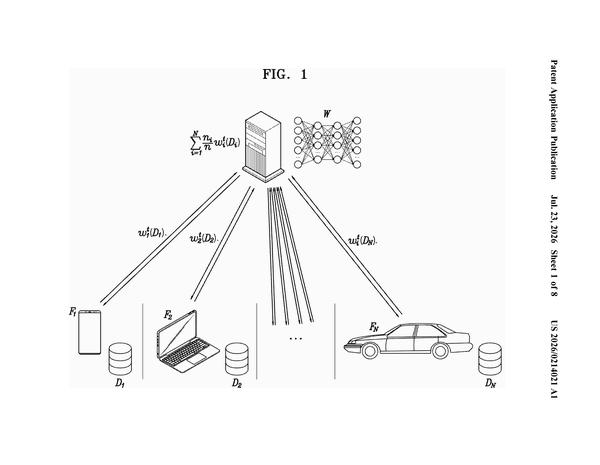
Federated training across cellular networks offers a concrete alternative to cloud-based collection: devices exchange model updates rather than raw data, keeping personal information on-device while still contributing to AI improvement.
Keeping the model compressed and unpacking only one section at a time lets phones run federated learning without hitting memory limits, solving a key constraint on truly local training.
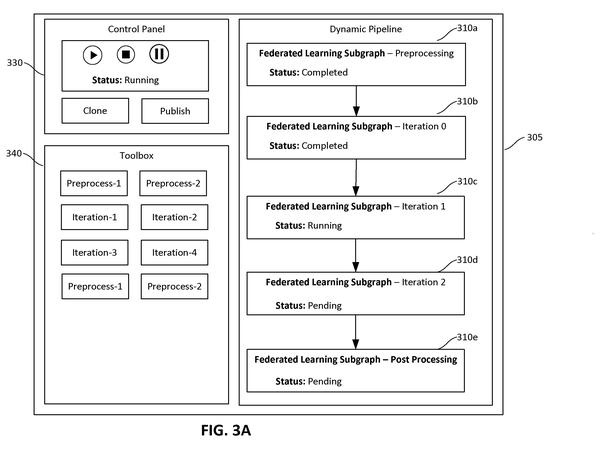
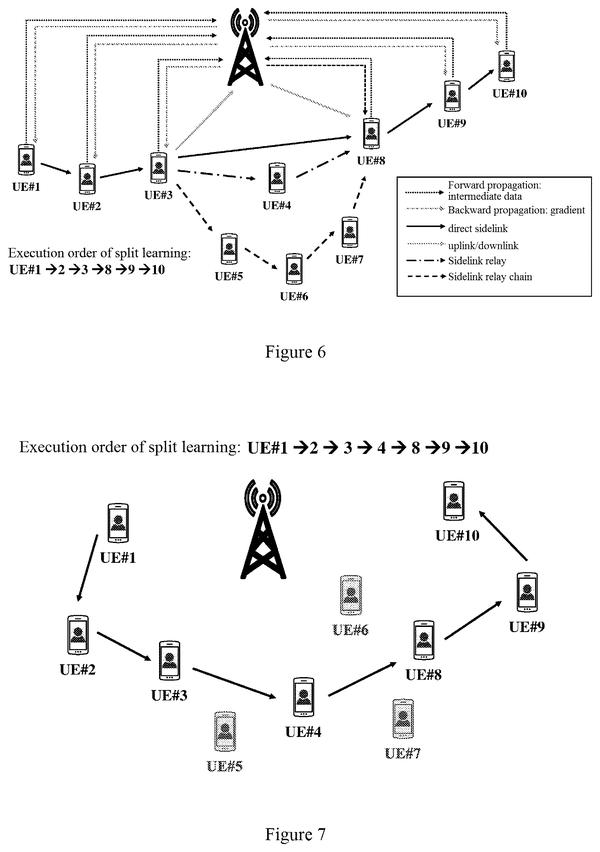
Sequential model updates across distributed machines let each participant train without centralizing sensitive data, advancing federated approaches where the model travels to the data rather than the reverse.
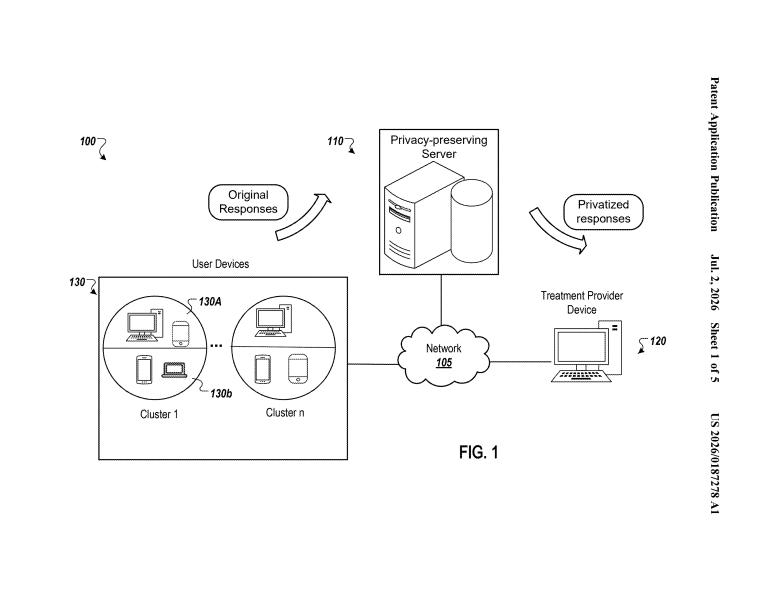
Prior filings focused on scrubbing data before transmission. Samsung's approach routes sensitive responses through the originating device instead, controlling *where* answers go rather than just what they contain.
Devices that filter sensitive audio in real time could let factories monitor equipment without capturing worker conversations, solving the problem of always-on microphones that currently threaten privacy.
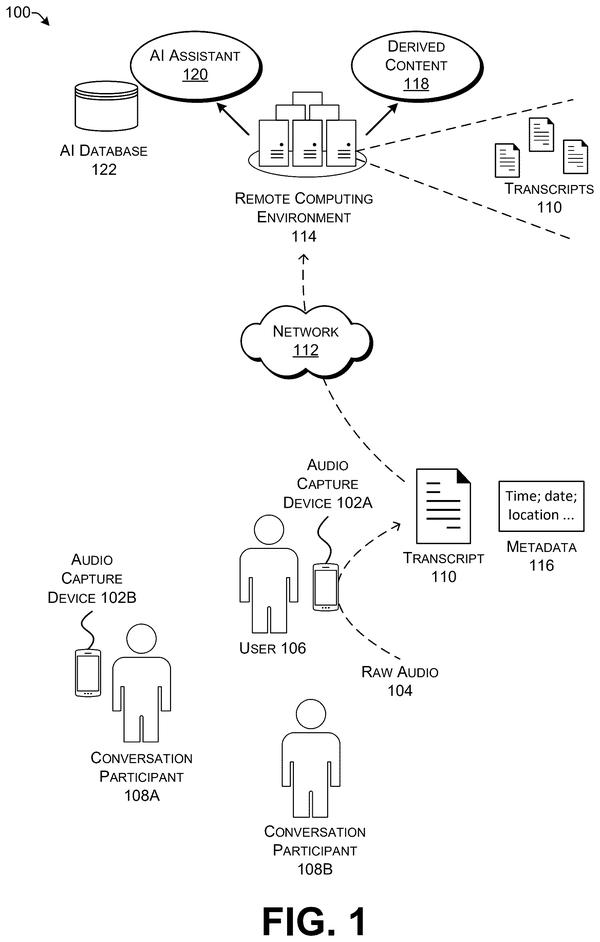
Filtering speaker identity from voice data before transmission keeps cloud AI systems from receiving biometric markers embedded in audio, even when transcription itself happens remotely.
Within the broader privacy push, this pins down how federated learning solves the core problem: models improve from your device's data without that data ever leaving.
Bidirectional knowledge transfer during training keeps the smaller model's real-world constraints visible to the larger one from the start, rather than compressing afterwards when those constraints can't reshape the architecture.
Dynamic early stopping during distributed training eliminates the need to centralize sensitive data, letting each location halt its local model updates once convergence signals sufficient learning.
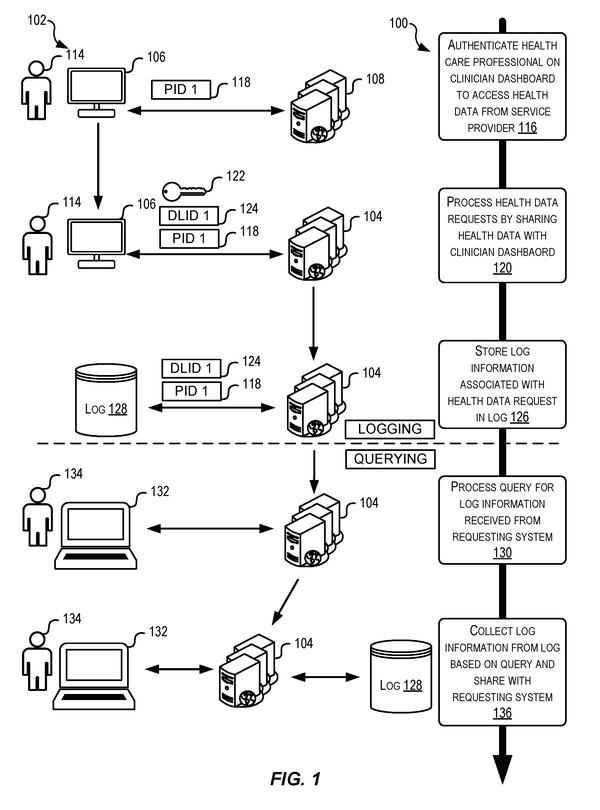
Extends the on-device privacy focus to health records stored in the cloud, adding cryptographic audit trails so patients can verify access without exposing raw data to the system doing the tracking.
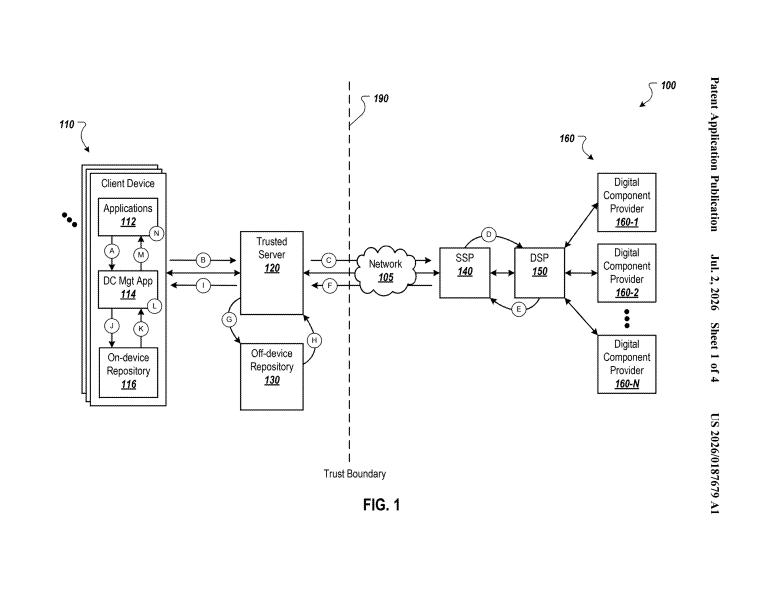
Within the watchlist's focus on filtering sensitive data before cloud transmission, this patent adds a specific mechanism: enforcing a minimum anonymity threshold on browsing context data before any ad system can access it at all.
Synthetic data generation sidesteps exposure by learning statistical patterns from real datasets, then producing fake but statistically valid alternatives, letting researchers share usable data without transmitting actual personal details.
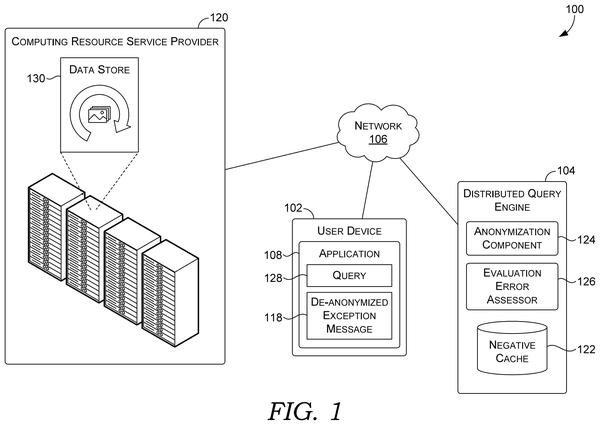
Extends the privacy perimeter from query execution to error handling itself: catches database failures before they expose user data in error messages, plugging a leak that happens silently at scale across large systems.
Phones validating network traffic classification locally, then reporting mismatches back to improve the shared model without exposing raw data streams.
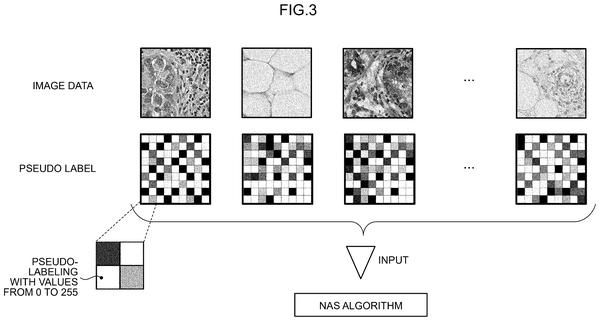
Reducing labeling costs by auto-generating synthetic training data during architecture search, so engineers can optimize network design before collecting expensive human-labeled examples.
If it works, advertisers could match users to ad profiles without any company holding the unencrypted personal data. The patent demonstrates a shift toward cryptographic matching that replaces data exposure with mathematical proofs of identity.
On-device model retraining without catastrophic forgetting means users could teach their phone to recognize custom objects while keeping existing recognition intact, all without uploading training data to the cloud.
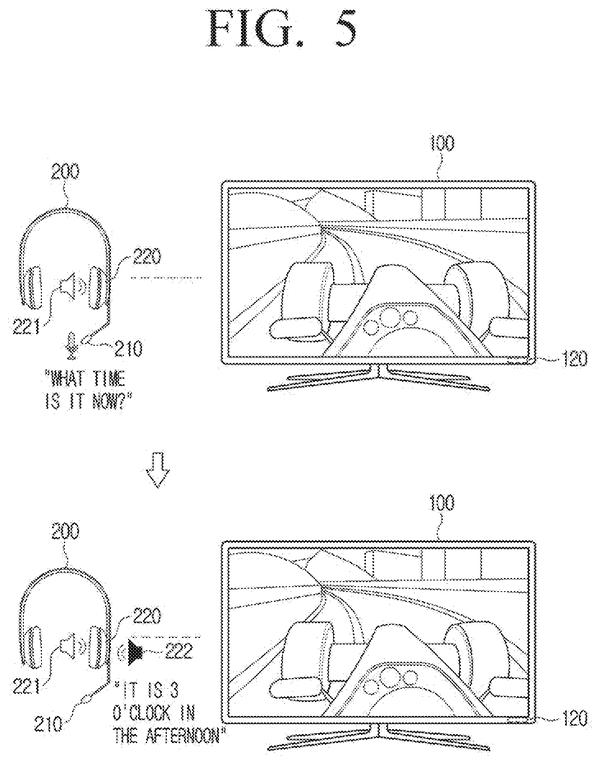
Shared devices can answer personal questions by pulling data directly from a user's phone and discarding it immediately after, avoiding storage of sensitive info on the communal hardware.
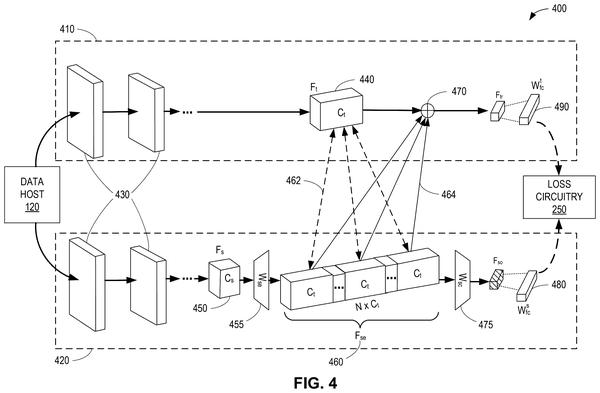
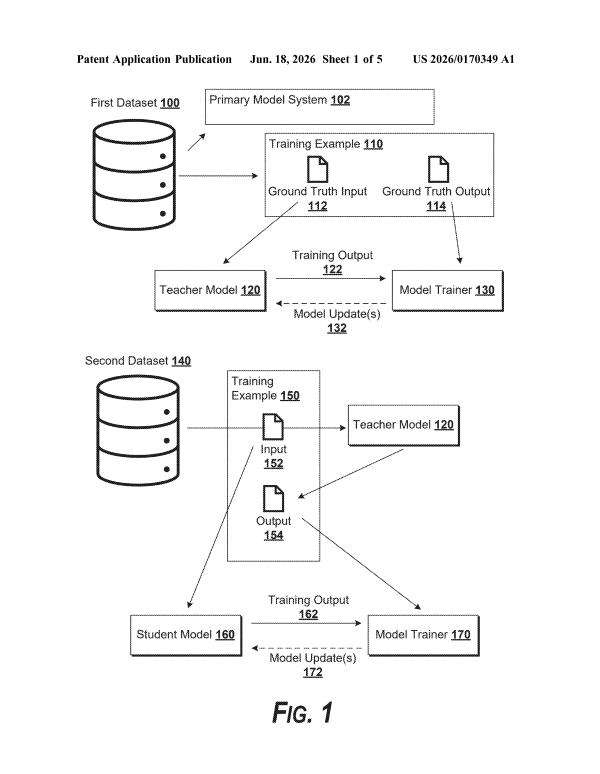
Smaller on-device models need less power but lose accuracy; Samsung's method uses a full model as a teacher to recover that lost precision without bloating the trimmed version.
Your computer's operating system sees nearly everything you do, including where you click inside sensitive apps. Microsoft's latest patent describes a way to encrypt that activity so the OS itself stays in the dark.
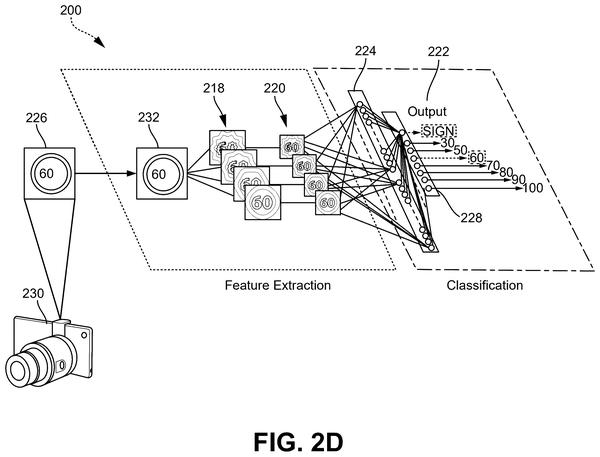
On-device facial recognition means security cameras can identify visitors without uploading face images to servers, keeping biometric data fully local and under user control.
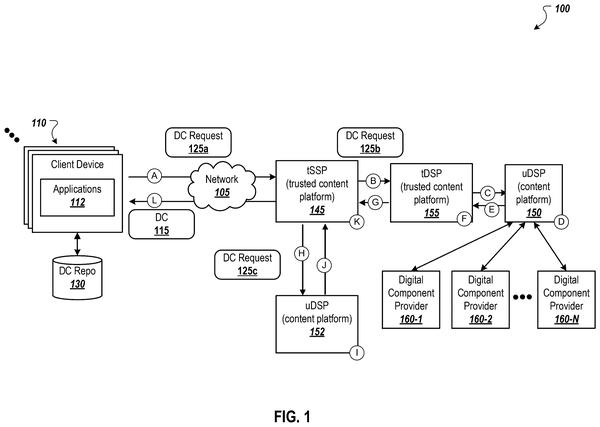
Serving ads to unidentified users without relying on cookies or login states. Microsoft's method abandons the requirement for certain user identity, instead ranking probabilistic guesses about who someone might be to deliver personalized content anyway.
Devices could automatically join networks that match their privacy settings instead of leaving users to manually choose between convenience and exposure, shifting the privacy burden from the user to the connection itself.
Could you prove a photo on your phone hasn't been altered? A new Apple patent describes a system that saves a certified copy of every image before any app ever sees it, creating a tamper-evident record you can check later.
Keeping image generation requests off the network entirely. Google's patent describes running GANs locally on devices, eliminating the server round trip that normally exposes user requests to cloud infrastructure.
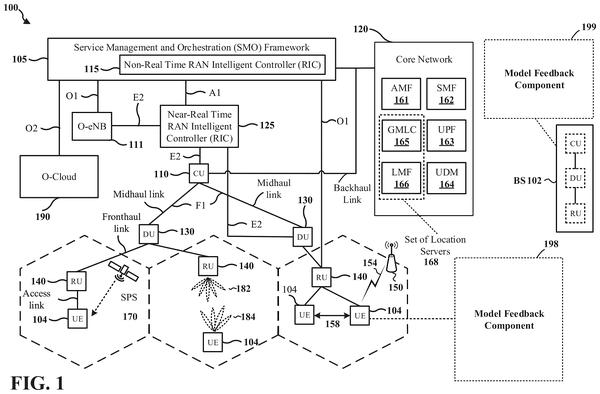
Keeping location inference local: the filing shows how to run positioning AI directly on the device using cell signal data, avoiding transmission of raw location traces to network servers.
Routing decisions based on live device and network conditions mean AI can stay local when it's faster or safer, shifting away from fixed deployment choices.
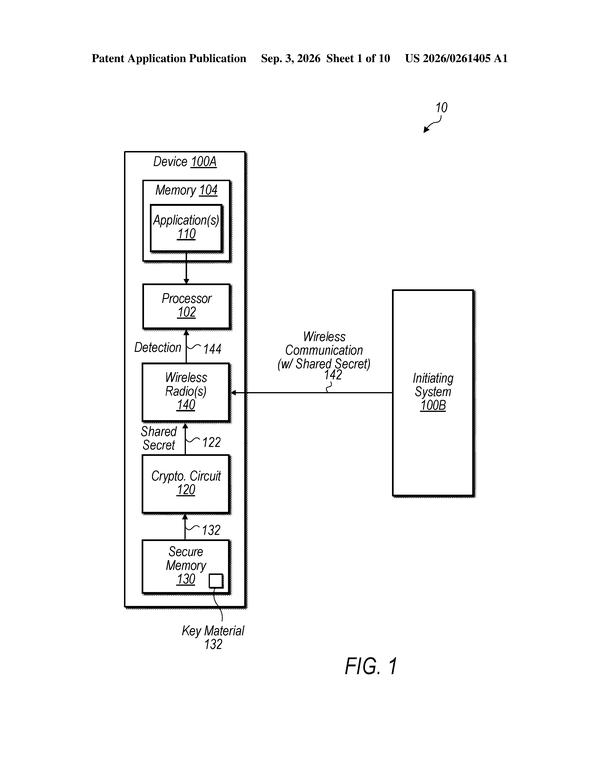
A separate low-power chip intercepts wireless wake signals using hardware-embedded codes that the main processor never sees, keeping sensitive unlock logic isolated from the always-connected processor.
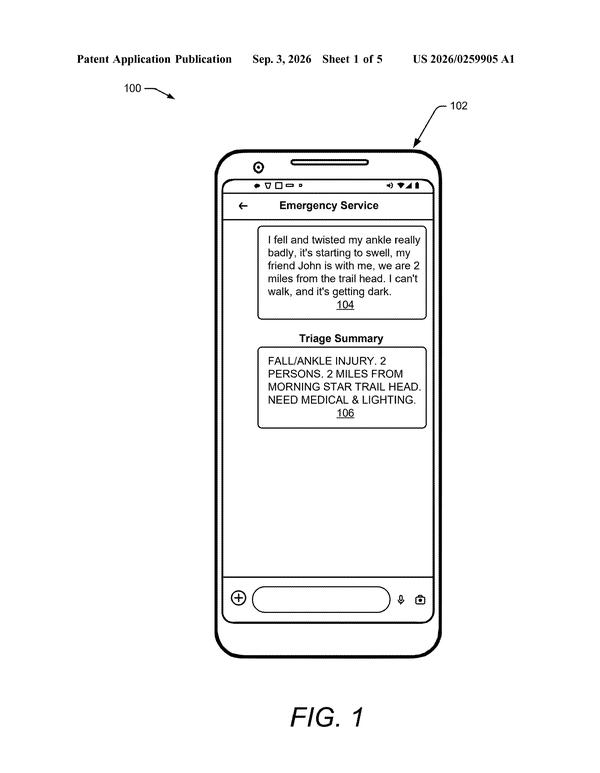
On-device language model processes raw emergency input locally, converting panicked speech or text into structured data before transmission to responders or cloud systems.
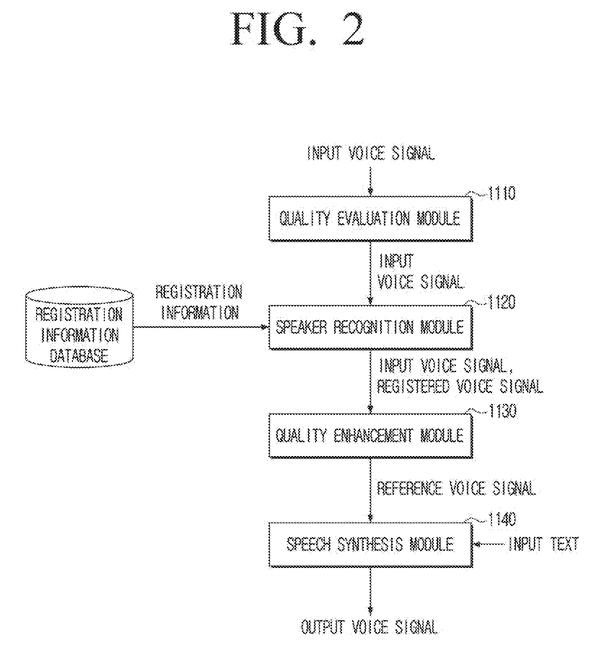
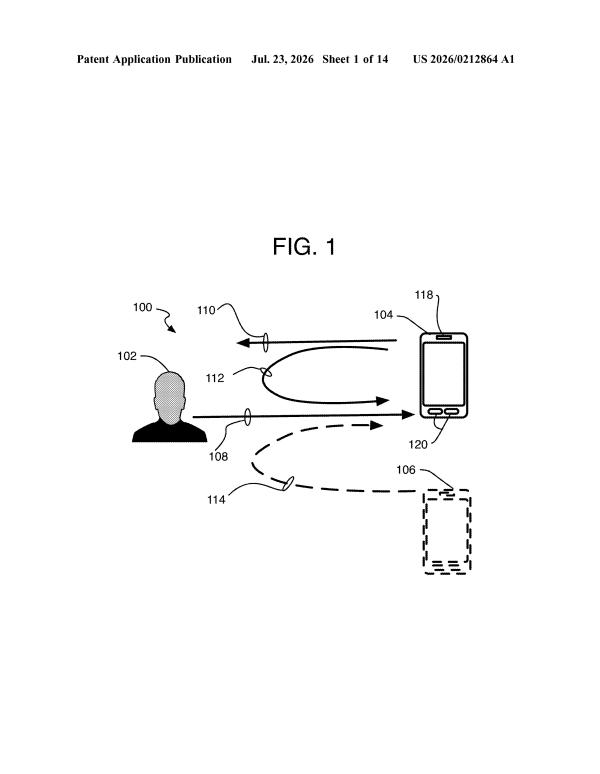
Voice quality scoring on-device triggers local voice model matching to reconstruct garbled input before sending to the assistant, keeping the correction loop offline rather than uploading poor audio to cloud services for reprocessing.
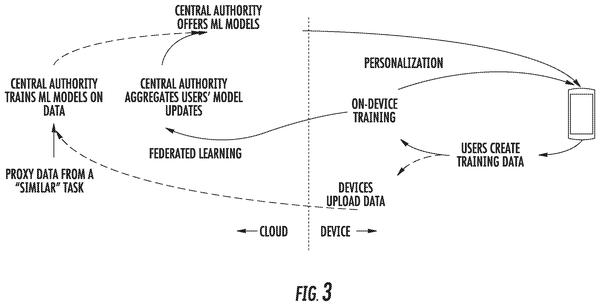
Within the broader privacy push, Sony's method shifts focus to the training stage itself, using public proxy data rather than trying to sanitize restricted datasets before use.
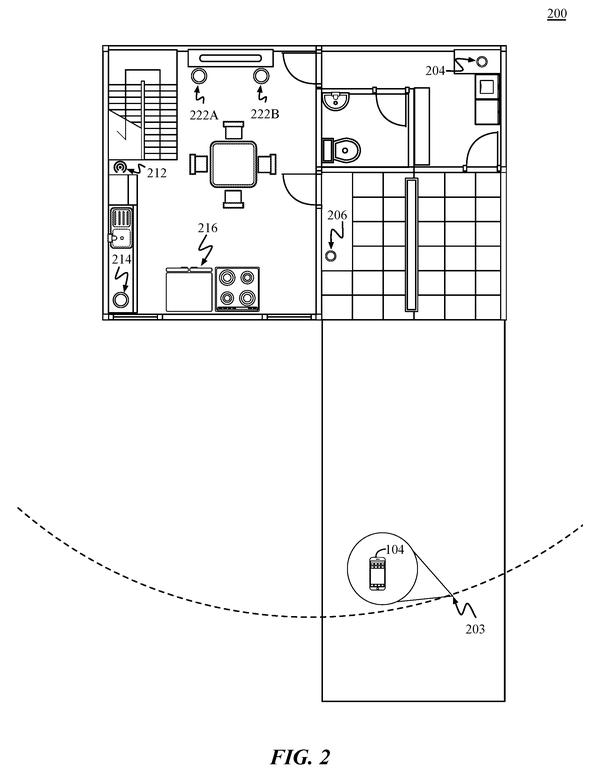
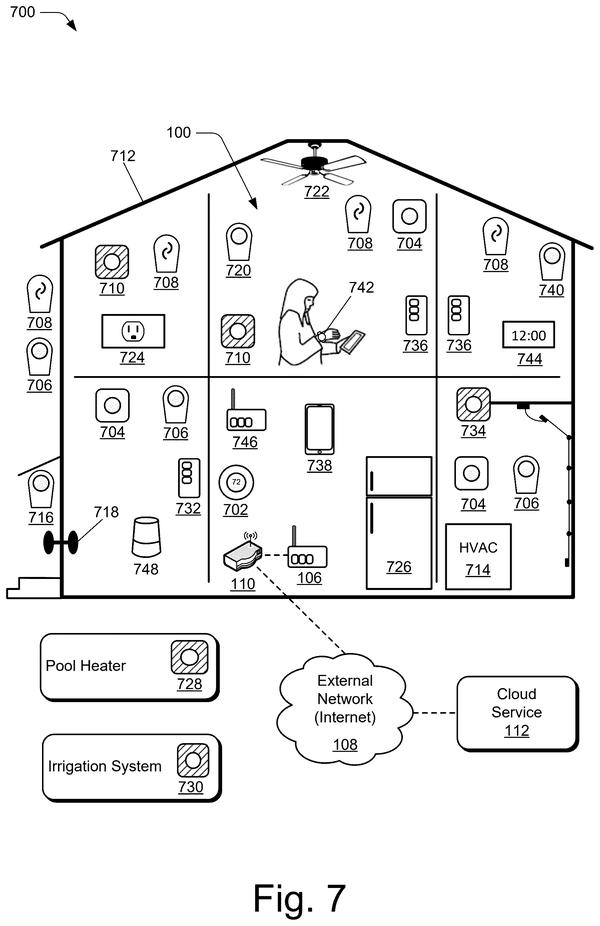
Where the on-device AI privacy push meets smart home infrastructure: Google's hub acts as a local relay, letting edge devices consume AI insights without individual cloud connections.
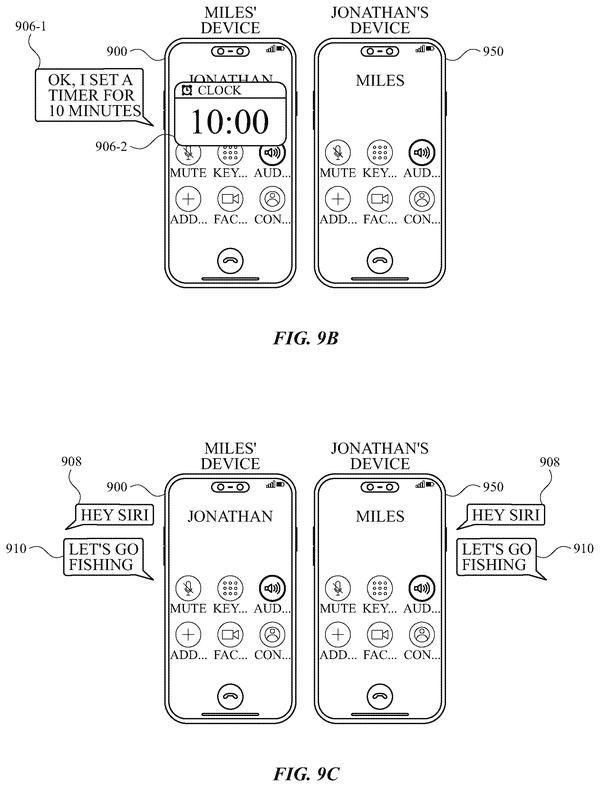
Detecting active phone calls lets Siri dynamically adjust data handling mid-session, keeping third parties out of the loop when someone else is already on the line.
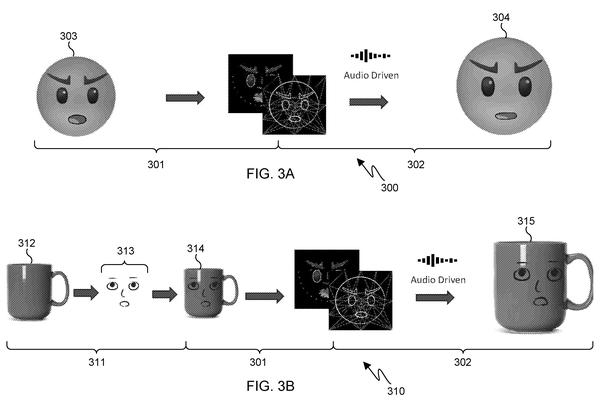
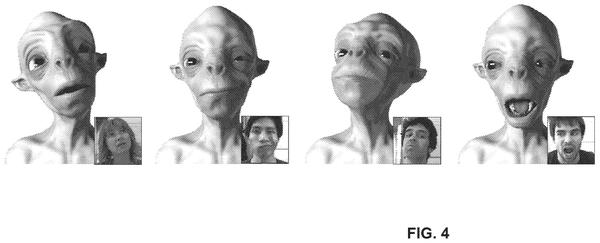
Keeping facial models local during setup and animation sidesteps uploading raw biometric data to train or run face-matching systems, letting the device build personalized recognition profiles without cloud dependency.
Devices could skip continuous video recording and process images only after audio or motion detection triggers them, reducing the raw data that needs privacy handling on the device or sent elsewhere.
On-device object detection at the sensor level means raw pixel data never enters the processing pipeline, eliminating the upstream exposure window that occurs when cameras transmit unfiltered images to external processors.
Deciding when to activate power-saving modes locally keeps the phone from broadcasting usage patterns to servers, eliminating a data leakage vector that currently exists even when cloud sync is disabled.
Device-side learning removes the need to upload video footage to a server to train camera AI on new objects, keeping raw footage contained while expanding what the camera can recognize without redeployment.
On-device image analysis becomes practical when phones can compress video frames into compact summaries before running detection models, eliminating the need to process or transmit raw pixel data.
Compressing video frames locally before AI analysis lets glasses extract meaning from dense visual data without transmitting raw footage, shrinking what needs processing on-device.
On-device filtering gains a practical point of entry: when apps request card credentials, Apple's secure chip intercepts and handles the exchange, keeping raw card data off the requesting app entirely.
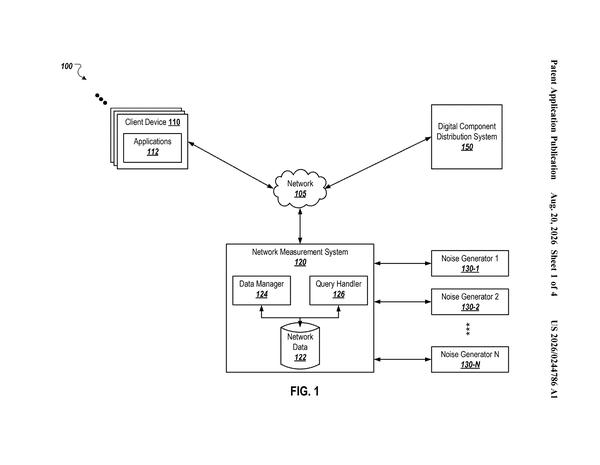
Distributing noise generation across separate servers means the privacy layer survives even if individual machines are compromised or malicious, eliminating the single point where an attacker could strip protections from raw data.
Distributed location matching on the device lets advertisers reach users by geography without centralizing coordinates on any server, extending the privacy-by-design model from data filtering to ad selection itself.
Encrypted intermediaries between apps and Bluetooth accessories prevent the pairing handshake from exposing device identity to companion apps that shouldn't see it, narrowing what data flows during the connection setup phase.
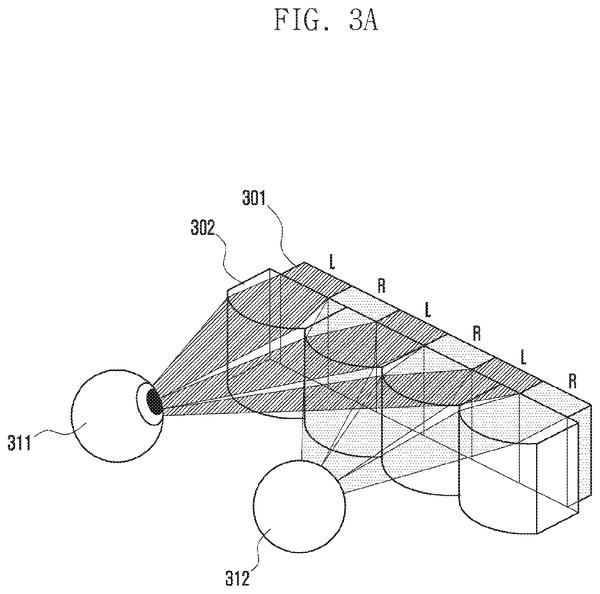
A display that geometrically distorts sensitive content based on viewing angle keeps passwords and financial data unreadable from side glances, shifting the privacy perimeter from software detection to the physical properties of the screen itself.
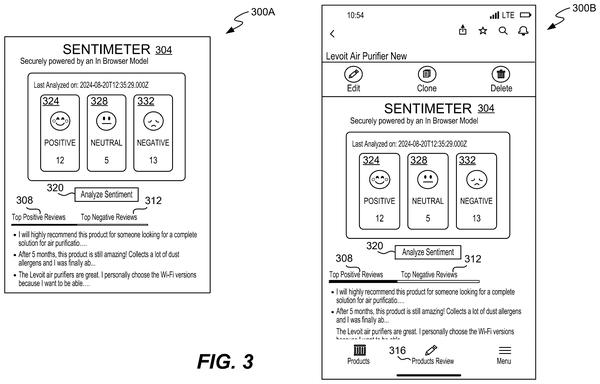
Running inference inside the browser eliminates the network round trip that currently forces sensitive data off-device, addressing the latency and exposure cost of cloud-dependent AI in real-time applications like clinical documentation.
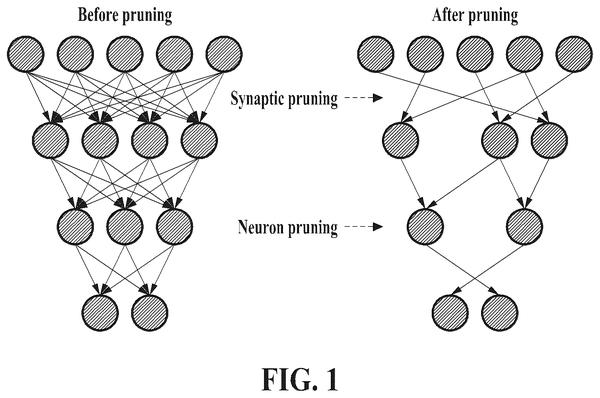
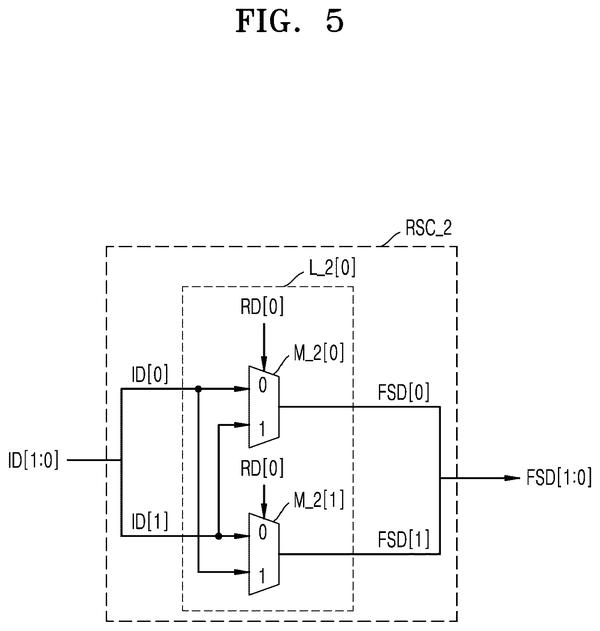
Samsung is patenting a way to scramble data inside a chip before encryption even begins, using a carefully sized network of switching circuits that guarantees every possible output is equally likely.
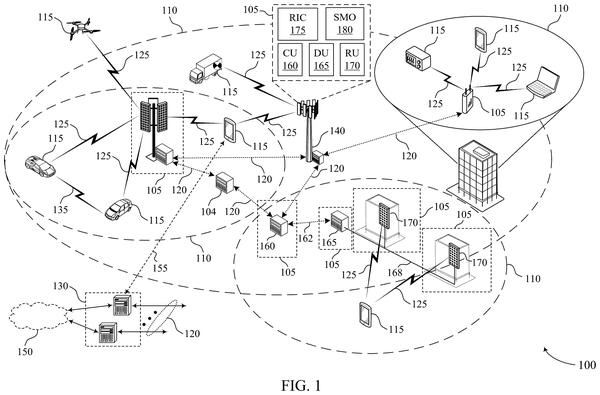
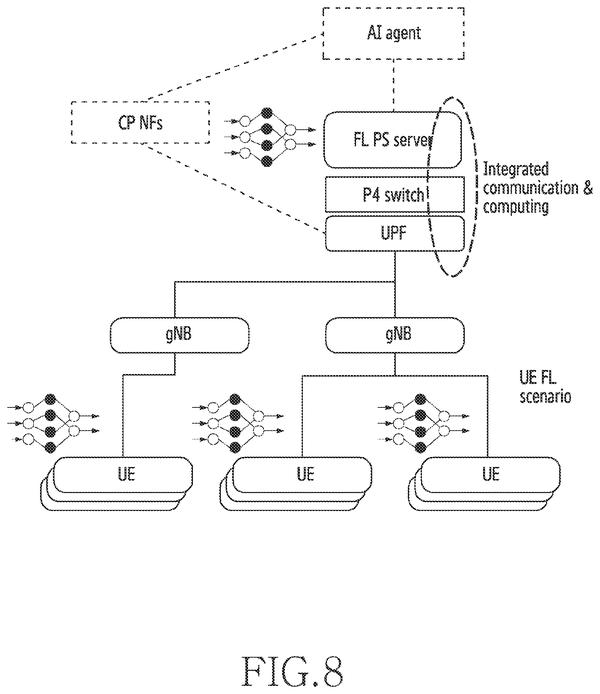
Routing federated learning updates through optimized 5G paths cuts the bandwidth needed to coordinate model training across multiple devices, letting hospitals or clinics pool AI insights without moving raw patient data.
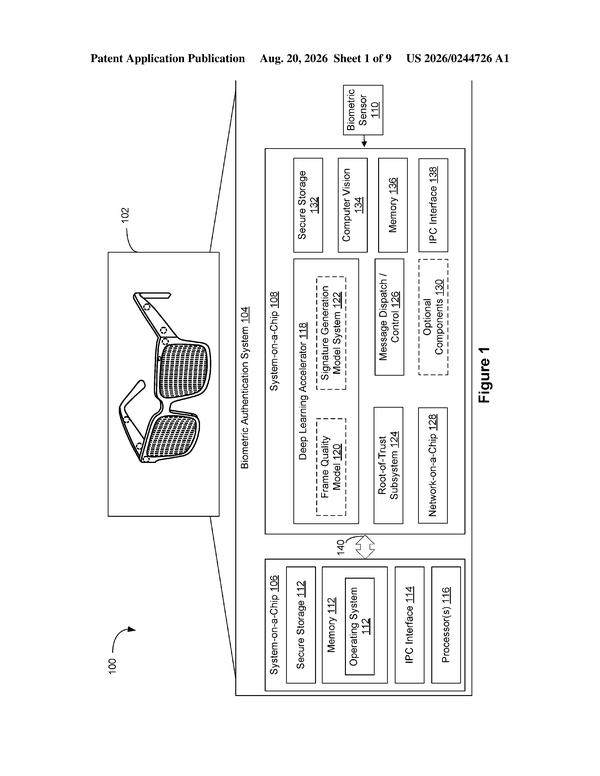
A separate hardware boundary isolates biometric processing from the main processor, preventing the wearable's general software stack from ever accessing raw fingerprint or face data, shifting from logical separation to physical chip isolation.
Running inference locally first to filter queries down to essentials confirms the strategy of using device-side models as privacy checkpoints rather than just preprocessing layers, keeping sensitive context from ever reaching remote systems.
On-device personalization could finally break the feedback loop where servers collect raw behavioral data to improve recommendations. This filing shows how a model can learn user preferences through local processing, sending only aggregated insights upstream.
Coordinating model versions across devices requires tracking which training data belongs to which model update. Apple's patent covers the infrastructure needed to keep distributed models synchronized without mixing datasets across phones, tablets, and servers.
Distributed teams can now optimize which network design performs best while keeping data locked in place, solving the architecture selection problem without centralizing training.
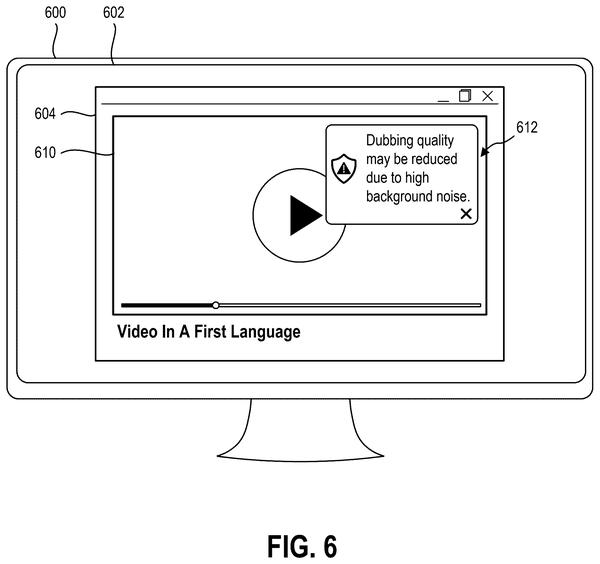
Filtering degraded AI output before playback requires local quality scoring, which keeps dubbing decisions off remote servers and prevents transmitting low-confidence audio clips that might expose the original dialogue.
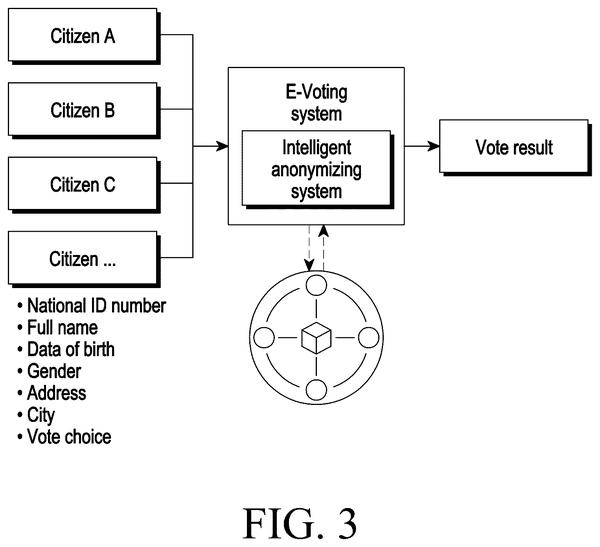
A filtering layer on the device removes personal details before blockchain recording, extending the privacy-scrubbing approach from cloud AI to distributed ledgers where data permanence makes exposure especially costly.
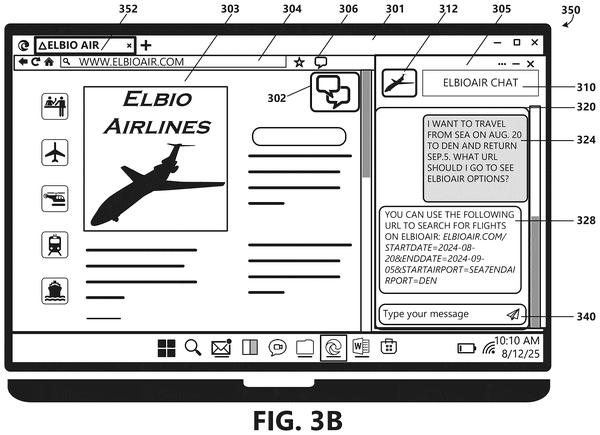
Moving AI inference from servers to browsers keeps user interactions off company infrastructure entirely, eliminating the server-side data collection that cloud-based chatbots require.
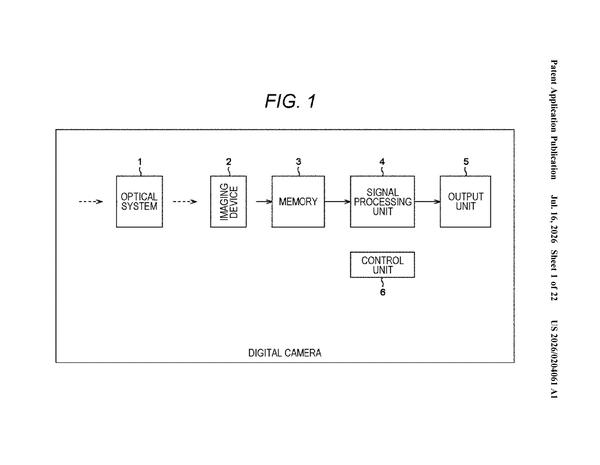
Running event detection on the camera chip itself lets the system discard raw video frames before they reach processing pipelines, keeping sensitive visual data contained at the hardware level.
Within filtering before cloud AI, this explores running inference directly in UI components so sensitive data stays client-side even when offline, shifting the scrubbing boundary to individual app panels.
Within the privacy-first training bucket, this filing proposes using diagnostic 5G signals already flowing between device and tower as a training data source, potentially reducing the need to transmit raw user data for model improvement.
Debugging tools expose everything by design, so IBM's method masks sensitive data during code inspection, letting engineers find bugs without revealing passwords or encryption keys that happen to be in memory.
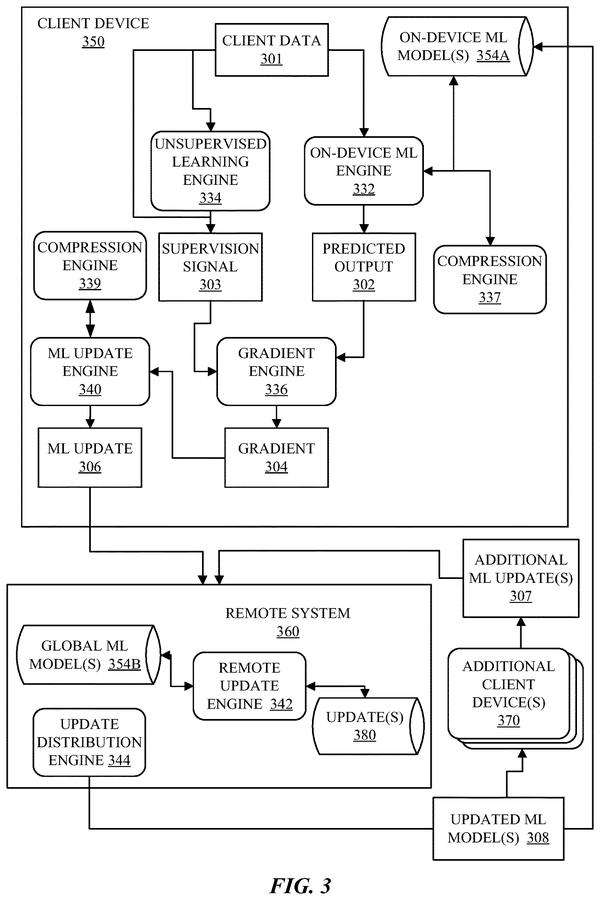
Local model training followed by encrypted weight-sharing lets devices improve a central AI without exposing raw user data to servers, shifting the privacy burden from input filtering to parameter transmission.
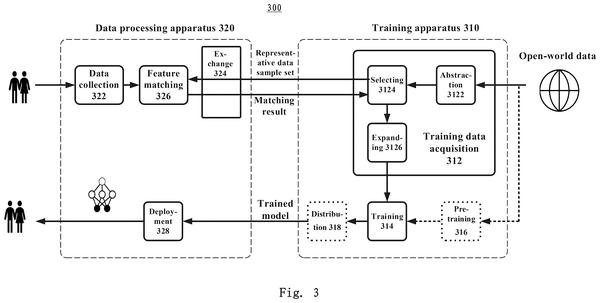
Where the watchlist has focused on keeping data local, Sony's filing adds a mechanics layer: how to partition training work across multiple nearby devices so no single phone bears the full computational load, keeping the entire process off remote servers.
Federated learning on resource-constrained devices requires phones to compress their local training updates before transmission, and this patent details how to strip unnecessary data from those updates without degrading model accuracy.
Within filtering before cloud reach, this confirms the shift from full identifiers to partial signals: Google measures app traffic intensity using only scrambled fragments, never complete user markers.
On-device model training needs diverse, representative data to avoid skewed performance. Qualcomm's approach collects location signals across varied conditions directly on the phone, preventing the bias that comes from passive or limited sampling.
Filtering search results on the display itself keeps spoiler metadata from ever reaching external servers, moving the privacy boundary to the moment content enters your screen.
Distributed training schemes need all devices to speak the same compression language or model updates won't combine cleanly. Qualcomm's negotiation layer lets phones agree on a common format before they start sending encrypted updates to a shared model.
Blocking cross-app identity reconstruction by monitoring what each app collects separately, then preventing combinations that would re-identify users even when individual datasets stay anonymized.
Users could get sharp vision rendering without apps learning their precise eye movements, letting devices filter gaze data before passing it along rather than trusting software to ignore sensitive patterns.
On-device training already assumes models stay local; Sony's filing shows how devices can still personalize those models by uploading statistics rather than raw readings, shrinking what leaves the device from full sensor streams to computed summaries.
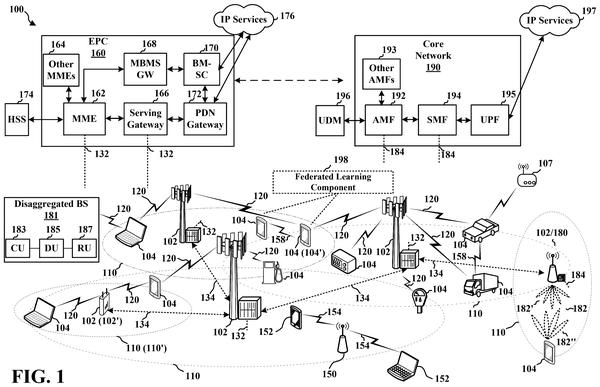
Training models across distributed devices has relied on one architecture so far; Samsung's filing shows how to weave together two different training approaches on the same 5G network, keeping raw data local while still combining what each node learns.
Where privacy-conscious on-device AI needs physical shielding, Qualcomm adds defense against side-channel attacks, preventing adversaries from reverse-engineering models through power consumption and timing patterns.
Filtering out audio the device itself is playing prevents false wake-word triggers from video and podcast content, narrowing the on-device processing to genuine user commands rather than filtering sensitive user speech.
Training image recognition models without uploading raw video keeps footage off the wire. Sony's camera chip updates its AI locally, so the device improves its own accuracy from live captures alone.
Devices could train AI locally while offloading compute to cell towers based on signal strength, distributing the workload rather than centralizing it.
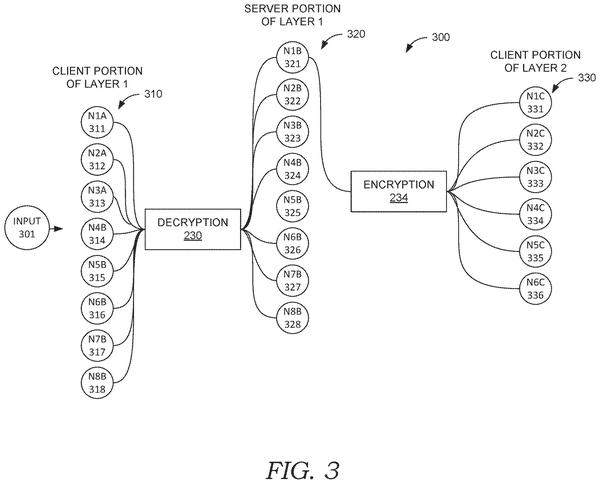
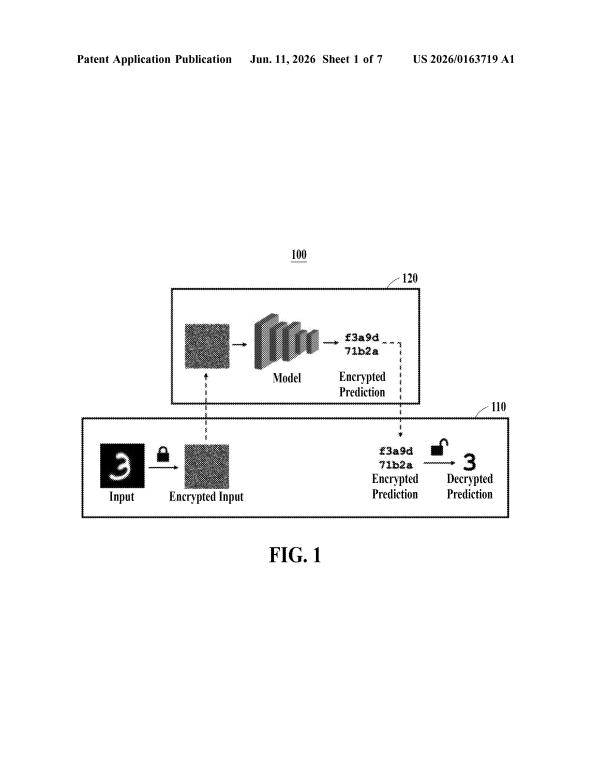
Keeping AI model weights and input data encrypted simultaneously during inference eliminates the decryption step where data typically becomes readable to the AI system.
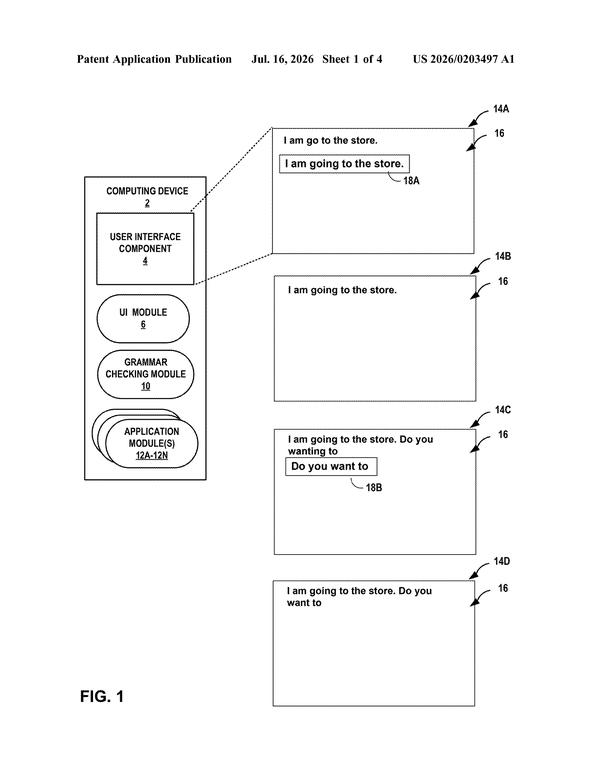
Filtering text before transmission requires local language models small enough for phones. Google's filing shows how to run grammar correction on-device without cloud processing, keeping raw writing data from ever leaving the device.
Broadcast signals from cameras and microphones alert nearby phones to their presence, letting users send privacy requests directly to the recording device rather than relying on posted notices or company policies.
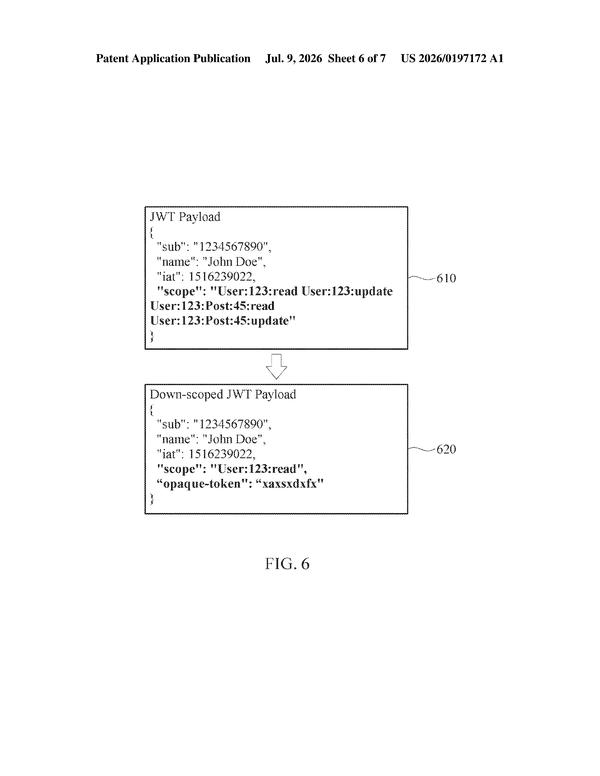
Filtering identity tokens at the device level before they reach apps prevents unnecessary exposure of claims like name and address that aren't required for authentication alone.
Training across distributed private data sources confirms the watchlist's shift from device-level scrubbing to multi-party computation, where mathematical noise replaces data movement as the privacy mechanism.
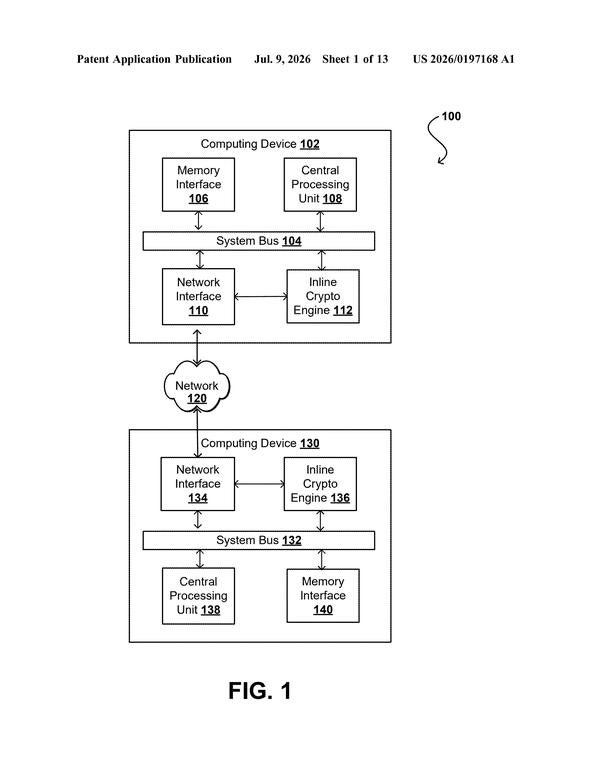
Hardware encryption vaults that process data internally rather than exposing keys to software running on the same chip, preventing local code from intercepting sensitive material during encryption operations.
Training AI on devices without retaining raw data stays central to this watchlist. Google's approach replaces actual user examples with synthetic proxies that preserve statistical patterns, pushing the technical boundary on what "no storage" actually means.
Training loop extensions confirm the watchlist's focus: feedback signals can shape models without exposing inputs, only the neural state itself needs to leave the device.
Decomposing mixed audio into discrete sound objects on-device avoids transmitting raw recordings to cloud servers, letting users filter sensitive background sounds before any data leaves their phone.
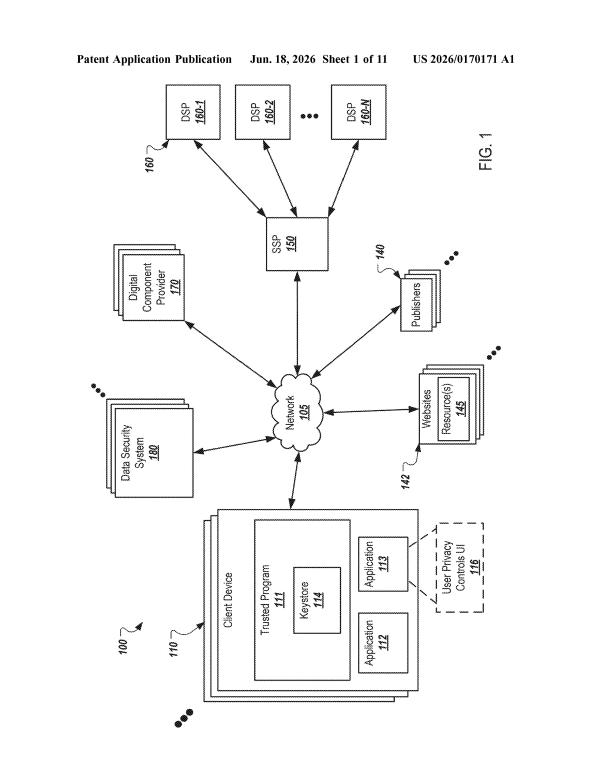
On-device interest summaries let ad platforms match ads without collecting browsing history on their servers, shifting the profiling work entirely to the user's device where raw data stays put.
Organizing training data into discrete compartments during model creation lets companies selectively remove learned patterns tied to specific records without full retraining, solving the operational headache of honoring deletion requests at scale.
Within the data-filtering layer, this filing focuses on the detection problem: identifying credential leaks at the moment of composition, before content ever reaches the destination app or service.
Pooling radio-layer observations across nearby devices lets each phone improve signal handling from collective experience while keeping wireless data local, extending the privacy approach from cloud models down to physical-layer learning.
Running A/B tests on device features requires collecting behavioral data at scale. Google's patent describes how to conduct these experiments and aggregate results without storing individual user logs, keeping the raw data ephemeral.
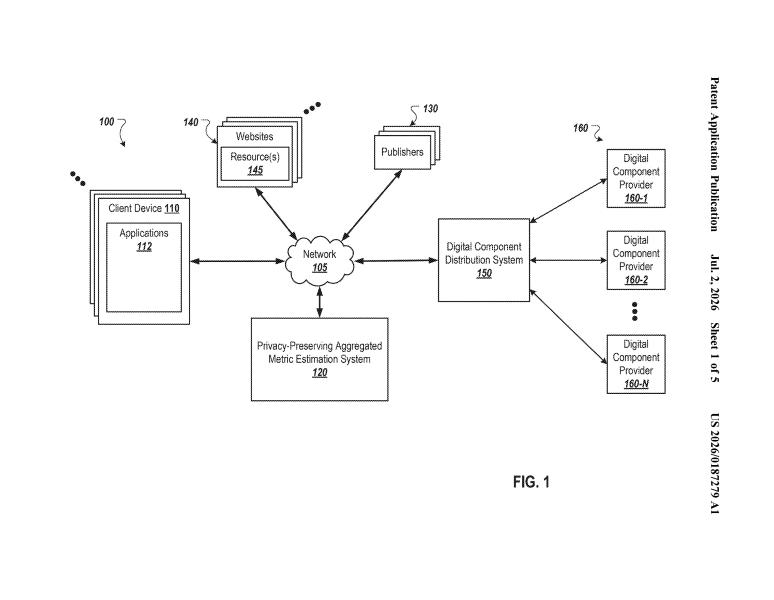
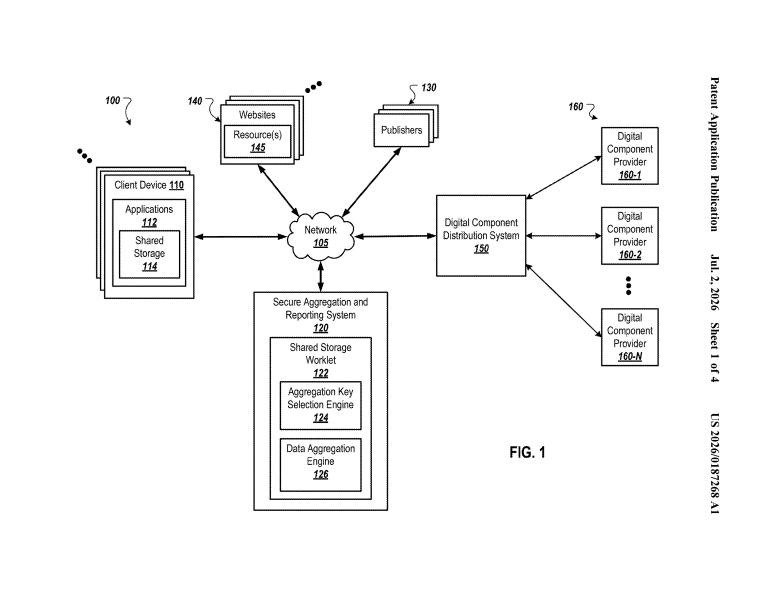
Filtering noise from aggregated ad reports recovers measurement accuracy without reconstructing individual user paths, letting advertisers validate campaign performance while keeping the Privacy Sandbox's anonymity layer intact.
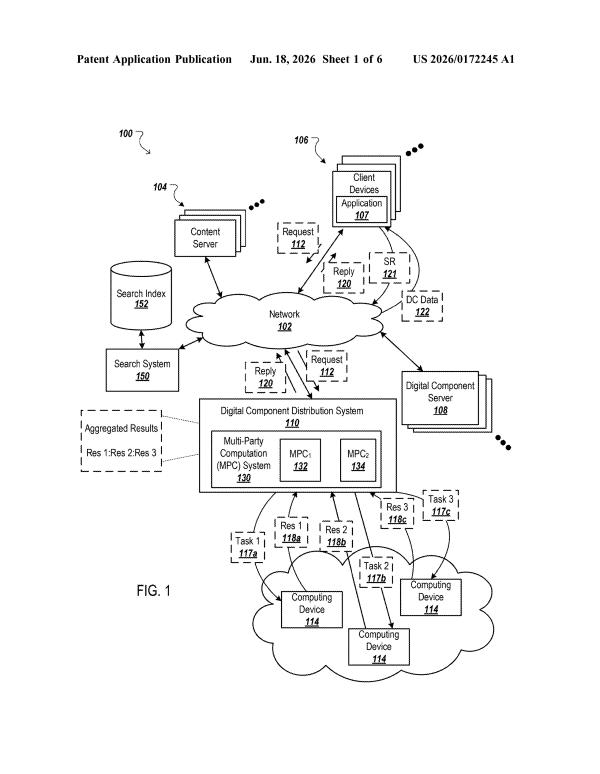
Device-side analytics means servers never need raw user data. Google's patent shows how to answer business questions through statistical noise rather than individual records, keeping sensitive behavior patterns off centralized servers.
On-device AI needs training data scrubbed before deployment. Google's method detects when speech models have memorized private voice fragments during training, stopping that leakage at the source rather than after models reach user devices.
Differential privacy's computational overhead limits hospital-scale deployments. Google's approach caps total compute requirements, making on-device training feasible for organizations that currently can't afford the privacy tax.
Generating synthetic factory data rather than anonymizing real records sidesteps the risk that stripped identifiers could be reverse-engineered to expose actual production methods.
Keeping the interest profile on-device and sending only aggregated signals to servers sidesteps the need to store individual browsing histories in the cloud, reducing what data actually leaves the phone.
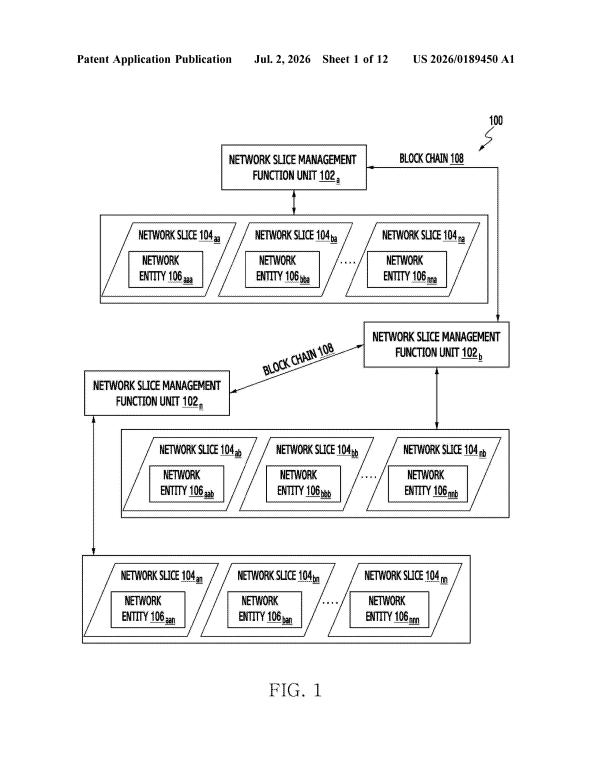
Within the data-filtering layer, Samsung adds a method for pooling intelligence across isolated network segments without exposing raw data to a central trainer.
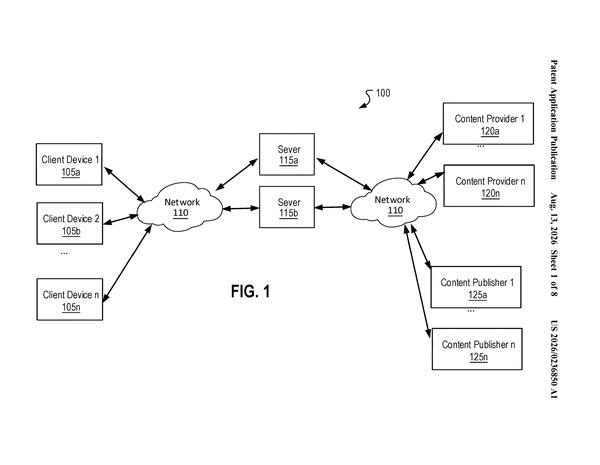
Devices deciding which ads to show users locally eliminates the server step entirely, keeping targeting data from ever uploading to Google's infrastructure.
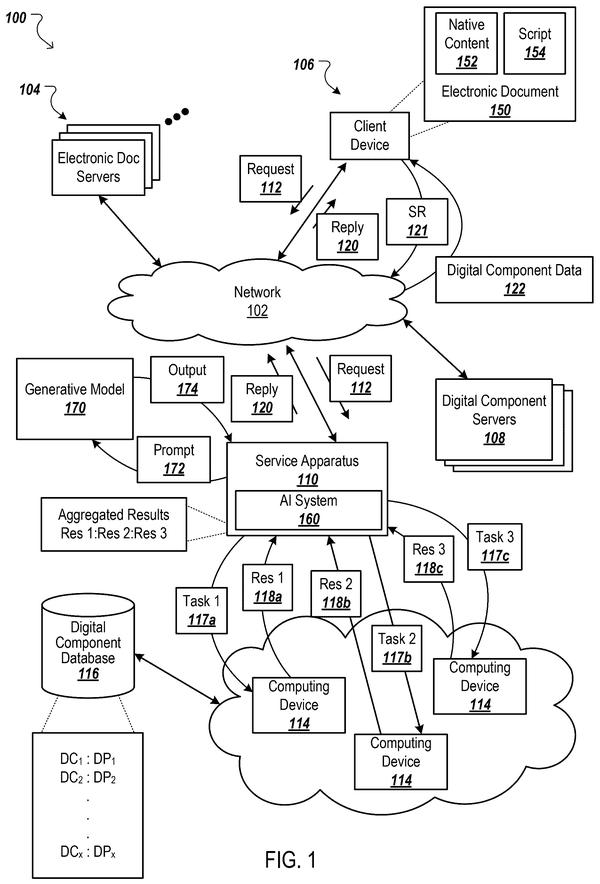
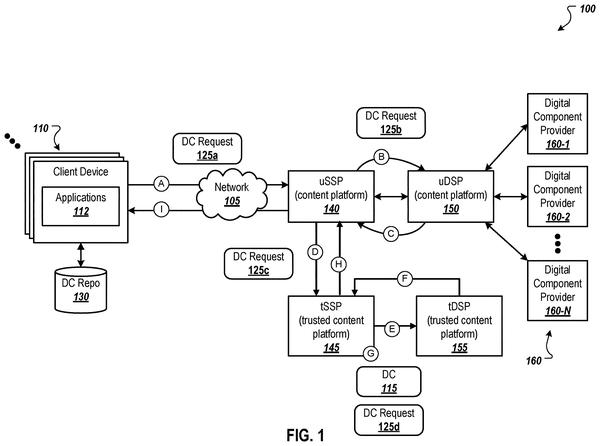
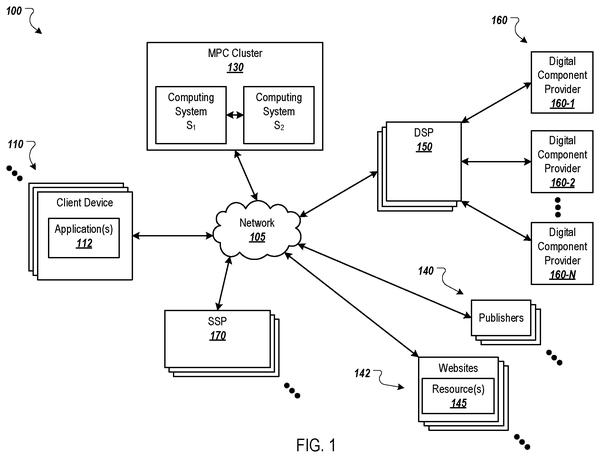
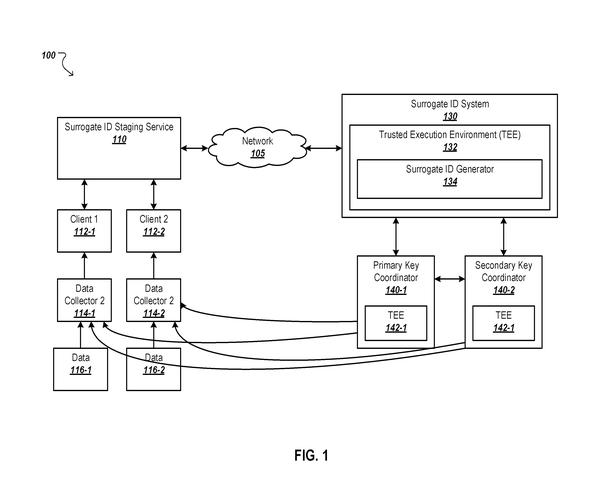
On-device AI needs ads that work without exposing user profiles. Google's split-server auction keeps ad selection distributed so no machine sees the full picture of who's watching.
Where cloud processing needs raw data exposure, FHE removes that requirement by computing directly on encrypted values. Intel's chip design targets the speed bottleneck that currently makes this impractical at scale.
Within the on-device AI privacy push, this filing adds a circuit-level defense: stopping attackers from inferring encryption keys by monitoring power consumption during data processing on the device itself.
Keeping ad selection logic split across isolated systems prevents any single server from matching specific users to the ads they see, a key technical requirement for on-device ad serving.
Running AI training on scrambled data means hospitals and banks could use real patient records and transactions without exposing the actual diagnoses or account details to anyone, even the engineers building the model.
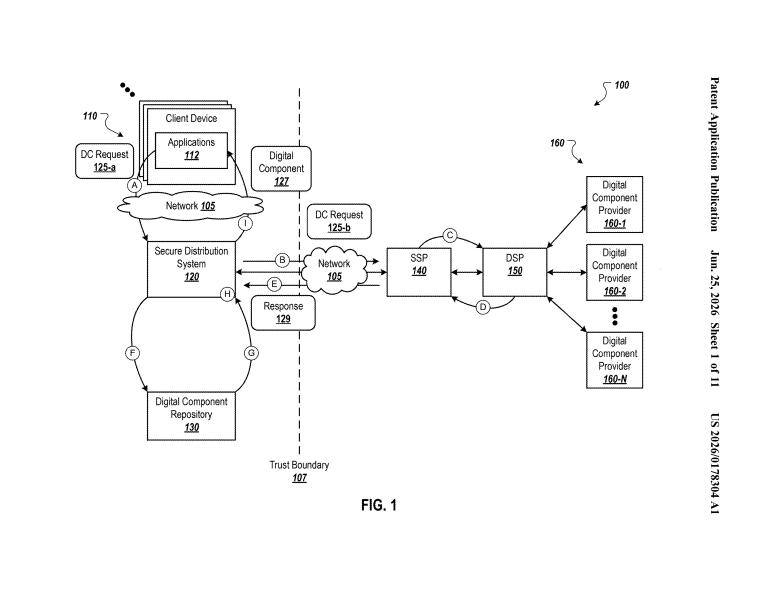
The ad stack itself becomes a target: Google proposes running the entire bidding process in one sealed environment rather than scattering user data across vendor networks.
On-device AI needs to stay reliable even when attackers know the training data. Google's approach uses a teacher-student model to filter out poisoned inputs before they corrupt the local model.
Bundling multiple ad requests into one trip prevents any single server from assembling a complete user profile, solving the fragmentation problem that currently lets advertisers stitch together behavioral data across separate slot-filling calls.
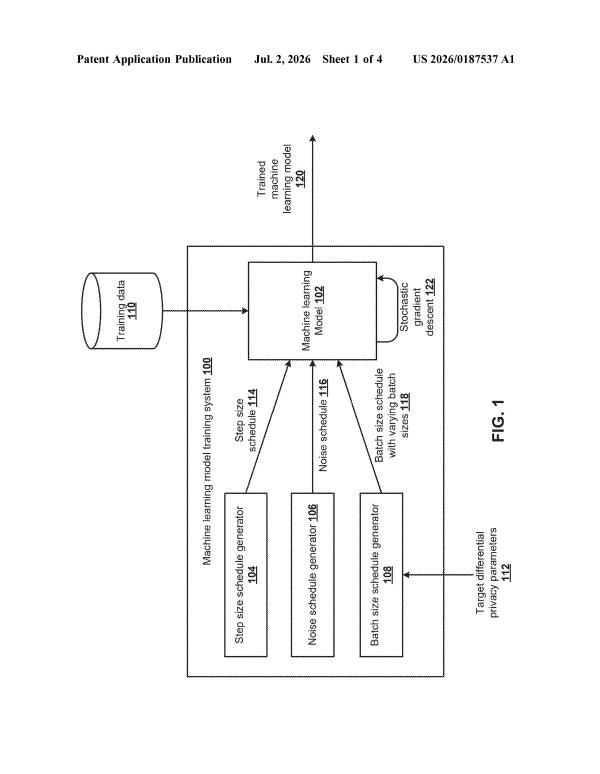
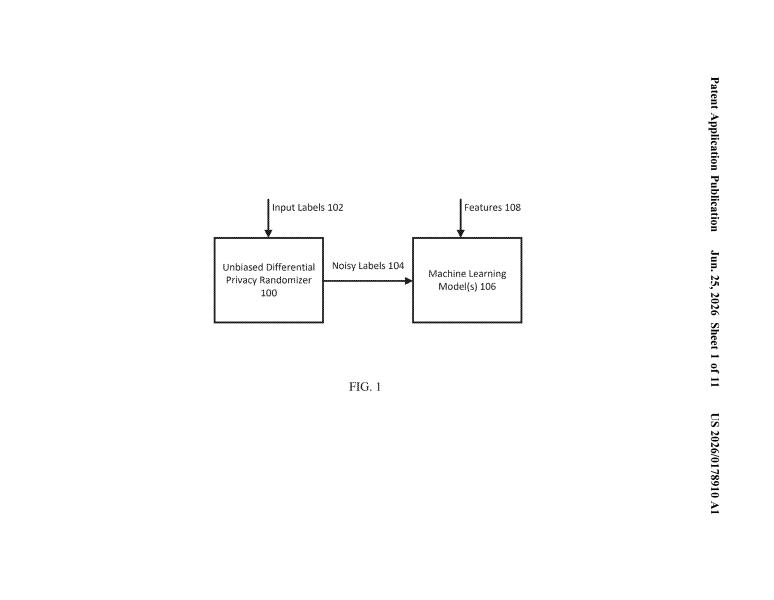
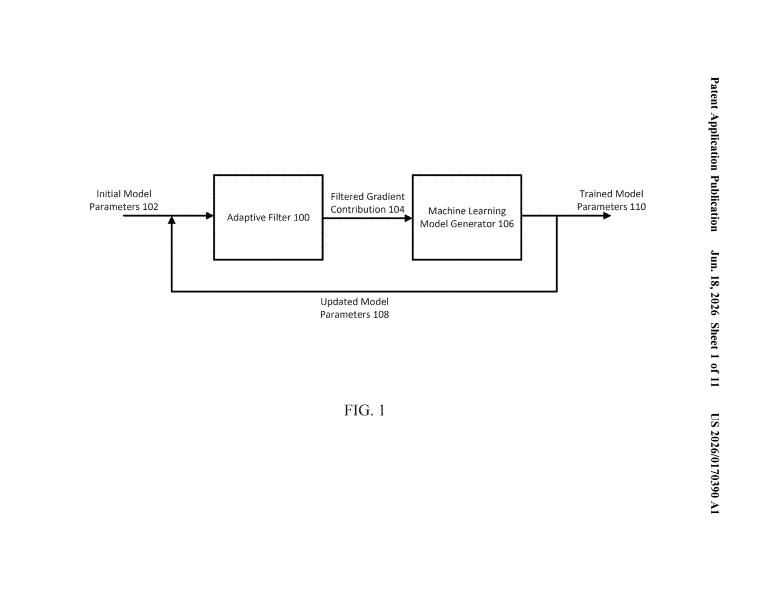
Injecting calibrated noise during training lets models learn from real user data while meeting formal privacy guarantees, solving the core tradeoff between personalization accuracy and data protection.
Intercepting identity handoffs between websites and trackers, this system substitutes cryptographic tokens for real email addresses, preventing publishers from linking your activity across the ad ecosystem.
On-device AI needs servers to train models, but servers see everything. Google's split-data approach lets multiple servers collaborate on learning without any one holding the complete profile.
Devices holding ad-profiling data locally means ad networks stop building remote dossiers on individual users. Google's approach shifts the tracking infrastructure from centralized servers to local processing, eliminating the data collection step entirely.
The distributed auction approach extends the privacy-first logic beyond model inference to advertising infrastructure, keeping user profiles fragmented across parties so no entity assembles a complete bidding picture.
Knowing when personal data actually improves an answer cuts unnecessary data exposure. Google's patent describes AI that retrieves your information only for questions where context genuinely matters, reducing privacy risk from indiscriminate profiling.
Filtering sensitive objects out of images before the AI model even sees them keeps private data from entering the processing pipeline at all, sidestepping the need to trust the model itself with restraint.
Running personalized AI queries entirely on-device means the phone itself becomes the knowledge base, eliminating the server round-trip that currently exposes user behavior data.
Keeping restricted cards from being casually transferred between phones requires identity verification baked into the wallet app itself, not just at the bank's backend.
Running cryptographic verification on a secure chipset isolates signature-checking from the main processor, preventing quantum attacks from compromising authentication even if device software gets breached.
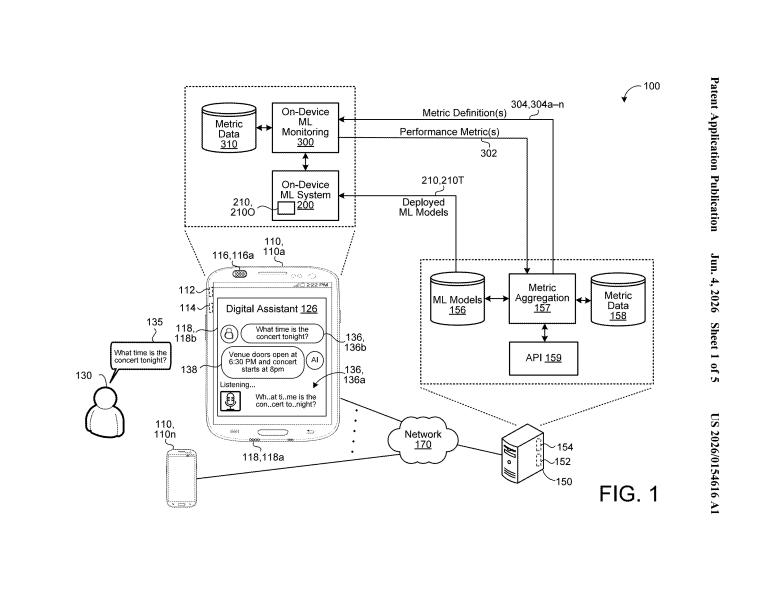
Monitoring local AI performance without exporting user data requires the phone to generate health metrics on-device, then send only aggregated summaries back to Google, solving the measurement problem that on-device deployment creates.
On-device models still need context to work well, but feeding them real data risks exposure. Samsung's solution: anonymize inputs before the AI processes them, then restore the original data after, keeping sensitive information away from the model entirely.
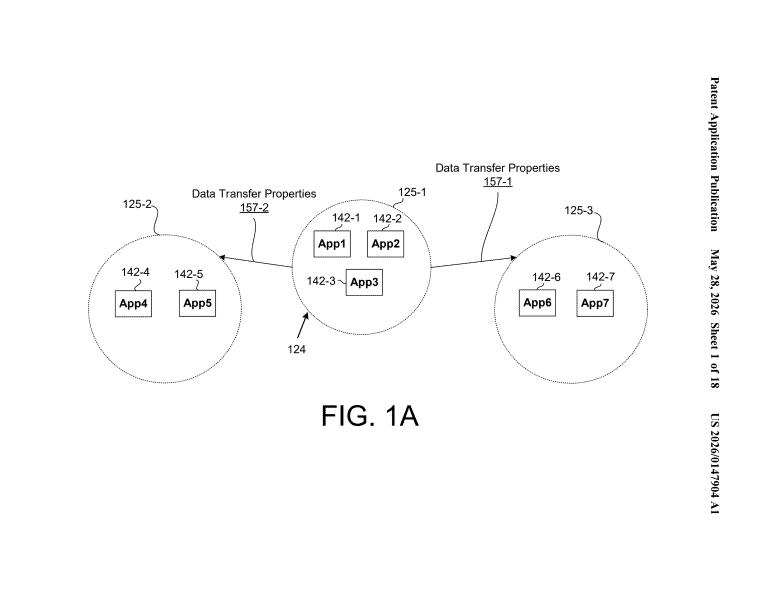
On-device data walls would let users group apps by trust level, preventing sensitive information from leaking between an approved work cluster and untrusted personal apps without requiring constant manual permission checks.
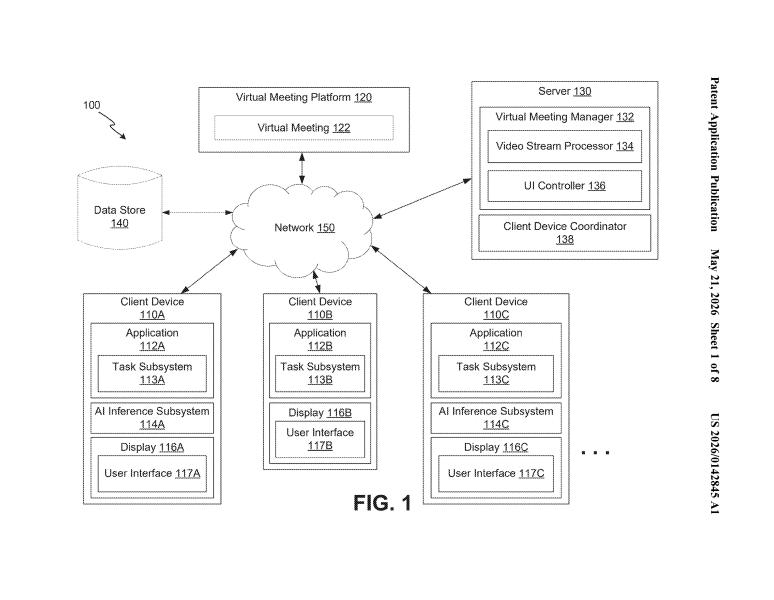
Distributing AI processing across multiple participants' devices during a call eliminates the need for a central server to handle meeting tasks like summarization and action-item extraction, keeping conversation data local throughout the interaction.
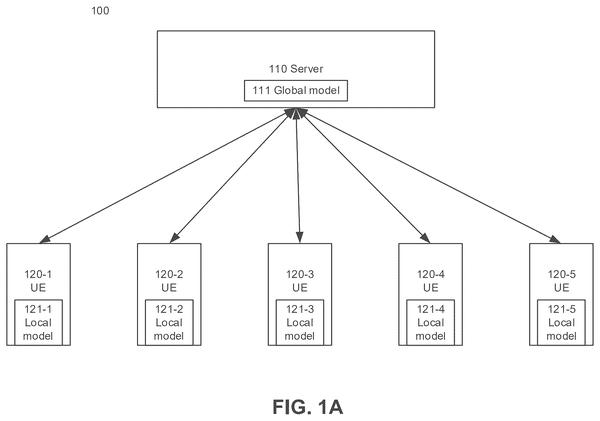
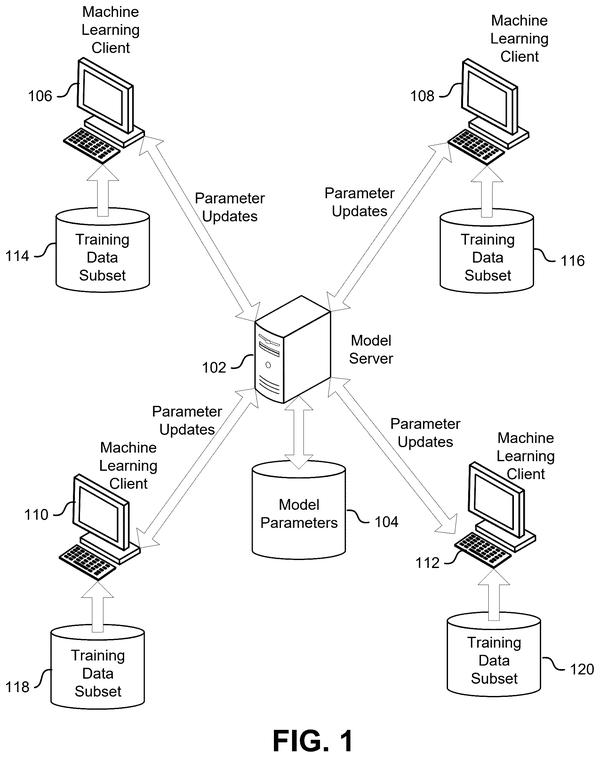
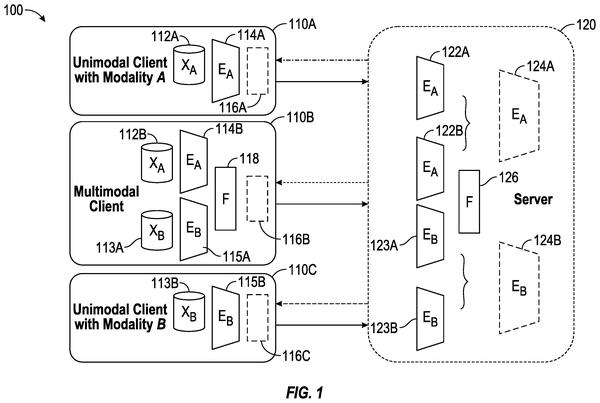
Training AI across millions of devices requires a way to share learning without exposing raw data. Google's approach sends summaries of what each phone learns to a central server, which combines them into a stronger model.
On-device recommendations mean streaming apps could learn viewing patterns without uploading watch history to the cloud, letting personalization happen where the data already lives.
As companies route queries between on-device and cloud AI systems, Google is solving the handoff problem: filtering sensitive details before voice data moves to untrusted external assistants.
Filtering sensitive data before cloud upload shifts the privacy burden from servers to the device itself, moving the filter upstream rather than asking cloud systems to handle it.
Keeping audio analysis on the device itself, Google's system lets smart speakers learn user-specific sound patterns through local feedback loops, sidestepping the need to transmit raw recordings for model training.
Questions readers ask
What problem is this watchlist actually about?
These filings show Big Tech engineers working on ways to run AI tasks like recommendations, voice assistants, and ad targeting directly on a phone or TV instead of a server, so personal data never has to leave the device. The goal is doing useful AI work while keeping raw user data local.
Does this mean Google and Samsung phones already run AI without sending data anywhere?
Not yet, and patents are not proof of a shipped feature. What we see is a documented direction: both companies are filing designs for scrubbing, filtering, and training AI locally, which signals engineering priority even before any feature reaches a real device or app.
Why does Samsung's post-quantum patent show up in a privacy watchlist?
It fits because the watchlist tracks device-level trust, not just data scrubbing. A post-quantum authentication system is about making sure a device can prove its own identity securely even after future computers break today's encryption, which supports the same on-device privacy goal from a different angle.
Who is filing the most patents in this race?
Right now the sample leans heavily toward Google, with Samsung also contributing filings on data substitution and future-proof security. The watchlist is designed to track new filers as they appear, so the balance between companies can shift as more patents get added each week.
Want this weekly breakdown for a company we don't cover?
Patentlyze Pro →
The weekly email: the best of Big Tech's filings, in plain English. Free.